1
 →

Prompt Engineering | Prompt Versioning | Use GPT or other prompt based models to get structured output. Join our discord for Prompt-Engineering, LLMs and other latest research
promptslab/Promptify is an open-source project on GitHub, mainly written in Python. Prompt Engineering | Prompt Versioning | Use GPT or other prompt based models to get structured output. It currently holds 4,636 stars and 364 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Prompt Engineering board.
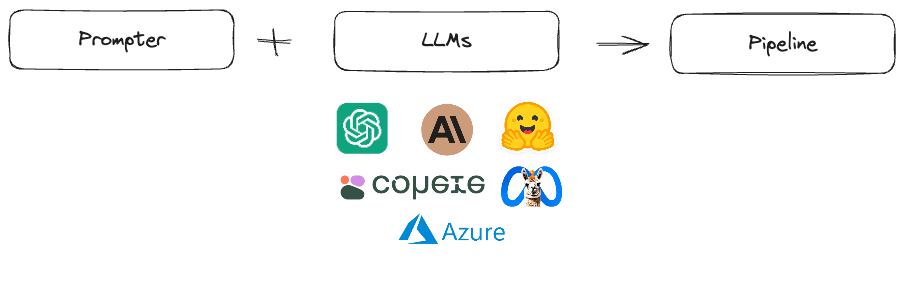
Task-based NLP engine with Pydantic structured outputs, built-in evaluation, and LiteLLM as the universal LLM backend. Think "scikit-learn for LLM-powered NLP".


Requires Python 3.9+.
pip install promptify
or
pip install git+https://github.com/promptslab/Promptify.git
For evaluation metrics support:
pip install promptify[eval]
from promptify import NER
ner = NER(model="gpt-4o-mini", domain="medical")
result = ner("The patient is a 93-year-old female with a medical history of chronic right hip pain, osteoporosis, hypertension, depression, and chronic atrial fibrillation admitted for evaluation and management of severe nausea and vomiting and urinary tract infection")
Output:
NERResult(entities=[
    Entity(text="93-year-old", label="AGE"),
    Entity(text="chronic right hip pain", label="CONDITION"),
    Entity(text="osteoporosis", label="CONDITION"),
    Entity(text="hypertension", label="CONDITION"),
    Entity(text="depression", label="CONDITION"),
    Entity(text="chronic atrial fibrillation", label="CONDITION"),
    Entity(text="severe nausea and vomiting", label="SYMPTOM"),
    Entity(text="urinary tract infection", label="CONDITION"),
])
from promptify import Classify
clf = Classify(model="gpt-4o-mini", labels=["positive", "negative", "neutral"])
result = clf("Amazing product! Best purchase I've ever made.")
Classification(label="positive", confidence=0.95)
from promptify import QA
qa = QA(model="gpt-4o-mini")
answer = qa("Einstein was born in Ulm in 1879.", question="Where was Einstein born?")
Answer(answer="Ulm", evidence="Einstein was born in Ulm", confidence=0.98)
from promptify import Task
from pydantic import BaseModel
class MovieReview(BaseModel):
    sentiment: str
    rating: float
    key_themes: list[str]
task = Task(model="gpt-4o", output_schema=MovieReview, instruction="Analyze this movie review.")
review = task("Nolan's best work. Stunning visuals but the plot drags.")
MovieReview(sentiment="mostly positive", rating=7.5, key_themes=["visuals", "pacing"])
ner_openai = NER(model="gpt-4o-mini")
ner_claude = NER(model="claude-sonnet-4-20250514")
ner_local  = NER(model="ollama/llama3")
results = ner.batch(["text1", "text2", "text3"], max_concurrent=10)
result = await ner.acall("Patient has diabetes")
from promptify.eval import evaluate
scores = evaluate(task=ner, dataset=labeled_data, metrics=["precision", "recall", "f1"])
{"precision": 0.92, "recall": 0.88, "f1": 0.90}
domain="medical" or any domain for context-aware promptsawait support with acall()eval())get_cost_summary()| Task | Class | Output Schema |
|------|-------|---------------|
| Named Entity Recognition | NER | NERResult (list of Entity) |
| Binary Classification | Classify | Classification |
| Multiclass Classification | Classify | Classification |
| Multilabel Classification | Classify(multi_label=True) | MultiLabelResult |
| Question Answering | QA | Answer |
| Summarization | Summarize | Summary |
| Relation Extraction | ExtractRelations | ExtractionResult |
| Tabular Extraction | ExtractTable | ExtractionResult |
| Question Generation | GenerateQuestions | list of GeneratedQuestion |
| SQL Generation | GenerateSQL | SQLQuery |
| Text Normalization | NormalizeText | normalized text |
| Topic Modelling | ExtractTopics | list of topics |
| Custom Task | Task | any Pydantic BaseModel |
@misc{Promptify2022,
  title = {Promptify: Structured Output from LLMs},
  author = {Pal, Ankit},
  year = {2022},
  howpublished = {\url{https://github.com/promptslab/Promptify}},
  note = {Prompt-Engineering components for NLP tasks in Python}
}
We welcome any contributions to our open source project, including new features, improvements to infrastructure, and more comprehensive documentation. Please see the contributing guidelines
→ →
 →
 →
 →
 →
 →
 →