
1
 →
microsoft/VibeVoice is an open-source project on GitHub, mainly written in Python. Open-Source Frontier Voice AI It currently holds 54,602 stars and 6,138 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the Today's Trending board, currently at rank #40 with 36 new stars today.
2026-09-03: 🚀 We released VibeVoice-ASR-Streaming, a unified streaming ASR model that continuously transcribes ''who said what'' as speech arrives, with support for customized hotwords and 10 languages. [Demo] [Models] [Report]
2026-07-23: ⚡ We released VibeVoice-ASR-BitNet, an edge CPU inference engine for VibeVoice-ASR. Through heterogeneous quantization (I8_S + I2_S), the model is compressed from 4.62 GB to 1.58 GB with real-time inference (RTF < 1) on 3+ CPU threads — no GPU required. [Code] [Models] [Report]
2026-03-12: 🚀 VibeVoice-ASR is now integrated into Azure AI Foundry Labs! You can now explore and test our unified speech-to-text capabilities directly through Microsoft Foundry.
2026-03-06: 🚀 VibeVoice ASR is now part of a Transformers release! You can now use our speech recognition model directly through the Hugging Face Transformers library for seamless integration into your projects.
2026-01-21: 📣 We open-sourced VibeVoice-ASR, a unified speech-to-text model designed to handle 60-minute long-form audio in a single pass, generating structured transcriptions containing Who (Speaker), When (Timestamps), and What (Content), with support for User-Customized Context. Try it in Playground.
2025-12-03: 📣 We open-sourced VibeVoice‑Realtime‑0.5B, a real‑time text‑to‑speech model that supports streaming text input and robust long-form speech generation. Try it on Colab.
2025-09-05: VibeVoice is an open-source research framework intended to advance collaboration in the speech synthesis community. After release, we discovered instances where the tool was used in ways inconsistent with the stated intent. Since responsible use of AI is one of Microsoft’s guiding principles, we have removed the VibeVoice-TTS code from this repository.
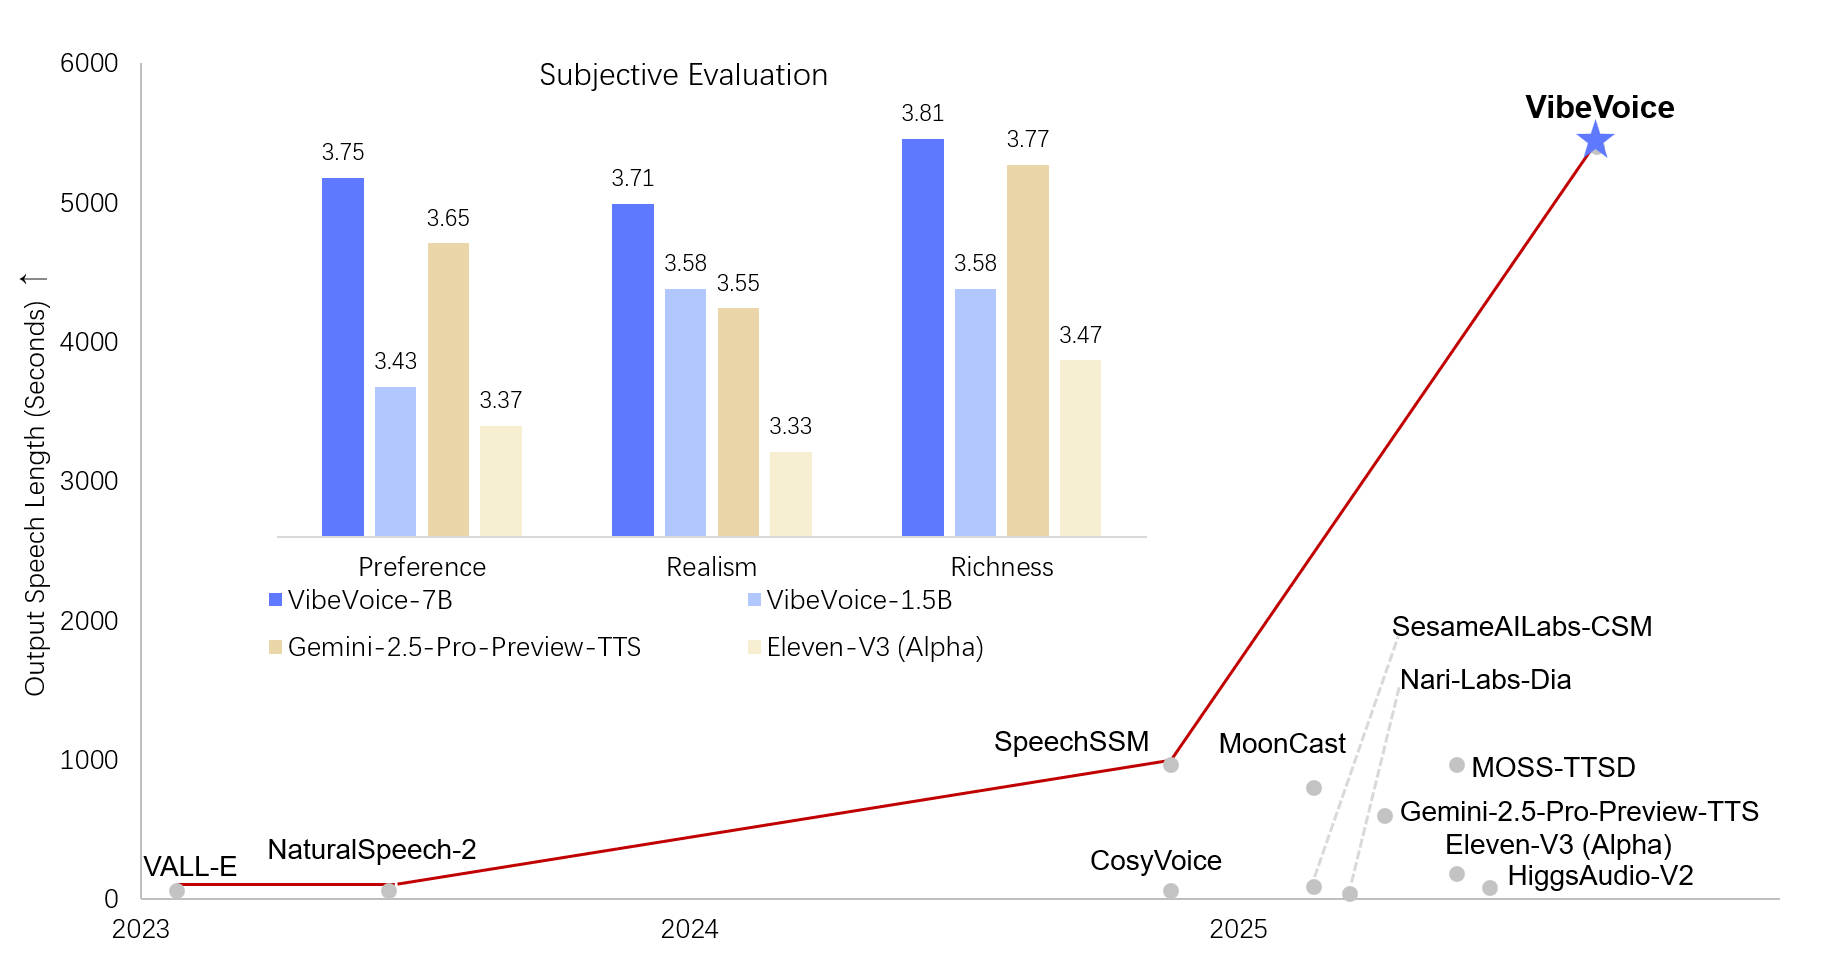
2025-08-25: 📣 We open-sourced VibeVoice-TTS, a long-form multi-speaker text-to-speech model that can synthesize speech up to 90 minutes long with up to 4 distinct speakers. — accepted as an Oral at ICLR 2026! 🔥
VibeVoice is a family of open-source frontier voice AI models that includes both Text-to-Speech (TTS) and Automatic Speech Recognition (ASR) models.
A core innovation of VibeVoice is its use of continuous speech tokenizers (Acoustic and Semantic) operating at an ultra-low frame rate of 7.5 Hz. These tokenizers efficiently preserve audio fidelity while significantly boosting computational efficiency for processing long sequences. VibeVoice employs a next-token diffusion framework, leveraging a Large Language Model (LLM) to understand textual context and dialogue flow, and a diffusion head to generate high-fidelity acoustic details.
For more information, demos, and examples, please visit our Project Page.
| Model | Weight | Quick Try | |-------|--------------|---------| | VibeVoice-ASR-7B | HF Link | Playground | | VibeVoice-ASR-Streaming | HF Link | Documentation | | VibeVoice-ASR-BitNet (CPU) | HF Link | VibeASR.cpp | | VibeVoice-TTS-1.5B | HF Link | Disabled | | VibeVoice-Realtime-0.5B | HF Link | Colab |
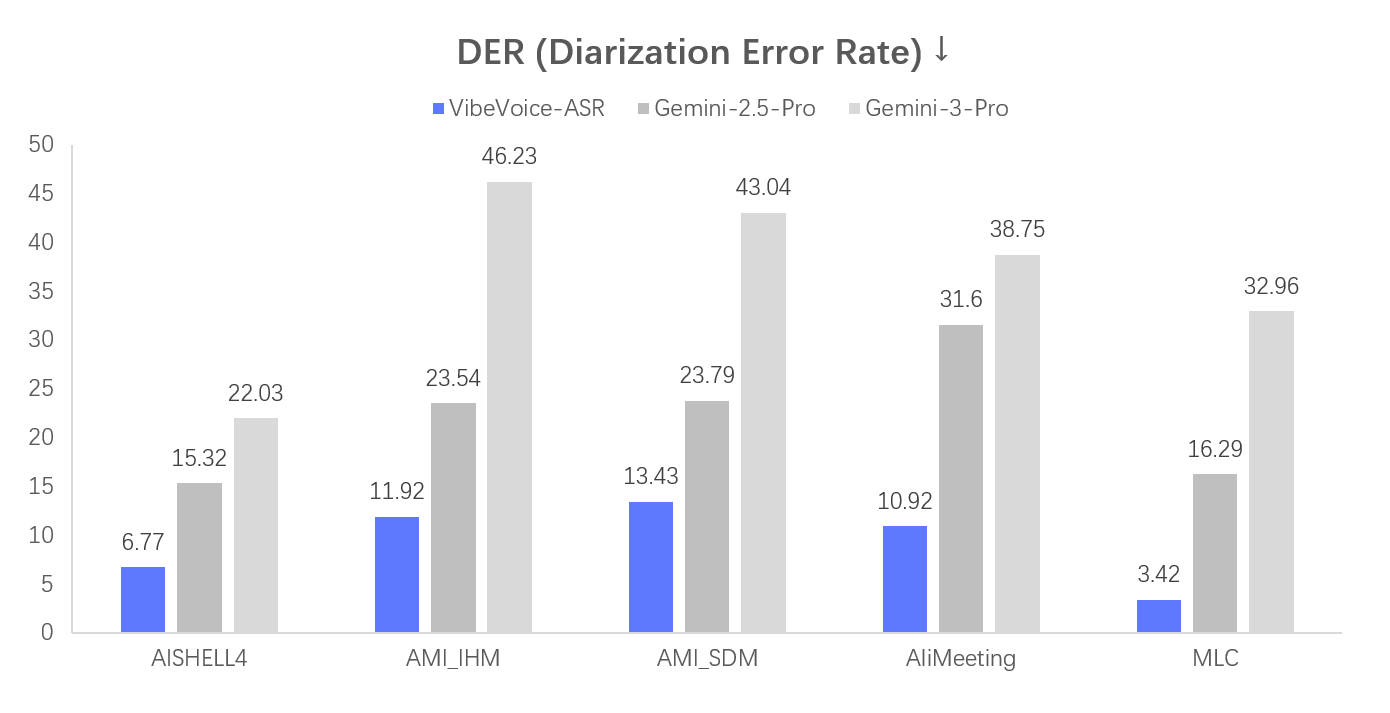
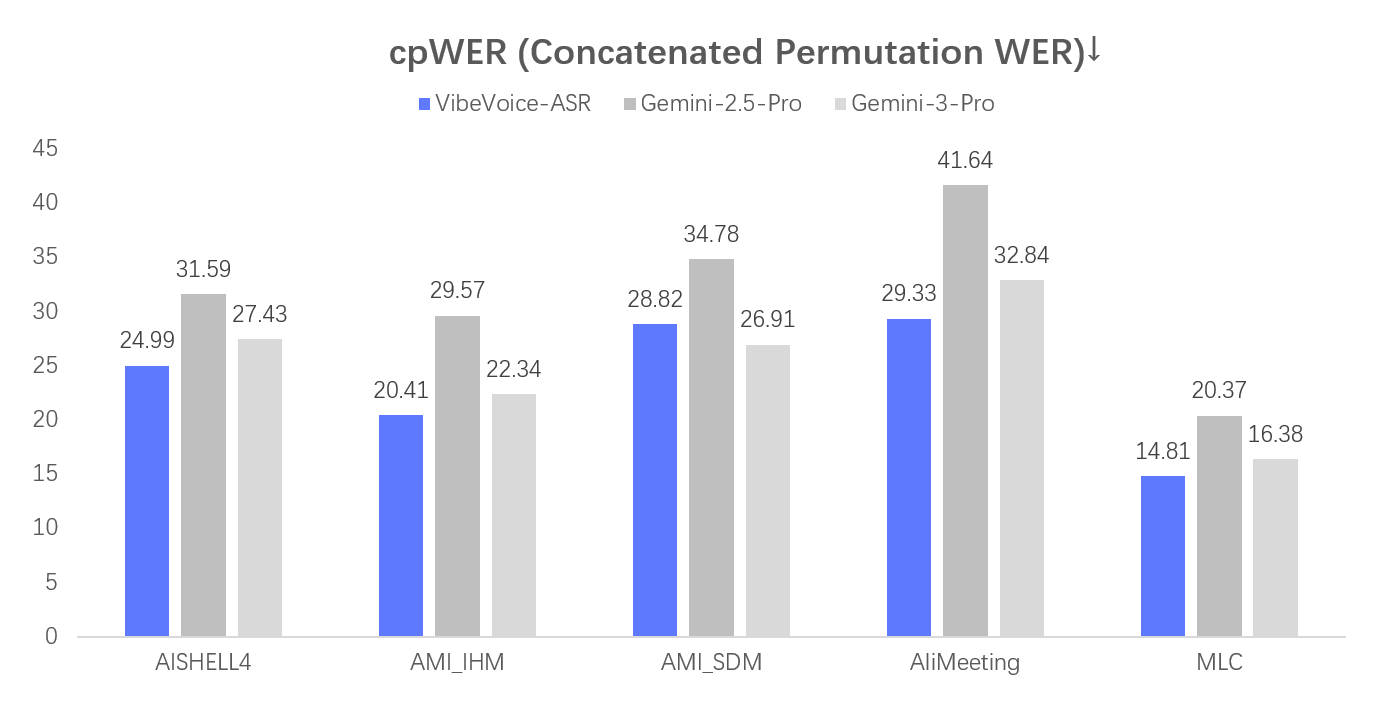
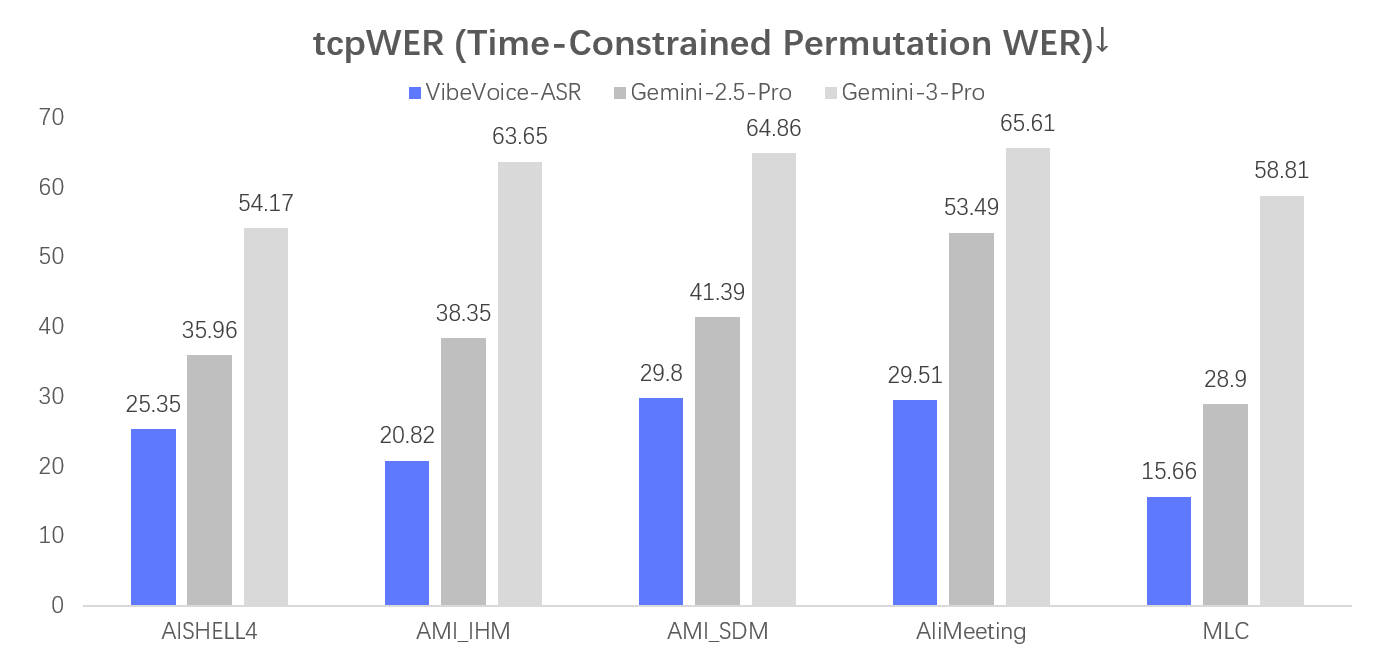
VibeVoice-ASR is a unified speech-to-text model designed to handle 60-minute long-form audio in a single pass, generating structured transcriptions containing Who (Speaker), When (Timestamps), and What (Content), with support for Customized Hotwords.
📖 Documentation | 🤗 Hugging Face | 🎮 Playground | 🛠️ Finetuning | 📊 Paper | 🎤 Streaming
https://github.com/user-attachments/assets/acde5602-dc17-4314-9e3b-c630bc84aefa
Best for: Long-form conversational audio, podcasts, multi-speaker dialogues
📖 Documentation | 🤗 Hugging Face | 📊 Paper
English
https://github.com/user-attachments/assets/0967027c-141e-4909-bec8-091558b1b784
Chinese
https://github.com/user-attachments/assets/322280b7-3093-4c67-86e3-10be4746c88f
Cross-Lingual
https://github.com/user-attachments/assets/838d8ad9-a201-4dde-bb45-8cd3f59ce722
Spontaneous Singing
https://github.com/user-attachments/assets/6f27a8a5-0c60-4f57-87f3-7dea2e11c730
Long Conversation with 4 people
https://github.com/user-attachments/assets/a357c4b6-9768-495c-a576-1618f6275727
VibeVoice-Realtime is a lightweight real‑time text-to-speech model supporting streaming text input and robust long-form speech generation.
https://github.com/user-attachments/assets/0901d274-f6ae-46ef-a0fd-3c4fba4f76dc
Please see CONTRIBUTING.md for detailed contribution guidelines.
While efforts have been made to optimize it through various techniques, it may still produce outputs that are unexpected, biased, or inaccurate. VibeVoice inherits any biases, errors, or omissions produced by its base model (specifically, Qwen2.5 1.5b in this release). Potential for Deepfakes and Disinformation: High-quality synthetic speech can be misused to create convincing fake audio content for impersonation, fraud, or spreading disinformation. Users must ensure transcripts are reliable, check content accuracy, and avoid using generated content in misleading ways. Users are expected to use the generated content and to deploy the models in a lawful manner, in full compliance with all applicable laws and regulations in the relevant jurisdictions. It is best practice to disclose the use of AI when sharing AI-generated content.
We do not recommend using VibeVoice in commercial or real-world applications without further testing and development. This model is intended for research and development purposes only. Please use responsibly.
→ →
 →
 →
 →
 →
 →
 →