1
 →

Streaming Persian (Farsi) speech recognition: fine-tuning NVIDIA Nemotron 3.5 ASR streaming. Data prep, training, evaluation, inference.
mallahyari/nemotron-asr-streaming-farsi is an open-source project on GitHub, mainly written in Python. Streaming Persian (Farsi) speech recognition: fine-tuning NVIDIA Nemotron 3.5 ASR streaming. Data prep, training, evaluation, inference. It currently holds 55 stars and 5 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the Today's Trending board, currently at rank #92 with 0 new stars today.
Code to train, evaluate and run mehdi-hf/nemotron-asr-streaming-farsi. It's a streaming speech-recognition model for Persian, fine-tuned from NVIDIA's nemotron-3.5-asr-streaming-0.6b on 1,181 hours of openly licensed Persian speech.
One model handles live audio, chunk by chunk, and whole files.
Word error rate (lower is better). The model streams the audio chunk by chunk with a 1.12 s look-ahead.
| Test set | NVIDIA stt_fa (zero-shot) | This model |
|---|---|---|
| FLEURS fa test (read speech, 852 clips) | 24.2% | 8.8% (CER 2.9%) |
| Held-out conversational test (YouTube, films; 9,154 clips) | 54.4% | 26.0% (CER 15.1%) |
| Held-out conversational dev (5,791 clips) | 57.4% | 29.6% |
| Common Voice 22 fa test (10,661 clips) | not comparable¹ | 19.1% |
persian_asr/text/asr_text.py). ZWNJ is read as a space, punctuation removed, Arabic letter forms folded, numbers spelled out.stt_fa was trained on Common Voice; this model's training data contains no Common Voice.
Requires uv and ffmpeg. Each script below declares its own dependencies, so uv run sets everything up the first time. The model downloads from Hugging Face.
uv run scripts/gradio_app.py                    # local web app: live microphone + file upload (http://127.0.0.1:7860)
uv run scripts/hf_transcribe_file.py audio.m4a  # transcribe files (any audio/video format)
uv run scripts/hf_stream_mic.py                 # live transcription from the microphone; Ctrl+C to stop
The local web app (gradio_app.py) has two tabs:
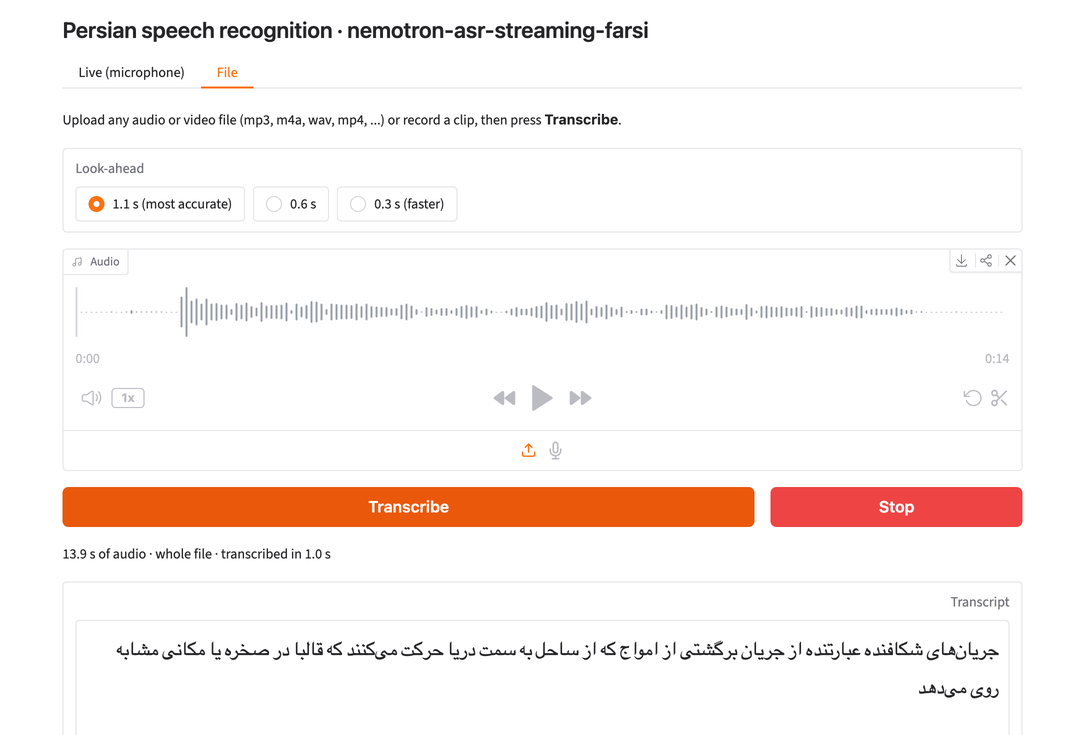
A long file, transcribed in streaming mode. The text grows as it goes, with progress, time left and a Stop button:
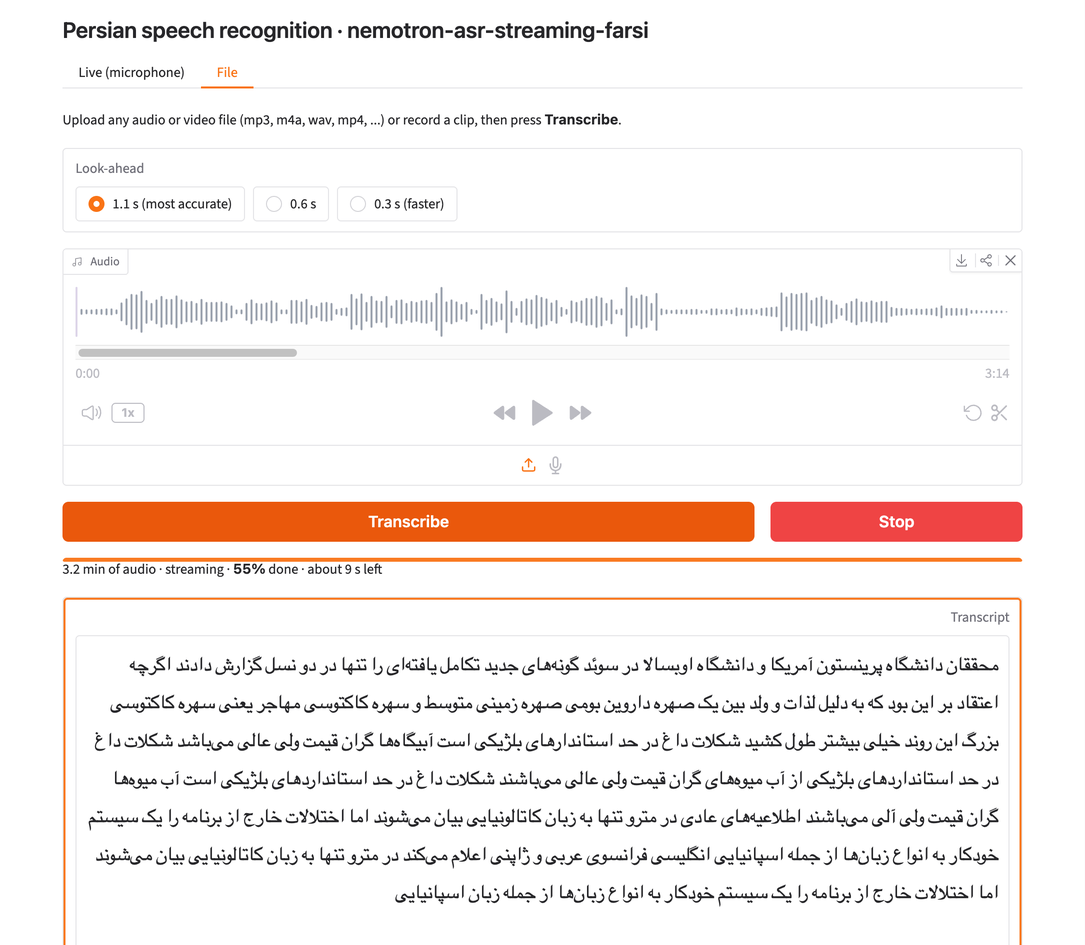
Audio: FLEURS Persian test set (CC-BY-4.0).
These use the 🤗 Transformers version of the model. It runs on Apple Silicon (MPS), CUDA or the CPU; on an M1 Pro it's about 10× faster than real time.
With NeMo instead: uv sync --extra train, then uv run --extra train python scripts/transcribe.py audio.m4a.
In code, see the model card. Set the language prompt to fa-IR.
REPRODUCE.md is the full recipe, with the exact commands:
The whole project cost about $644 on Google Cloud, from the billing dashboard. That covers everything:
| Path | What |
|---|---|
| persian_asr/text/ | Persian text normalization: training form (one spelling per word, ZWNJ lexicon) and scoring form |
| persian_asr/eval/metrics.py | WER / CER on the scoring form |
| scripts/prepare_asr_data.py, verify_manifests.py | Raw manifests → 16 kHz clips + train/dev/test manifests, and an independent check of the result |
| scripts/build_eval_sets.py, build_tokenizer.py | FLEURS and Common Voice test sets; Persian SentencePiece tokenizer |
| scripts/shard_manifest.py, oomptimizer_prompt.py | Sharded training manifests; batch-size profiling for this prompt model |
| scripts/gcp/ | Google Cloud VMs: data prep, training (train_nemotron.sh), unattended preemption-proof runs, evaluation |
| scripts/evaluate.py, nemo_eval_prompt.py | Evaluation via NeMo's eval scripts, with the language prompt fixed to fa-IR |
| scripts/transcribe.py, hf_*.py, gradio_app.py | Inference: NeMo, Transformers, local web app |
| data/splits/ | Frozen held-out speaker split and the language-ID drop list (for an identical dataset) |
uv sync && uv run pytest # text tooling and tests (no GPU needed)
The code is under Apache-2.0. The model weights are under NVIDIA's OpenMDW-1.1, the base model's license (see the model card).
nemotron-3.5-asr-streaming-0.6b, trained with NeMo.farsi-asr/farsi-asr-dataset (MIT);PerSets/youtube-persian-asr (CC0);PerSets/filimo-persian-asr (CC0);MahtaFetrat/Mana-TTS (CC0).→ →
 →
 →
 →
 →
 →
 →