labmlai/annotated_deep_learning_paper_implementations
๐งโ๐ซ 60+ Implementations/tutorials of deep learning papers with side-by-side notes ๐; including transformers (original, xl, switch, feedback, vit, ...), optimizers (adam, adabelief, sophia, ...)
About labmlai/annotated_deep_learning_paper_implementations
labmlai/annotated_deep_learning_paper_implementations is an open-source project on GitHub, mainly written in Python. ๐งโ๐ซ 60+ Implementations/tutorials of deep learning papers with side-by-side notes ๐; including transformers (original, xl, switch, feedback, vit, ...) It currently holds 67,679 stars and 6,780 forks with 46 open issues, and was last pushed on 2026-11-02 (repository created 2020-08-25).
Project Overview
AI Homed tracks it on the Today's Trending board, currently at rank #56 with 16 new stars today.
GitHub Repository Details
README
labml.ai Deep Learning Paper Implementations
Note: use the Annotated Implementation Skill with coding agents to implement any paper with annotations.
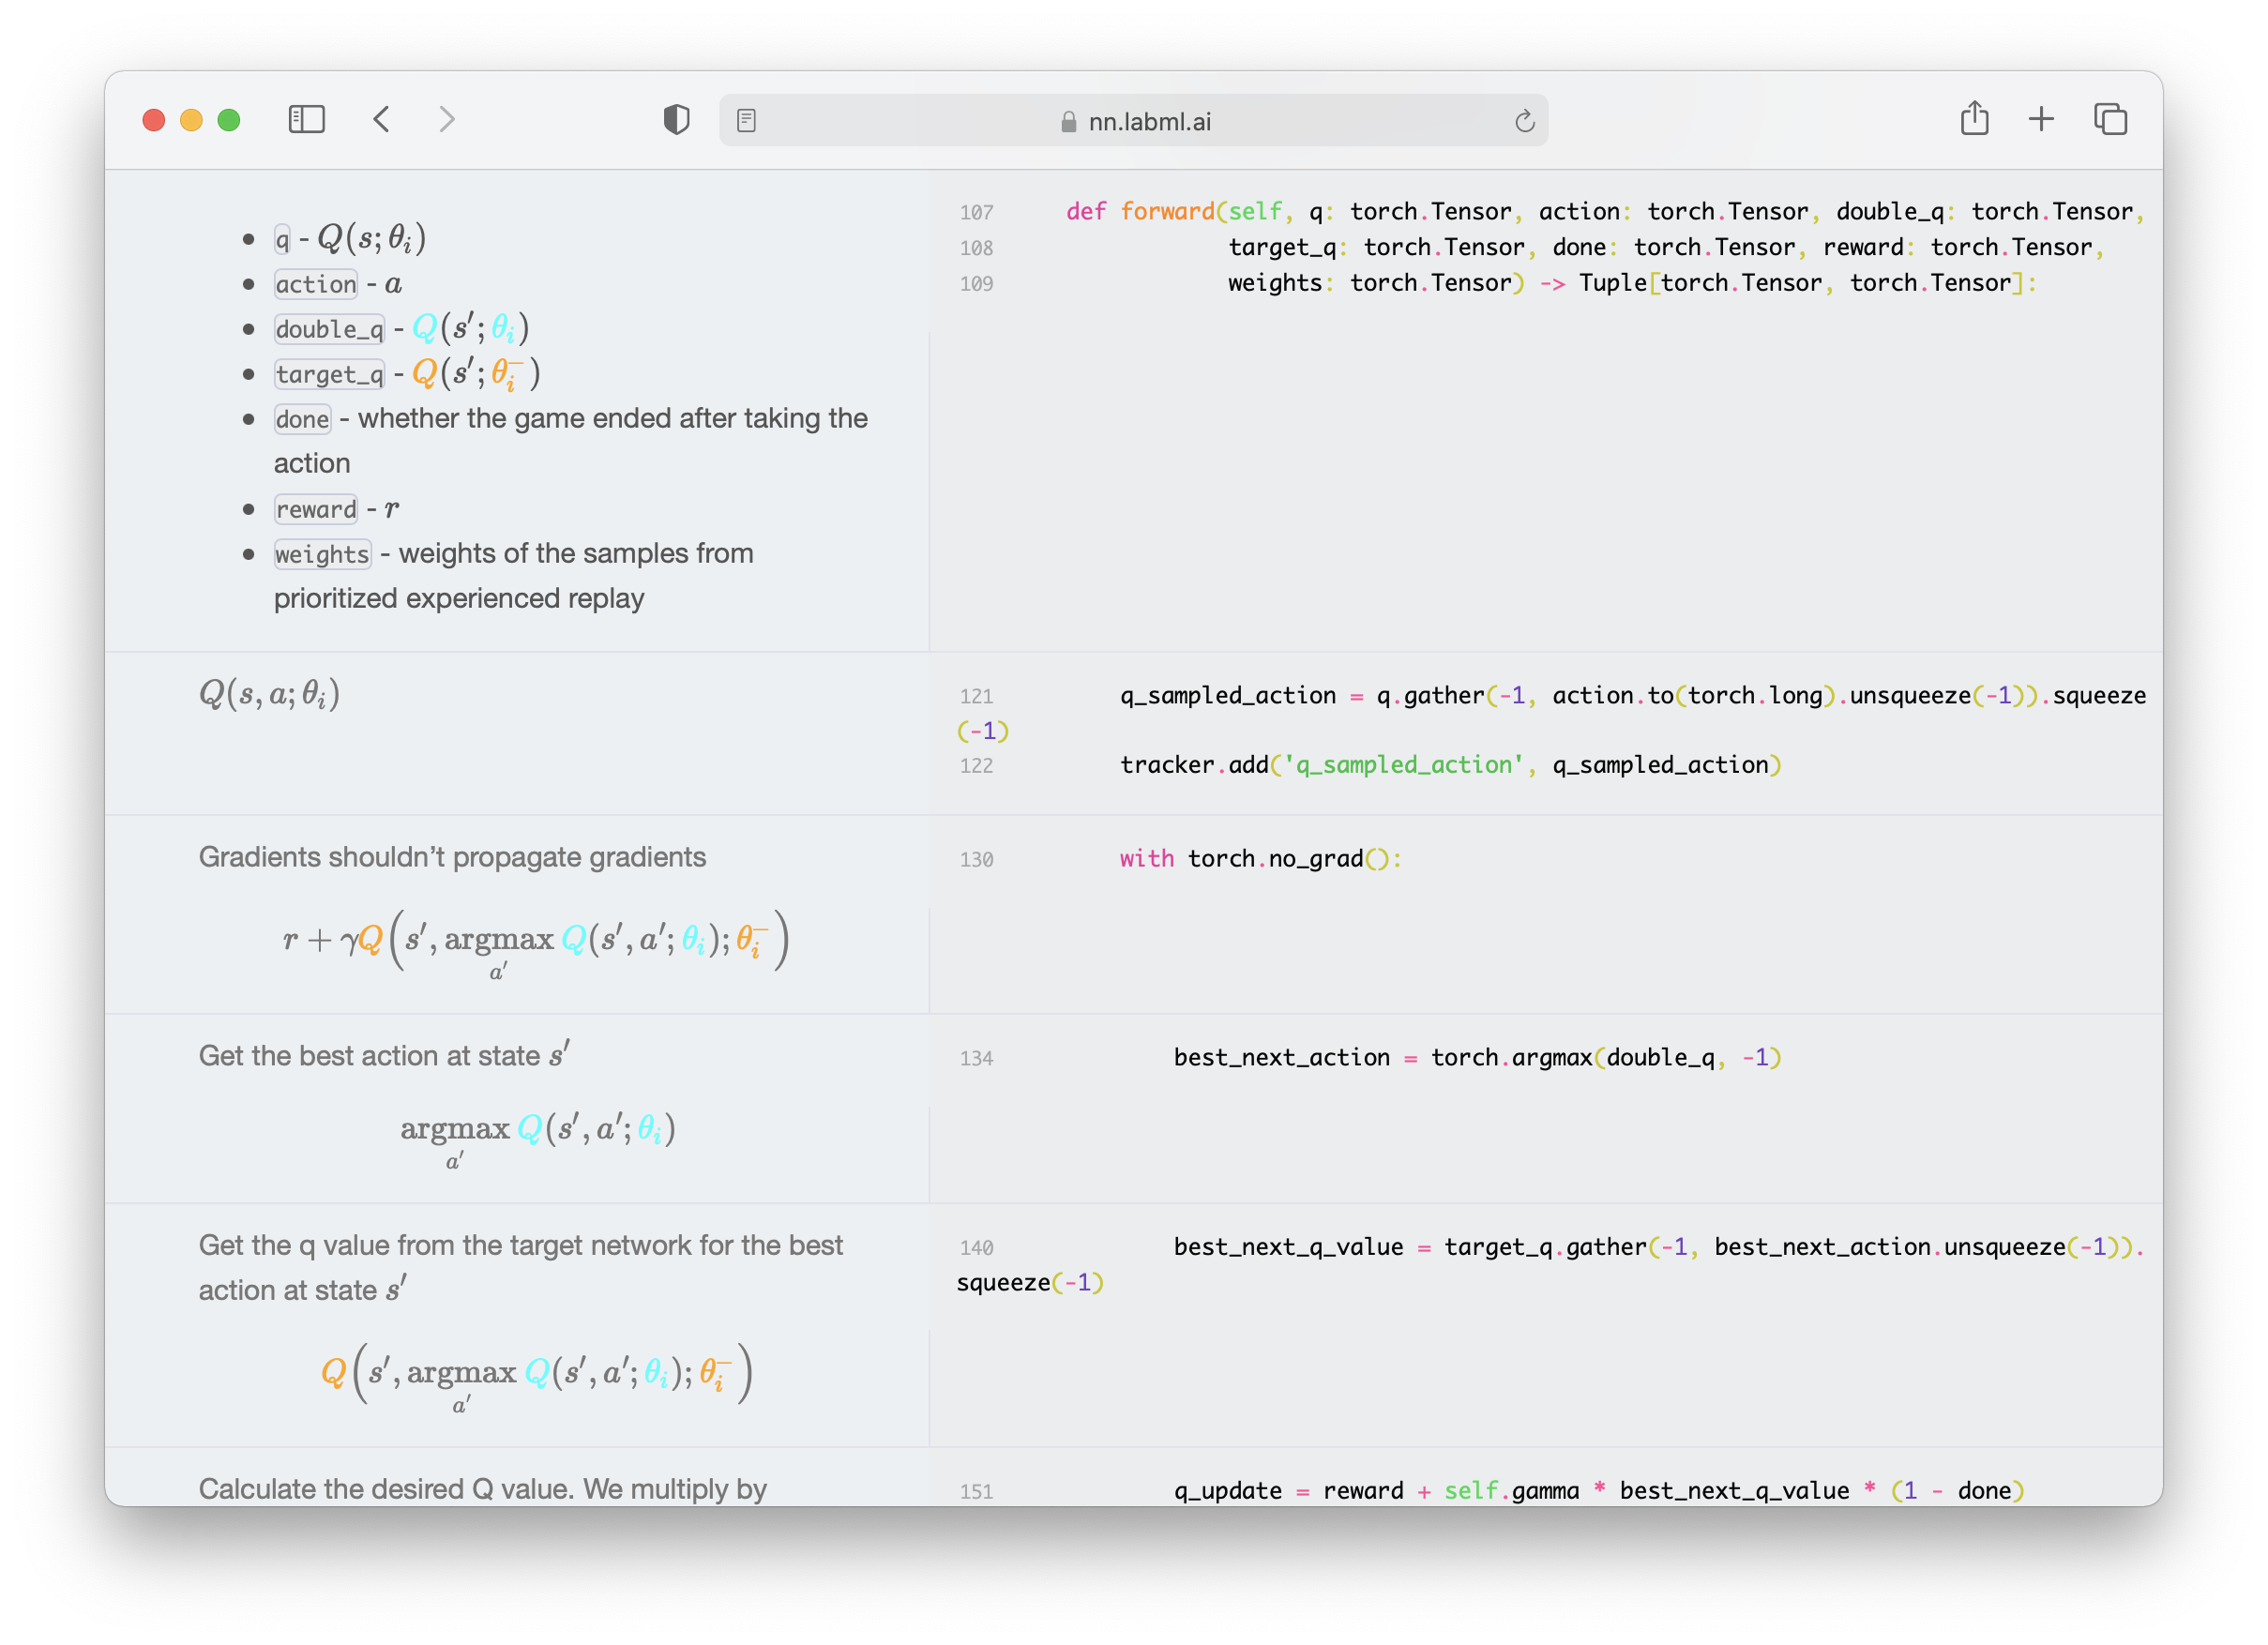
This is a collection of simple PyTorch implementations of neural networks and related algorithms. These implementations are documented with explanations,
The website renders these as side-by-side formatted notes. We believe these would help you understand these algorithms better.
We are actively maintaining this repo and adding new
implementations almost weekly.
for updates.
Paper Implementations
โจ Transformers
- JAX implementation
- Multi-headed attention
- Triton Flash Attention
- Transformer building blocks
- Transformer XL
- Relative multi-headed attention
- Rotary Positional Embeddings
- Attention with Linear Biases (ALiBi)
- RETRO
- Compressive Transformer
- GPT Architecture
- GLU Variants
- kNN-LM: Generalization through Memorization
- Feedback Transformer
- Switch Transformer
- Fast Weights Transformer
- FNet
- Attention Free Transformer
- Masked Language Model
- MLP-Mixer: An all-MLP Architecture for Vision
- Pay Attention to MLPs (gMLP)
- Vision Transformer (ViT)
- Primer EZ
- Hourglass
โจ Low-Rank Adaptation (LoRA)
โจ Eleuther GPT-NeoX
โจ Diffusion models
- Denoising Diffusion Probabilistic Models (DDPM)
- Denoising Diffusion Implicit Models (DDIM)
- Latent Diffusion Models
- Stable Diffusion
โจ Generative Adversarial Networks
- Original GAN
- GAN with deep convolutional network
- Cycle GAN
- Wasserstein GAN
- Wasserstein GAN with Gradient Penalty
- StyleGAN 2
โจ Recurrent Highway Networks
โจ LSTM
โจ HyperNetworks - HyperLSTM
โจ ResNet
โจ ConvMixer
โจ Capsule Networks
โจ U-Net
โจ Sketch RNN
โจ Graph Neural Networks
โจ Counterfactual Regret Minimization (CFR)
Solving games with incomplete information such as poker with CFR.
โจ Reinforcement Learning
Generalized Advantage Estimation- Deep Q Networks with
โจ Optimizers
- Adam
- AMSGrad
- Adam Optimizer with warmup
- Noam Optimizer
- Rectified Adam Optimizer
- AdaBelief Optimizer
- Sophia-G Optimizer
โจ Normalization Layers
- Batch Normalization
- Layer Normalization
- Instance Normalization
- Group Normalization
- Weight Standardization
- Batch-Channel Normalization
- DeepNorm
โจ Distillation
โจ Adaptive Computation
โจ Uncertainty
โจ Activations
โจ Langauge Model Sampling Techniques
โจ Scalable Training/Inference
Installation
pip install labml-nn