1
 →

Core ML model zoo for iOS/macOS — PyTorch models converted to ready-to-use .mlpackage, each with a conversion script and SwiftUI sample app.
john-rocky/CoreML-Models is an open-source project on GitHub, mainly written in Swift. Core ML model zoo for iOS/macOS — PyTorch models converted to ready-to-use .mlpackage, each with a conversion script and SwiftUI sample app. It currently holds 1,870 stars and 173 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the Local & On-Device AI board.
Maintained by Daisuke Majima — on-device AI for iOS & Android.
For a .aimodel bundle or a custom local model in a new Swift app, the Core AI start page connects the model zoo, CoreAIKit, and downloadable demo apps. It includes the tested environment for each starting point. Coding agents can read the task index.
This repository provides Core ML models and sample apps. Use the catalog below for existing Core ML integrations, earlier OS targets, or models available here; .mlpackage and .aimodel are different formats.
Take a look this model zoo, and if you found the CoreML model you want, download the model from google drive link and bundle it in your project. Or if the model have sample project link, try it and see how to use the model in the project. You are free to do or not.
If you like this repository, please give me a star so I can do my best.
| Google Drive Link | Size | Dataset |Original Project | License | | ------------- | ------------- | ------------- |------------- |------------- | | Efficientnetb0 | 22.7 MB | ImageNet | TensorFlowHub |Apache2.0|
| Google Drive Link | Size | Dataset |Original Project | License | Year| | ------------- | ------------- | ------------- |------------- |------------- |------------- | | Efficientnetv2 | 85.8 MB | ImageNet | Google/autoML | Apache2.0|2021|
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale.
| Google Drive Link | Size | Dataset |Original Project | License |Year| | ------------- | ------------- | ------------- |------------- |------------- |------------- | | VisionTransformer-B16 | 347.5 MB | ImageNet | google-research/vision_transformer | Apache2.0|2021|
Local Features Coupling Global Representations for Visual Recognition.
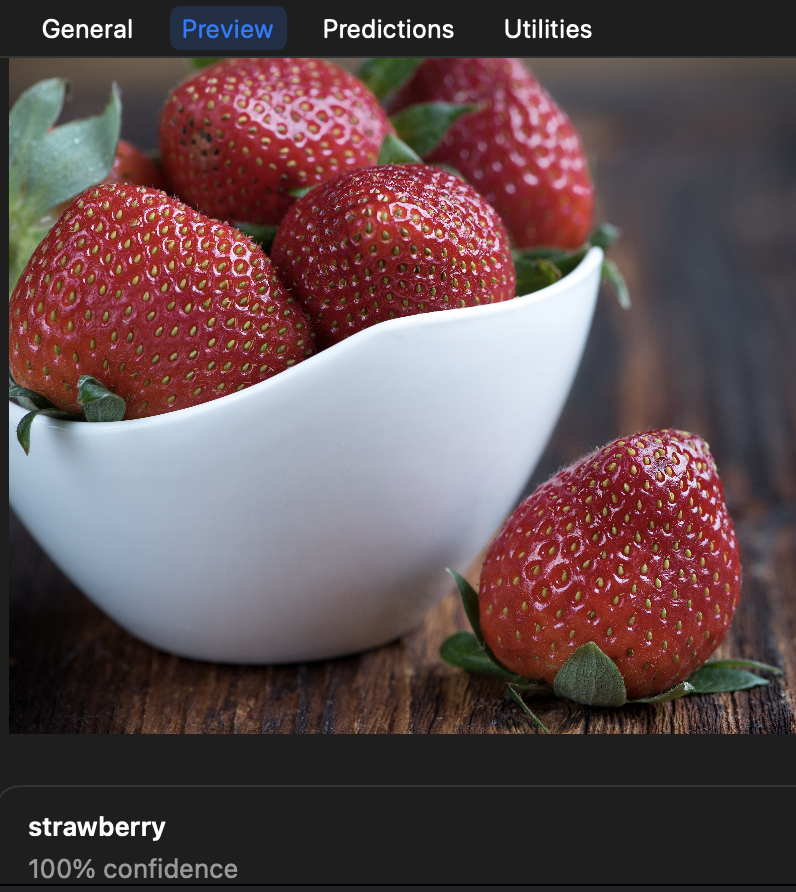
| Google Drive Link | Size | Dataset |Original Project | License |Year| | ------------- | ------------- | ------------- |------------- |------------- |------------- | | Conformer-tiny-p16 | 94.1 MB | ImageNet | pengzhiliang/Conformer | Apache2.0|2021|
Data-efficient Image Transformers
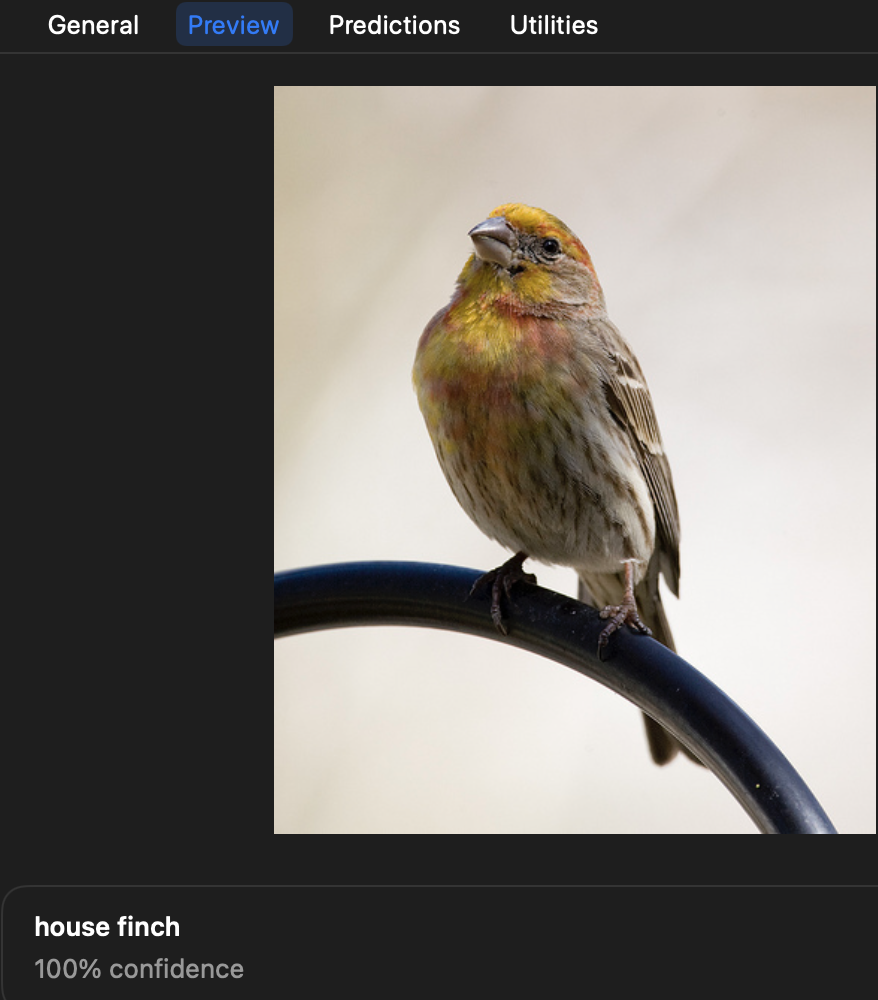
| Google Drive Link | Size | Dataset |Original Project | License |Year| | ------------- | ------------- | ------------- |------------- |------------- |------------- | | DeiT-base384 | 350.5 MB | ImageNet | facebookresearch/deit | Apache2.0|2021|
Making VGG-style ConvNets Great Again
| Google Drive Link | Size | Dataset |Original Project | License |Year| | ------------- | ------------- | ------------- |------------- |------------- |------------- | | RepVGG-A0 | 33.3 MB | ImageNet | DingXiaoH/RepVGG | MIT|2021|
Designing Network Design Spaces
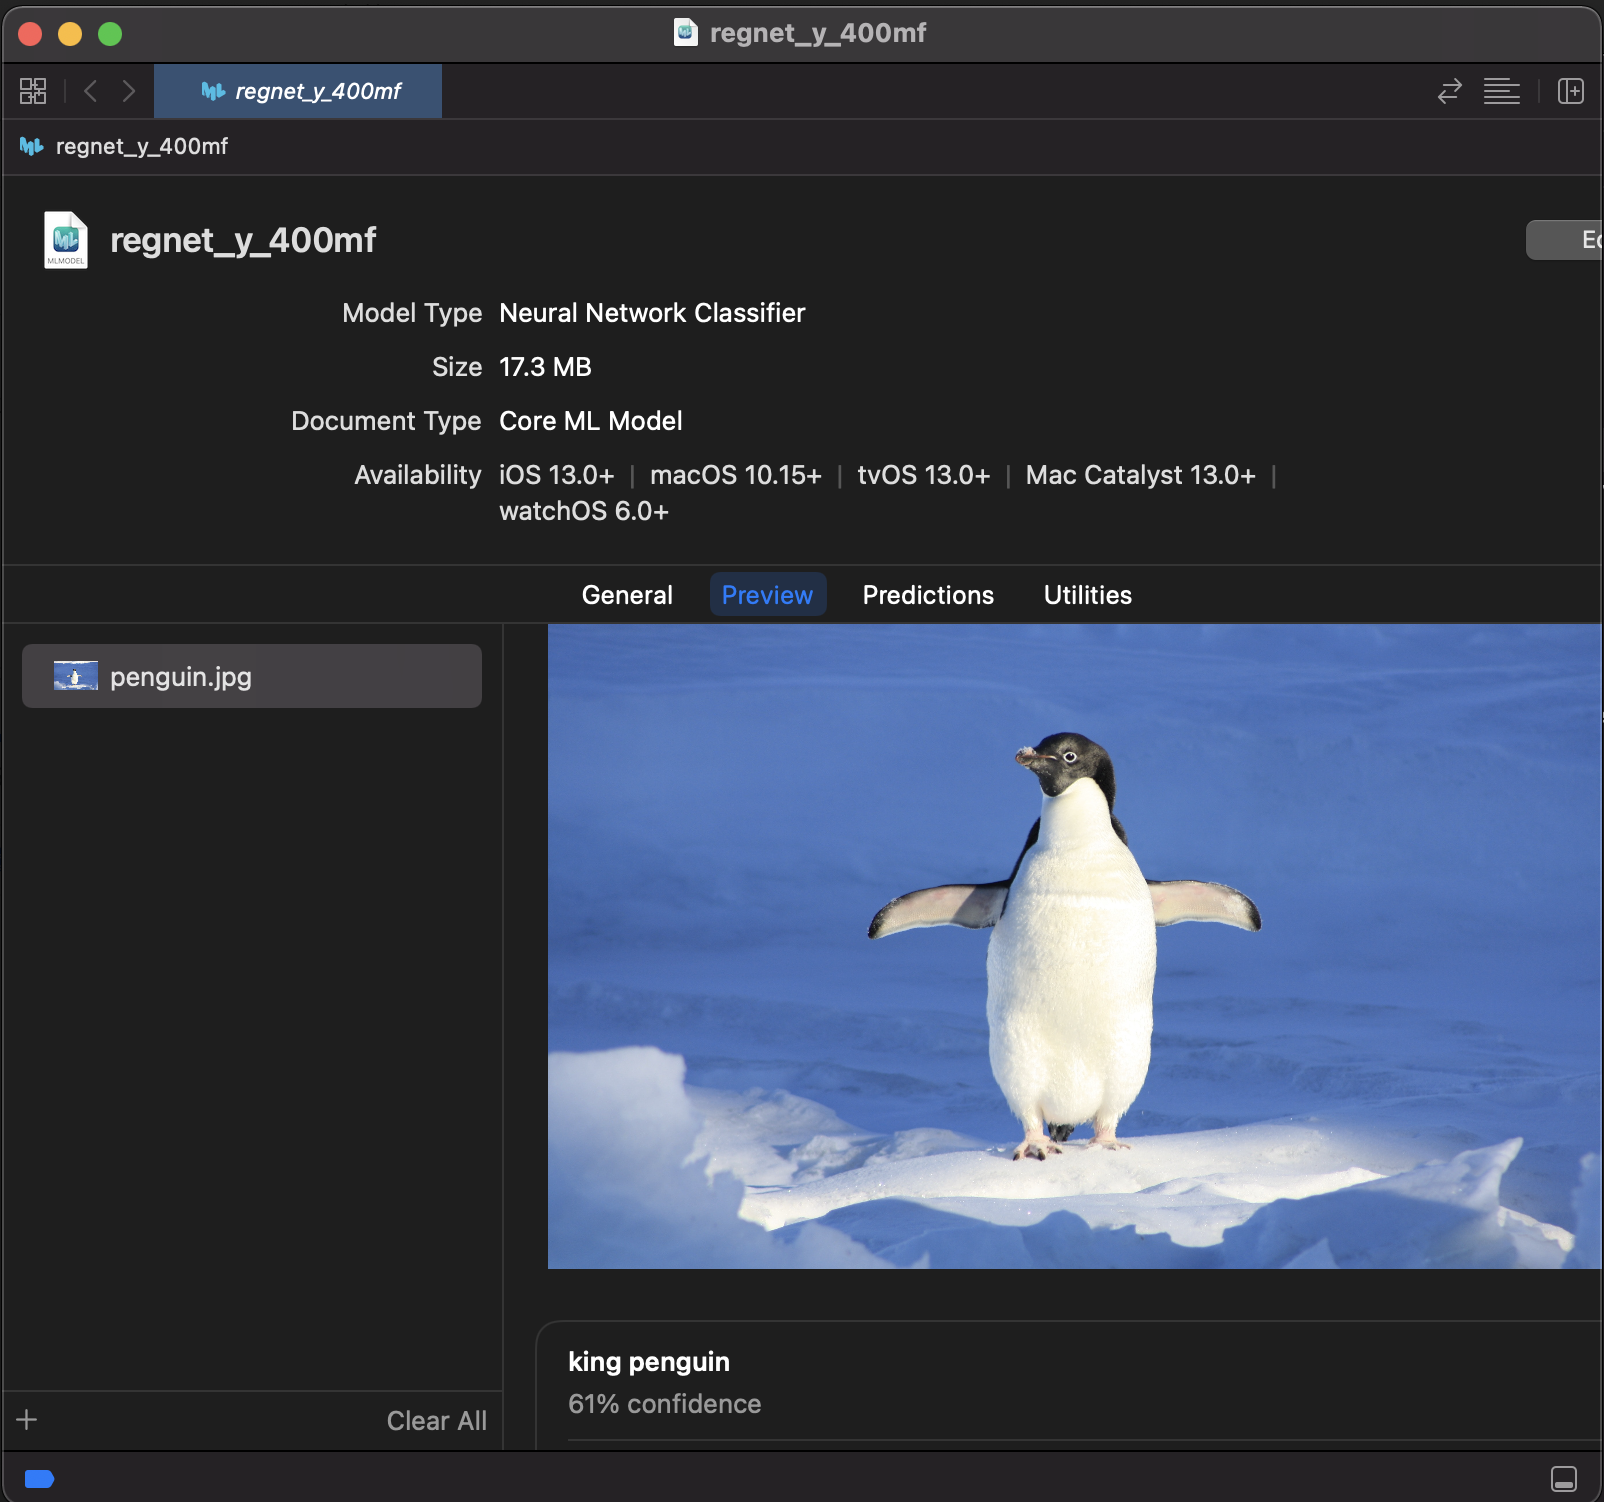
| Google Drive Link | Size | Dataset |Original Project | License |Year| | ------------- | ------------- | ------------- |------------- |------------- |------------- | | regnet_y_400mf | 16.5 MB | ImageNet | TORCHVISION.MODELS | MIT|2020|
CVNets: A library for training computer vision networks
| Google Drive Link | Size | Dataset |Original Project | License |Year|Conversion Script|
| ------------- | ------------- | ------------- |------------- |------------- |------------- |------------- |
| MobileViTv2 | 18.8 MB | ImageNet | apple/ml-cvnets | apple|2022| ) |
| Download Link | Size | Output | Original Project | License | Note | Sample Project | | ------------- | ------------- | ------------- | ------------- |------------- |------------- |------------- | |dfine-n-coco|13MB| Confidence(MultiArray (Float32 300 × 80)), Coordinates (MultiArray (Float32 300 × 4)) |Peterande/D-FINE|Apache 2.0|Input 640×640. Coordinates are normalized cxcywh. No NMS — filter by confidence threshold.| peaceofcake DFINEDemo |
| Download Link | Size | Output | Original Project | License | Note | Sample Project | | ------------- | ------------- | ------------- | ------------- |------------- |------------- |------------- | |rfdetr-n-coco|95MB| Confidence(MultiArray (Float32 300 × 91)), Coordinates (MultiArray (Float32 300 × 4)) |roboflow/rf-detr|Apache 2.0|Input 384×384. 91 classes (index 0 = background, 1-90 = COCO category IDs). Coordinates are normalized cxcywh. No NMS.| peaceofcake DFINEDemo |
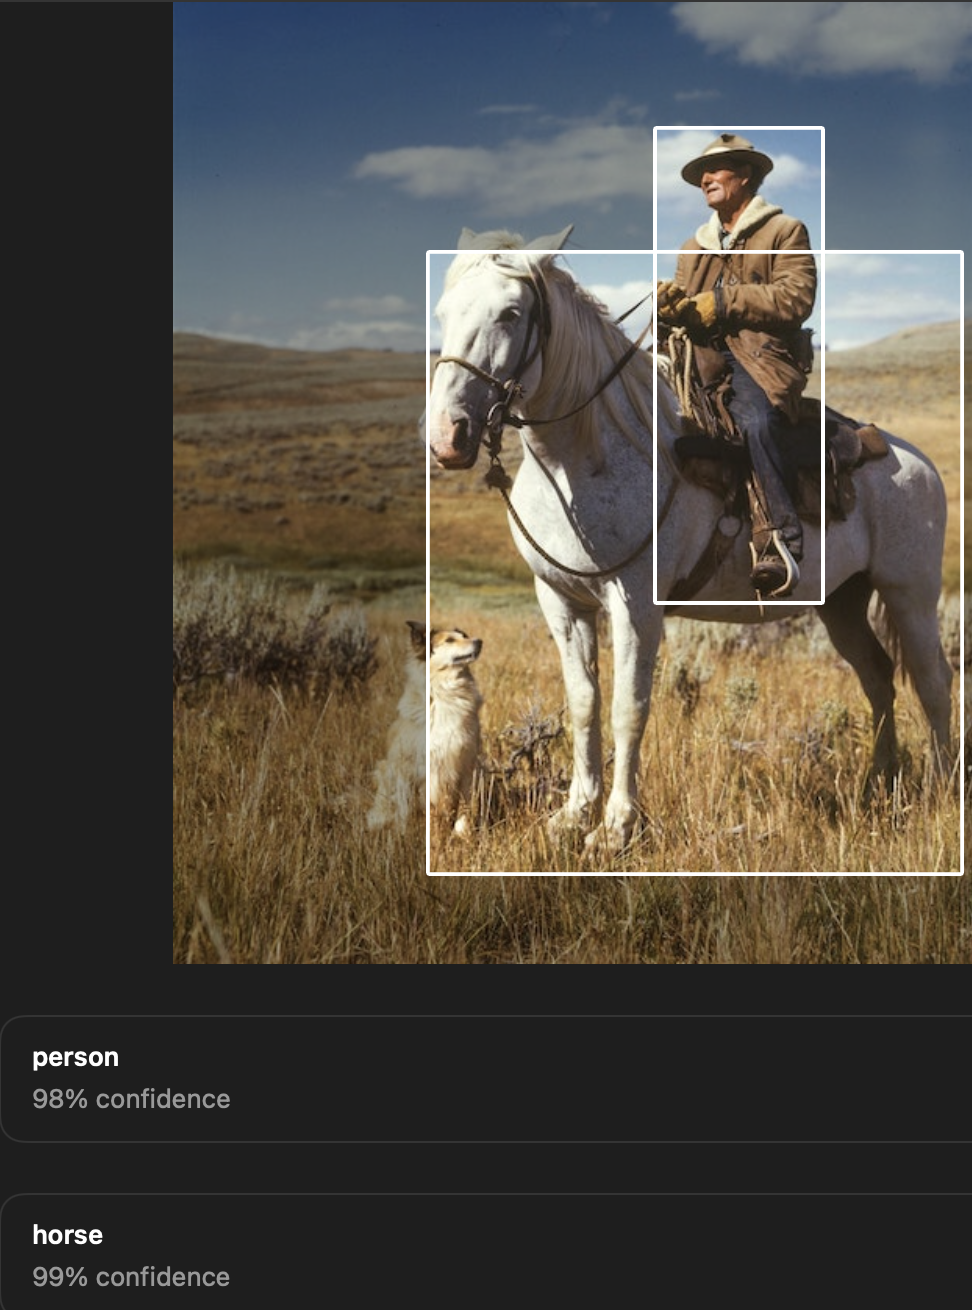
| Google Drive Link | Size | Output | Original Project | License | Note | Sample Project | | ------------- | ------------- | ------------- | ------------- |------------- |------------- |------------- | |YOLOv5s|29.3MB| Confidence(MultiArray (Double 0 × 80)), Coordinates (MultiArray (Double 0 × 4)) |ultralytics/yolov5|GNU|Non Maximum Suppression has been added.| CoreML-YOLOv5 |
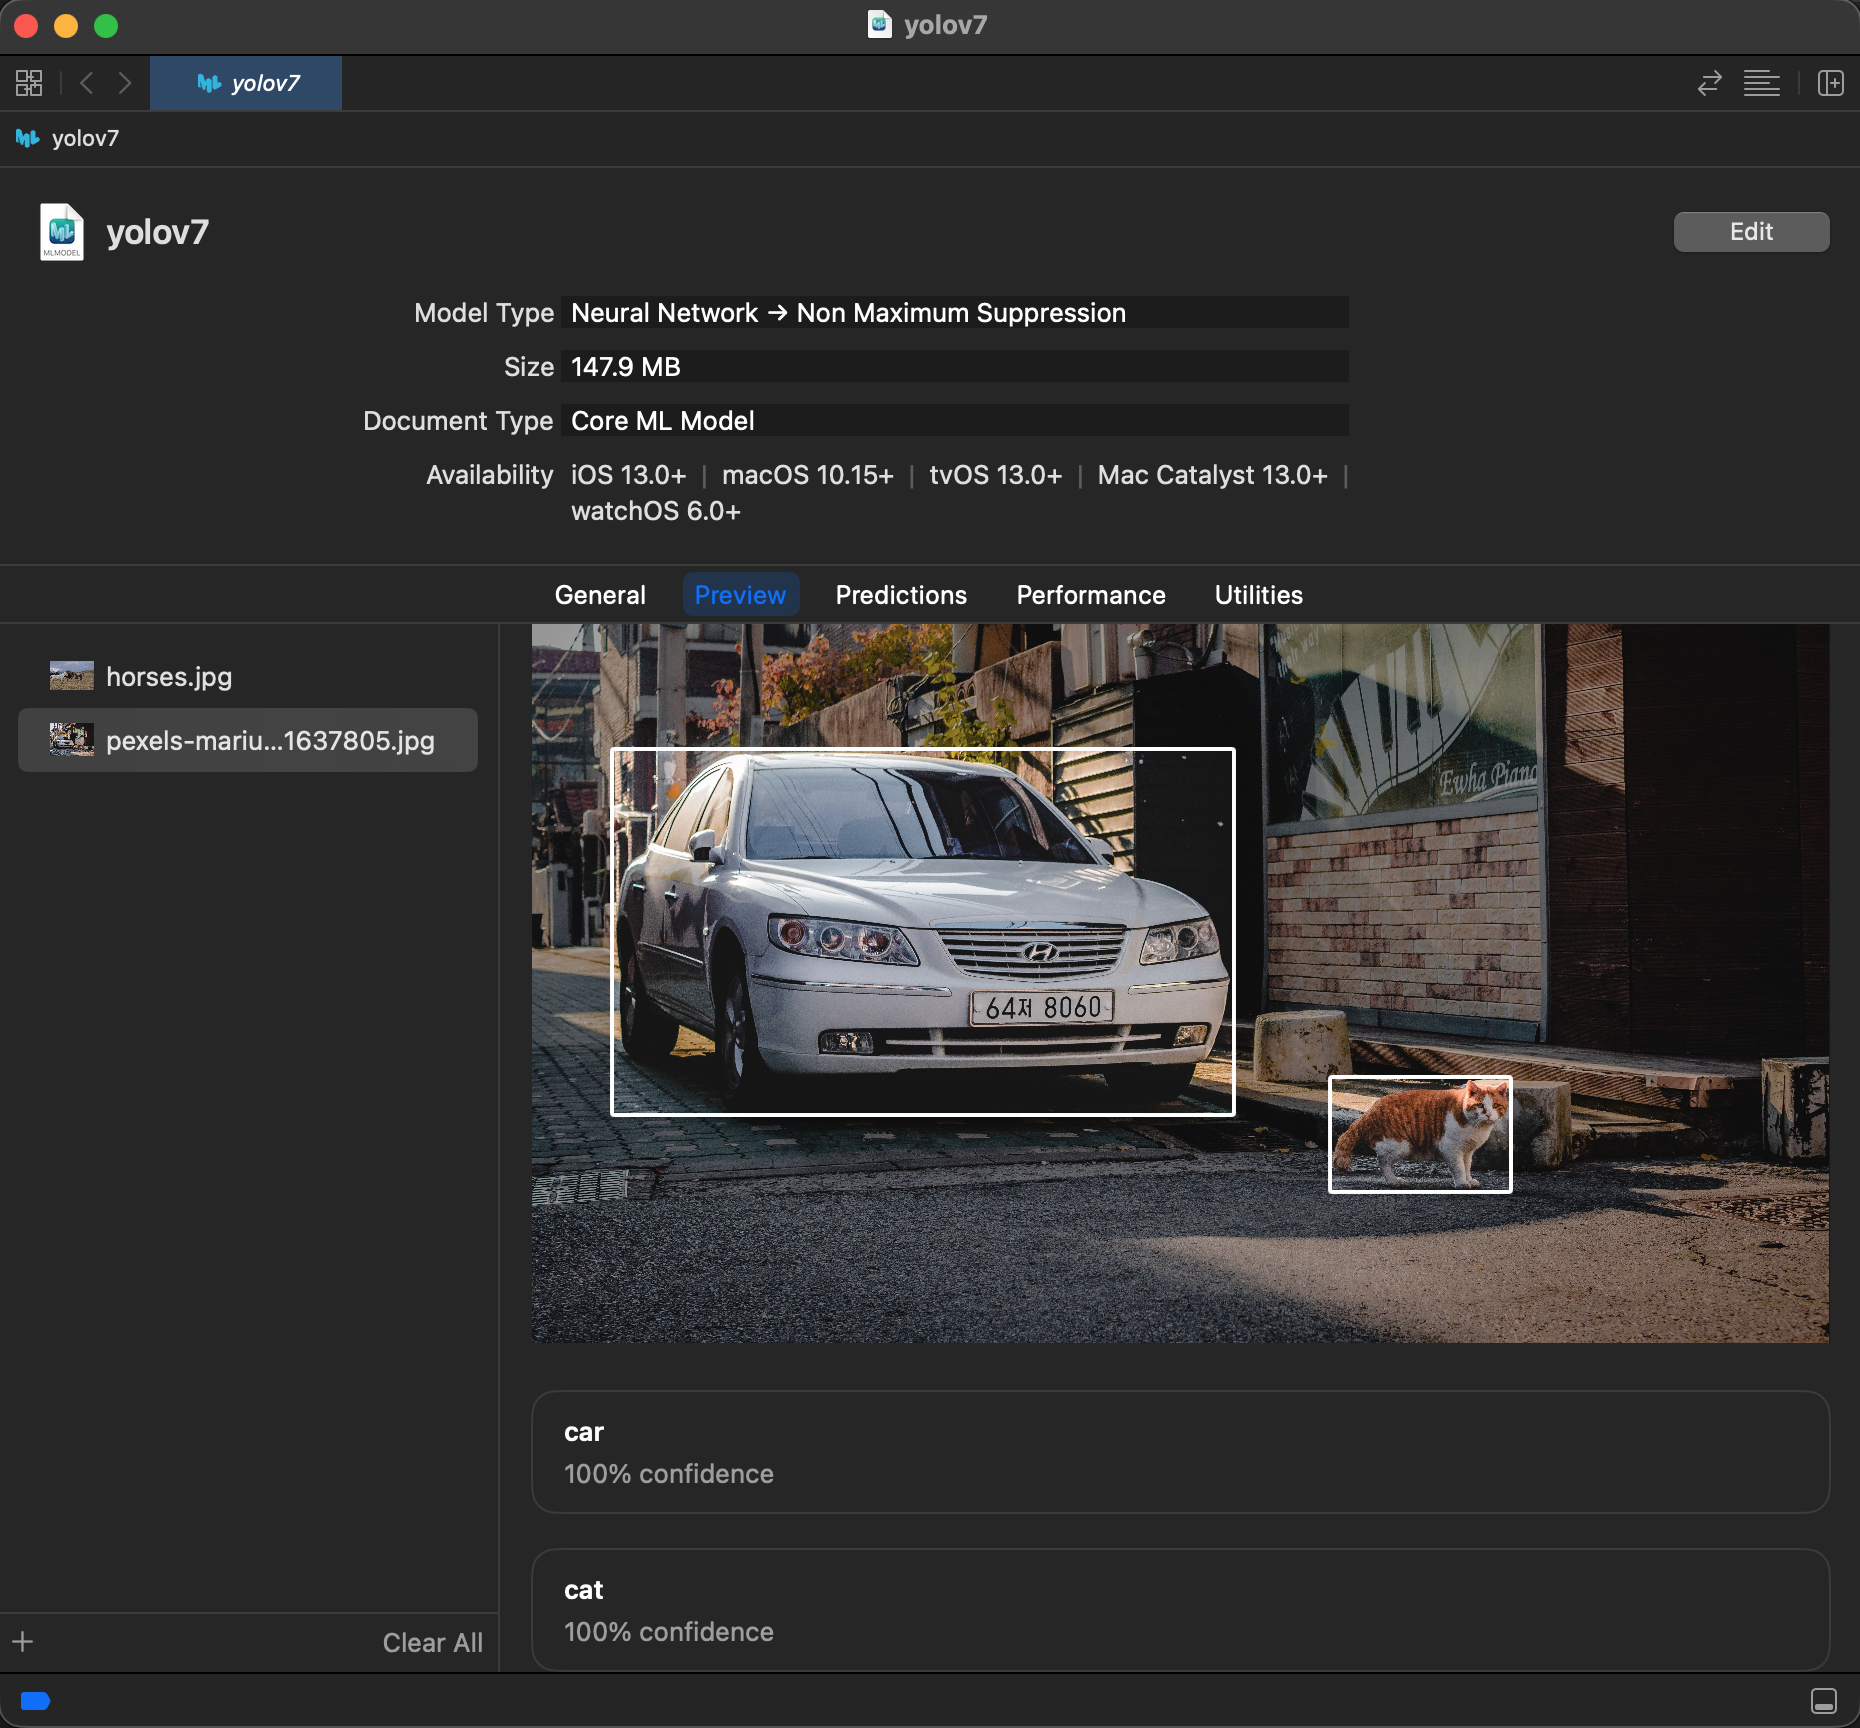
| Google Drive Link | Size | Output | Original Project | License | Note | Sample Project | Conversion Script |
| ------------- | ------------- | ------------- | ------------- |------------- |------------- |------------- |------------- |
|YOLOv7|147.9MB| Confidence(MultiArray (Double 0 × 80)), Coordinates (MultiArray (Double 0 × 4)) |WongKinYiu/yolov7|GNU|Non Maximum Suppression has been added.| CoreML-YOLOv5 | |
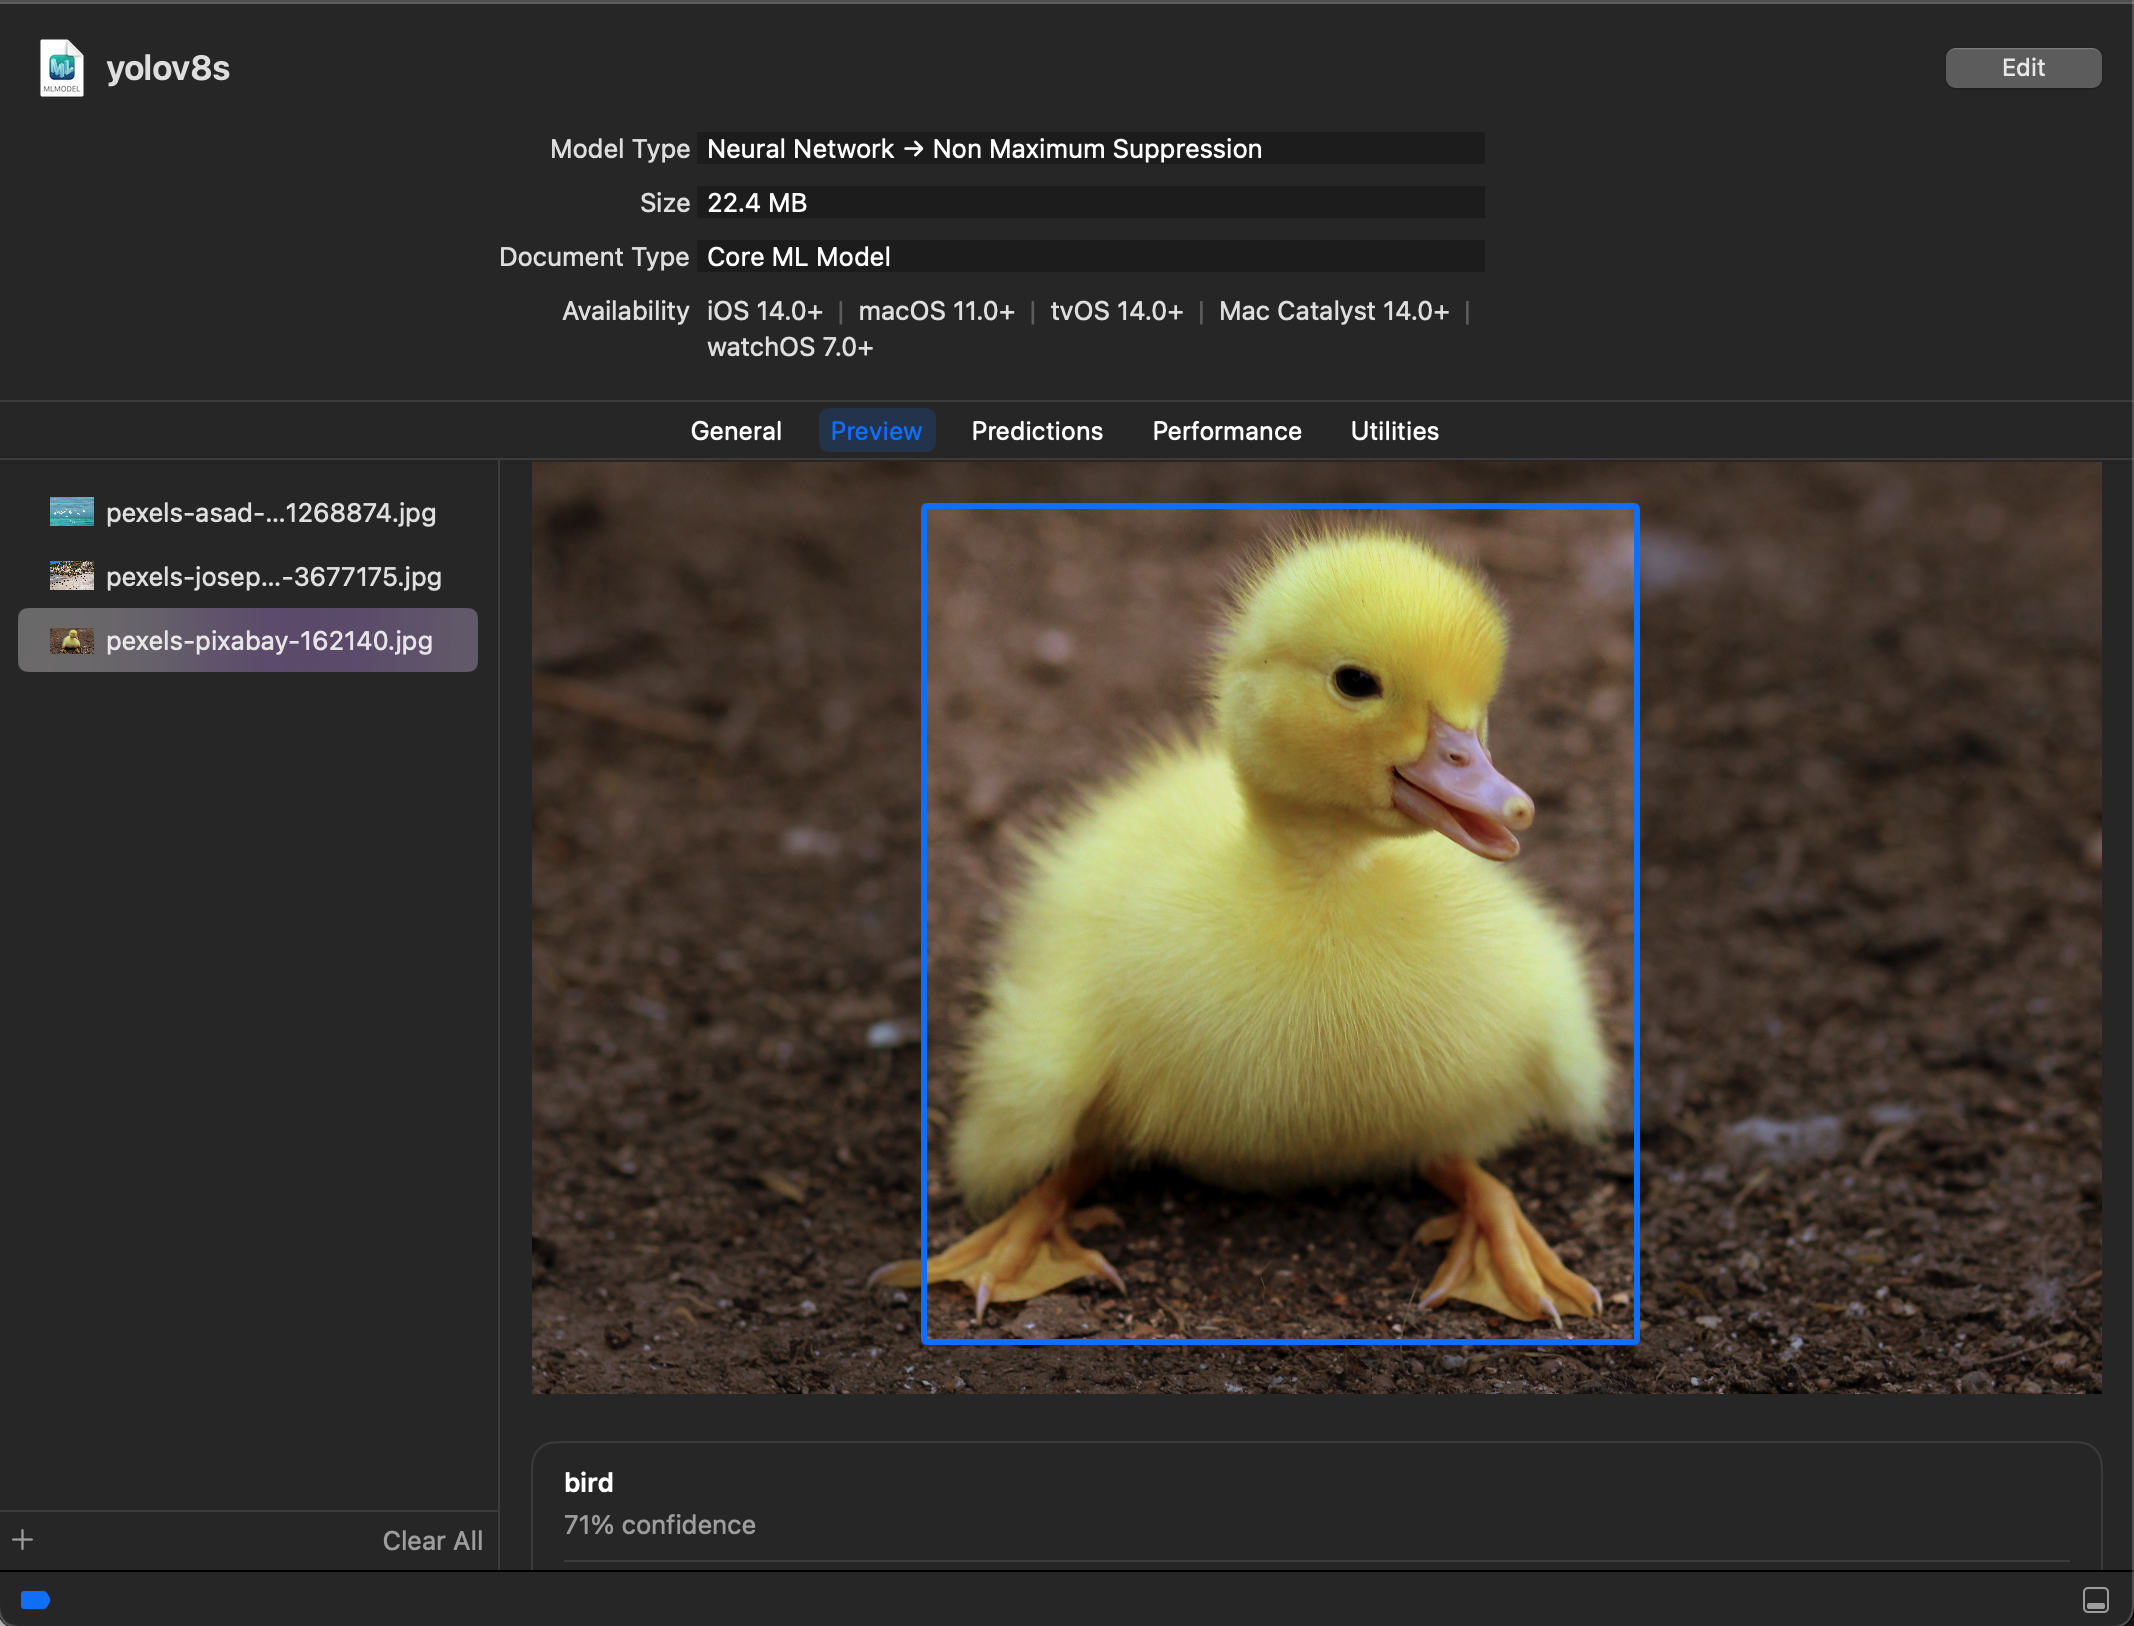
| Google Drive Link | Size | Output | Original Project | License | Note | Sample Project | | ------------- | ------------- | ------------- | ------------- |------------- |------------- |------------- | |YOLOv8s|45.1MB| Confidence(MultiArray (Double 0 × 80)), Coordinates (MultiArray (Double 0 × 4)) |ultralytics/ultralytics|GNU|Non Maximum Suppression has been added.| CoreML-YOLOv5 |
YOLOv9: Learning What You Want to Learn Using Programmable Gradient Information. Uses PGI and GELAN architecture for efficient object detection.
| Download Link | Size | Output | Original Project | License | Year | Note | Sample Project | | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | | yolov9s.mlpackage.zip | 14 MB | Confidence (MultiArray (Double 0 × 80)), Coordinates (MultiArray (Double 0 × 4)) | WongKinYiu/yolov9 | GPL-3.0 | 2024 | Non Maximum Suppression has been added. | YOLOv9Demo |
YOLOv10: Real-Time End-to-End Object Detection. NMS-free architecture using consistent dual assignments — no post-processing needed.
| Download Link | Size | Output | Original Project | License | Year | Note | Sample Project | | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | | yolov10s.mlpackage.zip | 14 MB | MultiArray (1 × 300 × 6) | THU-MIG/yolov10 | AGPL-3.0 | 2024 | NMS-free end-to-end detection. | YOLO26Demo |
YOLO11: Ultralytics latest YOLO with improved backbone and neck architecture. 22% fewer parameters than YOLOv8 with higher mAP.
| Download Link | Size | Output | Original Project | License | Year | Note | Sample Project | | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | | yolo11s.mlpackage.zip | 18 MB | Confidence (MultiArray (Double 0 × 80)), Coordinates (MultiArray (Double 0 × 4)) | ultralytics/ultralytics | AGPL-3.0 | 2024 | Non Maximum Suppression has been added. | YOLOv9Demo |
YOLO26: Edge-first vision AI with NMS-free end-to-end detection. Up to 43% faster CPU inference vs YOLO11 with DFL removal and ProgLoss.
| Download Link | Size | Output | Original Project | License | Year | Note | Sample Project | | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | | yolo26s.mlpackage.zip | 18 MB | MultiArray (1 × 300 × 6) | ultralytics/ultralytics | AGPL-3.0 | 2026 | NMS-free end-to-end detection. | YOLO26Demo |
YOLO-World: Real-Time Open-Vocabulary Object Detection. Type any text query and detect it — no fixed class list. Uses CLIP text encoder for open-vocabulary matching.
| Download Link | Size | Description | Original Project | License | Year | Sample Project | | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | | yoloworld_detector.mlpackage.zip | 25 MB | YOLO-World V2-S visual detector | AILab-CVC/YOLO-World | GPL-3.0 | 2024 | YOLOWorldDemo | | clip_text_encoder.mlpackage.zip | 121 MB | CLIP ViT-B/32 text encoder | openai/CLIP | MIT | 2021 | — | | clip_vocab.json.zip | 1.6 MB | BPE vocabulary for tokenizer | — | — | — | — |
YOLOE: Real-Time Open-Vocabulary Detection + Instance Segmentation. Detect and segment anything from a text query or a visual prompt (box an example object) — no fixed class list. Available in S (fast) and L (accurate). See YOLOEDemo for the region-embedding + MobileCLIP pipeline.
| Download Link | Size | Description | Original Project | License | Year | Sample Project | | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | | yoloe_detector_s.mlpackage.zip | 20 MB | YOLOE-11s-seg region-embedding detector + segmentation | THU-MIG/yoloe | AGPL-3.0 | 2025 | YOLOEDemo | | yoloe_detector_l.mlpackage.zip | 54 MB | YOLOE-11l-seg region-embedding detector + segmentation | THU-MIG/yoloe | AGPL-3.0 | 2025 | YOLOEDemo | | reprta_s.mlpackage.zip | 6 MB | YOLOE RepRTA text-refinement MLP (S) | THU-MIG/yoloe | AGPL-3.0 | 2025 | — | | reprta_l.mlpackage.zip | 6 MB | YOLOE RepRTA text-refinement MLP (L) | THU-MIG/yoloe | AGPL-3.0 | 2025 | — | | visual_prompt_encoder_s.mlpackage.zip | 20 MB | YOLOE SAVPE visual-prompt encoder (S): image + box → query | THU-MIG/yoloe | AGPL-3.0 | 2025 | YOLOEDemo | | visual_prompt_encoder_l.mlpackage.zip | 54 MB | YOLOE SAVPE visual-prompt encoder (L): image + box → query | THU-MIG/yoloe | AGPL-3.0 | 2025 | YOLOEDemo | | mobileclip_blt_text.mlpackage.zip | 121 MB | Apple MobileCLIP B-LT text encoder (shared) | apple/ml-mobileclip | Apple | 2024 | — | | clip_vocab.json.zip | 1.6 MB | BPE vocabulary for tokenizer (shared) | — | — | — | — |
Byt
→ →
 →
 →
 →
 →
 →
 →