1
 →

Run:ai is the AI workload orchestration platform for Kubernetes. This monorepo contains the control plane services, in-cluster Kubernetes operator/controllers, shared libraries and clients
dsx-ai-factory/run-ai is an open-source project on GitHub, mainly written in Go. Run:ai is the AI workload orchestration platform for Kubernetes. This monorepo contains the control plane services, in-cluster Kubernetes operator/controllers It currently holds 736 stars and 120 forks with 254 open issues, and was last pushed on 2026-11-10 (repository created 2026-08-25).
AI Homed tracks it on the Today's Trending board, currently at rank #68 with 5 new stars today.
Docs | Roadmap | Installation | API Reference | Contributing | License
NVIDIA Run:ai is an open-source AI workload and GPU orchestration platform for managing shared AI infrastructure on Kubernetes.
NVIDIA Run:ai provides a consistent way to run development, training, and inference workloads across Kubernetes environments, whether deployed on-premises, in the cloud, or across hybrid infrastructure. It combines GPU scheduling, resource management, workload orchestration, governance, and observability to help organizations share GPU resources efficiently across teams and clusters.
This monorepo contains the NVIDIA Run:ai control plane and cluster services, installer, CLI, MCP server, documentation, shared client packages, and the local development environment.
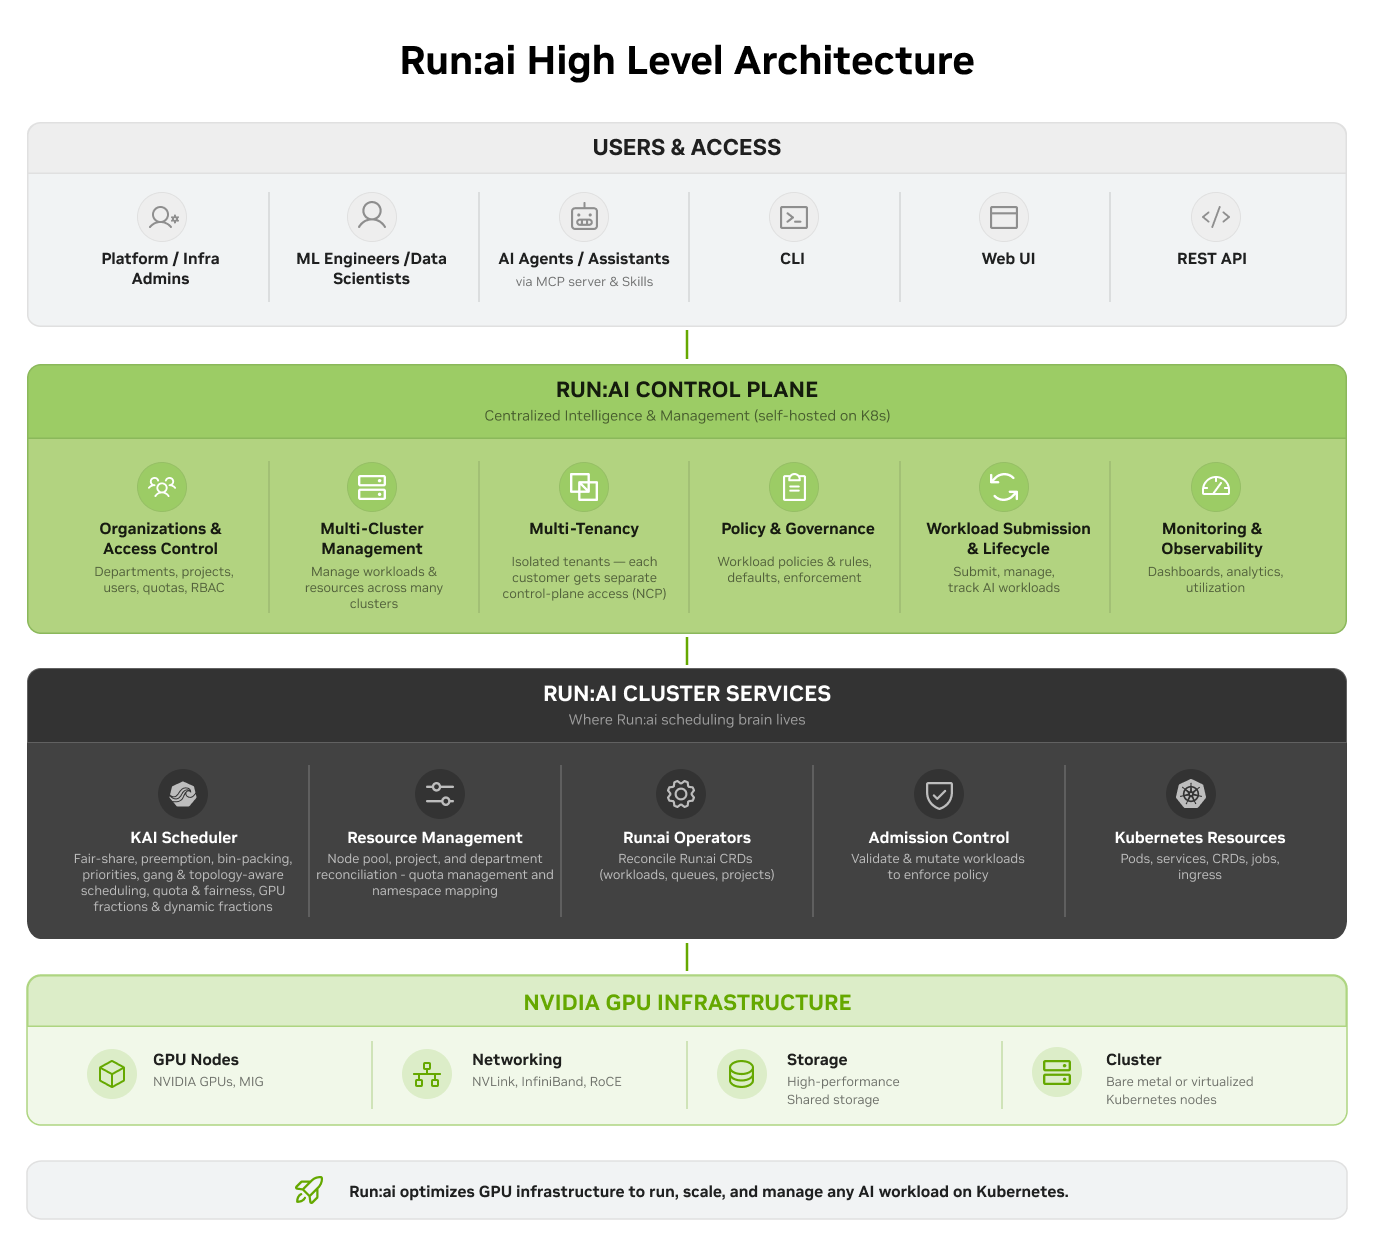
NVIDIA Run:ai is made up of two components, both installed on a Kubernetes cluster:
| Capability | What it does | | --------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------- | | AI-aware GPU scheduling | Schedules GPU workloads using fair-share, preemption, bin-packing, priorities, and topology-aware placement. | | Dynamic GPU allocation | Shares GPU resources across workloads with fractional GPU allocation and dynamic use of available capacity. | | Resource quotas and policies | Allocates GPU resources across departments and projects and enforces organizational resource policies. | | Multi-cluster management | Centrally manages workloads, resources, and configuration across multiple Kubernetes clusters. | | AI workload management | Manages workspaces, training, distributed training, and inference, with extensible support for additional Kubernetes workloads. | | Access control and governance | Controls access to NVIDIA Run:ai resources with role-based permissions and enforces organizational policies across workloads and resources. | | Monitoring and observability | Provides visibility into clusters, nodes, GPUs, workloads, resource utilization, and platform activity. | | Multiple interfaces | Supports NVIDIA Run:ai operations through the web UI, CLI, and REST API. |
NVIDIA Run:ai is a scheduling and orchestration layer on top of Kubernetes: it does not replace Kubernetes, a container runtime, or a CI/CD system.
| Layer | Tools | How NVIDIA Run:ai relates |
|---|---|---|
| Cluster orchestration | Kubernetes, OpenShift | NVIDIA Run:ai runs on these. It extends the cluster with GPU-aware scheduling rather than replacing native scheduling. |
| Schedulers | Default kube-scheduler, Volcano, Kueue | NVIDIA Run:ai ships the KAI Scheduler and adds fair-share, preemption, fractional GPUs, and quota hierarchies across departments and projects. |
| GPU enablement | NVIDIA GPU Operator, Network Operator | Complementary: these expose and configure GPUs on nodes; NVIDIA Run:ai decides which workloads get them and for how long. |
| ML platforms and pipelines | Kubeflow, Ray, Argo Workflows, Slurm | Complementary for the Kubernetes-based ones: they submit workloads, NVIDIA Run:ai schedules and governs the GPU capacity those workloads consume. Slurm is an alternative for HPC-style batch on bare metal. |
| Workload types | Training Operator, LeaderWorkerSet, Knative, KServe | NVIDIA Run:ai integrates with these to manage workspaces, training, distributed training, and inference as first-class workloads. |
If you need GPU sharing, quota enforcement, and multi-tenant governance across teams sharing one Kubernetes GPU estate, that is the gap NVIDIA Run:ai fills. If you only need to run a single team's jobs on dedicated GPUs, native Kubernetes scheduling may be sufficient.
| Component | Path | Description |
| -------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------- |
| Control Plane | control-plane/ | APIs and services that manage workloads, policies, identity, organizational structure, and platform configuration |
| NVIDIA Run:ai Cluster | runai-cluster/ | Controllers, admission webhooks, and services deployed into each managed Kubernetes cluster |
| Installer | runai-installer/ | CLI tool and provisioner service for deploying NVIDIA Run:ai on Kubernetes |
| MCP Server | runai-mcp-server/ | Model Context Protocol server that exposes NVIDIA Run:ai operations as tools for AI assistants |
| Clients and shared packages | runai-clients/, runai-common-packages/, runai-application-packages/ | Generated API clients and shared Go libraries |
| Scale/Load Testing | scale-tests/ | Load-testing SDK and unified load-test suite used to validate platform behavior at scale |
| Documentation | docs/, fern/ | Product and developer documentation |
| Local environment | local-dev.sh, local-dev.md | One-command local Kubernetes (Kind) development environment |
For a detailed breakdown of individual services and components, see the Service Reference.
The local-dev.sh script builds the NVIDIA Run:ai control plane and cluster services from source and deploys them to a self-contained Kind cluster with a local image registry.
./local-dev.sh                                  # full build + cluster + deploy
./local-dev.sh --skip-build --skip-cluster      # re-deploy only
./local-dev.sh --teardown                       # tear the environment down
See Local Development Guide for prerequisites (Docker/Podman, make, git, curl, python3, openssl, and minimum CPU/RAM/disk; kind, kubectl, and helm are installed automatically) and all available flags. Go, Node, and Java are not needed on the host: all builds run inside containers.
Each service directory has a Makefile with standard targets (make build, make test, make lint, make validate) and a README describing how to build, test, and work with that service. See the Service Reference for a breakdown of individual services and components.
NVIDIA Run:ai can be deployed on Kubernetes or OpenShift in connected or air-gapped environments. To understand the full installation lifecycle, see the Installation and Configuration Overview.
Before you start:
runai-installer CLI with a configuration YAML file. The installer performs preflight checks, installs required dependencies, and deploys the NVIDIA Run:ai control plane and cluster.Released NVIDIA Run:ai container images are published to the NVIDIA NGC container registry under nvcr.io/nvidia/runai-oss, and the Helm charts to https://helm.ngc.nvidia.com/nvidia/runai-oss: these are the locations the installer and Helm charts pull from by default. Source releases and their notes are on the GitHub Releases page; see Release Process for how releases are cut and versioned.
Contributions are welcome. Please read Contributing for the development workflow, branch and PR policy, and CI expectations, and Code of Conduct for community guidelines.
NVIDIA Run:ai does not publish a long-range feature roadmap in this repository. What is planned and in progress is tracked in the open:
Known limitations: the root Makefile targets are placeholders; real build, test, and lint targets live in each service directory (see Building Individual Services). The full CI gate runs remotely and is reported back on pull requests as the Validate Successful Run check.
Licensed under the Apache License, Version 2.0; see LICENSE. Third-party attributions are listed in NOTICE and in the per-component NOTICE files.
Trademark notice: Apache 2.0 applies to the software code in this repository. It does not grant permission to use NVIDIA or Run:ai trademarks, logos, product names, fonts, artwork, or other brand assets. Please see Trademarks for details.
Some subdirectories contain vendored third-party code or bundled assets under their own license. Each is listed below with its license and the path to that license file:
| Subdirectory | License | License file |
|--------------|---------|--------------|
| skills/ | Apache-2.0 AND CC-BY-4.0 | skills/LICENSE |
| runai-cluster/cluster/goofys/ | Apache-2.0 | runai-cluster/cluster/goofys/LICENSE.md (attributions in the adjacent NOTICE) |
| control-plane/assets-service/third_party/go_acc/ | Apache-2.0 | .../go_acc/LICENSE |
| control-plane/workloads-and-policies/third_party/kserve/ | Apache-2.0 | .../kserve/LICENSE |
| runai-application-packages/jsonutils/conjungo/ | MIT | .../conjungo/LICENSE |
| runai-application-packages/jsonutils/gojsonq/ | MIT | .../gojsonq/LICENSE.md |
| runai-application-packages/validation/ | MIT | .../validation/LICENSE |
| runai-cluster/cluster/workload-controller/third_party/validation/ | MIT | .../third_party/validation/LICENSE |
| control-plane/frontend/public/static-cli/fonts/ | Apache-2.0 | .../fonts/LICENSE.txt |
The following subdirectories ship an aggregated third-party dependency license report (not a license for their own code):
| Subdirectory | Report |
|--------------|--------|
| runai-cluster/cluster/init-ca/licenses/ | THIRD-PARTY-LICENSES.md (generated by go-licenses) |
→ →
 →
 →
 →
 →
 →→