1
 →

One-click character swap for videos: an open-source, local Higgsfield Genjutsu alternative built on ComfyUI and MiniMax H3, with FLUX.3 Klein relighting.
D3voz/openjutsu is an open-source project on GitHub, mainly written in TypeScript. One-click character swap for videos: an open-source, local Higgsfield Genjutsu alternative built on ComfyUI and MiniMax H3, with FLUX.3 Klein relighting. It currently holds 1,727 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Video Projects board and on the AI AI Video Projects list.
An open-source, Genjutsu-style character and object swap for video. Drop a video and a character photo, press Generate, and the main person in the video is replaced by your character. Or change their hair or clothes, remove something, or put them somewhere else. The camera, cuts, motion and soundtrack stay. Everything runs on open weights on your own GPU: MiniMax H3 for the video, SAM 3.1 to track people, and Qwen3-VL 8B to describe the pictures and shots.
The app is a small Next.js front end over a ComfyUI workflow. It uses @comfyorg/sdk, following Comfy's comfy-reshoot reference app.
https://github.com/user-attachments/assets/2d8d763a-1764-49a6-9116-d6d1be661ff6
| Advanced: several people, pick who becomes who | Object swap: paint where it goes |
| --- | --- |
| 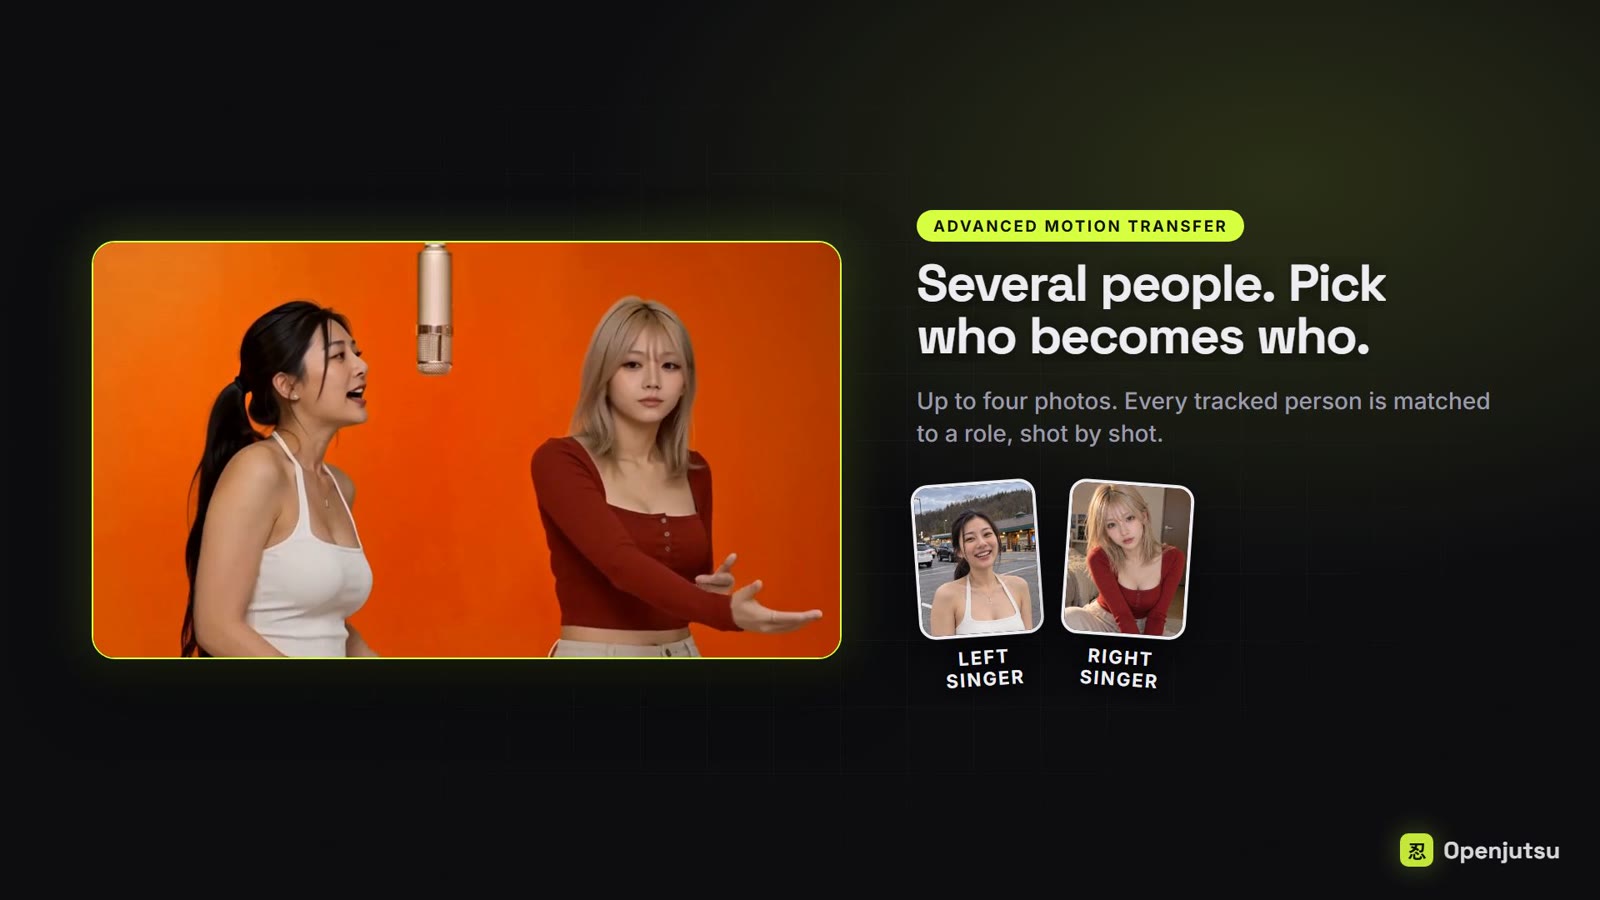 |
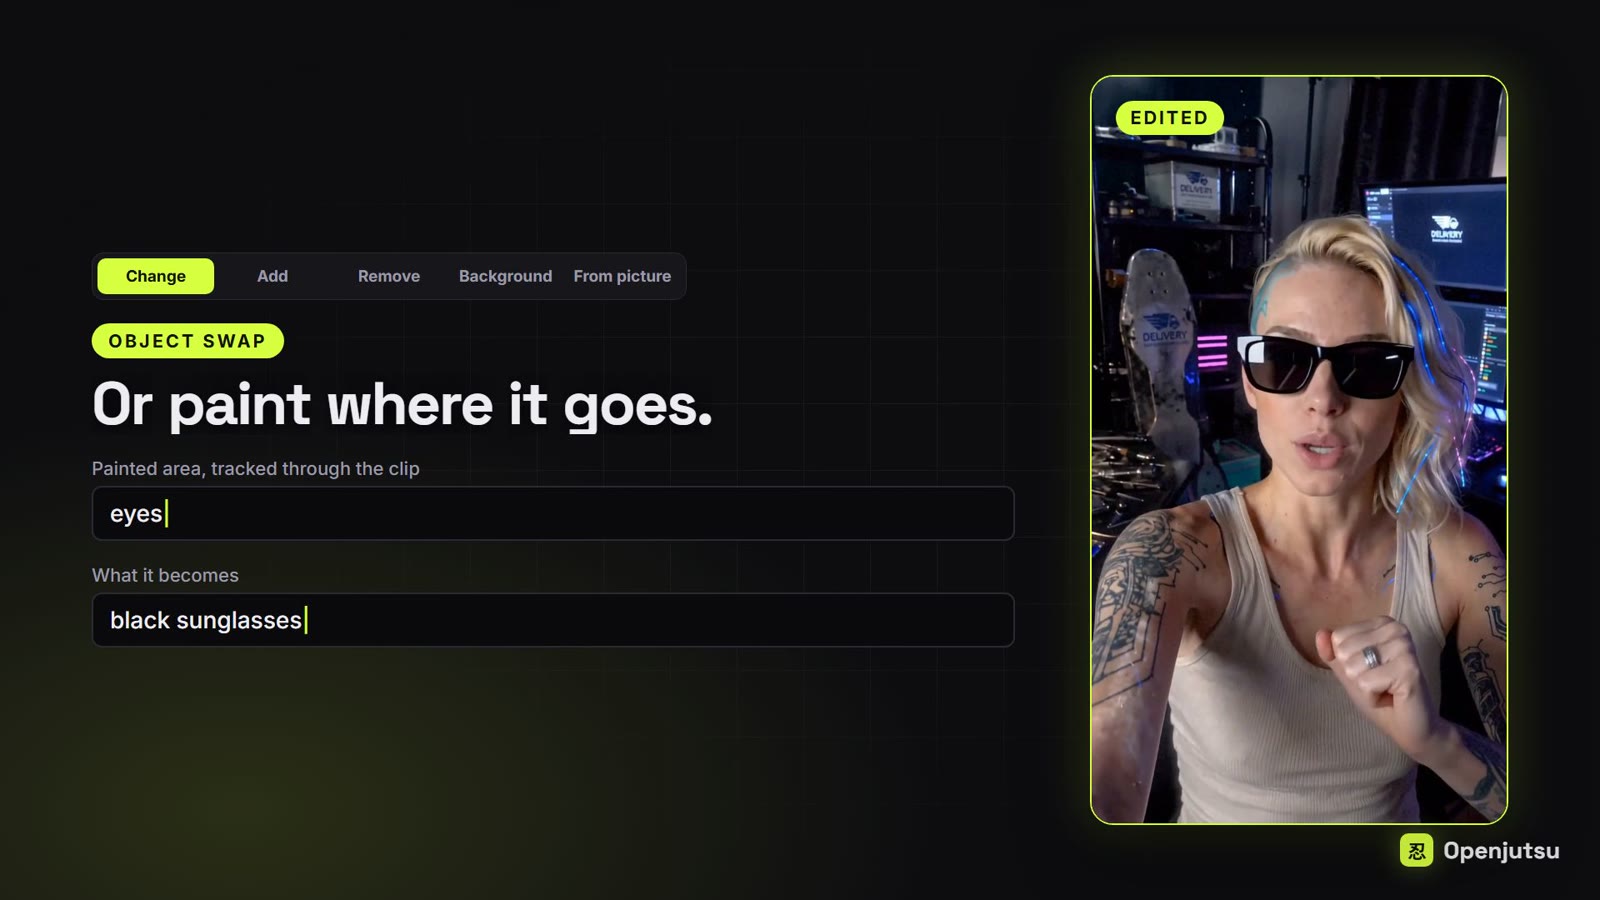 |
| From picture: a new look and place from one picture | Post-processing: fix faces |
|
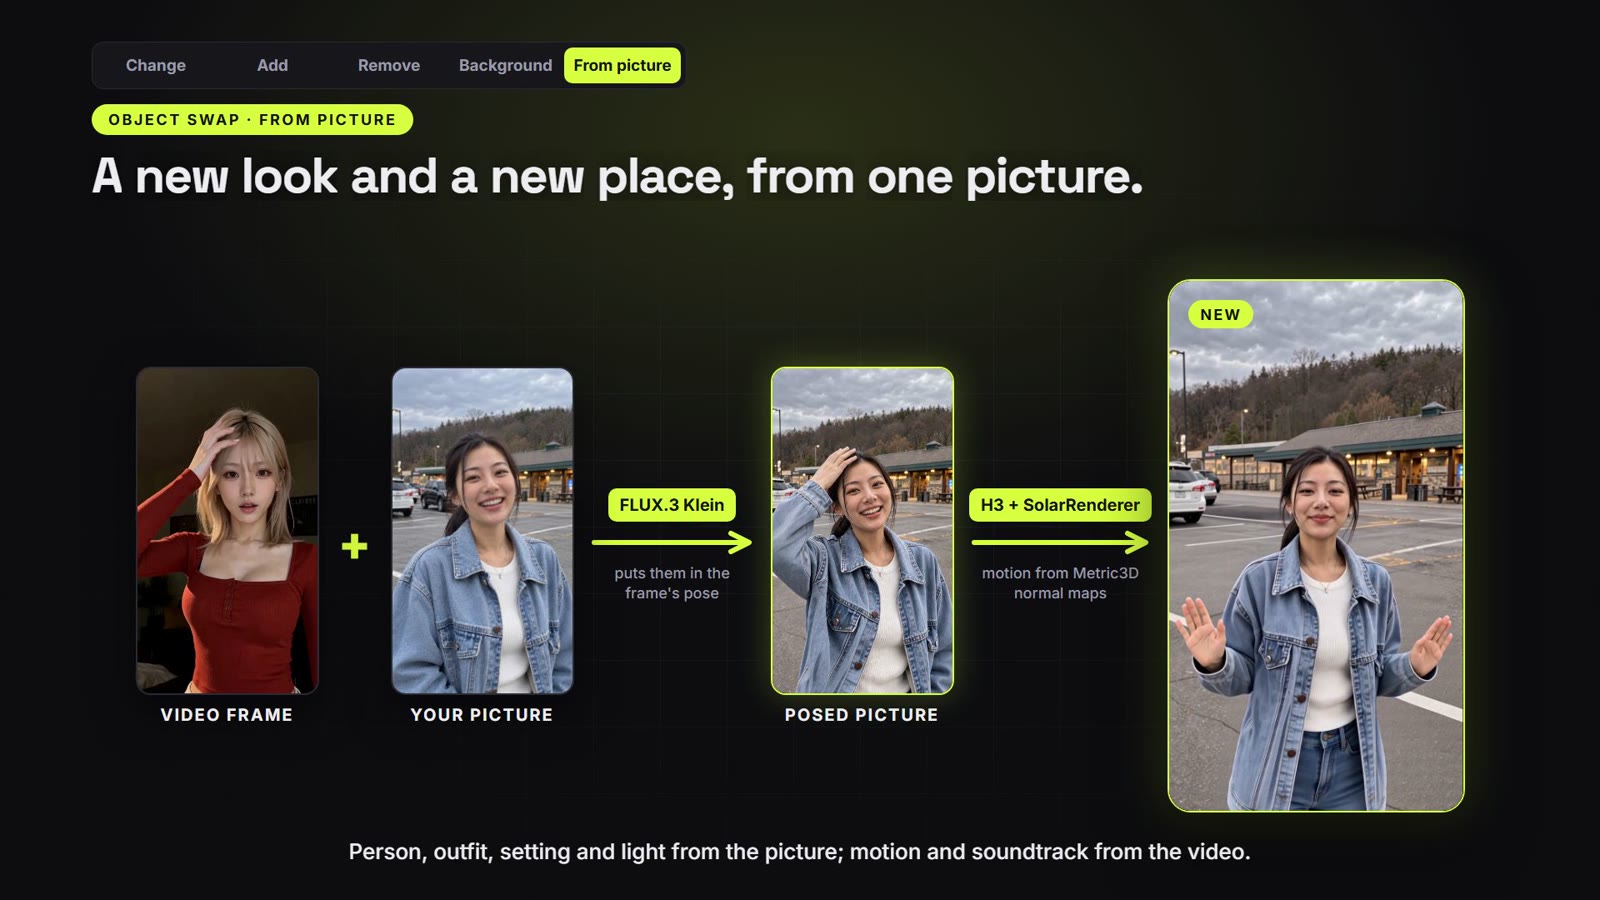 |
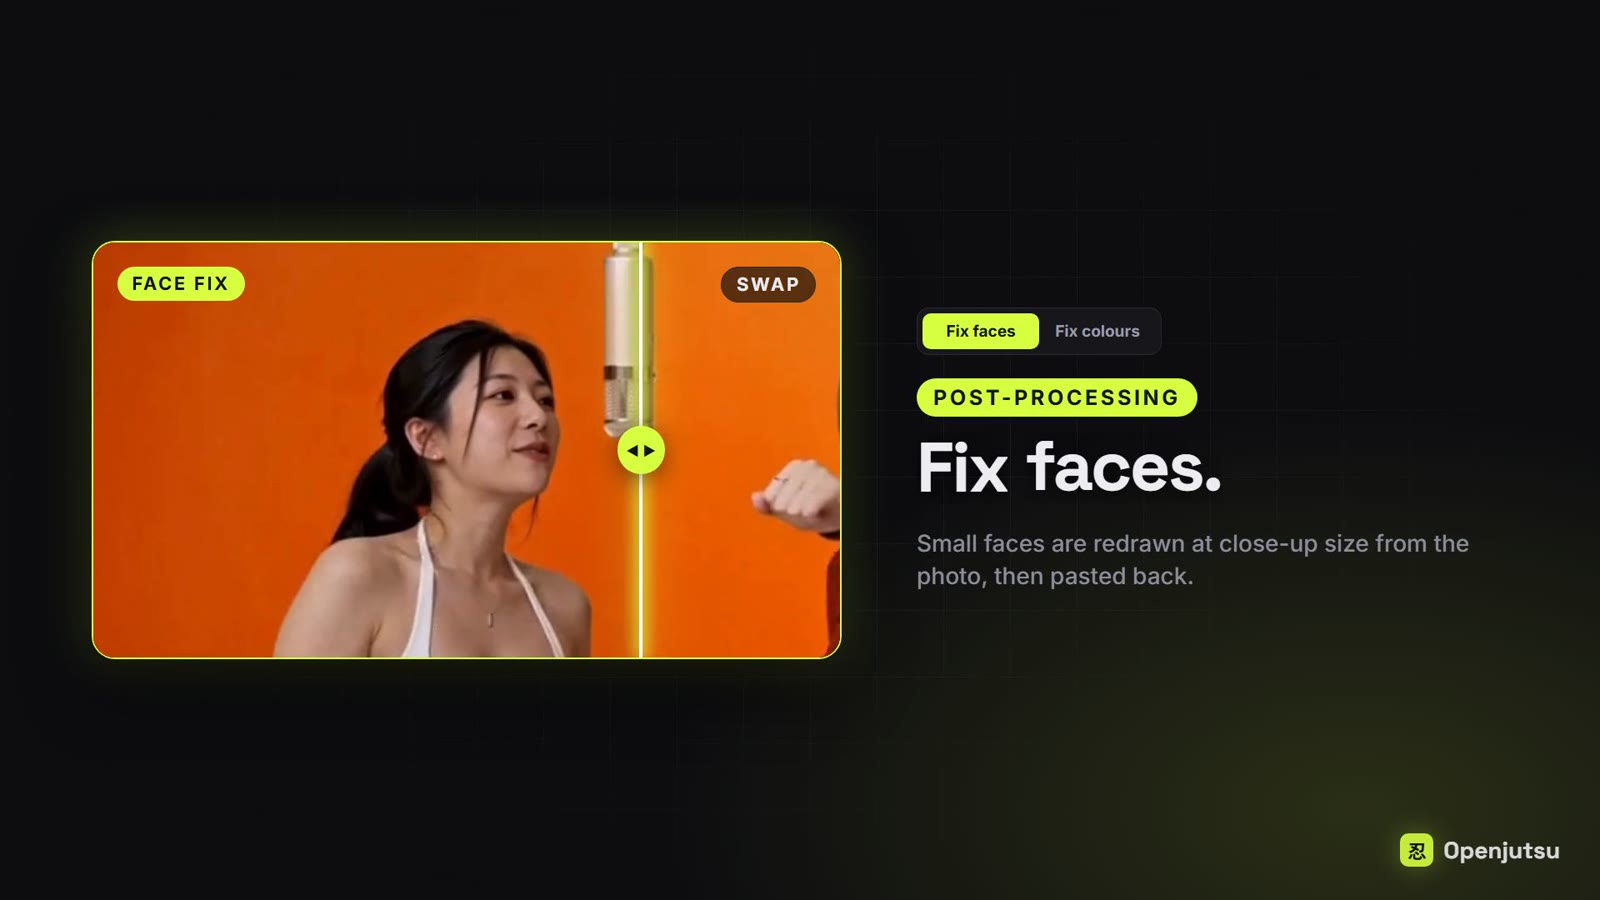 |
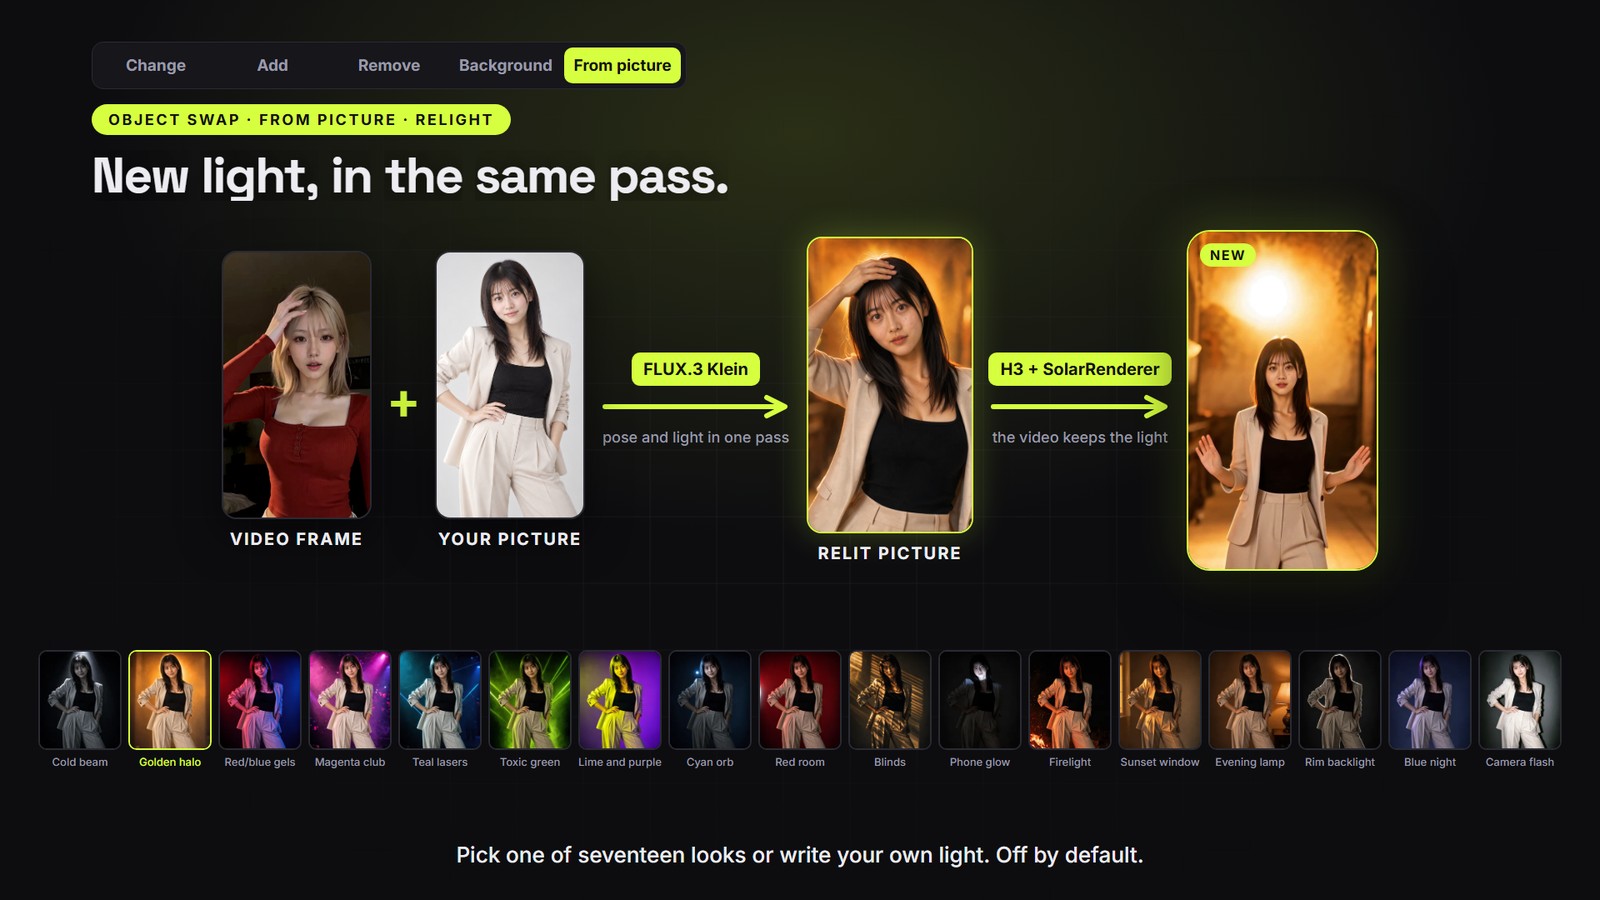
From picture → Relight: new light in the same pass
The welcome page lets you choose the vision-language model that describes pictures and video frames and writes prompts. Qwen3-VL 8B INT8 remains the default; Qwen3-VL 4B FP8 and Gemma 4 E2B INT8 are smaller alternatives. Install a compatible single-file model including its vision weights in ComfyUI/models/text_encoders, then press Refresh models. Other installed models can be selected if they support image/video input and text generation through ComfyUI's CLIPLoader and Generate Text nodes. Text-only models and files requiring a different loader are unsuitable.
Choose according to available VRAM and leave room for image/video context and working memory; file size is not a VRAM requirement, and H3 generation has separate memory needs. Your selection is saved in this browser and used for swaps, prompt descriptions and Find people. Reopen Welcome & models to change it, or use Visual describer under Model components. Alternative describers may change prompt quality and person matching. Set up later opens the editor; generation still checks the required files. The separate H3 text encoder remains unchanged.
workflows/simple.api.json, exported from H3 One-Click Single Swap (DMAD 6 step).json.workflows/advanced.api.json, exported from H3 One-Click Advanced Swap (DMAD 6 step).json; One pass per person (two characters) runs workflows/advanced_maxq.api.json.person stays). Only that area is regenerated. Runs workflows/object.api.json, exported from H3 One-Click Object Swap (DMAD 6 step).json.models/loras and its subfolders. Use this image also has the visual describer watch the part and write what happens (actions, held objects, expressions), then rewrite it for the prepared picture; check and edit that video description before rendering. Render video reuses the saved preview with normal-map motion guidance, the video description and the source soundtrack, in one clip without a context loop. H3 rounds the requested length down to its valid frame grid. Relight (off by default) changes the light in the same FLUX pass: pick one of seventeen looks, each shown with an example picture, or describe your own light. FLUX then sees only your picture, and the Qwen 3.5 9B prompt upsampler reads the pose from the video frame. Magenta club and Teal lasers mostly recolour the background. Relight the video's own person skips the character picture: FLUX relights the video frame itself, keeping its person, pose and setting. See the workflow requirements.workflows/face.api.json, written by workflows/build/openjutsu_face_build.py. Fix colours softens H3's harsh look without an H3 run: Image Detail Contrast takes some fine detail contrast out, then Orion4D's DCTL Tone Mapper grades every frame. Runs workflows/color.api.json.comfy-api-proxy.Install these into ComfyUI/custom_nodes (ComfyUI Manager finds the first three by name):
| Pack | Used for | | --- | --- | | SolarRenderer | From picture: SolarRenderer LoRA loading, conditioning and four-step sampling | | ComfyUI-MiniMaxH3-Context-Loop 0.7.3+ | clip loop, checkpoints, final assembly | | ComfyUI-Fantastic-MiniMaxH3-PromptBuilder | masked video-edit latent | | ComfyUI-KJNodes | Grow Mask With Blur; From picture: VRAM cleanup | | comfyui_controlnet_aux | From picture: Metric3D normal maps | | ComfyUI-VideoHelperSuite | video loading | | comfyui-h3-oneclick-swap | swap and object plans, people and role masks, grey mannequins, track labelling, cut finder, shot list, face-fix chunks | | ComfyUI-H3-FaceRefine | Fix faces: face tracking and cropping, SAM face masks, pasting back | | ComfyUI-Impact-Pack | Fix faces: SAM loader | | comfyui-image-detail-contrast | Fix colours: Image Detail Contrast | | Orion4D_FXMax | Fix colours: DCTL Tone Mapper and its presets | | comfyui-websocket-reconnect-fix | every job: keeps live progress coming after the proxy reconnects to ComfyUI (adds no nodes) |
Restart ComfyUI after installing them.
Before uploading a job, Openjutsu checks the selected workflow against ComfyUI's node and model lists. Missing packs appear with installation links; missing model files appear with their destination folders. Disabled steps are excluded from the check. This checks registered nodes and listed model files, not Python dependencies, model integrity or available VRAM. COMFYUI_URL must point at ComfyUI itself (normally http://127.0.0.1:8188).
For From picture → SolarRenderer, download solarrenderer_4step_lora.safetensors and solarrenderer_control_lora.safetensors from Enderfga/SolarRenderer, or the corresponding rank-64 pair from mdevoz/SolarRendererRank64. Put both in ComfyUI/models/loras or a subfolder, reload the app and choose their paths in the render settings.
| Folder in ComfyUI/models | File |
| --- | --- |
| diffusion_models | minimax_h3_ref2va_pruned_int8_convrot.safetensors |
| loras | minimax_h3_DMAD_4step_full_lora_avg_rank_39_bf16.safetensors |
| text_encoders | qwen3vl_32b_minimax_h3_int4_convrot.safetensors (H3 text encoder) |
| text_encoders | qwen3vl_8b_int8_convrot.safetensors (describer) |
| vae | minimax_h3_video_vae_int8_convrot.safetensors, minimax_h3_audio_vae_fp32.safetensors |
| checkpoints | sam3.1_multiplex_fp16.safetensors |
| ultralytics/bbox, ultralytics/segm | face_yolov8m.pt, person_yolov8m-seg.pt (Bingsu/adetailer), for Fix faces |
| sams | sam_vit_b_01ec64.pth, for Fix faces |
| insightface/models | buffalo_l (InsightFace downloads it on first use), for Fix faces |
On Windows, double-click start_openjutsu.bat (ComfyUI must be running, or started while it waits). The first run installs comfy-api-proxy 0.1.6 into .venv-proxy and the node packages, and patch_proxy.py fixes the proxy's live progress (node changes and mid-job previews). Each run builds the app, then opens the proxy and the app (npm start, the production server) in two windows and the page in your browser. Close those two windows to stop Openjutsu. The manual steps:
1. Start ComfyUI on 127.0.0.1:8188. On Windows, set AIOHTTP_NOSENDFILE=1 first (PowerShell: $env:AIOHTTP_NOSENDFILE = "1"). Without it, the first partial-file request (the video player sends one when you seek) can stall ComfyUI's /view, and every later file download hangs until ComfyUI restarts.
2. Install the proxy, fix its live progress with this repo's patch_proxy.py (run it with the same Python), and start it. It serves the Comfy API v2 on 127.0.0.1:8189. Raise the upload cap for longer videos (the default is 100 MB):
   pip install comfy-api-proxy==0.1.6
   python openjutsu/patch_proxy.py
   comfy-api-proxy run --max-upload-mb 500
3. Install and start the app:
   git clone  openjutsu
   cd openjutsu
   cp .env.example .env.local
   npm ci
   npm run build
   npm start
While changing the code, npm run dev runs the development server instead.
4. Open .
.env.local sets COMFY_BASE_URL=http://127.0.0.1:8189. Leave COMFY_API_KEY empty for a local proxy. The base model and LoRA pickers read ComfyUI's model lists from COMFYUI_URL (default http://127.0.0.1:8188); without it they become text fields.
Uploads are limited to 512 MB total per request, including reference pictures. Uploads are streamed to a temporary folder, and up to three can arrive at once per app process; a fourth is asked to retry shortly. After a job ends, its uploads are removed from comfy-api-proxy, but the files stay in ComfyUI's input/ folder. Generation continues in ComfyUI independently.
A 6 s clip at 480p takes about 6–13 minutes on a 4060 Ti, most of it in H3 sampling. 736p is the default; 1080p is about 2.5× slower than 736p and needs much more memory. Custom sets an exact width × height from 256 to 2048 px a side (rounded to 32); the video is scaled and centre-cropped to that shape first. It needs the short_edge input of the H3 Swap Plan nodes in comfyui-h3-oneclick-swap.
Advanced motion transfer has a Montage tab for edited clips where different people take turns within one shot without a hard cut (whip pans, selfie handovers, travel montages). Write roles as "who - looks" ("the dancer - white polo, jeans"): the looks help match the people, and only the part before " - " reaches H3. Generate tracks everyone with SAM over the whole video, matches each appearance to the roles with Qwen (a person SAM loses and finds again is matched again, so they keep their photo; Qwen sees each appearance in its frame and close up at three moments, a few appearances at a time, and is asked again about any it skips or matches to one photo twice at the same moment) and makes the video as one chain like Standard, with overlapping clips: each clip has one H3 pass per photo on screen in it (the two with the most screen time) that masks only that photo's appearances, with a prompt about that person only. Appearances on screen for under 12 frames or at under 2% of the frame stay as they are, since H3 draws them as grey figures; the result page lists them. Find people (about 3 minutes for 18 s of video) is the optional review: it does the tracking and matching alone, lists the appearances with a photo picker each and saves the tracks, and Generate from that list masks with exactly those tracks. The saved tracks live in ComfyUI's temp folder and are checked against the video, part and size, so after a ComfyUI restart or a change, Find people again. It needs the pack's H3TrackCrops and H3TrackRoles (which now runs Qwen itself), H3MontagePeople, H3MontageTracks, H3MontagePicks, H3MontagePlan and H3MontagePass nodes.
comfyui-h3-oneclick-swap and restart ComfyUI for H3PaintedEditArea.a chocolate cake on a plate) and where it goes (on the table). Draw a box covering the whole object and its shadow in the placement editor. An optional reference picture controls its appearance. One box stays fixed on screen; for camera movement, scrub forward and draw more boxes to animate the placement. This uses manual placement keyframes, not SAM tracking. Changing the source video, selected section or resolution clears the boxes. Update comfyui-h3-oneclick-swap and restart ComfyUI to load the new H3ObjectPlacementMask node.the singer), never by clothes: clothing words leak into the result. Leave it blank and the describer names them.person by default, an animal such as cat, or a short description (black and white cat) when the biggest match is the wrong one. The biggest match in the frame is replaced.hair, jacket, poster), or several separated by commas (hair, top) to change them together. Every match changes unless Only the biggest one is on (one of each thing). A picture of an outfit, hairstyle, product or place is copied onto it. For Remove, say what shows instead only when it is not obvious (a plain wall). Mask margin is smaller here (10, 20 or 40 px). Change keeps the outline of what it replaces: a tank top turned into a flannel shirt stays sleeveless.H3 soft.json in Orion's presets/color_fx_dctl_tone_mapper folder to have it in the list; without it the page uses its built-in copy. A 1.75 s 480p clip took 5 s. The video is read at 24 fps.the drummer, optionally with how they look after - (the drummer - man in a cap); the look only helps match people and never reaches H3. One pass per person gives each of two characters their own H3 pass with only their photo (about twice the time). Check mask is Simple-only for now.Each clip, SAM 3.1 tracks everyone at 1008 px (its own working size), and H3 People Mask keeps the largest person. The edit mask adds 10% headroom above the head, holds each pose for 2 frames and grows by 40 px, so a differently built character has room; it does not affect the motion. The motion reference H3 follows is the source clip with that person turned into a sharp grey mannequin of their exact silhouette, so the pose, arms and fingers stay readable.
workflows/simple.api.json is one API export of that workflow with the hat fix and No lip-sync enabled. For each request, lib/simple.ts:
lib/model.ts then sets the Swap Plan's steps and the H3 Diffusion Model file, and replaces the DMAD LoRA node with the chosen LoRAs in a chain (or links the model straight through when there are none). Advanced mode does the same.
lib/comfy.ts binds the uploaded video to VHS_LoadVideo and the photo to the LoadImage node, then submits with the SDK. /api/jobs/[id]/events reads the job's raw event stream (the SDK's low-level getJobEvents) and forwards it to the page as server-sent events. Node ids are turned into node titles and clip numbers there: each clip after the first is a graph expansion of the loop, whose node ids carry a prefix per clip (64, 66.0.0.64, 66.0.0.Recurse.0.0.64 for Save Clip in clips 1–3). The final MP4 is the output of the Final Video node (MiniMaxH3ChainAssemble, node 67).
workflows/mask.api.json is the mask check: the same SAM, People Mask and grow settings over the whole video, with the mask tinted over the frames next to the mannequin, saved as an MP4.
Advanced mode labels the people before it masks them. Per clip, H3 Track Crops shows each SAM track once per shot (the person alone, and the frame with them boxed) to Qwen3-VL 8B, which names the subject or "other"; H3 Track Roles reads that answer and settles a subject named twice in one shot by colour. H3 Role Mask builds the edit mask from the labelled tracks only, and the shot-list describer sees each labelled person outlined in their subject's colour, so the prompt names the same people the masks do. lib/advanced.ts finds nodes by title, drops unused picture branches and, without the hat fix or No lip-sync, their nodes; the exports are made from workflows/build/oneclick_advanced_build.js with every optional group on.
Object swap uses the same masked edit for the tracked things; SAM 3 tracks each comma-sep
→ →
 →
 →
 →
 →
 →
 →