1
 →

[ICLR 2026] LightMem: Lightweight and Efficient Memory-Augmented Generation
zjunlp/LightMem is an open-source project on GitHub, mainly written in Python. [ICLR 2026] LightMem: Lightweight and Efficient Memory-Augmented Generation It currently holds 1,168 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Agent Memory board.

---
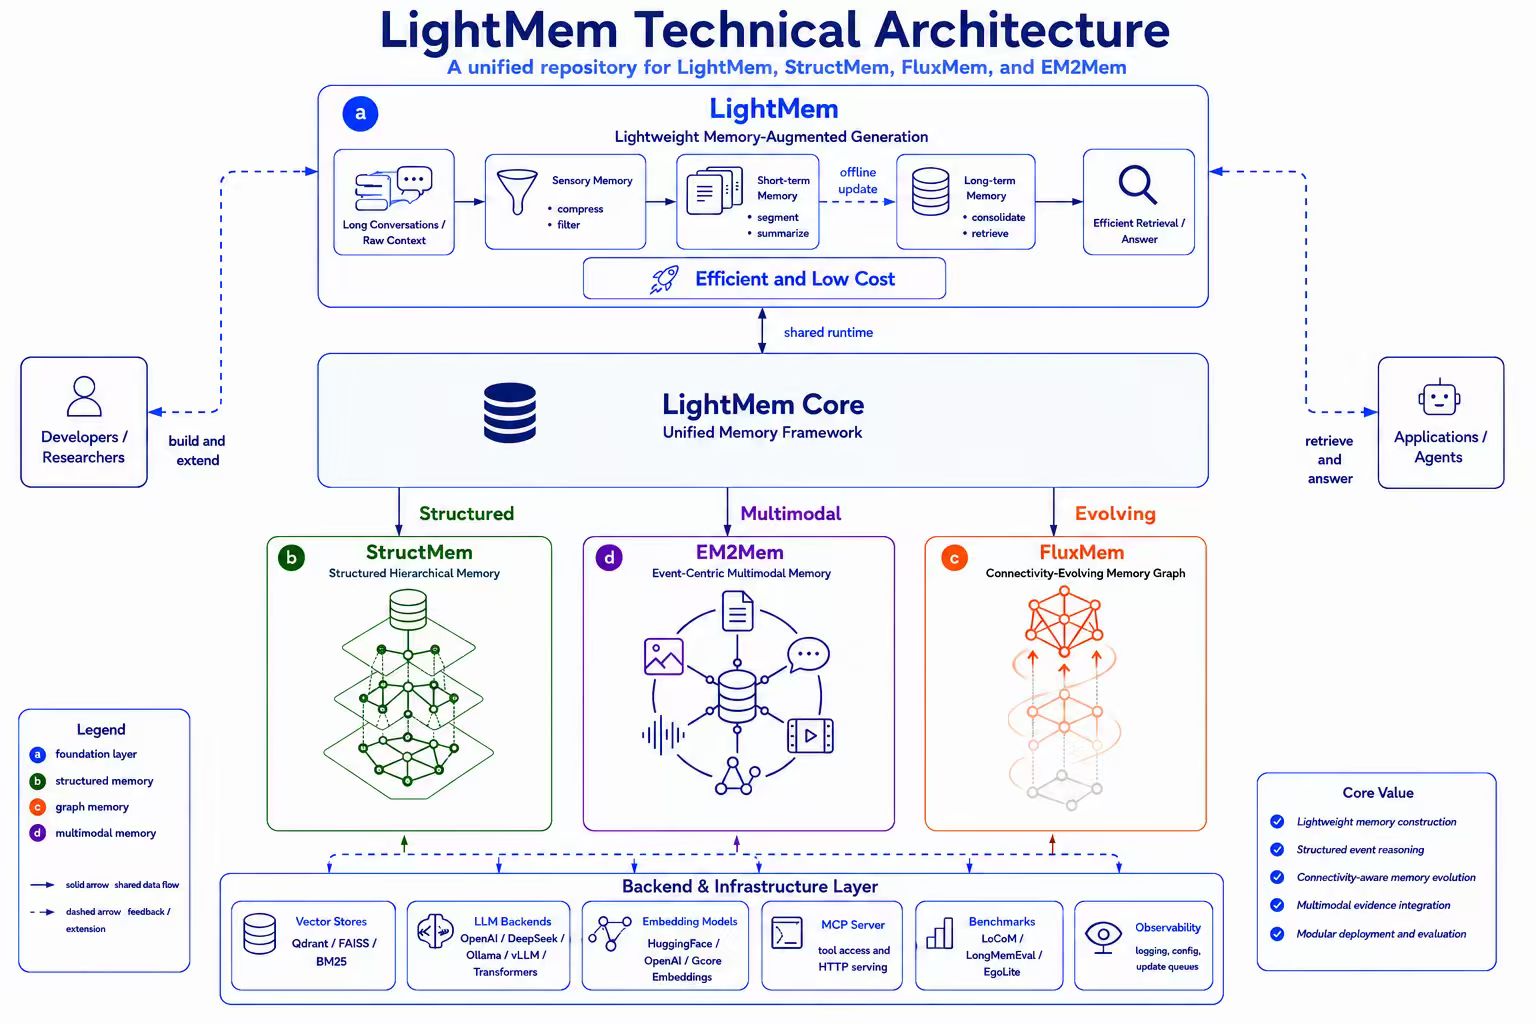
LightMem is a lightweight and efficient memory management framework designed for Large Language Models and AI Agents. It provides a simple yet powerful memory storage, retrieval, and update mechanism to help you quickly build intelligent applications with long-term memory capabilities.
deepseek-v4-flash and deepseek-v4-pro, with reasoning_effort and thinking-mode configuration!This repository hosts multiple memory methods. The table below provides an overview and links to each method's documentation:
| Method | Description | Paper | Documentation | | :--- | :--- | :--- | :--- | | LightMem | Lightweight and efficient memory-augmented generation framework | ICLR 2026 | README.md | | FluxMem | Connectivity-evolving memory framework modeling memory as a heterogeneous graph | arXiv (under review at EMNLP 2026) | FluxMem.md | | EM²Mem | Event-centric multimodal memory for long-video question answering | Coming soon | EM2Mem.md | | StructMem | Structured hierarchical memory preserving event-level bindings and cross-event connections | ACL 2026 | StructMem.md |
We provide lightweight, ready-to-run scripts for reproducing results on LoCoMo, LongMemEval, and their combined baselines.
| Dataset | Description | Script | Result | | :----------------------- | :--------------------------------------------------------------------------- | :--------------------------------------------------------------------------------------------------------------| :---------------------------------------------| | LongMemEval | Run LightMem on LongMemEval, including evaluation and offline memory update. | run_lightmem_longmemeval.md | LongMemEval Results | | LoCoMo | Scripts for reproducing LightMem results on LoCoMo. | run_lightmem_locomo.md | LoCoMo Results | | LongMemEval & LoCoMo | Unified baseline scripts for running both datasets. | run_baselines.md | Baseline Results |
We provide a comprehensive baseline evaluation framework, supporting the benchmarking of memory layers such as Mem0, A-MEM, and LangMem on multiple datasets like LoCoMo and LongMemEval.
Watch Demo: YouTube | Bilibili
tutorial-notebooks directory.
| Scenario | Description | Notebook Link | | :--- | :--- | :--- | | Travel Planning | A complete guide to building a travel agent with memory. | LightMem_Example_travel.ipynb | | Code Assistant | A complete guide to building a code agent with memory. | LightMem_Example_code.ipynb | | LongMemEval | A tutorial on how to run evaluations on LongMemEval benchmarks using LightMem. | LightMem_Example_longmemeval.ipynb |
# Clone the repository
git clone https://github.com/zjunlp/LightMem.git
cd LightMem
Create virtual environment
conda create -n lightmem python=3.11 -y
conda activate lightmem
Install dependencies
unset ALL_PROXY
pip install -e .
pip install lightmem # Coming soon
1. Modify the JUDGE_MODEL, LLM_MODEL, and their respective API_KEY and BASE_URL in API Configuration.
2. Download LLMLINGUA_MODEL from microsoft/llmlingua-2-bert-base-multilingual-cased-meetingbank and EMBEDDING_MODEL from sentence-transformers/all-MiniLM-L6-v2 and modify their paths in Model Paths.
3. Download the dataset from longmemeval-cleaned, and modidy the path in Data Configuration.
cd experiments
python run_lightmem_qwen.py
LightMem/
├── src/lightmem/            # Main package
│   ├── __init__.py          # Package initialization
│   ├── configs/             # Configuration files
│   ├── factory/             # Factory methods
│   ├── memory/              # Core memory management
│   └── memory_toolkits/     # Memory toolkits
├── mcp/                     # LightMem MCP server
├── experiments/             # Experiment scripts
├── datasets/                # Datasets files
└── examples/                # Examples
The following table lists the backends values currently recognized by each configuration module. Use the model_name field (or the corresponding config object) to select one of these backends.
| Module (config) | Supported backends |
| :--- | :--- |
| PreCompressorConfig | llmlingua-2, entropy_compress |
| TopicSegmenterConfig | llmlingua-2 |
| MemoryManagerConfig | openai, deepseek, ollama, vllm, etc. |
| TextEmbedderConfig | huggingface |
| MMEmbedderConfig | huggingface |
| RetrieverConfig | qdrant, FAISS, BM25 |
import os
from datetime import datetime
from lightmem.memory.lightmem import LightMemory
LOGS_ROOT = "./logs"
RUN_TIMESTAMP = datetime.now().strftime("%Y%m%d_%H%M%S")
RUN_LOG_DIR = os.path.join(LOGS_ROOT, RUN_TIMESTAMP)
os.makedirs(RUN_LOG_DIR, exist_ok=True)
API_KEY='your_api_key'
API_BASE_URL='your_api_base_url'
LLM_MODEL='your_model_name' # such as 'gpt-4o-mini' (API) or 'gemma3:latest' (Local Ollama) ...
EMBEDDING_MODEL_PATH='/your/path/to/models/all-MiniLM-L6-v2'
LLMLINGUA_MODEL_PATH='/your/path/to/models/llmlingua-2-bert-base-multilingual-cased-meetingbank'
config_dict = {
    "pre_compress": True,
    "pre_compressor": {
        "model_name": "llmlingua-2",
        "configs": {
            "llmlingua_config": {
                "model_name": LLMLINGUA_MODEL_PATH,
                "device_map": "cuda",
                "use_llmlingua2": True,
            },
        }
    },
    "topic_segment": True,
    "precomp_topic_shared": True,
    "topic_segmenter": {
        "model_name": "llmlingua-2",
    },
    "messages_use": "user_only",
    "metadata_generate": True,
    "text_summary": True,
    "memory_manager": {
        "model_name": 'xxx', # such as 'openai' or 'ollama' ...
        "configs": {
            "model": LLM_MODEL,
            "api_key": API_KEY,
            "max_tokens": 16000,
            "xxx_base_url": API_BASE_URL # API model specific, such as 'openai_base_url' or 'deepseek_base_url' ...
        }
    },
    "extract_threshold": 0.1,
    "index_strategy": "embedding",
    "text_embedder": {
        "model_name": "huggingface",
        "configs": {
            "model": EMBEDDING_MODEL_PATH,
            "embedding_dims": 384,
            "model_kwargs": {"device": "cuda"},
        },
    },
    "retrieve_strategy": "embedding",
    "embedding_retriever": {
        "model_name": "qdrant",
        "configs": {
            "collection_name": "my_long_term_chat",
            "embedding_model_dims": 384,
            "path": "./my_long_term_chat",
        }
    },
    "summary_retriever": {
        "model_name": "qdrant",
        "configs": {
            "collection_name": "my_chat_summaries",
            "embedding_model_dims": 384,
            "path": "./my_chat_summaries",
        }
    },
    "update": "offline",
    "logging": {
        "level": "DEBUG",
        "file_enabled": True,
        "log_dir": RUN_LOG_DIR,
    }
}
lightmem = LightMemory.from_config(config_dict)
session = {
"timestamp": "2025-01-10",
"turns": [
    [
        {"role": "user", "content": "My favorite ice cream flavor is pistachio, and my dog's name is Rex."},
        {"role": "assistant", "content": "Got it. Pistachio is a great choice."}],
    ]
}
for turn_messages in session["turns"]:
    timestamp = session["timestamp"]
    for msg in turn_messages:
        msg["time_stamp"] = timestamp

    store_result = lightmem.add_memory(
        messages=turn_messages,
        force_segment=True,
        force_extract=True
    )
lightmem.construct_update_queue_all_entries()
lightmem.offline_update_all_entries(score_threshold=0.8)
summary_result = lightmem.summarize()
question = "What is the name of my dog?"
related_memories = lightmem.retrieve(question, limit=5)
print(related_memories)
LightMem also supports the Model Context Protocol (MCP) server:
# Running at Root Directory
cd LightMem
Environment
pip install '.[mcp]'
MCP Inspector [Optional]
npx @modelcontextprotocol/inspector python mcp/server.py
Start API by HTTP (http://127.0.0.1:8000/mcp)
fastmcp run mcp/server.py:mcp --transport http --port 8000
The MCP config json file of your local client may looks like:
{
  "yourMcpServers": {
    "LightMem": {
      "url": "http://127.0.0.1:8000/mcp",
      "otherParameters": "..."
    }
  }
}
For transparency and reproducibility, we have shared the results of our experiments on Google Drive. This includes model outputs, evaluation logs, and predictions used in our study.
🔗 Access the data here: Google Drive - Experimental Results
Please feel free to download, explore, and use these resources for research or reference purposes.
backbone: gpt-4o-mini, judge model: gpt-4o-mini & qwen2.5-32b-instruct
| Method | ACC(%) gpt-4o-mini | ACC(%) qwen2.5-32b-instruct | Memory-Con Tokens(k) Total | QA Tokens(k) total | Total(k) | Calls | Runtime(s) total | |-------------------|--------------------|------------------------------|-----------------------------|---------------------|--------------|--------|------------------| | FullText | 73.83 | 73.18 | – | 54,884.479 | 54,884.479 | – | 6,971 | | NaiveRAG | 63.64 | 63.12 | – | 3,870.187 | 3,870.187 | – | 1,884 | | A-MEM | 64.16 | 60.71 | 11,494.344 | 10,170.567 | 21,664.907 | 11,754 | 67,084 | | MemoryOS(eval) | 58.25 | 61.04 | 2,870.036 | 7,649.343 | 10,519.379 | 5,534 | 26,129 | | MemoryOS(pypi) | 54.87 | 55.91 | 5,264.801 | 6,126.111 | 11,390.004 | 10,160 | 37,912 | | Mem0 | 36.49 | 37.01 | 24,304.872 | 1,488.618 | 25,793.490 | 19,070 | 120,175 | | Mem0(api) | 61.69 | 61.69 | 68,347.720 | 4,169.909 | 72,517.629 | 6,022 | 10,445 | | Mem0-g(api) | 60.32 | 59.48 | 69,684.818 | 4,389.147 | 74,073.965 | 6,022 | 10,926 |
backbone: qwen3-30b-a3b-instruct-2507, judge model: gpt-4o-mini & qwen2.5-32b-instruct
| Method | ACC(%) gpt-4o-mini | ACC(%) qwen2.5-32b-instruct | Memory-Con Tokens(k) Total | QA Tokens(k) total | Total(k) | Calls | Runtime(s) total | |-------------------|--------------------|------------------------------|-----------------------------|---------------------|--------------|--------|------------------| | FullText | 74.87 | 74.35 | – | 60,873.076 | 60,873.076 | – | 10,555 | | NaiveRAG | 66.95 | 64.68 | – | 4,271.052 | 4,271.052 | – | 1,252 | | A-MEM | 56.10 | 54.81 | 16,267.997 | 17,340.881 | 33,608.878 | 11,754 | 69,339 | | MemoryOS(eval) | 61.04 | 59.81 | 3,615.087 | 9,703.169 | 11,946.442 | 4,147 | 13,710 | | MemoryOS(pypi) | 51.30 | 51.95 | 6,663.527 | 7,764.991 | 14,428.518 | 10,046 | 20,830 | | Mem0 | 43.31 | 43.25 | 17,994.035 | 1,765.570 | 19,759.605 | 16,145 | 46,500 |
backbone: gpt-4o-mini, judge model: gpt-4o-mini & qwen2.5-32b-instruct
| Method | Summary Tokens(k) In | Summary Tokens(k) Out | Update Tokens(k) In | Update Tokens(k) Out | QA Tokens(k) In | QA Tokens(k) Out | Runtime(s) mem-con | Runtime(s) qa | |-------------------|-----------------------|------------------------|----------------------|-----------------------|------------------|-------------------|----------------------|----------------| | FullText | – | – | – | – | 54,858.770 | 25.709 | – | 6,971 | | NaiveRAG | – | – | – | – | 3,851.029 | 19.158 | – | 1,884 | | A-MEM | 1,827.373 | 492.883 | 7,298.878 | 1,875.210 | 10,113.252 | 57.315 | 60,607 | 6,477 | | MemoryOS(eval) | 1,109.849 | 333.970 | 780.807 | 645.410 | 7,638.539 | 10.804 | 24,220 | 1,909 | | MemoryOS(pypi) | 1,007.729 | 294.601 | 3,037.509 | 924.962 | 6,116.239 | 9.872 | 33,325 | 4,587 | | Mem0 | 8,127.398 | 253.187 | 12,722.011 | 3,202.276 | 1,478.830 | 9.788 | 118,268 | 1,907 | | Mem0(api) | \ | \ | \ | \ | 4,156.850 | 13.059 | 4,328 | 6,117 | | Mem0-g(api) | \ | \ | \ | \ | 4,375.900 | 13.247 | 5,381 | 5,545 |
backbone: qwen3-30b-a3b-instruct-2507, judge model: gpt-4o-mini & qwen2.5-32b-instruct
| Method | Summary Tokens(k) In | Summary Tokens(k) Out | Update Tokens(k) In | Update Tokens(k) Out | QA Tokens(k) In | QA Tokens(k) Out | Runtime(s) mem-con | Runtime(s) qa | |-------------------|-----------------------|------------------------|----------------------|-----------------------|------------------|-------------------|----------------------|----------------| | FullText | – | – | – | – | 60,838.694 | 34.382 | – | 10,555 | | NaiveRAG | – | – | – | – | 4,239.030 | 32.022 | – | 1,252 | | A-MEM | 1,582.942 | 608.507 | 9,241.928 | 4,835.070 | 17,528.876 | 82.005 | 55,439 | 13,900 | | MemoryOS(eval) | 1,222.139 | 531.157 | 1,044.307 | 817.484 | 9,679.996 | 23.173 | 12,697 | 1,012 | | MemoryOS(pypi) | 2,288.533 | 516.024 | 2,422.693 | 1,436.277 | 7,743.391 | 21.600 | 19,822 | 1,007 | | Mem0 | 8,270.874 | 186.354 | 7,638.827 | 1,897.980 | 1,739.246 | 26.324 | 45,407 | 1,093 |
gpt-4o-mini, judge model: gpt-4o-mini
| Method | Overall ↑ | Multi | Open | Single | Temp | | :--- | :---: | :---: | :---: | :---: | :---: | | FullText | 73.83 | 68.79 | 56
→ →
 →
 →
 →
 →
 →
 →