1
 →

[WWW 2022] KnowPrompt: Knowledge-aware Prompt-tuning with Synergistic Optimization for Relation Extraction
zjunlp/KnowPrompt is an open-source project on GitHub, mainly written in Python. [WWW 2022] KnowPrompt: Knowledge-aware Prompt-tuning with Synergistic Optimization for Relation Extraction It currently holds 207 stars and 35 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Prompt Engineering board.
Code and datasets for the WWW2022 paper KnowPrompt: Knowledge-aware Prompt-tuning with Synergistic Optimization for Relation Extraction.
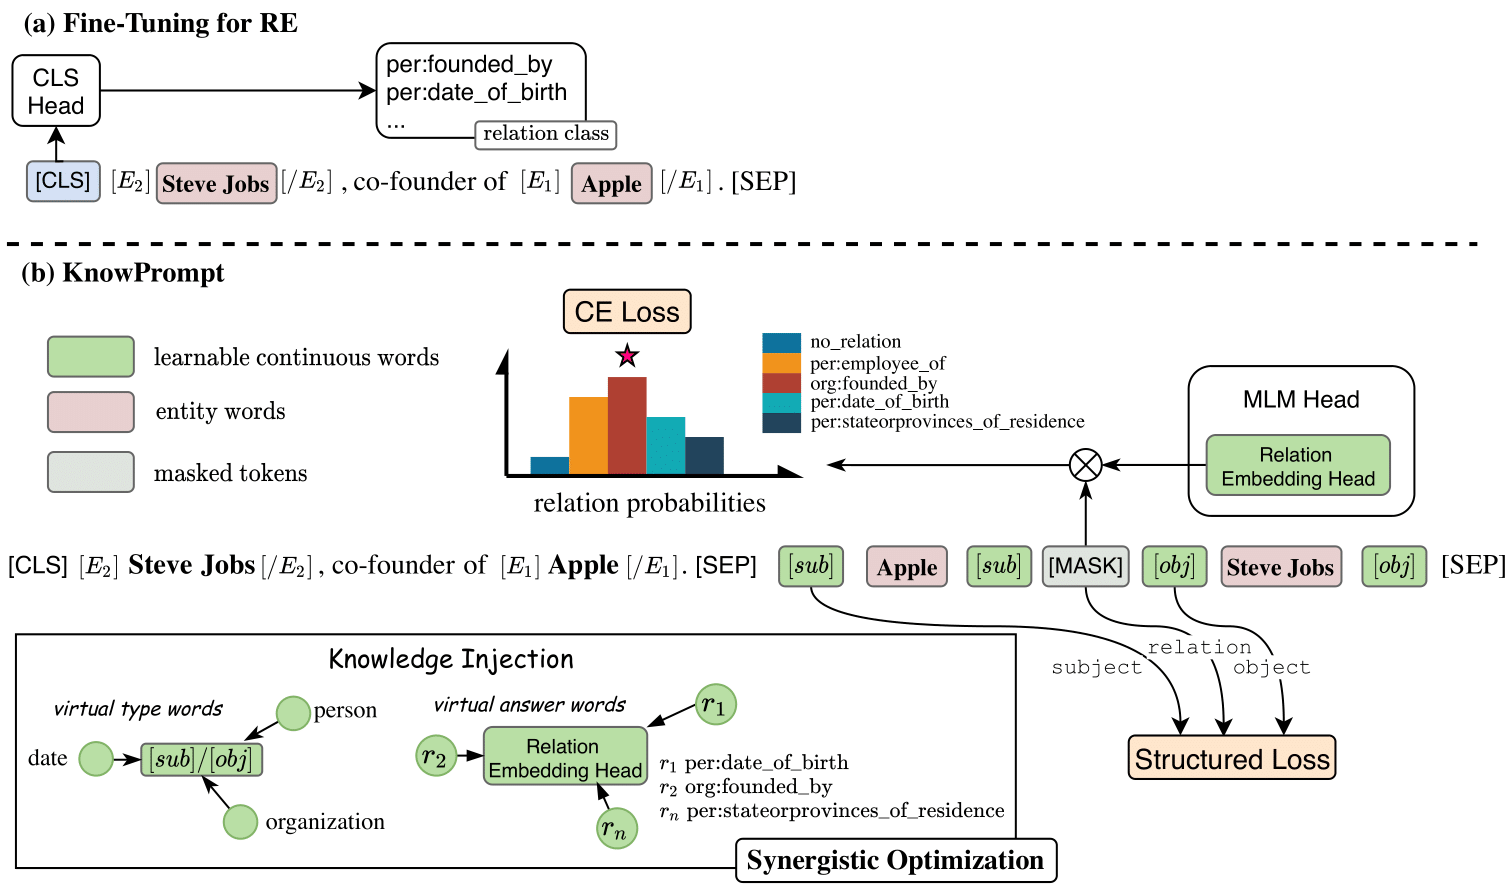
SemEval dataset at huggingface model hubIt is recommended to use a virtual environment to run KnowPrompt.
conda create -n knowprompt python=3.8
conda activate knowprompt
To install requirements:
pip install -r requirements.txt
Datasets ==========
We provide all the datasets and prompts used in our experiments.
+ [[SEMEVAL]](dataset/semeval)
+ [[DialogRE]](dataset/dialogue)
+ [[TACRED-Revisit]](dataset/tacrev)
+ [[Re-TACRED]](dataset/retacred)
+ [[TACRED]](dataset/tacred)
The expected structure of files is:
knowprompt
 |-- dataset
 |    |-- semeval
 |    |    |-- train.txt
 |    |    |-- dev.txt
 |    |    |-- test.txt
 |    |    |-- temp.txt
 |    |    |-- rel2id.json
 |    |-- dialogue
 |    |    |-- train.json
 |    |    |-- dev.json
 |    |    |-- test.json
 |    |    |-- rel2id.json
 |    |-- tacred
 |    |    |-- train.txt
 |    |    |-- dev.txt
 |    |    |-- test.txt
 |    |    |-- temp.txt
 |    |    |-- rel2id.json
 |    |-- tacrev
 |    |    |-- train.txt
 |    |    |-- dev.txt
 |    |    |-- test.txt
 |    |    |-- temp.txt
 |    |    |-- rel2id.json
 |    |-- retacred
 |    |    |-- train.txt
 |    |    |-- dev.txt
 |    |    |-- test.txt
 |    |    |-- temp.txt
 |    |    |-- rel2id.json
 |-- scripts
 |    |-- semeval.sh
 |    |-- dialogue.sh
 |    |-- ...
Run the experiments ==========
Use the comand below to get the answer words to use in the training.
python get_label_word.py --model_name_or_path bert-large-uncased --dataset_name semeval
The {answer_words}.ptwill be saved in the dataset, you need to assign the model_name_or_path and dataset_name in the get_label_word.py.
Download the data first, and put it to dataset folder. Run the comand below, and get the few shot dataset.
python generate_k_shot.py --data_dir ./dataset --k 8 --dataset semeval
cd dataset
cd semeval
cp rel2id.json val.txt test.txt ./k-shot/8-1
k and dataset to assign k-shot and dataset. Here we default seed as 1,2,3,4,5 to split each k-shot, you can revise it in the generate_k_shot.py
Our script code can automatically run the experiments in 8-shot, 16-shot, 32-shot and standard supervised settings with both the procedures of train, eval and test. We just choose the random seed to be 1 as an example in our code. Actually you can perform multiple experments with different seeds.
>> bash scripts/semeval.sh # for roberta-large
TACRED-Revist, Re-TACRED, Wiki80 included in our paper are also provided, you just need to run it like above example.
>> bash scripts/dialogue.sh # for roberta-base
We report emperical results on more datasets in the EMNLP 2022 (Findings) paper "Towards Realistic Low-resource Relation Extraction: A Benchmark with Empirical Baseline Study" [code].
Part of our code is borrowed from code of PTR: Prompt Tuning with Rules for Text Classification, many thanks.
@inproceedings{DBLP:conf/www/ChenZXDYTHSC22,
  author    = {Xiang Chen and
               Ningyu Zhang and
               Xin Xie and
               Shumin Deng and
               Yunzhi Yao and
               Chuanqi Tan and
               Fei Huang and
               Luo Si and
               Huajun Chen},
  editor    = {Fr{\'{e}}d{\'{e}}rique Laforest and
               Rapha{\"{e}}l Troncy and
               Elena Simperl and
               Deepak Agarwal and
               Aristides Gionis and
               Ivan Herman and
               Lionel M{\'{e}}dini},
  title     = {KnowPrompt: Knowledge-aware Prompt-tuning with Synergistic Optimization
               for Relation Extraction},
  booktitle = {{WWW} '22: The {ACM} Web Conference 2022, Virtual Event, Lyon, France,
               April 25 - 29, 2022},
  pages     = {2778--2788},
  publisher = {{ACM}},
  year      = {2022},
  url       = {https://doi.org/10.1145/3485447.3511998},
  doi       = {10.1145/3485447.3511998},
  timestamp = {Tue, 26 Apr 2022 16:02:09 +0200},
  biburl    = {https://dblp.org/rec/conf/www/ChenZXDYTHSC22.bib},
  bibsource = {dblp computer science bibliography, https://dblp.org}
}
 →
 →
 →
 →
 →
 →
 →