1
 →

Adapt local language models into Jev-compatible structured decision engines with Choice, Score, and Noul outputs powered by prefill-only binary inference.
Yinsongxu/LLM2Jev is an open-source project on GitHub, mainly written in Python. Adapt local language models into Jev-compatible structured decision engines with Choice, Score, and Noul outputs powered by prefill-only binary inference. It currently holds 82 stars and 8 forks with 0 open issues, and was last pushed on 2026-09-20 (repository created 2026-09-19).
AI Homed tracks it on the Today's Trending board, currently at rank #92 with 0 new stars today.
LLM2Jev adapts local language models to Jev-style structured decisions. It accepts runtime-defined Choice, Score, and Noul questions and returns typed answers with probabilities.
LLM2Jev is an independent open-source project. It is not affiliated with or endorsed by Jev or TypeSafe.
On Linux with a supported NVIDIA GPU, run a local model through SGLang:
git clone https://github.com/Yinsongxu/LLM2Jev.git
cd LLM2Jev
uv sync --extra sglang
source .venv/bin/activate
python examples/sglang_inference.py --model-path /path/to/model
The example submits Choice, Score, and Noul questions and prints the response as JSON.
Replace /path/to/model with a local Hugging Face-compatible causal language model directory.
Choice, Score, and Noul questions at runtime. Get option probabilities, weighted scores, or the probability that a condition is true; Choice and Score also include confidence.state, and candidates for the same question also share its instructions. LLM2Jev first scores a real criteria candidate to establish the prefix cache, then submits candidates that can reuse it. Each candidate is scored once, reducing repeated computation for long inputs with many candidates.
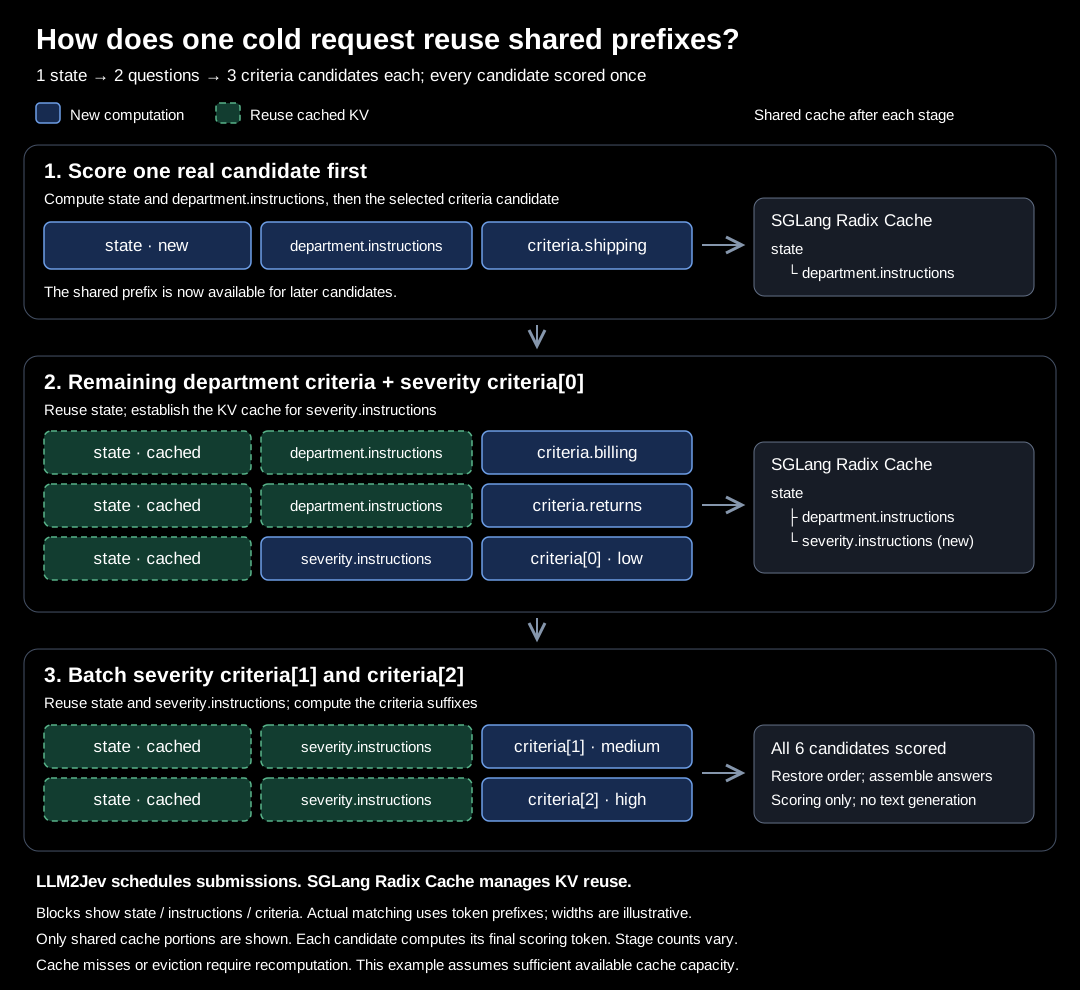
Learn how it works: From Jev Request to LLM Request → Shared-prefix design.
See Installation for environment requirements, SGLang and Transformers dependencies, and uv or pip installation.
See the Usage guide for complete examples:
See Performance benchmarks for the Qwen3-1.7B / RTX 5090 measurements, test conditions, and comparison of staged and all across cold and warm caches. Gains depend on input length, candidate count, and cache state.
python -m unittest discover -s tests -v
This project is licensed under the Apache License 2.0.
→ →
 →
 →
 →
 →
 →
 →