1
 →

Sprix AI at 屿智同行 × 保研岛 — an open-source benchmark for AI agents in Baoyan advising and application planning.
yeyuxin777/baoyan-agent-benchmark is an open-source project on GitHub, mainly written in Python. Sprix AI at 屿智同行 × 保研岛 — an open-source benchmark for AI agents in Baoyan advising and application planning. It currently holds 127 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the Today's Trending board, currently at rank #100 with 0 new stars today.
This is 屿智同行's benchmark project for graduate admissions agents, evaluating agent configurations (execution systems paired with models) for admissions advising, application planning and updating advice as student information changes. The current results cover eight agent configurations.
The benchmark contains 70 Chinese-language tasks, 23 cases and 83 answer stages, with per-task rubrics and reference programs. The public dataset is available without access approval; scoring materials must be withheld from the agents being evaluated.
简体中文 · Results · Quick start · Questions and scoring · Hugging Face dataset · Methodology
This leaderboard summarizes evaluation records for 70 public tasks, showing the mean score and completion rate of eight agent configurations. See the documentation for evaluation settings and scoring.
| Rank | Agent configuration (system + model) | Tasks | Completion | Mean score / 100 | | ---: | --- | ---: | ---: | ---: | | 1 | Codex + GPT Sol 6.1 | 70 | 70/70 (100.0%) | 79.08 | | 2 | Codex + GPT Astra 6 | 70 | 70/70 (100.0%) | 78.36 | | 3 | DSH + DeepSeek V4.1 Flash | 70 | 70/70 (100.0%) | 68.16 | | 4 | Volcengine Managed Agent + GLM 5.3 Flash | 70 | 70/70 (100.0%) | 66.80 | | 5 | Qwen Code + Qwen 3.8 Max | 70 | 70/70 (100.0%) | 64.24 | | 6 | Kimi Code + Kimi K3 | 70 | 70/70 (100.0%) | 58.96 | | 7 | Antigravity + Gemini 3.8 Flash | 70 | 70/70 (100.0%) | 58.23 | | 8 | Antigravity + Gemini 3.1 Pro | 70 | 70/70 (100.0%) | 55.55 |
All eight agent configurations completed 70 tasks; 0 current tasks timed out. These results combine different real runs with input versions and budgets that are not fully uniform. Complete tool traces are not available for every public record; the leaderboard does not imply uniform execution conditions.
All 70 current tasks and rubrics have owner-confirmed teacher calibration. The owner-approved difficulty labels are 14 easy (20%), 34 medium (48.57%) and 22 hard (31.43%); this is not an independent double review. Per-answer scored_draft and teacher_calibration labels remain in the captured scoring records. official=false is a separate result-certification flag.
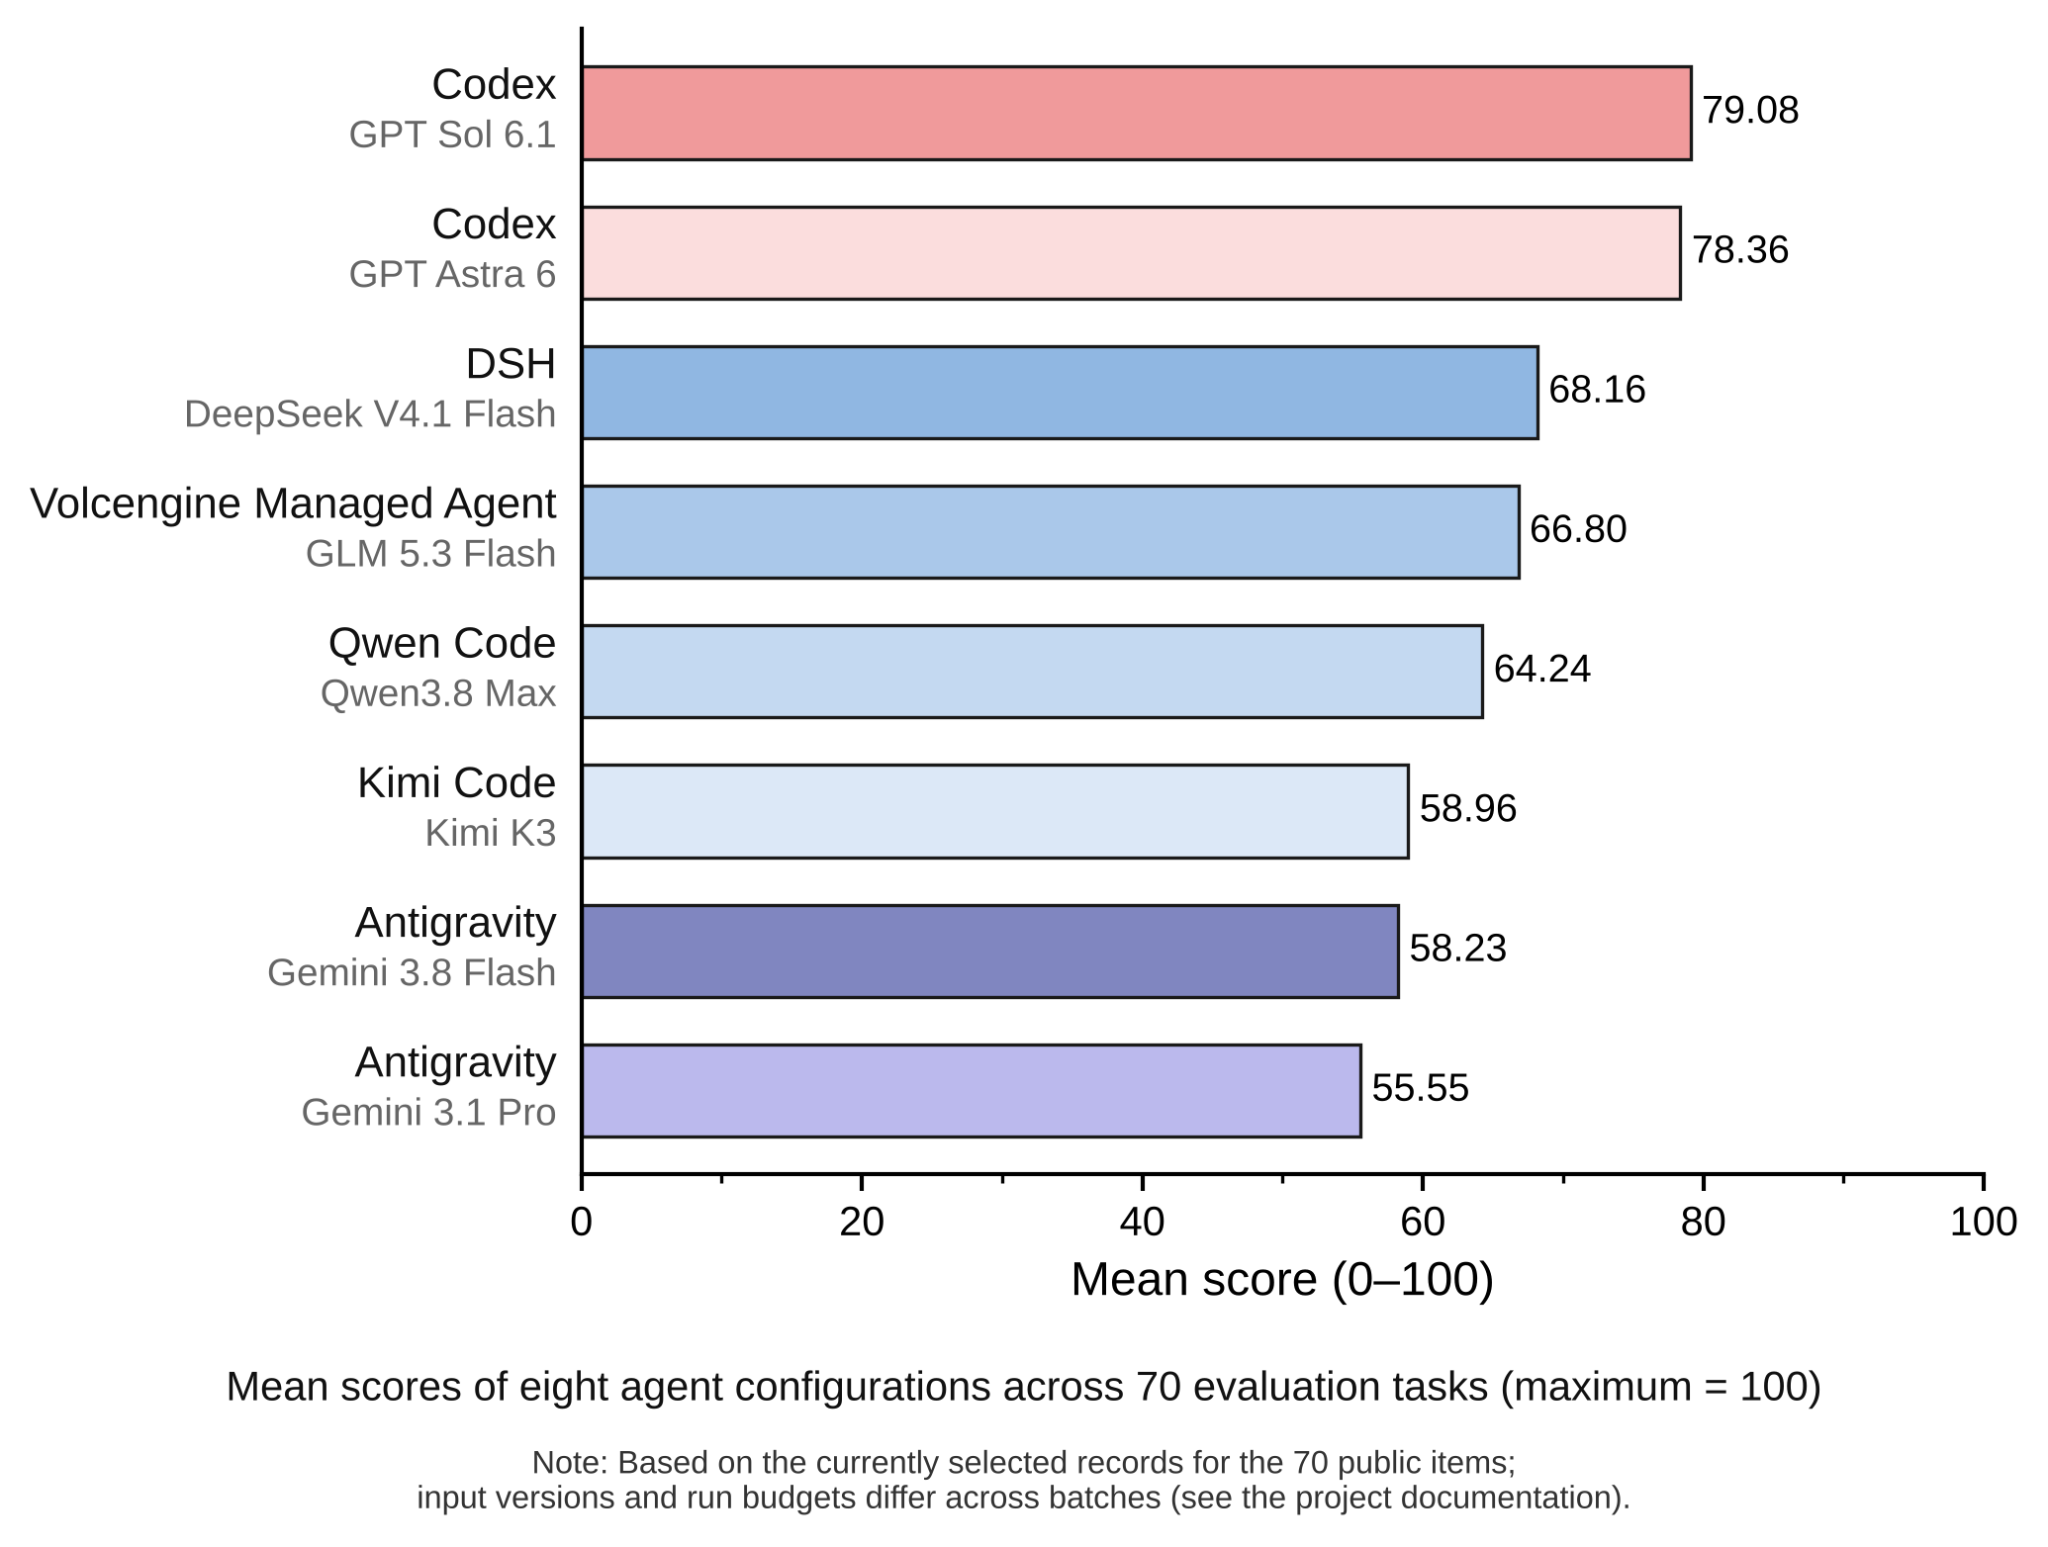
Mean scores of eight agent configurations across 70 evaluation tasks (maximum = 100).

Score data · Per-task results · Answers and scores by agent configuration
Run from the repository root. Automated native execution requires macOS Seatbelt and Python 3.10+ (3.11+ for Kimi subscription configuration). The framework uses only the standard library; no pip install is needed. Install the official client and prepare your own subscription login or API key.
Choose a configuration from the current agent registry. These IDs are used with --agent; they are not client model arguments:
| Agent configuration | Agent ID | Client | Template authentication |
| --- | --- | --- | --- |
| Codex + GPT Astra 6 | gpt-6-astra | Codex / codex | ChatGPT subscription |
| Codex + GPT Sol 6.1 | gpt-6-1-sol | Codex / codex | ChatGPT subscription |
| Claude Opus | claude-opus-5-5 | Claude Code / claude | Subscription OAuth |
| Claude Sonnet | claude-sonnet-5-5 | Claude Code / claude | Subscription OAuth |
| Gemini Flash | antigravity-gemini-3-8-flash-high | Antigravity / agy | Subscription |
| DeepSeek Flash | deepseek-v4-1-flash | DeepSeek Harness / dsh | API |
| Qwen Max | qwen3-8-max-0902 | Qwen Code / qwen | DashScope API |
| Kimi K3 | kimi-k3 | Kimi Code / kimi | Subscription OAuth |
Every configuration uses the same workflow. Replace AGENT with an ID above and retain its chosen authentication mode:
AGENT=gpt-6-1-sol
python3 -m benchmark setup --agent "$AGENT"
python3 -m benchmark cli-check --agent "$AGENT"
python3 -m benchmark cli-batch \
  --selection config/selections/current.json \
  --agent "$AGENT" --out "./runs/current-$AGENT"
setup saves local configuration. After cli-check returns ready_for_trial, try one task first. Batch execution defaults to a preview of 70 tasks and 83 stages without model calls; add --execute to use your account allowance. For multiple models, configure and check each, then repeat --agent, for example --agent gpt-6-1-sol --agent claude-opus-5-5, and use a new output directory.
Scoring can use a separate Codex subscription session to review exported materials. Optional API judging requires separate configuration. See the quick start for trials, subscription review, API judging and reports, and the native CLI guide for installation, authentication and multiple stages.

Each task is worth 100 points. Full recommendation tasks allocate 70 points to reference-program matching and 30 to recommendation quality. A separate reviewer scores the full answer; rubrics stay outside the answering process.
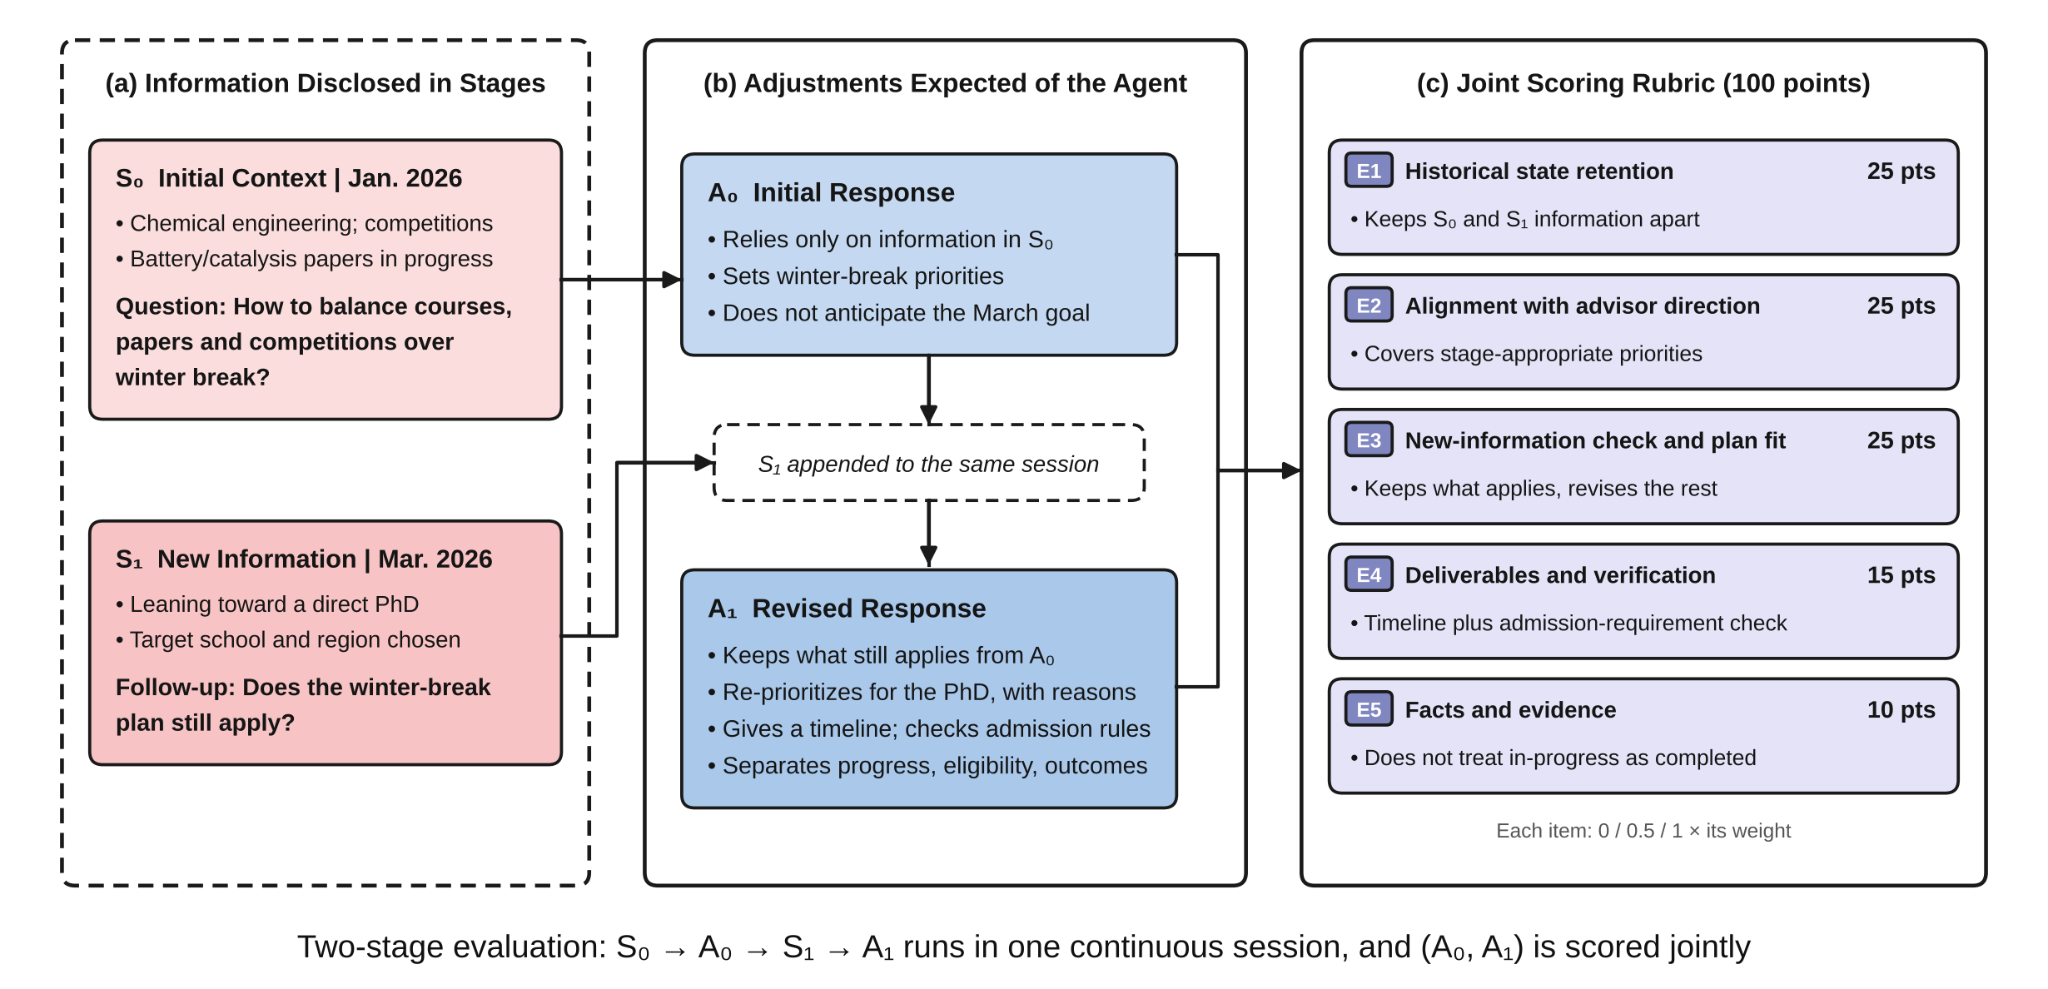
Two-stage tasks supply initial context S₀ followed by updated information S₁ in the same session, producing initial response A₀ and revised response A₁ for joint scoring. The January-to-March scenario and shift to direct PhD applications correspond to public task O03-04. E1–E5 correspond to this example’s five scoring criteria, weighted 25, 25, 25, 15 and 10 points; see the O03-04 rubric. Panel (b) illustrates task requirements, and panel (c) shows the rubric.
All questions and criteria · Task index · Data format · Scoring rules
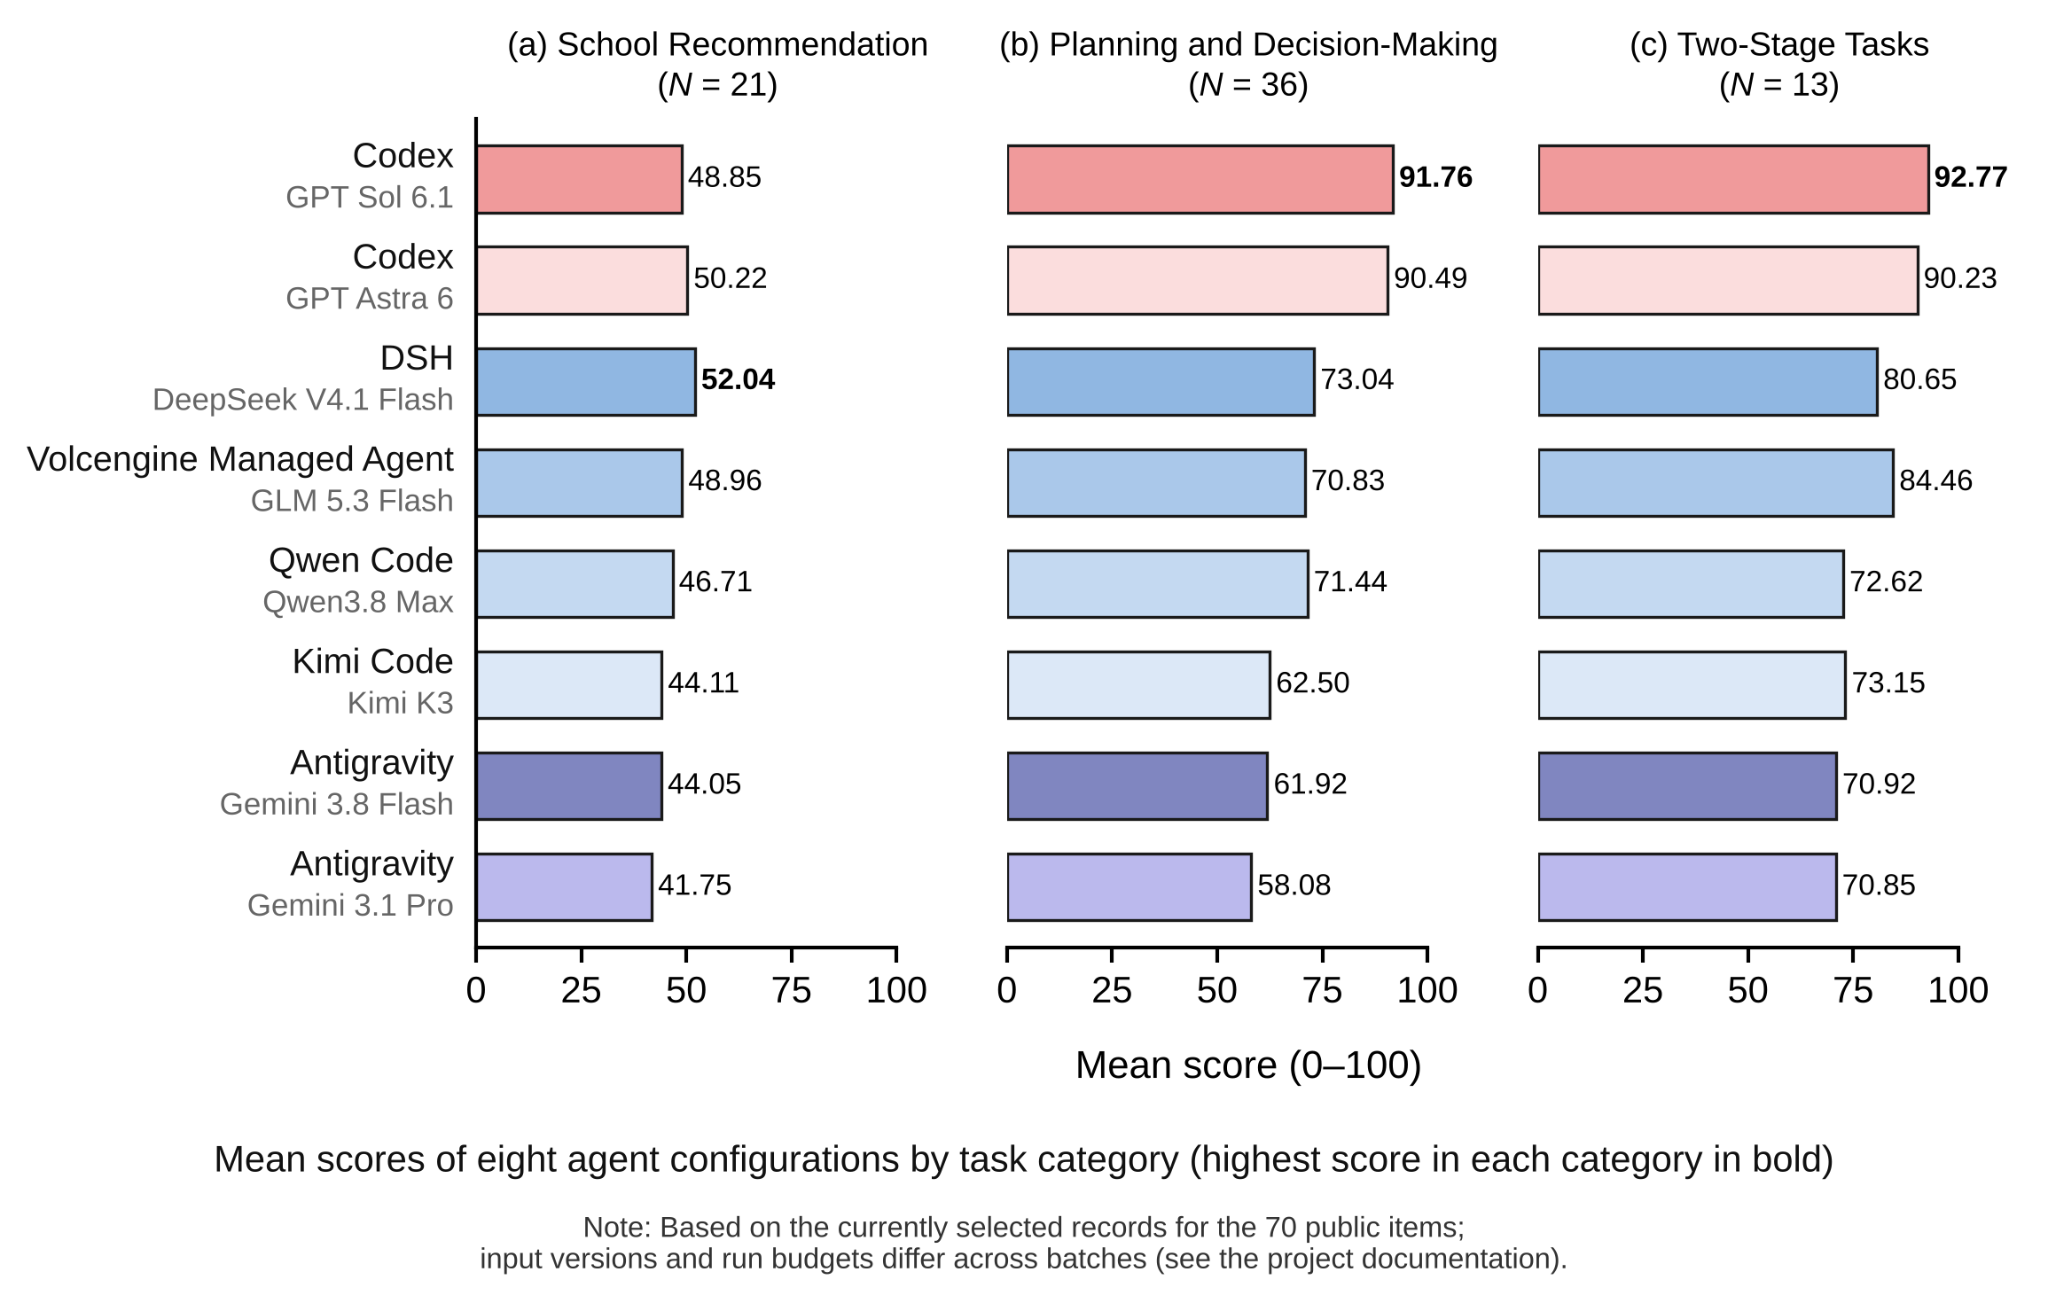
The categories contain 21 recommendation tasks, 36 planning and decision tasks, and 13 two-stage tasks. Scores are category means out of 100; the highest score in each category is bold.
See per-task results and public answers for statuses, score intervals and full answer text.
Evaluation and run records document the composition and limitations of these results; the review protocol describes independent scoring. The reproduction guide covers frozen inputs, submissions and score verification. See local export for dataset export.
This is 屿智同行's benchmark project for graduate admissions agents.
Yonghao Zhang is CEO and holds a master's degree in Computer Science from Tsinghua University; Yichen Wang is CTO and project lead.
Contributions to questions, rubrics, evaluation tools and documentation are welcome through Issues and Pull Requests. Cite the MIT-licensed software for code and tooling, and the CC BY 4.0 dataset for tasks or rubrics. Record the version, content hashes and agent configuration used.
We thank 保研岛 for providing data for this benchmark.
Code and software documentation are licensed under MIT. Original public task definitions, rubrics and related dataset materials are licensed under CC BY 4.0, within the scope specified in the license file. Third-party materials retain their respective rights.
→ →
 →
 →
 →
 →
 →
 →