1
 →

ARIS ⚔️ (Auto-Research-In-Sleep) — Lightweight Markdown-only skills for autonomous ML research: cross-model review loops, idea discovery, and experiment automation.
wanshuiyin/Auto-claude-code-research-in-sleep is an open-source project on GitHub, mainly written in Python. ARIS ⚔️ (Auto-Research-In-Sleep) — Lightweight Markdown-only skills for autonomous ML research: cross-model review loops, idea discovery It currently holds 16,395 stars and 1,396 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Coding Agents board.
·
·
·
·
·
·
·
· 💬 Join Community ·
🌱 ARIS is a methodology, not a platform. What matters is the research workflow — take it wherever you go.
💡 Use ARIS as a skill-based workflow in Claude Code / Codex CLI / Cursor / Trae / Antigravity / GitHub Copilot CLI / OpenClaw / DeepSeek Harness — enjoy any way you like!
The executor drives, an independent model (Codex MCP by default) reviews. Alternative model combinations, including ModelScope-hosted models, need no Claude or OpenAI API.
📦 Those are the skills installed directly. Want it in one command? ARIS also ships as a standalone CLI and as plugins: ·
·
·
❗ codex-cli 0.154.0 removed
codex mcp-server — the entry point every ARIS reviewer call used. No impact on ARIS: the codex MCP server is now ARIS's own bridge over codex exec (mcp-servers/codex-exec/), same tools, same results, all 82 skills unchanged, ultra and per-thread resume intact. One re-registration is all it takes — already installed? → Quick Start step 2b · new install → step 2 · what changed.
🧩 The ARIS family — same method, other jobs. One line each; the details live in their own repos.
— EasyAIOffer: 34 bilingual ML / LLM interview cheat sheets on one page — derivations, from-scratch PyTorch, 25 questions each. 希望大家秋招轻松一点 🌱
·
— two sides of one disease. HERO: a ~550-token block for
CLAUDE.md / AGENTS.md against the four shapes agents over-defend in (Hashing, Edge cases, Rubrics, Overbuild), bounding what the agent proposes, never what it looks for. Anti-Autoresearch: 61 integrity signals into a deterministic, reviewer-ready report — fabrication forensics, not an AI-text detector.
— ARIS goes multimodal: a rough story in, a movie told in still frames out, every scene checked by another model; the same loop draws clean method diagrams (
/method-figure).
— a tiny always-on-top macOS widget that lights up 🔴 when a session waits for your approval;
cd aris-monitor && ./run.sh. Many windows? Claude Fleet by @tianyilt is the full dashboard.
🔥 ARIS-Code CLI — 独立安装版 · English | ⬇️ Download · — v0.4.27: launching and quitting the REPL leaves no empty session file. v0.4.26: the
fable alias and /model now point at Fable 5.1 (default stays Opus 5). v0.4.25: the Codex reviewer works again on codex-cli ≥ 0.154 (built-in codex exec bridge, nothing to register), /since takes you back to your last input, /resume lists sessions by index, Windows multi-line paste fixed (pending confirmation), 83 bundled skills on GPT-6-Astra.
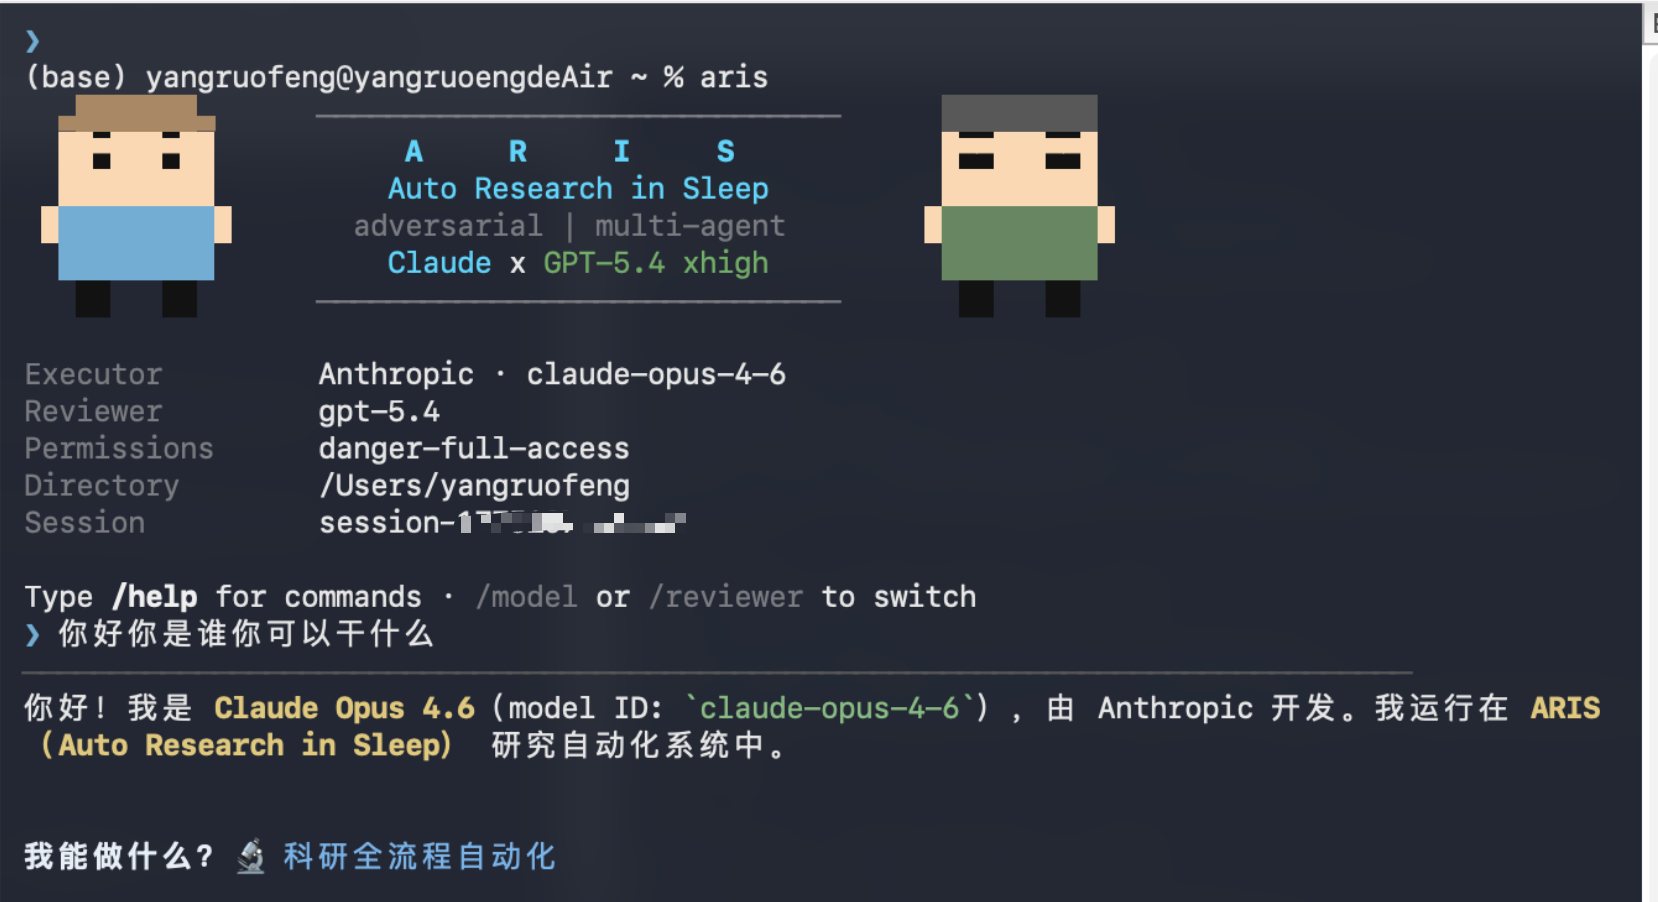
📰 ARIS-Code v0.4.27 (2026-09) — latest: launching and quitting the REPL no longer leaves an empty session file, and /resume lists only sessions with messages (#439 follow-up). v0.4.26 made Fable 5.1 the fable alias and the first /model entry (the default executor stays Opus 5). v0.4.25 is the reviewer-bridge release: codex-cli 0.154 removed codex mcp-server, so every Codex review from ARIS-Code died on an updated codex. The reviewer now runs over a built-in codex exec bridge — no mcpServers.codex entry, old entries migrate in memory, thread records interoperate with ARIS's Python bridge. Also: /since replays everything after your last input (folded like the live display, /since full for complete output), /resume lists sessions with indices and shows where you stopped (#439), Windows multi-line paste no longer submits line by line (#430, pending confirmation), the Windows shim message carries the native installer (#428), and the bundle moves to 83 skills on GPT-6-Astra. Recent headliners: v0.4.24 — Claude 5 model refresh (Opus 5 default, Fable 5 tier, availability chain) and v0.4.23 — output folding. Caps a 23-release run (v0.4.5 → v0.4.27); per-release detail below. Credits: @GetIT-Sunday, @Anduin9527, @GO-player-hhy, @Jxy-yxJ, @screw-44, @StevenUST, @opposj, @ShijunLei-cn, @algojogacor, @YukinoshitaLove, @jinliye-2026, @SajimJC.
Per-release details (v0.4.5 → v0.4.27)
> v0.4.27 (2026-09-19) — launching and quitting the REPL no longer leaves an empty session file; /resume lists only sessions with messages (#439 follow-up).
> v0.4.26 (2026-09-16) — Fable 5.1: thefablealias now resolves toclaude-fable-5-1,/modellists Fable 5.1 first (Fable 5 stays selectable) and the system-prompt identity names it; the default executor remainsclaude-opus-5(the Mythos tier is $10/$50 vs Opus 5's $5/$25, so the default does not move). Savedexecutor_modelvalues are ids, not aliases, and are untouched. Pricing already matched onfable; a test pins 5.1. Tests unchanged (aris-cli 225 + 4 e2e / runtime 252 / tools 71 / commands 6). Codex MCP (gpt-6-astra xhigh) gate: GO.
> v0.4.25 (2026-09-16) — the reviewer-bridge release. codex-cli 0.154 removedcodex mcp-server, the entry point ARIS-Code'saris setuphad written into settings.json for every Codex review; on an updated codex every review call died. Built-incodex execbridge:mcp__codex__codex/codex-replyrun ascodex exec --jsonwith nothing to register — no settings entry, a legacycodex mcp-serverentry is migrated in memory (env,-cdefaults,requestTimeoutSecs, trust kept), an explicit Python-bridge entry is used as configured, thread records share~/.codex/state/codex-exec/threads/with the Python bridge, 1800 s budget forultraaudits,ARIS_CODEX_BRIDGE=0restores the old path;aris doctorprints the effective backend. Found on the way: the model never received a Codex result'sthreadId(it lives only instructuredContent), socodex-replycould not continue a thread — results now start with athreadId:line./since [full]replays the user's last input and everything after it with the live formatters (display only; after/resumeand in--resumebatch mode too); a dim hint after turns with ≥ 8 tool calls (ARIS_TURN_SUMMARY=0). #430 Windows consoles deliver no paste event, so each pasted line became its own Enter — lines are now merged into the input and never auto-submitted, Ctrl+C discards the rest (ARIS_PASTE_BURST=0; inferred from crossterm's source, pending confirmation on a Windows machine). #439/resumelists sessions with[n]indices and ages and accepts an index, a unique id prefix or a path; the last turn is replayed after loading. #428 the.cmd-shim message carries the official native installer one-liner. Bundle 81→83 (pin 3e49e63 → 4734364):/proof-orchestrator,/research-implement-feature, 32 helpers (+review_gate.py,copilot_native_evidence.py,idea_discovery_gate.py), repo-roottemplates/bundled; reviewer doctrine and system prompt on gpt-6-astra (fallback gpt-5.6-sol → gpt-5.5), explicit— reviewer:directives win,LlmReviewresults carryreviewer_model:so HTTP rounds report toreview_gate.pytruthfully; gpt-6-astra pricing tier $10/$50 (cache write $12.50, read $1). Tests: api 35+6 / aris-cli 225 + 4 e2e / runtime 252 / tools 71 / commands 6, all green; livecodex execfresh + resume roundtrip on codex-cli 0.154.0. Codex MCP (gpt-6-astra): ultra design gate (2 rounds), xhigh implementation gate per step (5/2/2/2 rounds), final whole-diff gate (2 rounds) → GO.
> v0.4.24 (2026-08-09) — the Claude 5 model refresh (#392, requested by @YukinoshitaLove). Explicit--model claude-opus-5/claude-fable-5already passed through on every platform — this release makes them first-class. Default →claude-opus-5(main session, subagents,aris setup; same $5/$25 tier as Opus 4.8); the v0.4.18 availability fallback becomes an ordered chain walk (Opus 5 → Opus 4.8 → Opus 4.7, one step per precise404 not_found_error, explicit choices never silently change) — the naive constant swap would have stranded 4.7-only accounts and configs saved by v0.4.23's setup, a regression the cross-model review caught and an end-to-end mock-404 chain test now locks./modelpicker adds Fable 5 / Opus 5 / Sonnet 5; newfablealias. New Mythos-class pricing tier (fable/mythos= $10/$50, cache write $12.50 / read $1, verified 2026-08 — previously fell to the conservative $15/$75 unknown-model tier, a 1.5× over-estimate); Opus 5 / Sonnet 5 pinned on their existing branches. Tests: api 41 / aris-cli 213 + 4 e2e / runtime 226 / tools 70 / commands 5, all green; live smoke on claude-opus-5, claude-fable-5 and the fable alias. Codex MCP (gpt-6-astra xhigh) implementation gate: NO-GO → NO-GO → GO.
> v0.4.23 (2026-08-02) — the output-folding release (top real-user complaint: "aris dumps thinking and the full content of documents it reads onto the screen"). 🧹 Tool-output folding, display layer ONLY: the disk-verified culprits were format_read_result appending the ENTIRE read payload, bash pushing full stdout/stderr, grep dumping its full content blob, and the edit preview capping line counts but not line LENGTH. Now Read/Grep show the first 6 lines, Bash shows first 4 + last 4 per stream (stderr keeps its red), each kept line capped at 240 chars (the minified-single-line case), then one dim "… (+N more lines — set ARIS_TOOL_OUTPUT_LINES=0 for full output)" hint. ONE env knob: unset = defaults, a positive integer overrides every tool, 0 = the exact old display; the session, model context,--output-format jsonand/exportare untouched and always complete. Thinking was verified to never print (Anthropic deltas only accumulate; Kimi reasoning_content only feeds the replay cache — the "thinking dump" perception came from the document dumps); two end-to-end sentinel tests (real binary vs mock SSE server) lock that thinking/reasoning never reaches the terminal. Interactive expand/collapse was deliberately rejected as over-engineering. 🐛 Bash timeout now kills the command: a timed-out call reportedinterrupted: truewhile the dropped tokio future left the child RUNNING — side effects landed after the report; now kill_on_drop (escape hatchARIS_BASH_KILL_ON_TIMEOUT=0; background tasks untouched; locked by a real behavioral test — a timed-out "sleep 1 && touch marker" must not create the marker). 📦 Bundle 79→81 (pin 7182624 → 3e49e63):/integrity-forensics— the Anti-Autoresearch SHA-pinned thin launcher (span-anchored evidence ledger → GPT auditors propose → deterministic rules-only adjudicator decides → typed BLOCK/WARN gate + obligations ledger) — and/web-debug-search, +tools/forensics_gate.py (29 helpers, 104 embedded resources). 🎁 Also: grep's content mode no longer shows a false "0 matches" above real results (the gate caught that"numMatches": nullserializes with the key present, defeating a naive presence check); all four crates' local-mock-server tests are now proxy-immune (a shell with http(s)_proxy set used to turn 15 tests red on a released tag — 127.0.0.1 was routed through the proxy). The rest of the runtime-state package (compaction re-arm, failed-turn cleanup, /cost dollars, SSE tail) ships as v0.4.24 — the cached-token cost fix is deliberately held back because it changes what the compaction trigger measures. Tests: api 41 / aris-cli 212 + 3 e2e / runtime 225 / tools 69 / commands 5 (+13), all green under a live proxy; new-code clippy delta zero. Codex MCP (gpt-6-astra): ultra scope+design adjudication, then a 3-round implementation gate (round 1 caught the null-serialization defeat and a non-hermetic behavioral test; round 3 GO).
> v0.4.22 (2026-07-12) — the skills-resync + GPT-6-Astra release. 📦 Bundle resync (pin 7e3ab67 → 7182624, 93 commits): 79 bundled skills (+meta-apply, +paper-poster-html;paper-posterretired to a redirect stub), 28 tools helpers (8 new: capture_filter, evidence_check, iteration_log, provenance, run_state, threat_scan, meta_opt/trigger_eval + sample evals), 11 new shared-references docs (fan-out-pattern, acceptance-gate, external-cadence, skill-governance, compute-env-contract, resumable-runs, evidence-precheck, injection-hygiene, capture-antipatterns, output-composition, taste-calibration); sync hardening —ARIS_SYNC_EXPECT_SHAguard (aborts before touching assets if main moved; it caught a real move on first use) + exact-inventory drift tests + the vendored posterly MIT license text now ships. 🎛 GPT-6-Astra two-tier reviewer alignment: the CLI's system-prompt nudge now passes the skills' explicitmodel: gpt-6-astra+ per-call effort pins through (the v0.4.17 blanket "never pass a model" rule would have silently stripped deep audits from ultra to xhigh), carries the canonical capability-only fallback chain (effort-unsupported → same model xhigh, deep tier only; model-unknown → explicit gpt-5.5+xhigh; never degrade on transport-class errors; an explicit call-level override disables the chain), pinsapproval-policy: "never"+ explicitsandboxon every fresh codex call, and makes the HTTP fallback pre-dispatch-only with parameter stripping; the HTTP LlmReview default deliberately stays gpt-5.5 pending a real smoke; gpt-5.6 family pricing (sol $5/$30, terra $2.50/$15, luna $1/$6) verified against the official page; banner/Reviewer display//reviewerare honest about primary-vs-fallback (pure-Codex setups get status + guidance instead of a fake picker). 🐛 8 verified fixes: explicit--modelwas silently overridden by the saved executor model (model provenance now tracked end-to-end; the 4.8→4.7 availability fallback respects explicit choices;/modeland/setupre-arm it); saved models no longer leak across provider transports (blank saved models count as absent; OpenAI transport with no model source fails fast; the first-run wizard's config now actually feeds startup model resolution);--output-format jsonnever prompts (locked by a real end-to-end binary test against a mock SSE server); Windowsaris loginfixed (PKCE randomness read /dev/urandom → getrandom); Windows command probing fixed (the PowerShell tool probed itself throughsh; now where.exe); codex.cmdshims classified honestly (three-state probe; setup requires explicit confirmation before writing a config the MCP client can't spawn); nested config.json warns instead of silently parsing to all-defaults; NotebookEdit mints collision-free cell ids. 🖥 New windows-latest CI job (workspace compile gate + three targeted test groups, each guarded against silent 0-test green). Tests: api 41 / aris-cli 204 + 1 e2e / runtime 223 / tools 69 / commands 5 (+54), all green; new-code clippy delta zero. Codex MCP (gpt-6-astra): ultra design gate — 5 rounds, NO-GO ×4 → GO — then a 3-round implementation gate whose round 2 caught a first-run config-wiring blocker before it shipped; 4 implementation subagents, every report disk-verified.
> v0.4.21 (2026-06-28) — bug-fix patch: 5 new user-facing bugs from a Codex adversarial hunt (all disk-verified, distinct from v0.4.20), each cross-model reviewed at a design gate and an implementation gate (gpt-5.5 xhigh; both started NO-GO — the reviewer caught an off-by-one in the grep line-mapping and a missing stream-level test before GO). 🐛 Headline: OpenAI-compatible streaming corrupted multi-byte UTF-8 (CJK / emoji) split across network chunks into�— each HTTP body chunk wasfrom_utf8_lossy'd independently, so a 3-byte Chinese character or 4-byte emoji straddling a chunk boundary broke on both sides (a frequent hit for Chinese users on domestic OpenAI-compatible providers — Kimi/GLM/MiniMax/DeepSeek/Qwen/Doubao — streaming Chinese text); the stream buffer is now raw bytes, decoding only complete SSE lines. A saved OpenAI/custom executor config no longer overrides a shell-setEXECUTOR_PROVIDER— the startup "shell-provided vars win" path had one ungated write that re-pointedEXECUTOR_PROVIDER=anthropic … aris …to OpenAI (wrong executor / model-not-found). An Anthropic stream truncated after content but before a terminal signal now hard-errors (premature_eof) instead of saving a half-finished answer to history as a complete turn (symmetric to the OpenAI#249guard; thestop_reason-only compat path is preserved, andARIS_ALLOW_EOF_WITHOUT_STOP=1opts a terminal-signal-less proxy back into the old behavior).grep_searchwithmultiline: truenow matches across lines in content mode (was silently empty —countmode already worked). MCP tool results carried only instructuredContent(emptycontent) are no longer dropped — the model gets the JSON structured payload. Tests (CI mode): api 32→35 / runtime 205→212 / tools 67 / aris-cli 172→181 / commands 5 (+21, incl. 2 stream-level integration tests), all green. Codex MCP (gpt-5.5 xhigh): design gate (NO-GO → GO after fixing the off-by-one) → implementation gate (NO-GO → GO after adding the stream-level integration tests); the Anthropic streaming spec (every stream ends withmessage_stop) was WebFetch-verified. Two latent-only candidates (Anthropic block-indexrouting, OpenAI multi-line SSE) remain deferred.
> v0.4.20 (2026-06-19) — bug-fix patch: 7 user-facing bugs surfaced by a Codex adversarial hunt, each reviewed across 3 rounds (the reviewer caught a redraw gap, a trailing-blank, a spinner tail, and a blank-line edge before GO). 🐛 Headline (#299): short REPL replies showed only "✔ Done" — the spinner draws "⠋ Thinking…" with Save/RestorePosition so streamed output overwrites it on the same line, butfinishthen cleared that whole line, erasing a short single-line reply. The REPL now finishes without clearing when the turn printed visible text (Clear(UntilNewLine)wipes only the spinner tail after the reply). Streamed multi-paragraph replies rendered glued ("para1para2") — each chunk's paragraph separator was trimmed at the stream boundary; the markdown streamer now preserves separators via a held-separator so streamed output equals a single full render (no dangling blank line). Markdown tables with CJK/fullwidth content misaligned — width now counts display cells (CJK = 2), not chars.aris "prompt"/aris setup(REPL-only before) — a configured OpenAI/custom executor got the Anthropic default sent to its endpoint; the one-shot and REPL paths now share one resolver. Esc now actually closes the completion dropdown (it was recomputed right back).glob_searchreports
→ →
 →
 →
 →
 →
 →
 →