
1
 →
Vchitect/VBench is an open-source project on GitHub, mainly written in Python. [CVPR2024 Highlight] VBench - We Evaluate Video Generation It currently holds 1,778 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Video Projects board and on the AI AI Video Projects list.
This repository provides unified implementations for the VBench series of works, supporting comprehensive evaluation of video generative models across a wide spectrum of capabilities and settings.
If your questions are not addressed in this README, please contact Ziqi Huang at ZIQI002 [at] e [dot] ntu [dot] edu [dot] sg.
This repository provides unified implementations for the VBench series of works, supporting comprehensive evaluation of video generative models across a wide spectrum of capabilities and settings.
TL;DR: Evaluating Video Generation — Benchmark • Evaluation Dimensions • Evaluation Methods • Human Alignment • Insights
VBench: Comprehensive Benchmark Suite for Video Generative Models
Ziqi Huang∗, Yinan He∗, Jiashuo Yu∗, Fan Zhang∗, Chenyang Si, Yuming Jiang, Yuanhan Zhang, Tianxing Wu, Qingyang Jin, Nattapol Chanpaisit, Yaohui Wang, Xinyuan Chen, Limin Wang, Dahua Lin+, Yu Qiao+, Ziwei Liu+
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024
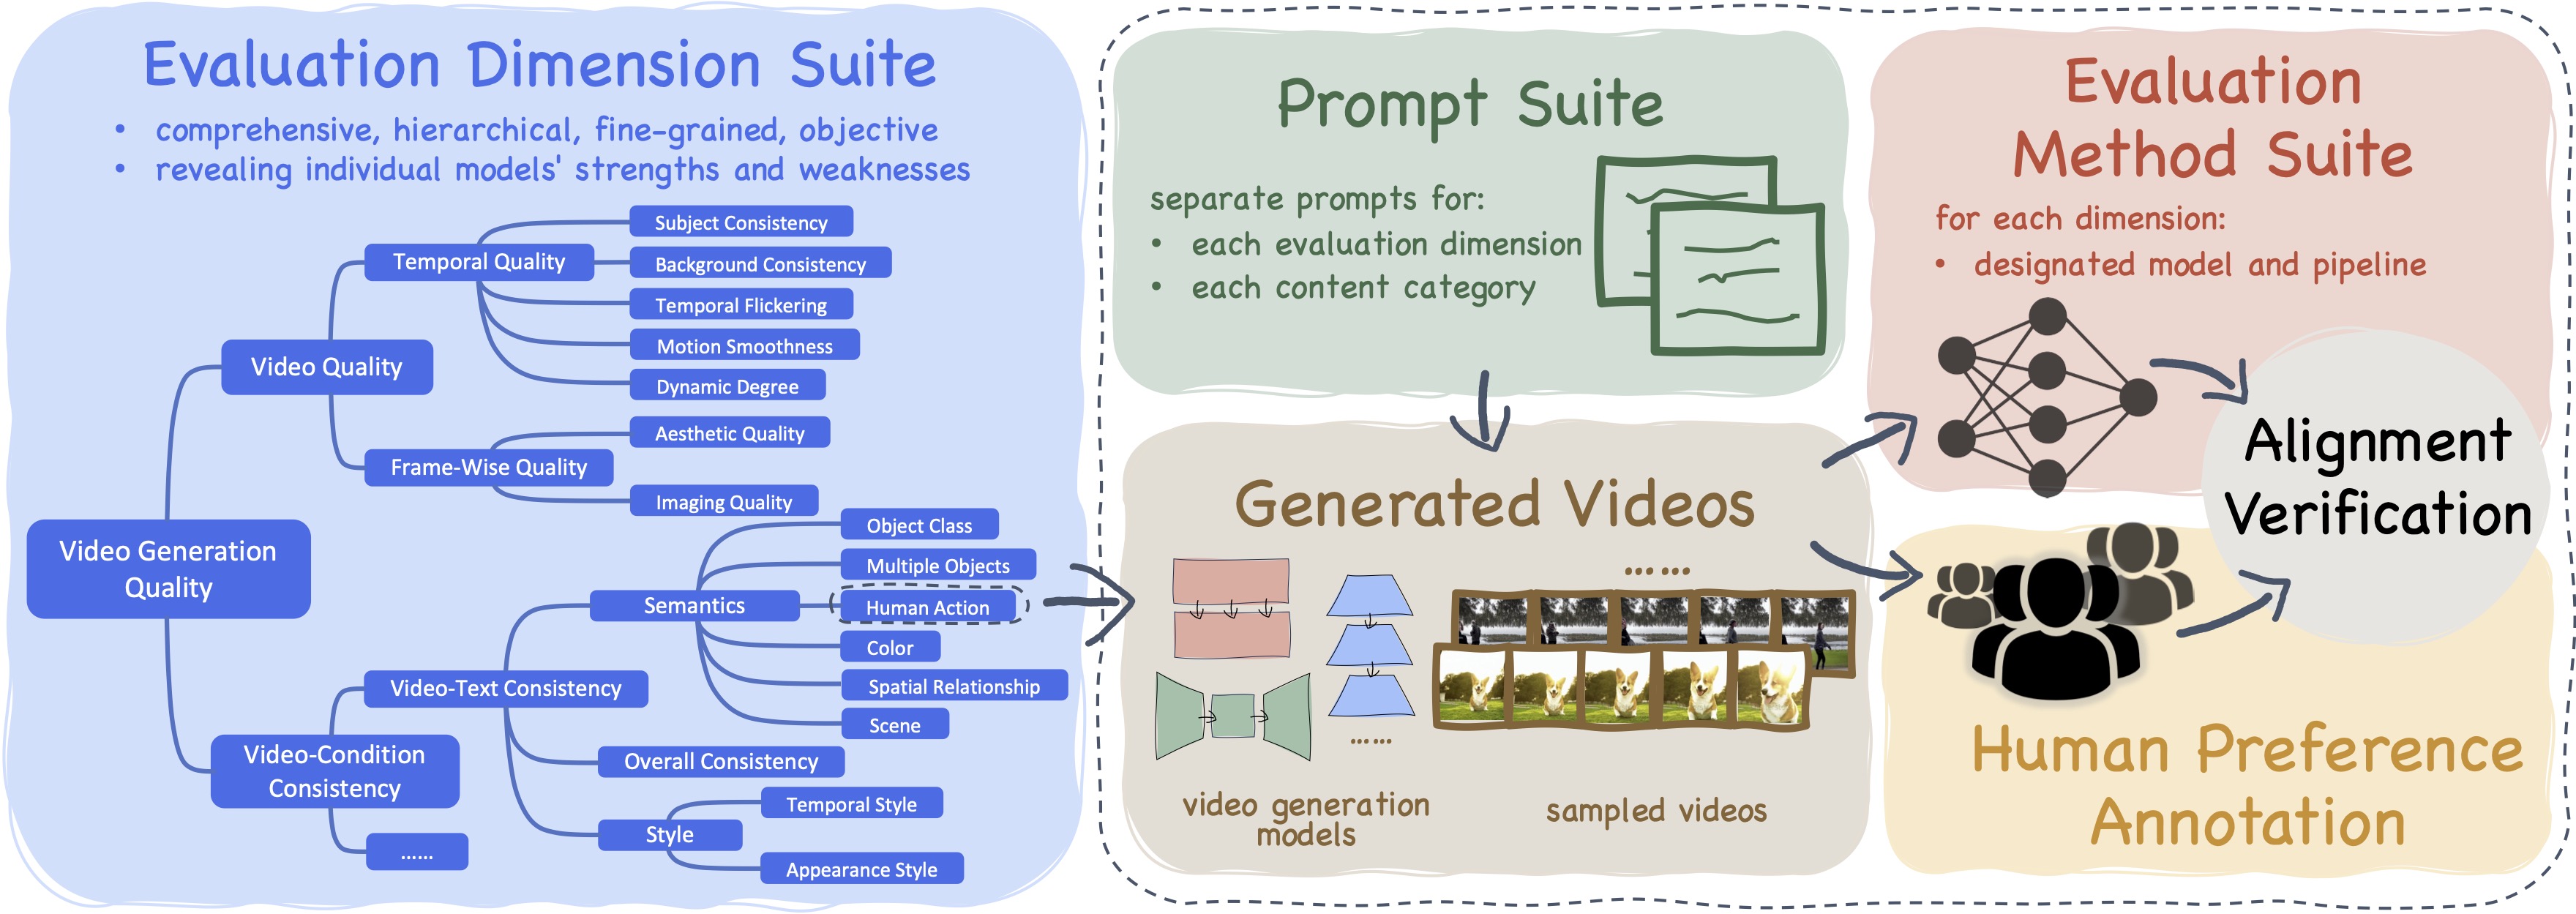
We propose VBench, a comprehensive benchmark suite for video generative models. We design a comprehensive and hierarchical Evaluation Dimension Suite to decompose "video generation quality" into multiple well-defined dimensions to facilitate fine-grained and objective evaluation. For each dimension and each content category, we carefully design a Prompt Suite as test cases, and sample Generated Videos from a set of video generation models. For each evaluation dimension, we specifically design an Evaluation Method Suite, which uses carefully crafted method or designated pipeline for automatic objective evaluation. We also conduct Human Preference Annotation for the generated videos for each dimension, and show that VBench evaluation results are well aligned with human perceptions. VBench can provide valuable insights from multiple perspectives.
Note: The code and README for the VBench components are located here, relative path: ..
@InProceedings{huang2023vbench,
    title={{VBench}: Comprehensive Benchmark Suite for Video Generative Models},
    author={Huang, Ziqi and He, Yinan and Yu, Jiashuo and Zhang, Fan and Si, Chenyang and Jiang, Yuming and Zhang, Yuanhan and Wu, Tianxing and Jin, Qingyang and Chanpaisit, Nattapol and Wang, Yaohui and Chen, Xinyuan and Wang, Limin and Lin, Dahua and Qiao, Yu and Liu, Ziwei},
    booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
    year={2024}
}
TL;DR: Extends VBench with (1) VBench-I2V for image-to-video, (2) VBench-Long for long videos, and (3) VBench-Trustworthiness covering fairness, bias, and safety.
VBench++: Comprehensive and Versatile Benchmark Suite for Video Generative Models
Ziqi Huang∗, Fan Zhang∗, Xiaojie Xu, Yinan He, Jiashuo Yu, Ziyue Dong, Qianli Ma, Nattapol Chanpaisit, Chenyang Si, Yuming Jiang, Yaohui Wang, Xinyuan Chen, Ying-Cong Chen, Limin Wang, Dahua Lin+, Yu Qiao+, Ziwei Liu+
IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI), 2025
VBench++ supports a wide range of video generation tasks, including text-to-video and image-to-video, with an adaptive Image Suite for fair evaluation across different settings. It evaluates not only technical quality but also the trustworthiness of generative models, offering a comprehensive view of model performance. We continually incorporate more video generative models into VBench to inform the community about the evolving landscape of video generation.
Note: The code and README for the VBench++ components are located at:
vbench2_beta_i2vvbench2_beta_longvbench2_beta_trustworthiness@article{huang2025vbench++,TL;DR: Extends VBench to evaluate intrinsic faithfulness — a key challenge for next-generation video generation models.
VBench-2.0: Advancing Video Generation Benchmark Suite for Intrinsic Faithfulness
Dian Zheng∗, Ziqi Huang∗, Hongbo Liu, Kai Zou, Yinan He, Fan Zhang, Yuanhan Zhang, Jingwen He, Wei-Shi Zheng+, Yu Qiao+, Ziwei Liu+
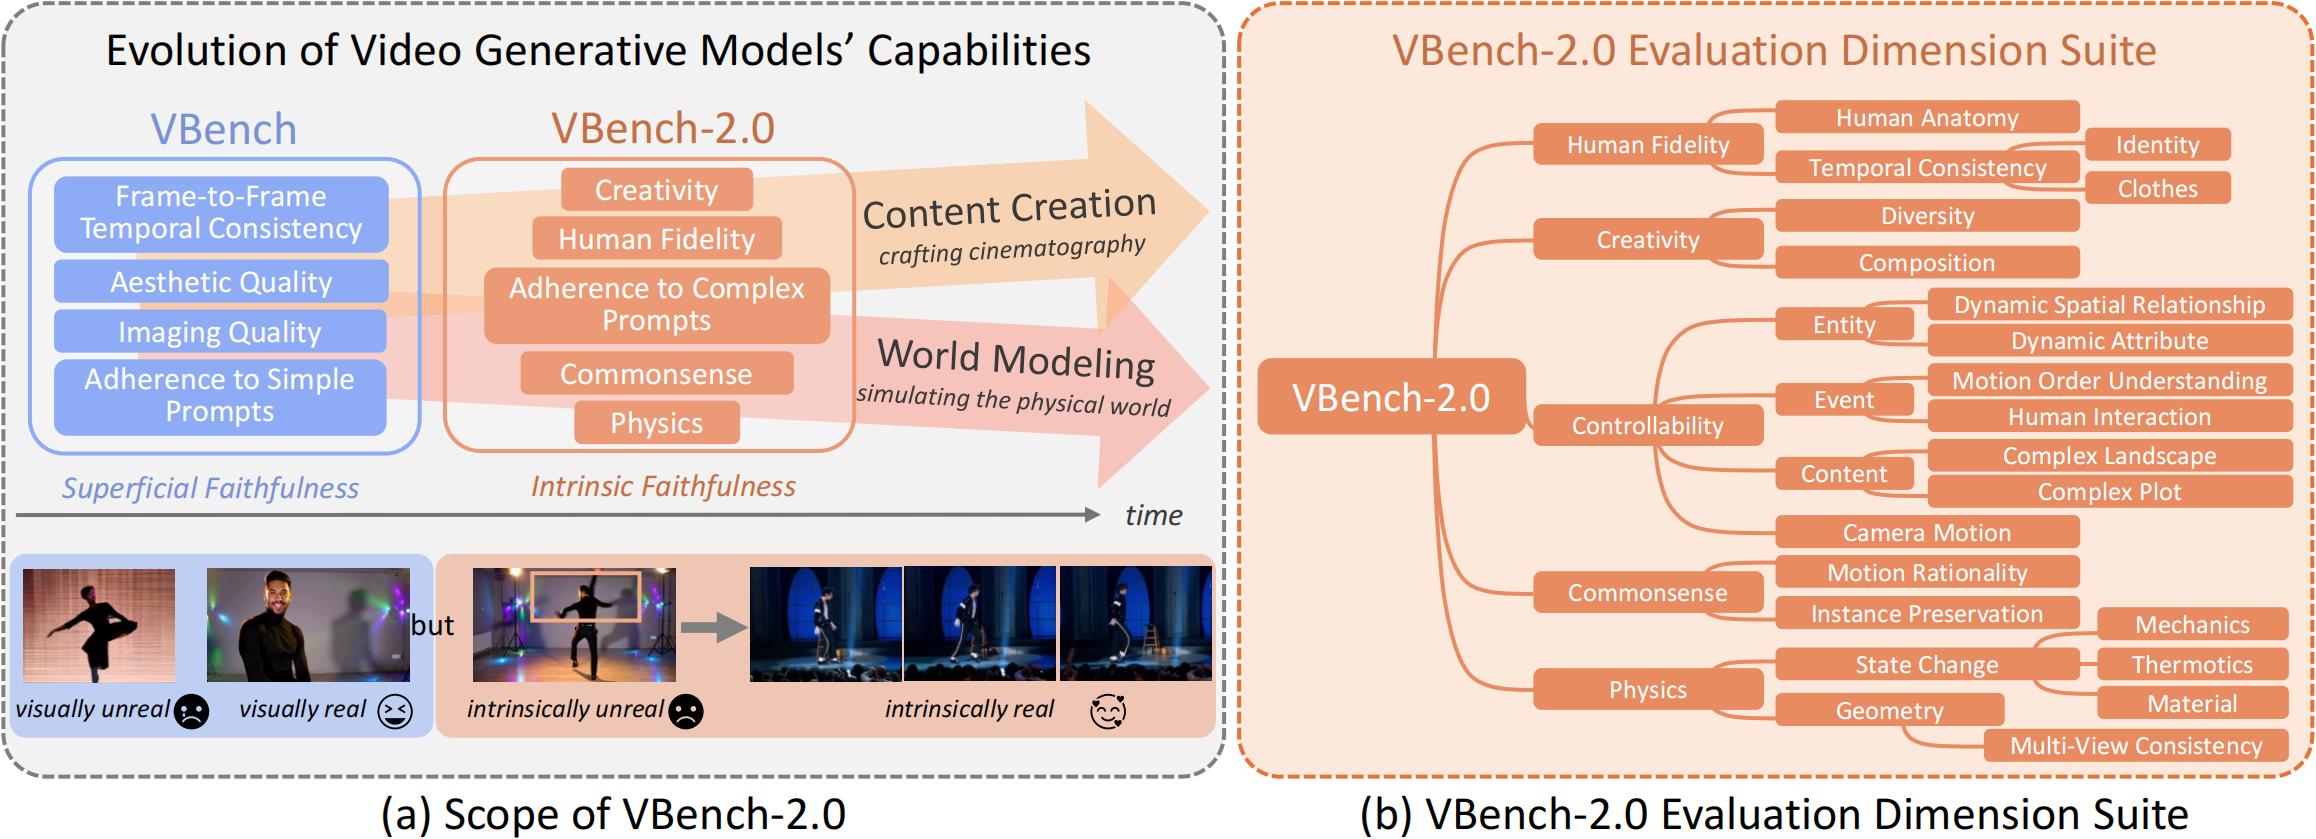 Overview of VBench-2.0. (a) Scope of VBench-2.0. Video generative models have progressed from achieving superficial faithfulness in fundamental technical aspects such as pixel fidelity and basic prompt adherence, to addressing more complex challenges associated with intrinsic faithfulness, including commonsense reasoning, physics-based realism, human motion, and creative composition. While VBench primarily assessed early-stage technical quality, VBench-2.0 expands the benchmarking framework to evaluate these advanced capabilities, ensuring a more comprehensive assessment of next-generation models. (b) Evaluation Dimension of VBench-2.0. VBench-2.0 introduces a structured evaluation suite comprising five broad categories and 18 fine-grained capability dimensions.
Note: The code and README for the VBench-2.0 components are located at link, relative path: VBench-2.0.
@article{zheng2025vbench2,
    title={{VBench-2.0}: Advancing Video Generation Benchmark Suite for Intrinsic Faithfulness},
    author={Zheng, Dian and Huang, Ziqi and Liu, Hongbo and Zou, Kai and He, Yinan and Zhang, Fan and Zhang, Yuanhan and He, Jingwen and Zheng, Wei-Shi and Qiao, Yu and Liu, Ziwei},
    journal={arXiv preprint arXiv:2503.21755},
    year={2025}
}
vbench is updated to version 0.1.2. This includes changes in the preprocessing for high-resolution images/videos for imaging_quality, support for evaluating customized videos, and minor bug fixes.pip install vbench.['subject_consistency', 'background_consistency', 'temporal_flickering', 'motion_smoothness', 'dynamic_degree', 'aesthetic_quality', 'imaging_quality', 'object_class', 'multiple_objects', 'human_action', 'color', 'spatial_relationship', 'scene', 'temporal_style', 'appearance_style', 'overall_consistency']See our leaderboard for the most updated ranking and numerical results (with models like Gen-3, Kling, Pika).
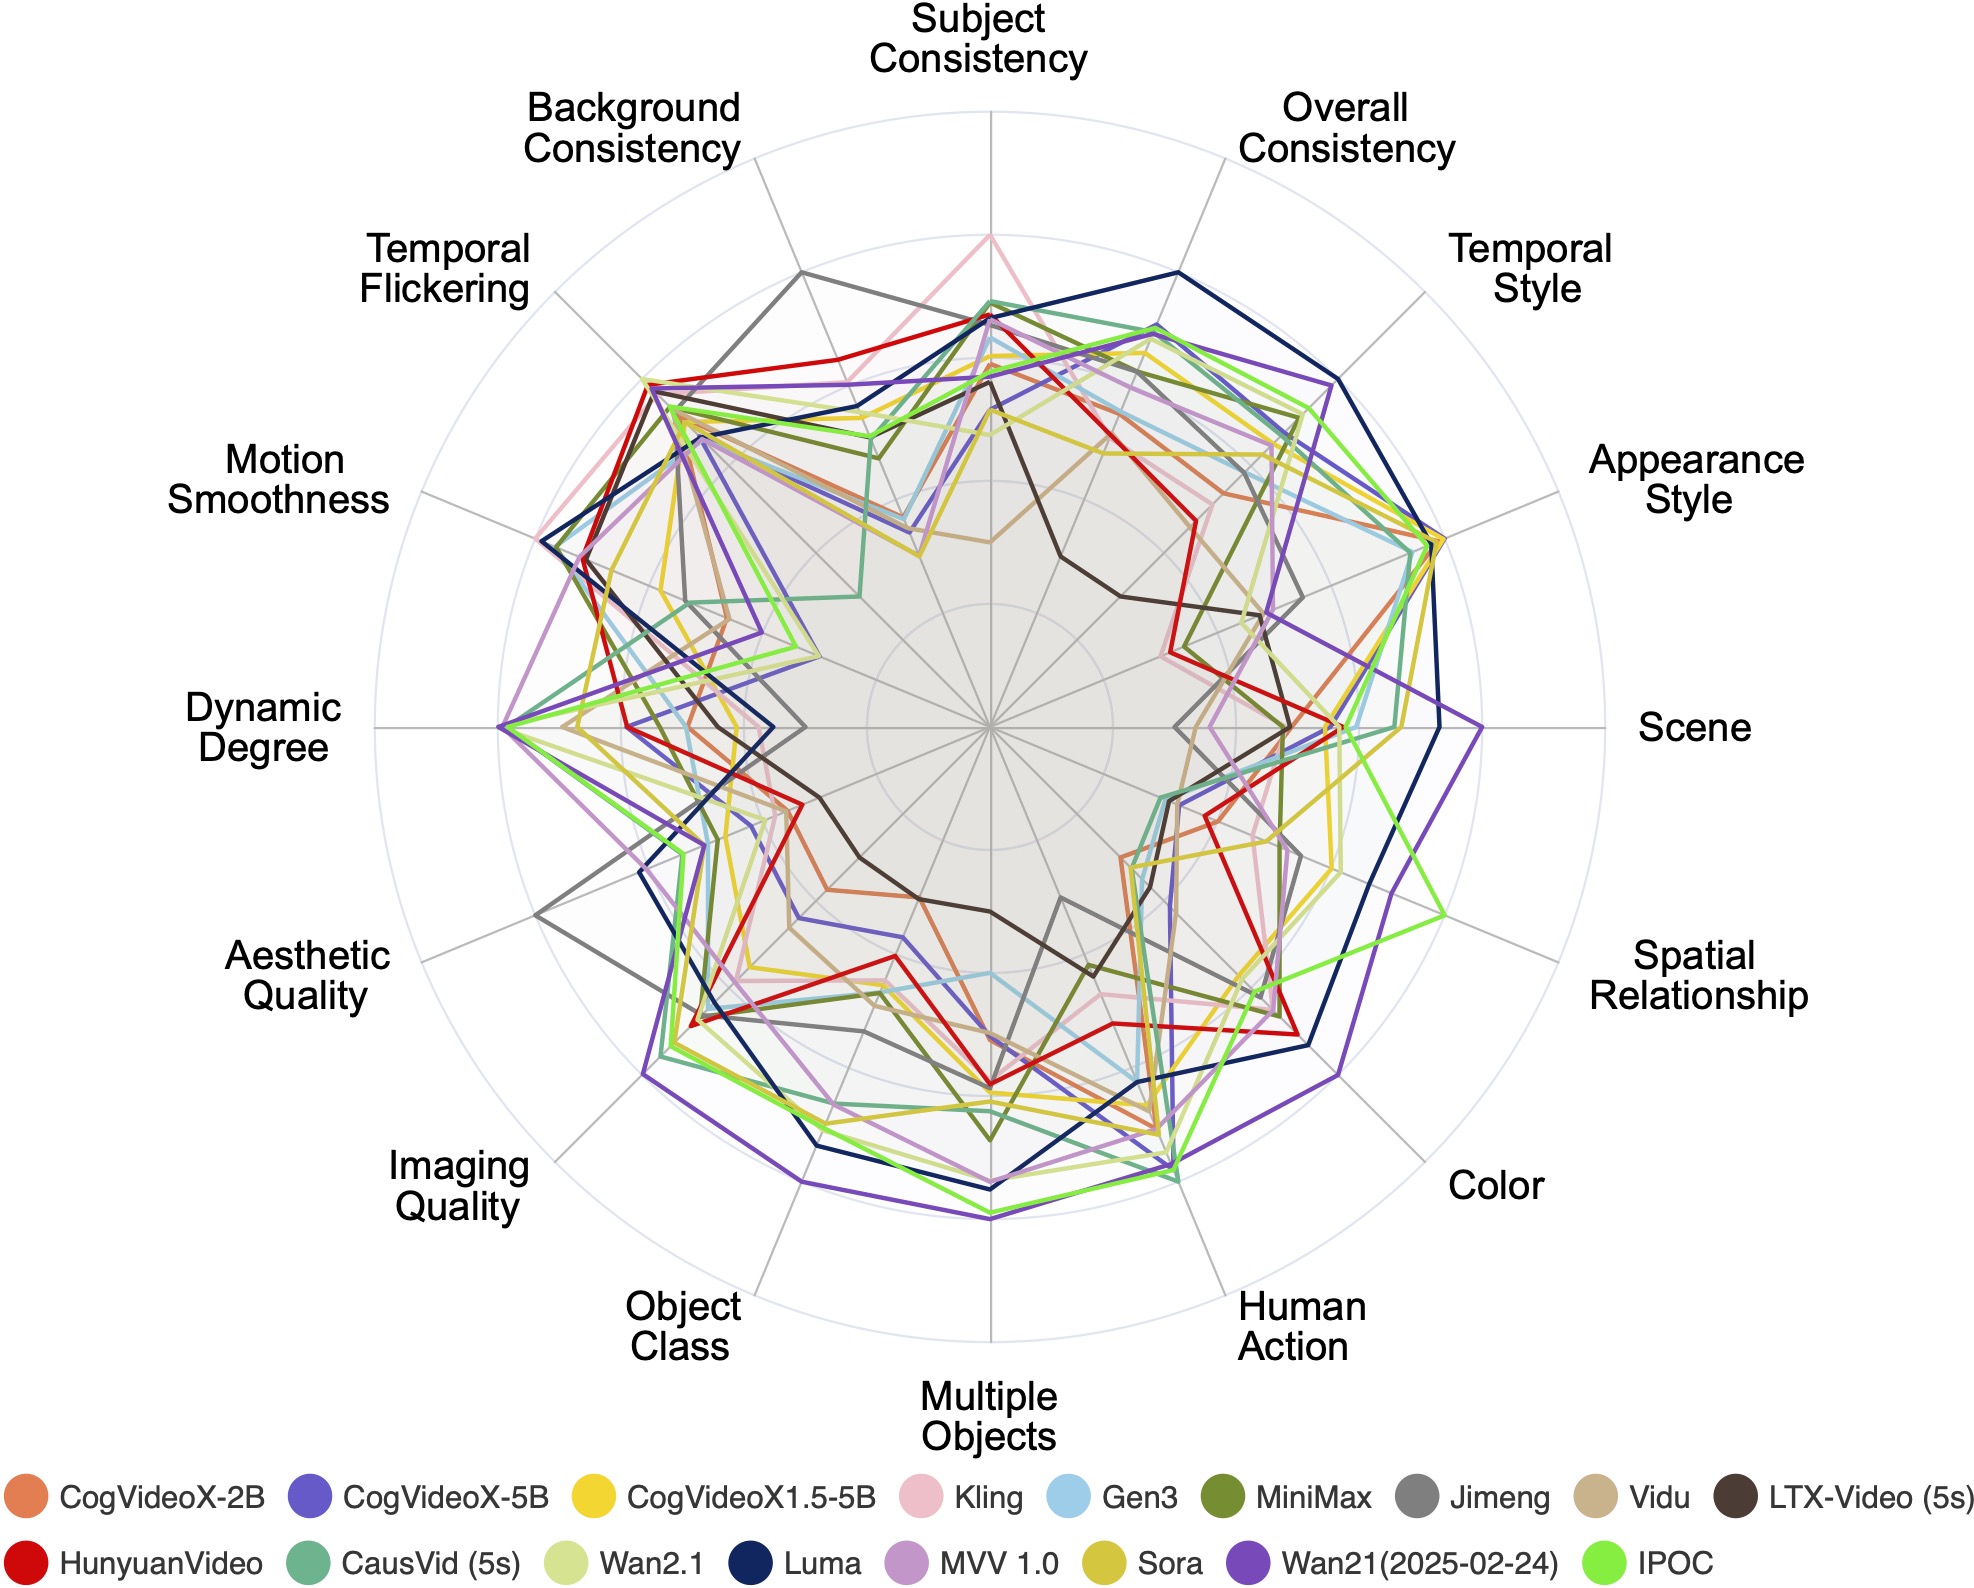
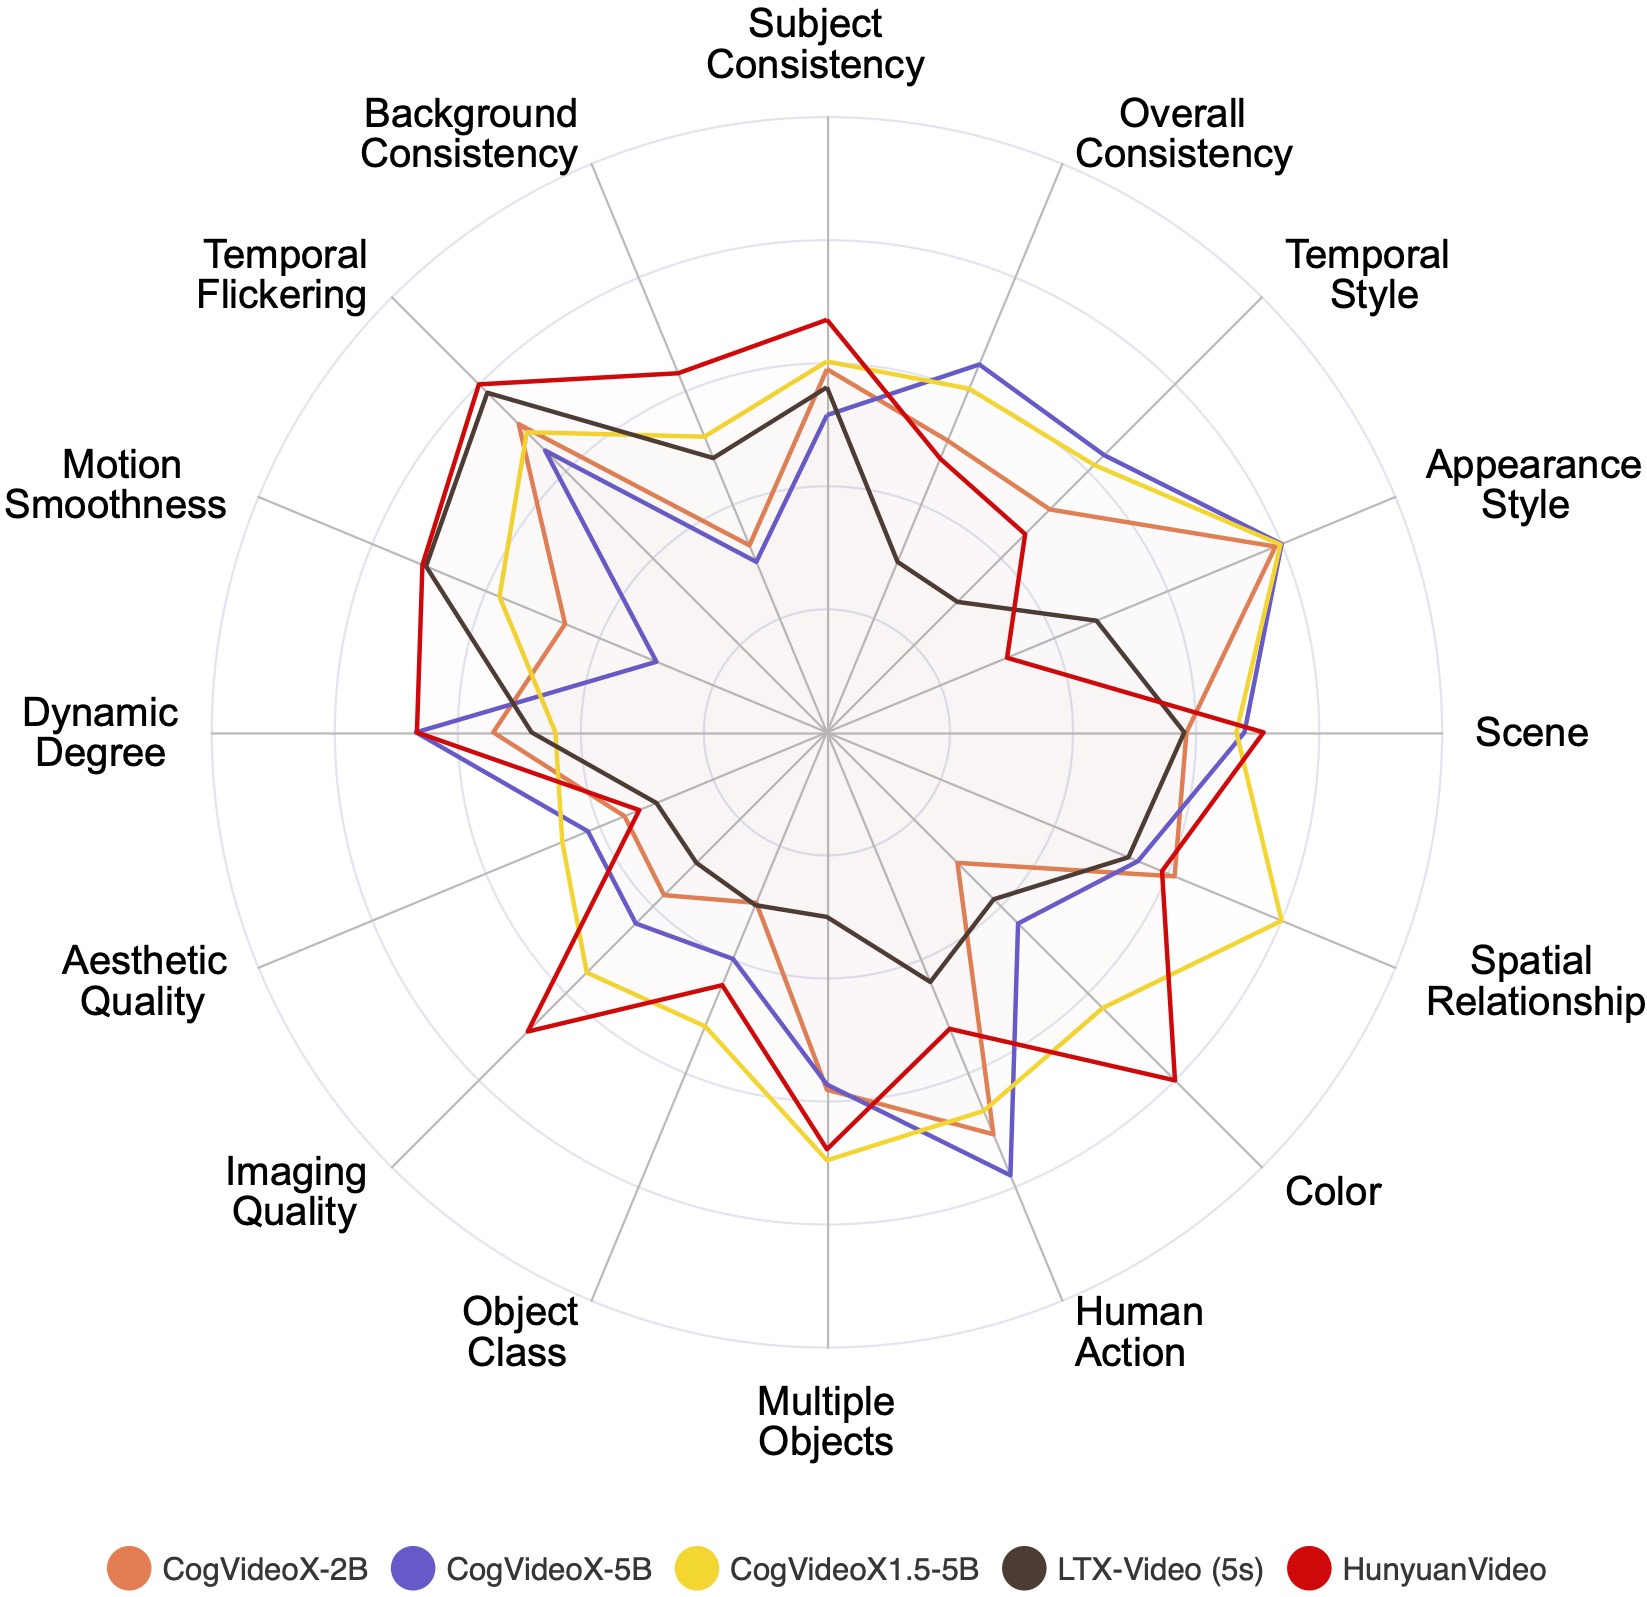
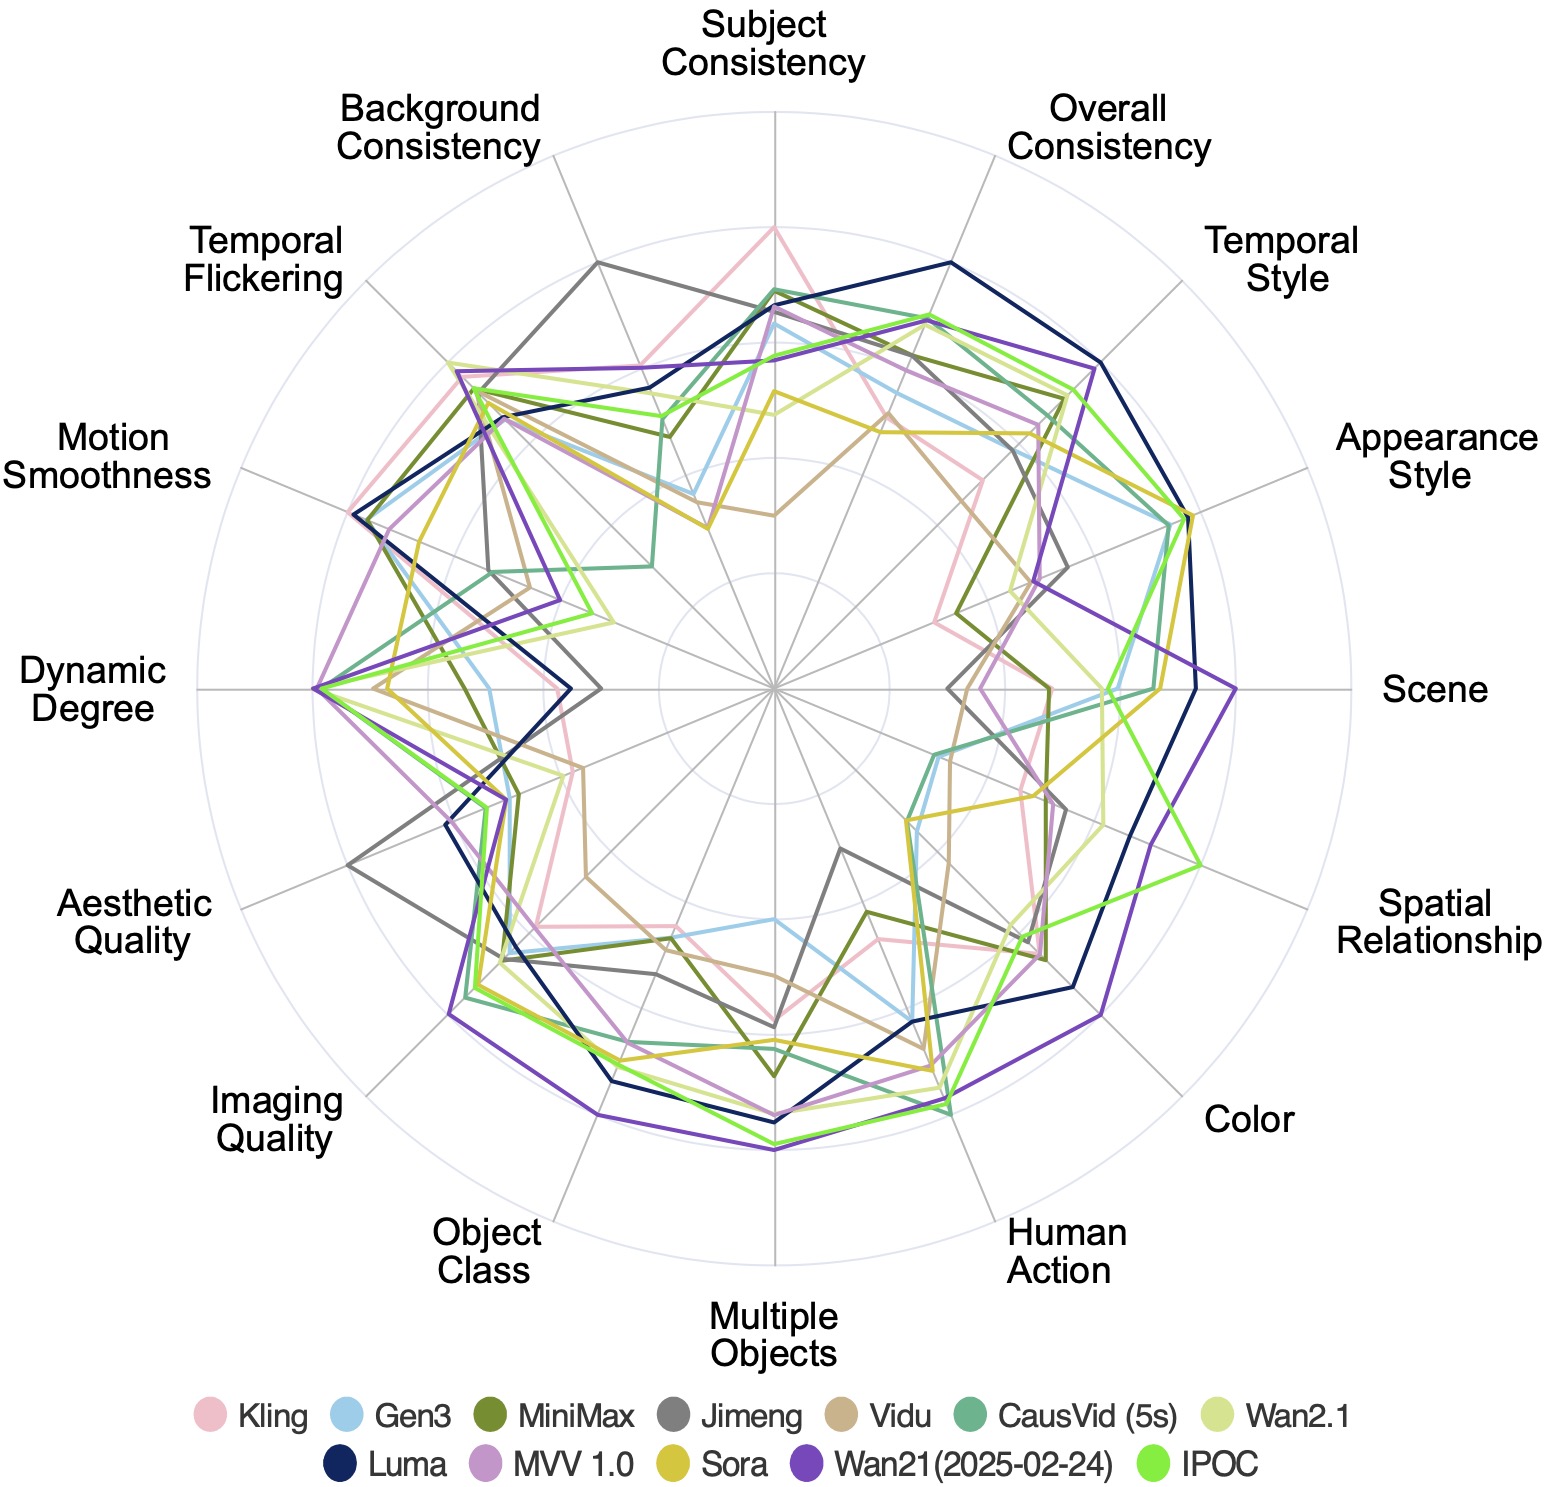
Additionally, we present radar charts separately for the evaluation results of open-source and closed-source models. The results are normalized per dimension for clearer comparisons.
See numeric values at our Leaderboard :1st_place_medal::2nd_place_medal::3rd_place_medal:
pip install torch torchvision --index-url https://download.pytorch.org/whl/cu118 # or any other PyTorch version with CUDA<=12.1
pip install vbench
To evaluate some video generation ability aspects, you need to install detectron2 via:
pip install detectron2@git+https://github.com/facebookresearch/detectron2.git
Download VBench_full_info.json to your running directory to read the benchmark prompt suites.
mode=custom_input, and you can evaluate your own videos.'subject_consistency', 'background_consistency', 'motion_smoothness', 'dynamic_degree', 'aesthetic_quality', 'imaging_quality'To evaluate videos with customized input prompt, run our script with --mode=custom_input:
python evaluate.py \
    --dimension $DIMENSION \
    --videos_path /path/to/folder_or_video/ \
    --mode=custom_input
vbench evaluate \
    --dimension $DIMENSION \
    --videos_path /path/to/folder_or_video/ \
    --mode=custom_input
To evaluate using multiple gpus, we can use the following commands:
torchrun --nproc_per_node=${GPUS} --standalone evaluate.py ...args...
vbench evaluate --ngpus=${GPUS} ...args...
vbench evaluate --videos_path $VIDEO_PATH --dimension $DIMENSION
vbench evaluate --videos_path "sampled_videos/lavie/human_action" --dimension "human_action"
from vbench import VBench
my_VBench = VBench(device, , )
my_VBench.evaluate(
    videos_path = <video_path>,
    name = ,
    dimension_list = [, , ...],
)
from vbench import VBench
my_VBench = VBench(device, "vbench/VBench_full_info.json", "evaluation_results")
my_VBench.evaluate(
    videos_path = "sampled_videos/lavie/human_action",
    name = "lavie_human_action",
    dimension_list = ["human_action"],
)
vbench evaluate \
    --videos_path $VIDEO_PATH \
    --dimension $DIMENSION \
    --mode=vbench_category \
    --category=$CATEGORY
 →
 →
 →
 →
 →
 →
 →