1
 →

Burn is a next generation tensor library and Deep Learning Framework that doesn't compromise on flexibility, efficiency and portability.
tracel-ai/burn is an open-source project on GitHub, mainly written in Rust. Burn is a next generation tensor library and Deep Learning Framework that doesn't compromise on flexibility, efficiency and portability. It currently holds 16,053 stars and 1,079 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the Today's Trending board, currently at rank #48 with 17 new stars today.


---
Burn is both a tensor library and a deep learning framework, optimized for
numerical
computing, training and inference.
Training and inference usually live in separate worlds. Models are typically trained in Python then exported to an open format like ONNX or optimized for production engines like vLLM, ONNX Runtime, or TensorRT. This export step is often brittle and lossy, ruling out complex architectures and advanced deployment use cases.
Burn unifies the two. By executing multi-platform tensor operations via a single, unified API, the exact code used for training is the exact code that runs in production. This makes workloads like on-device personalization and federated learning straightforward, while enabling teams to go from prototype to deployment in a single codebase.
Burn preserves the intuitive ergonomics of PyTorch, with dynamic shapes and graphs, but JIT-compiles streams of tensor operations, performing automatic kernel fusion. You get the flexibility of dynamic graphs without the performance drop.
Rust used to be a tough sell for research: long compilation times disrupted the fast edit-compile-run loop that draws researchers to Python. Burn changes this paradigm. Designed around incremental compilation, modifying model code recompiles in under 5 seconds, even in release mode. This delivers a Python-like feedback loop with the speed and safety of Rust.
Burn is the core of a growing, fully open-source Rust AI ecosystem. You are not adopting a single library, you are joining a stack that spans GPU compute, model interop and domain toolkits, with plenty of room to help shape what comes next.
| Category | Project | Description |
| ------------- | ----------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Compute | CubeCL | GPU compute language and compiler behind Burn's accelerated backends. Write kernels once in Rust, run on CUDA, ROCm, Metal, Vulkan and WebGPU. Usable standalone. |
| Model interop | burn-onnx | Import ONNX models into Burn as native Rust code |
| | burn-store | Save, load and import model weights, including PyTorch and Safetensors |
| Domains | burn-vision | Computer vision operators and building blocks |
| | burn-rl | Reinforcement learning building blocks |
| | burn-dataset | Dataset loading, transforms and ready-made sources |
| Models | models | Curated pre-trained models and examples built with Burn |
| Tooling | burn-bench | Benchmark and compare backends, tracking performance over time |
Burn's CubeCL backends (CUDA, ROCm, Metal, Vulkan, WebGPU,
CPU) compose with autodiff, fusion and remote-execution decorators, while the pure-Rust Flex
CPU/no_std backend composes with autodiff only. See
Supported Backends below for the full matrix.
Every project here is open-source and actively developed. Want to help build the Rust AI ecosystem? The good first issues are a great place to start, and the Contributing guide will get you set up.
These crates are not maintained by Tracel, but they are part of the same Rust AI story. Anything that helps you load data, build environments, or ship models belongs here. Built something that fits? Open a PR to add it!
| Category | Crate | Description | | -------------------------- | --------------------------------------------------------------- | ----------------------------------------------------------------- | | Data & loading | polars | Fast DataFrames for tabular data | | | arrow-rs | Apache Arrow columnar memory format | | | image | Image decoding, encoding and processing | | | hf-hub | Download models and datasets from the Hugging Face Hub | | Tokenization & NLP | tokenizers | Fast, production-ready tokenizers | | | rust-bert | Ready-to-use NLP pipelines and transformer models | | Numerical & linear algebra | ndarray | N-dimensional arrays | | | nalgebra | Linear algebra | | Classical ML | linfa | Classical ML toolkit, in the spirit of scikit-learn | | | smartcore | Classical ML algorithms, no BLAS/LAPACK required | | Inference & runtimes | candle | Minimalist ML framework with a focus on LLM inference | | | mistral.rs | Fast, multimodal LLM inference engine | | | ort | ONNX Runtime bindings for hardware-accelerated inference | | | tract | Pure-Rust inference for ONNX and NNEF models | | | wonnx | 100% Rust, WebGPU-accelerated ONNX runtime for native and the web | | LLM apps & RAG | rig | Build modular LLM applications and agents | | | langchain-rust | LangChain-style chain orchestration | | Embeddings & vector search | fastembed | Generate text embeddings and rerank locally | | | qdrant | Vector search engine, written in Rust | | | lancedb | Embedded, developer-friendly vector database | | Computer vision | kornia-rs | Low-level 3D computer vision library | | Simulation & environments | rapier | Physics engine for robotics and RL environments | | Visualization | rerun | Multimodal data and CV/robotics visualization | | | plotters | Plotting and charting |
Burn strives to be as fast as possible on as many hardwares as possible, with robust implementations. We believe this flexibility is crucial for modern needs where you may train your models in the cloud, then deploy on customer hardwares, which vary from user to user.
Most backends support all operating systems, so we don't mention them in the tables below.
GPU Backends:
| | CUDA | ROCm | Metal | Vulkan | WebGPU | | ------- | ---- | ---- | ----- | ------ | ------ | | Nvidia | ☑️ | - | - | ☑️ | ☑️ | | AMD | - | ☑️ | - | ☑️ | ☑️ | | Apple | - | - | ☑️ | - | ☑️ | | Intel | - | - | - | ☑️ | ☑️ | | Qualcom | - | - | - | ☑️ | ☑️ | | Wasm | - | - | - | - | ☑️ |
CPU Backends:
| | Cpu (CubeCL) | Flex | | ------ | ------------ | ---- | | X86 | ☑️ | ☑️ | | Arm | ☑️ | ☑️ | | Wasm | - | ☑️ | | no-std | - | ☑️ |
The two native CPU backends are independent. Cpu (cpu feature) is the CubeCL
runtime for the CPU: it JIT-compiles the same kernels as the GPU backends through LLVM and supports
fusion. Flex (flex feature) is a pure-Rust eager backend with no
native dependencies that also runs on Wasm and no_std.
Migration: LibTorch was deprecated in0.22.0and has been removed frommain.
For GPU acceleration, use a CubeCL backend (CUDA,
ROCm, Metal, Vulkan, WebGPU). For CPU execution, use the CubeCL CPU backend or burn-flex.
Burn's backend architecture lets you swap backends while keeping the same model code. You can enable
multiple backends in the same application and choose the device for your tensors and modules at
runtime through Device. This gives you the freedom to use different backends side by side and
select the hardware best suited to each workload.
Autodifferentiation and automatic kernel fusion integrate with the same tensor and module APIs, so models benefit from these capabilities on supported backends without changing their implementation.
In application code, autodiff is runtime context carried by tensors. Devices provide the default context for newly created tensors, and each tensor can later enable or remove autodiff independently. Enabling autodiff permits graph recording; it does not by itself make a tensor retain gradients.
Internally, Burn implements this by decorating a concrete backend, so autodiff cannot execute by
itself. Enable it on a device before creating tensors or initializing a model. With the autodiff
and wgpu features enabled:
use burn::tensor::{Device, Distribution, Tensor};
fn main() {
    let device = Device::wgpu(Default::default()).autodiff();
let x: Tensor<2> = Tensor::random([32, 32], Distribution::Default, &device);
    let y: Tensor<2> = Tensor::random([32, 32], Distribution::Default, &device).require_grad();
let tmp = x.clone() + y.clone();
    let tmp = tmp.matmul(x);
    let tmp = tmp.exp();
let grads = tmp.backward();
    let y_grad = y.grad(&grads).unwrap();
    println!("{y_grad}");
}
backward() checks graph participation at runtime. Enable autodiff before the forward pass and call
require_grad() on source leaves whose gradients you need. is_autodiff(), is_tracked(), and
is_require_grad() inspect autodiff association, graph participation, and gradient retention
respectively. See the autodiff guide.
See the Autodiff Backend README for more details.
This backend decorator enhances a backend with kernel fusion, provided that the inner backend
supports it. Note that you can compose this backend with other backend decorators such as Autodiff.
All first-party accelerated backends (like WGPU and CUDA) use Fusion by default (burn/fusion
feature flag), so you typically don't need to apply it manually.
#[cfg(not(feature = "fusion"))]
pub type Cube = burn_cubecl::CubeBackend;
[cfg(feature = "fusion")]
pub type Cube = burn_fusion::Fusion<burn_cubecl::CubeBackend>;
Device::autodiff().gradient_checkpointing() enables the balanced gradient-checkpointing strategy,
which trades recomputation for reduced activation storage during training.
See the Fusion Backend README for more details.
Remote execution has a client and a server. The server's devices select the compute backend;
clients use a remote Device with the same tensor API. Iroh, the default transport, reaches a
server across any network, authenticated and encrypted; see the server example
and the distributed computing guide. On a
trusted network, WebSocket is the simplest setup: enable remote-server, remote-websocket, and
cuda on the server, and remote-websocket plus autodiff on the client:
use burn::remote::RemoteHost;
use burn::server::{RemoteServer, ServeError, WebSocketTransport};
use burn::tensor::{Device, Distribution, Tensor};
fn main_server() -> Result<(), ServeError> {
    RemoteServer::new([Device::cuda(0)]).serve(WebSocketTransport::new(3000))
}
fn main_client() -> Result<(), burn::remote::ConnectError> {
    let host = RemoteHost::websocket("ws://localhost:3000");
    let device = Device::remote_options(&host).init()?.autodiff();
    let tensor_gpu = Tensor::<2>::random([3, 3], Distribution::Default, &device);
    Ok(())
}
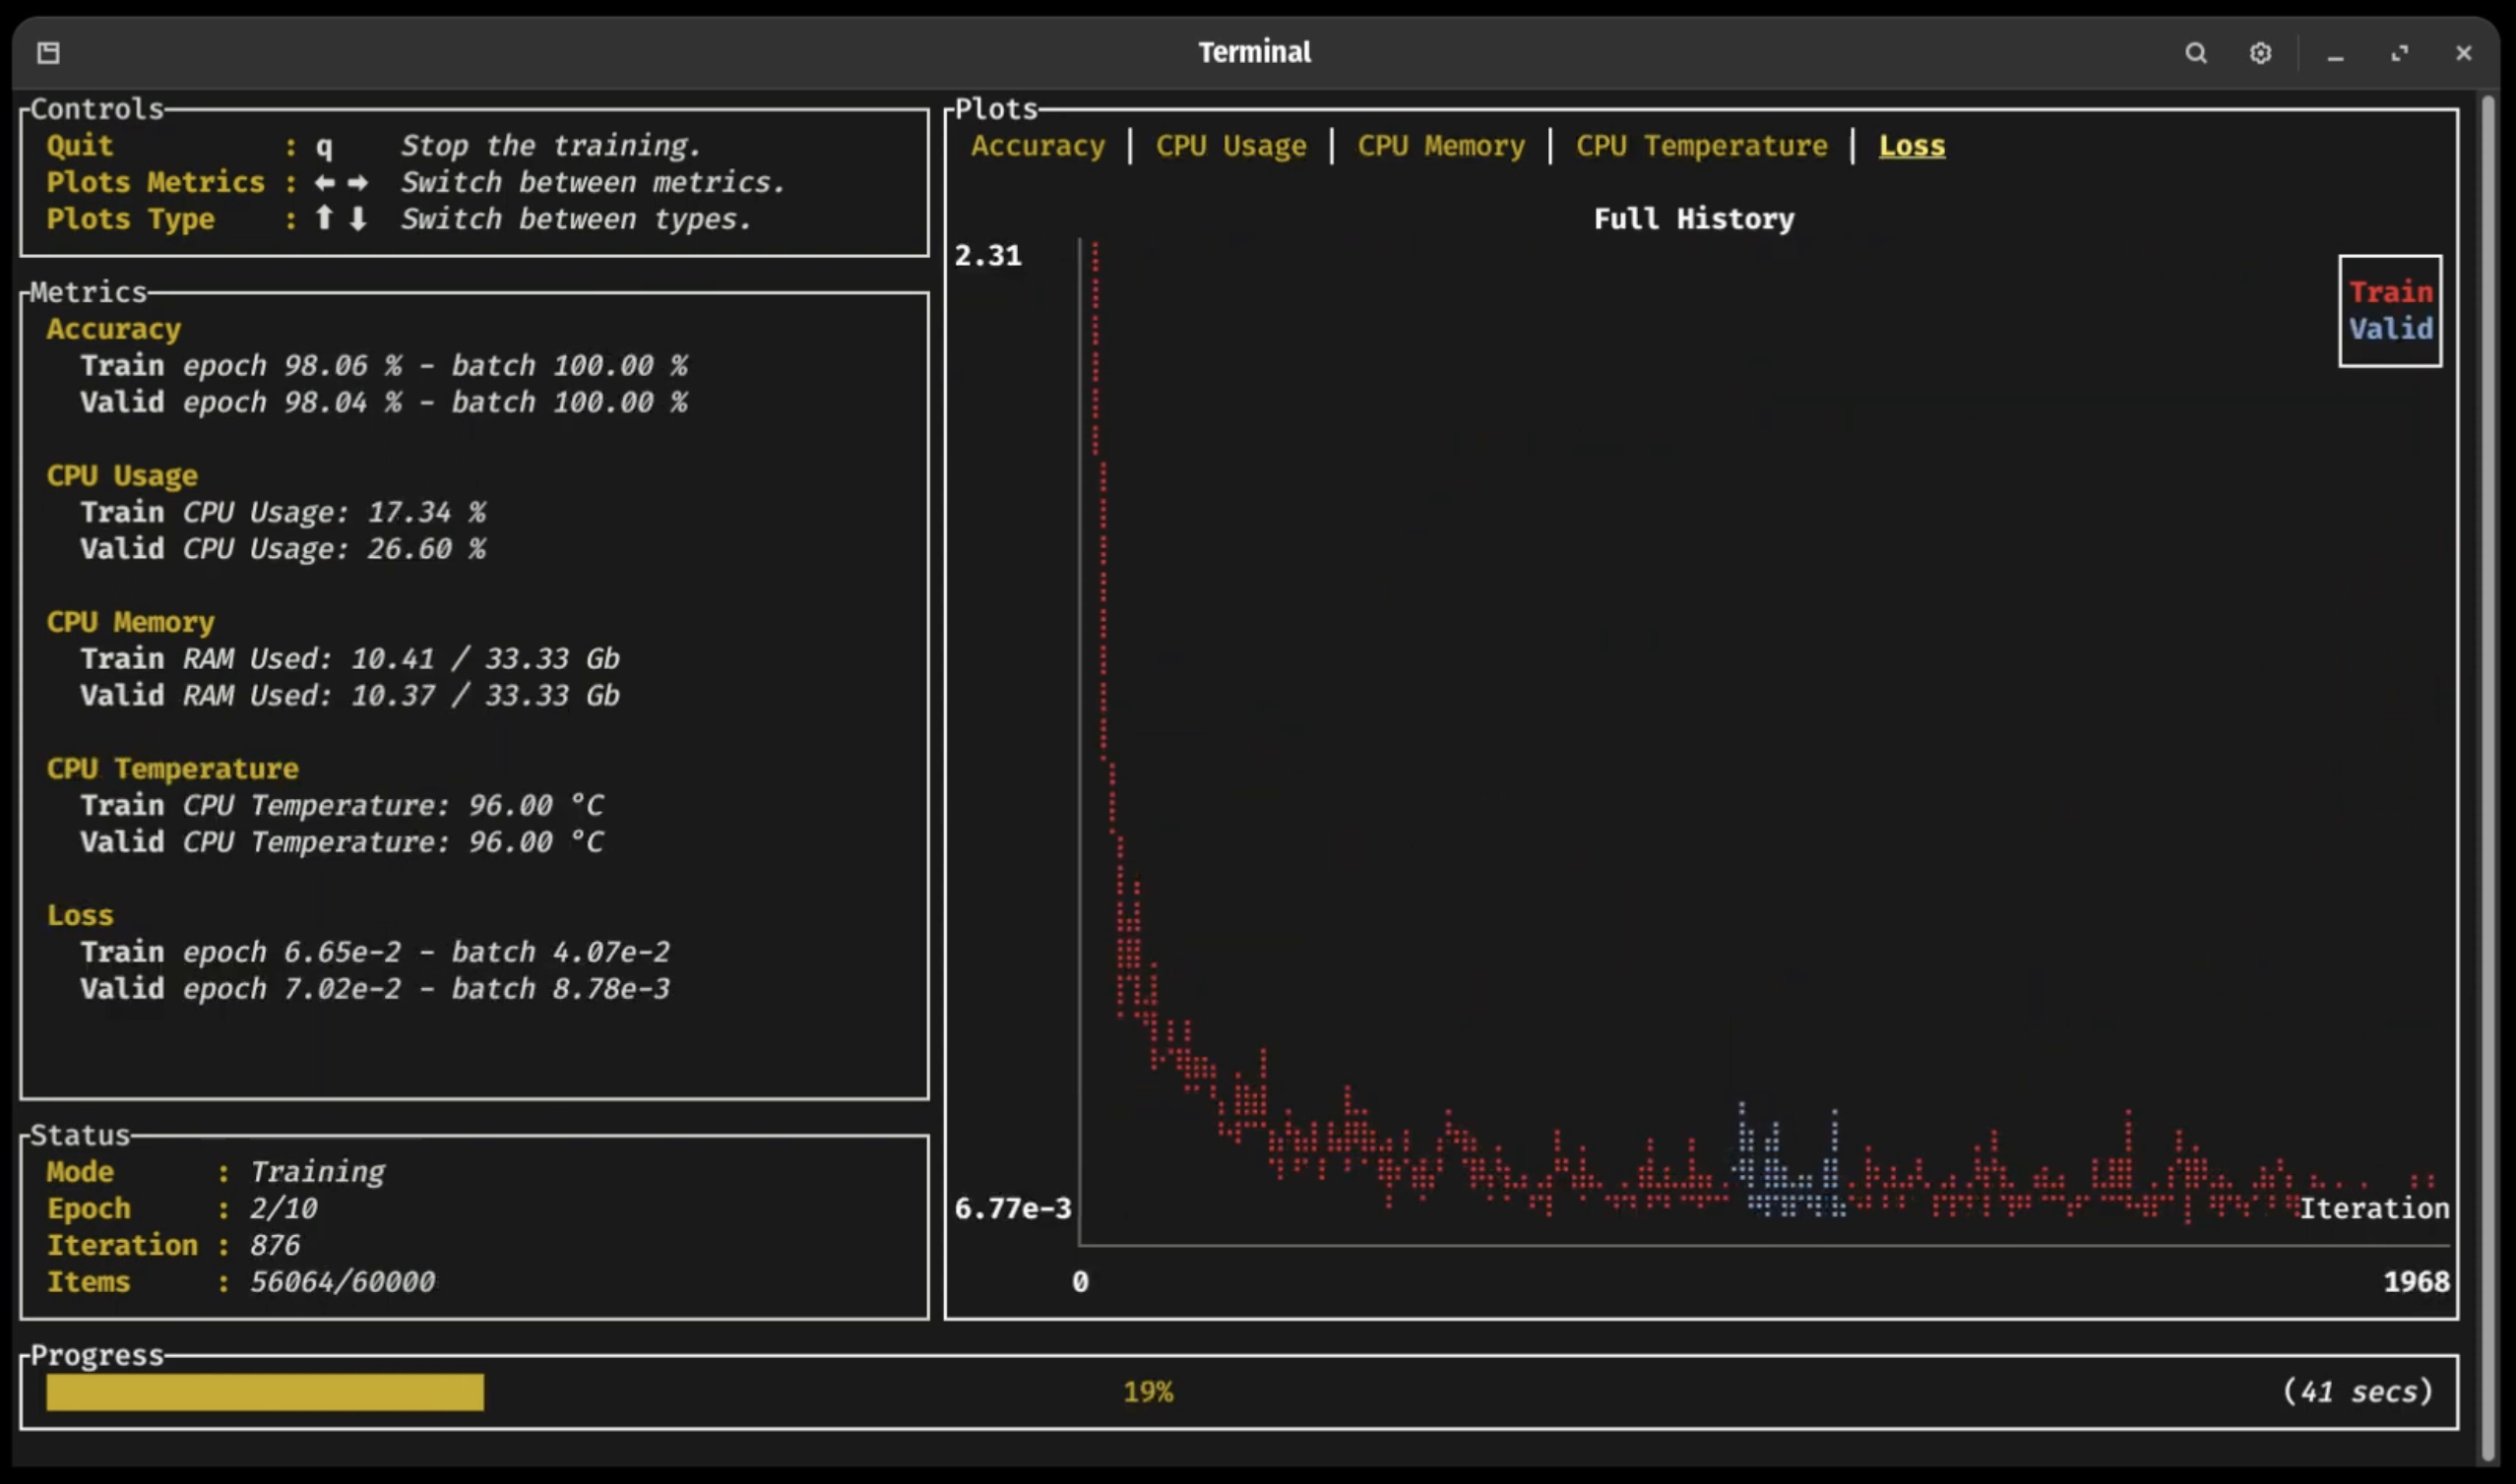
The whole deep learning workflow is made easy with Burn, as you can monitor your training progress with an ergonomic dashboard, and run inference everywhere from embedded devices to large GPU clusters.
Burn was built from the ground up with training and inference in mind. It's also worth noting how Burn, in comparison to frameworks like PyTorch, simplifies the transition from training to deployment, eliminating the need for code changes.
Click on the following sections to expand 👇
As you can see in the previous video (click on the picture!), a new terminal UI dashboard based on the Ratatui crate allows users to follow their training with ease without having to connect to any external application.
You can visualize your training and validation metrics updating in real-time and analyze the lifelong progression or recent history of any registered metrics using only the arrow keys. Break from the training loop without crashing, allowing potential checkpoints to be fully written or important pieces of code to complete without interruption 🛡
Burn supports importing ONNX (Open Neural Network Exchange) models through the burn-onnx crate, allowing you to easily port models from TensorFlow or PyTorch to Burn. The ONNX model is converted into Rust code that uses Burn's native APIs, enabling the imported model to run on any Burn backend (CPU, GPU, WebAssembly) and benefit from all of Burn's optimizations like automatic kernel fusion.
Our ONNX support is further described in this section of the Burn Book 🔥.
Note: This crate is in active development and currently supports a
limited set of ONNX operators.
You can load weights from PyTorch or Safetensors formats directly into your Burn-defined models. This makes it easy to reuse existing models while benefiting from Burn's performance and deployment features.
Learn more in the Saving & Loading Models section of the Burn Book.
Several of our backends can run in WebAssembly environments: Flex for CPU execution, and WGPU for GPU acceleration via WebGPU. This means that you can run inference directly within a browser. We provide several examples of this:
Burn's core components support no_std. This means it can run in bare metal environment such as embedded devices without an operating system.
As of now, only the Flex backend can be used in a _no_std_ environment.
To evaluate performance across different backends and track improvements over time, we provide a dedicated benchmarking suite.
Run and compare benchmarks using burn-bench.
Just heard of Burn? You are at the right place! Just continue reading this section and we hope you can get on board really quickly.
To begin working effectively with Burn, it is crucial to understand its key components and philosophy. This is why we highly recommend new users to read the first sections of The Burn Book 🔥. It provides detailed examples and explanations covering every facet of the framework, including building blocks like tensors, modules, and optimizers, all the way to advanced usage, like coding your own GPU kernels.
The project is constantly evolving, and we try as much as possible to keep the book up to date
with new additions. However, we might miss some details sometimes, so if you see something weird,
let us know! We also gladly accept Pull Requests 😄
Let's start with a code snippet that shows how intuitive the framework is to use! In the following, we declare a neural network module with some parameters along with its forward pass.
use burn::nn;
use burn::module::Module;
use burn::tensor::Tensor;
[derive(Module, Debug)]
pub struct PositionWiseFeedForward {
    linear_inner: nn::Linear,
    linear_outer: nn::Linear,
    dropout: nn::Dropout,
    gelu: nn::Gelu,
}
impl PositionWiseFeedForward {
    pub fn forward(&self, input: Tensor) -> Tensor {
        let x = self.linear_inner.forward(input);
        let x = self.gelu.forward(x);
        let x = self.dropout.forward(x);
self.linear_outer.forward(x)
    }
}
We have a somewhat large amount of examples in the repository that shows how to use the framework in different scenarios.
Following the book:
Module to train on the MNIST datasetLearner.
Additional examples:
→ →
 →
 →
 →
 →
 →
 →