1
 →

High-Quality Human Motion Video Generation with Confidence-aware Pose Guidance
Tencent/MimicMotion is an open-source project on GitHub, mainly written in Python. High-Quality Human Motion Video Generation with Confidence-aware Pose Guidance It currently holds 2,657 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Video Projects board and on the AI AI Video Projects list.
MimicMotion: High-Quality Human Motion Video Generation with Confidence-aware Pose Guidance
Yuang Zhang1,2, Jiaxi Gu1, Li-Wen Wang1, Han Wang1,2, Junqi Cheng1, Yuefeng Zhu1, Fangyuan Zou1
[1Tencent 2Shanghai Jiao Tong University]
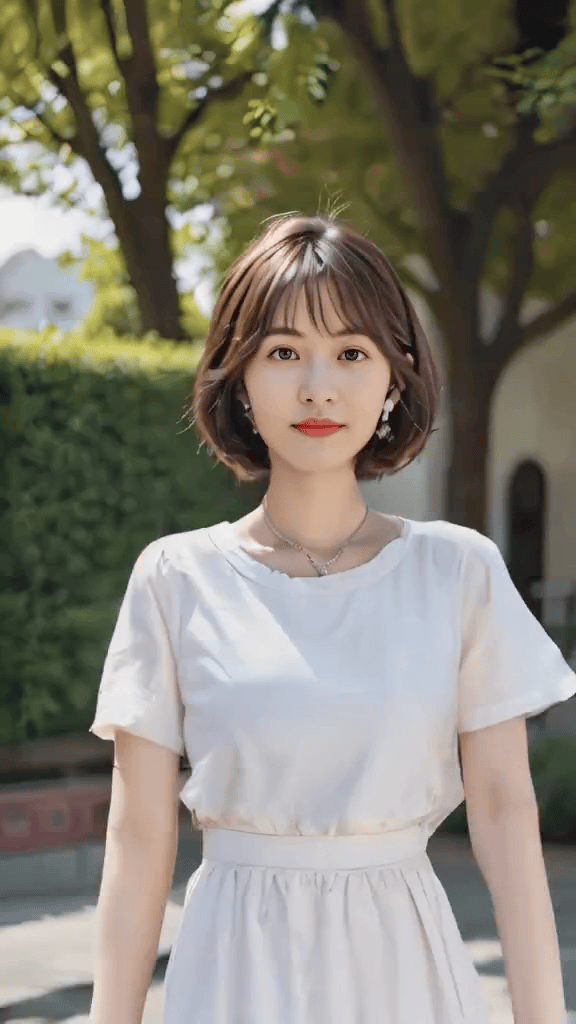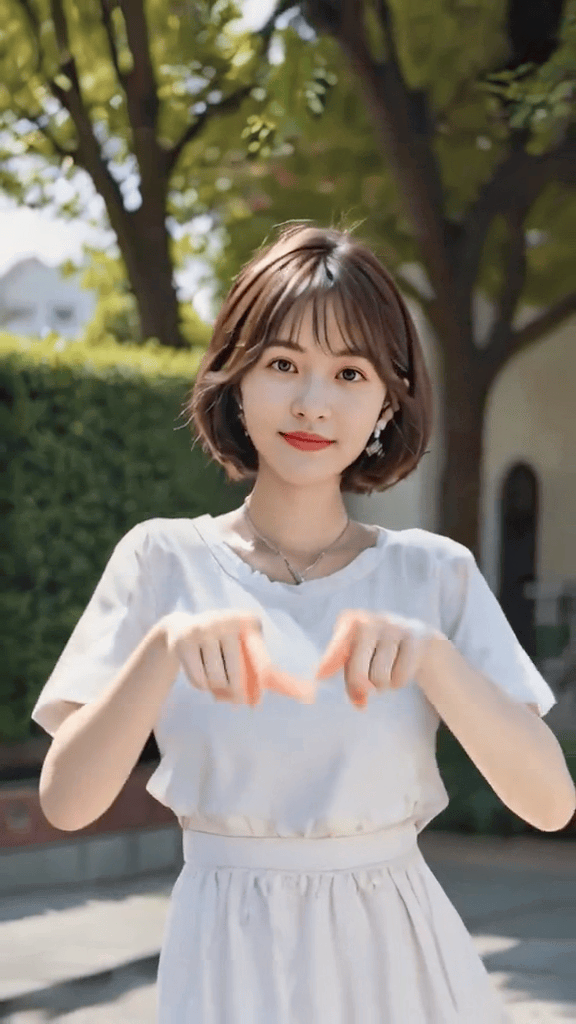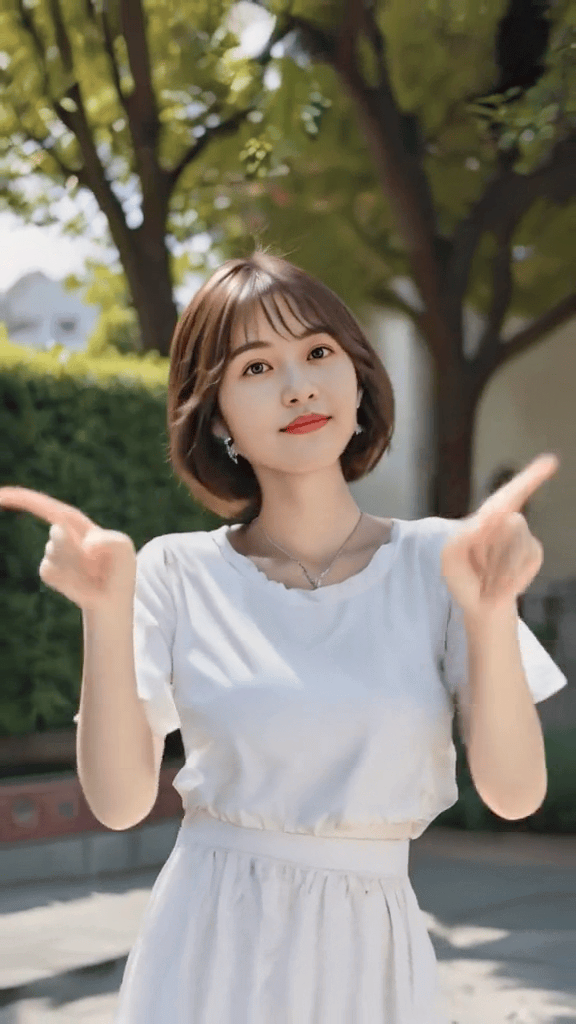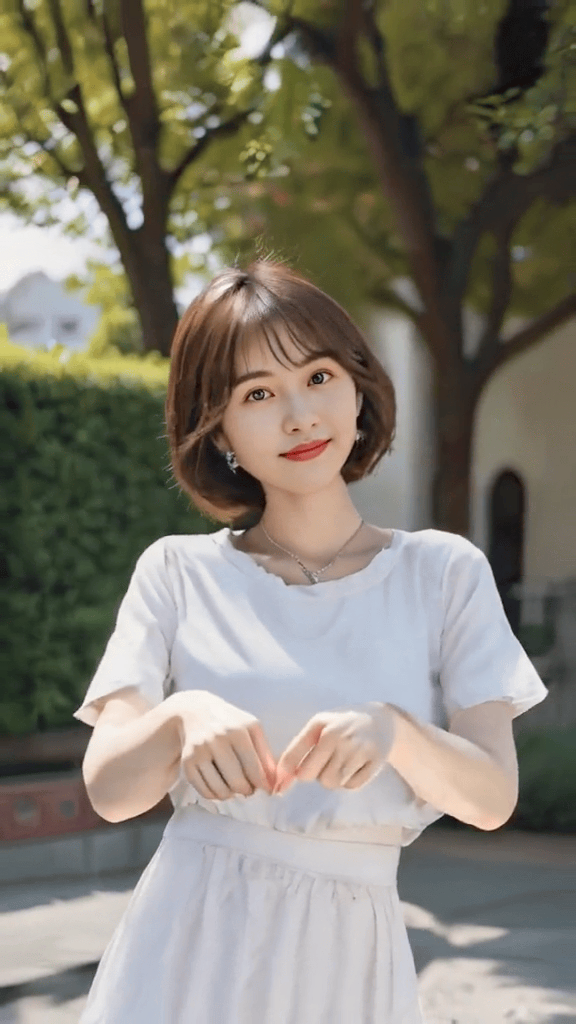
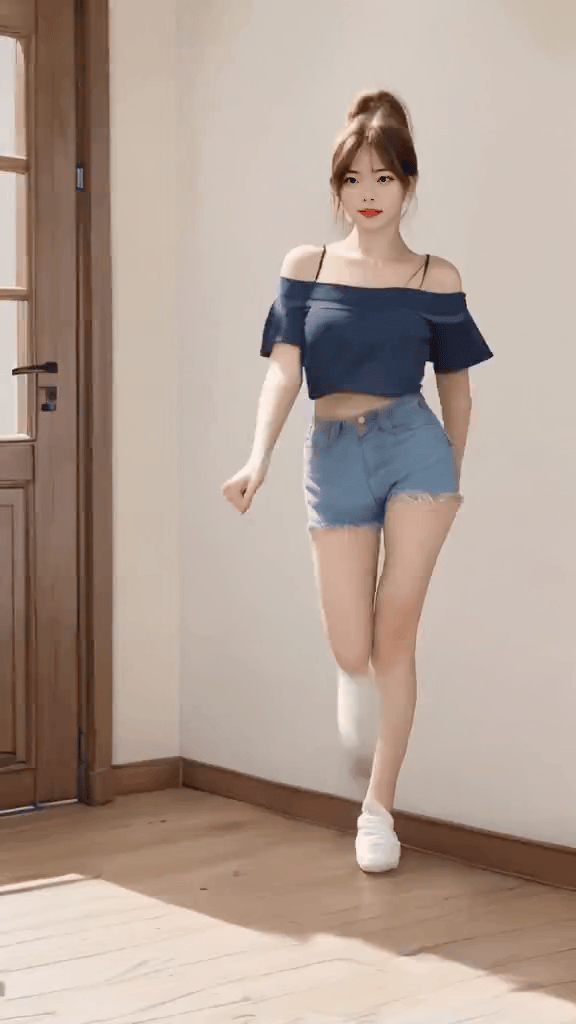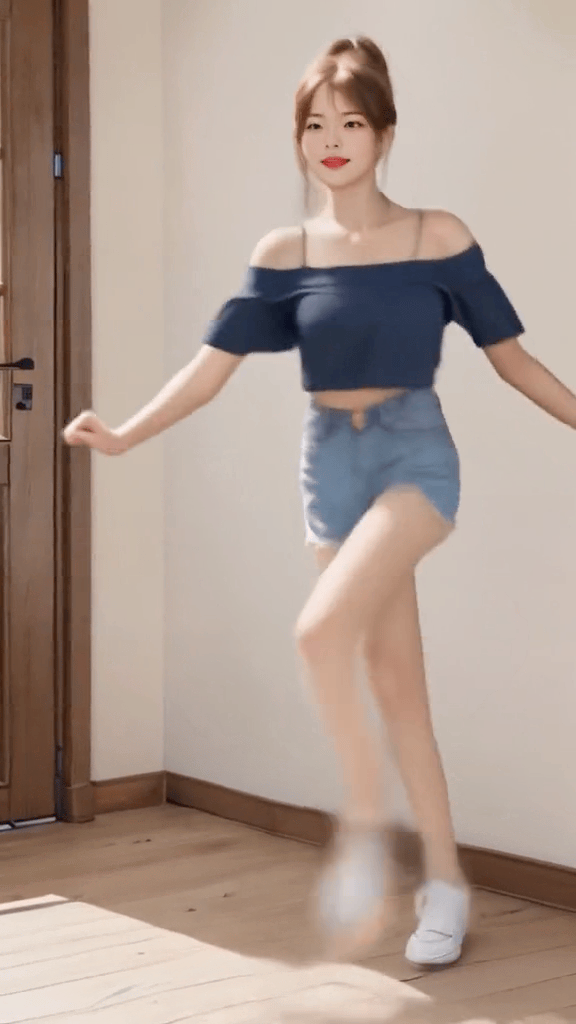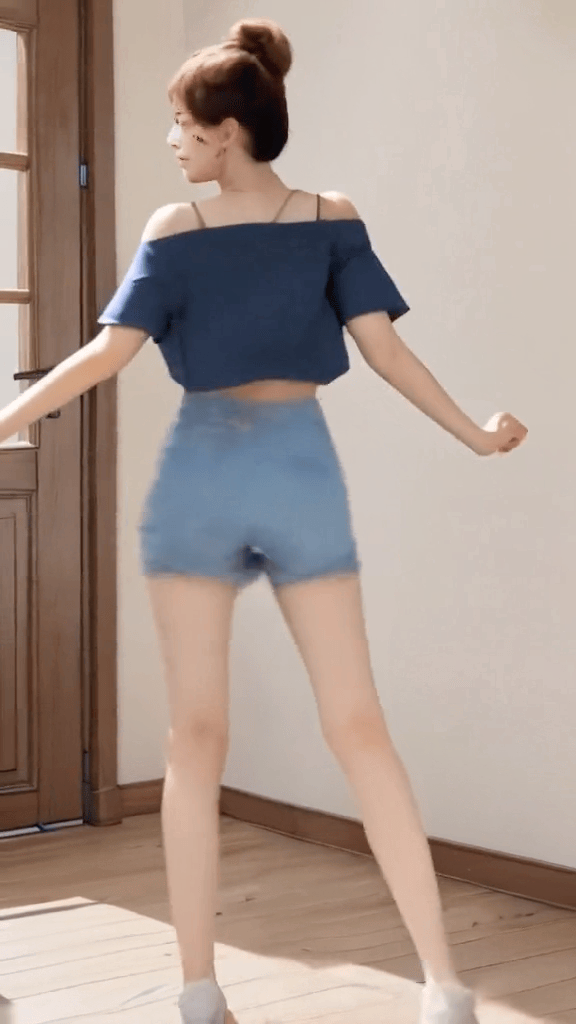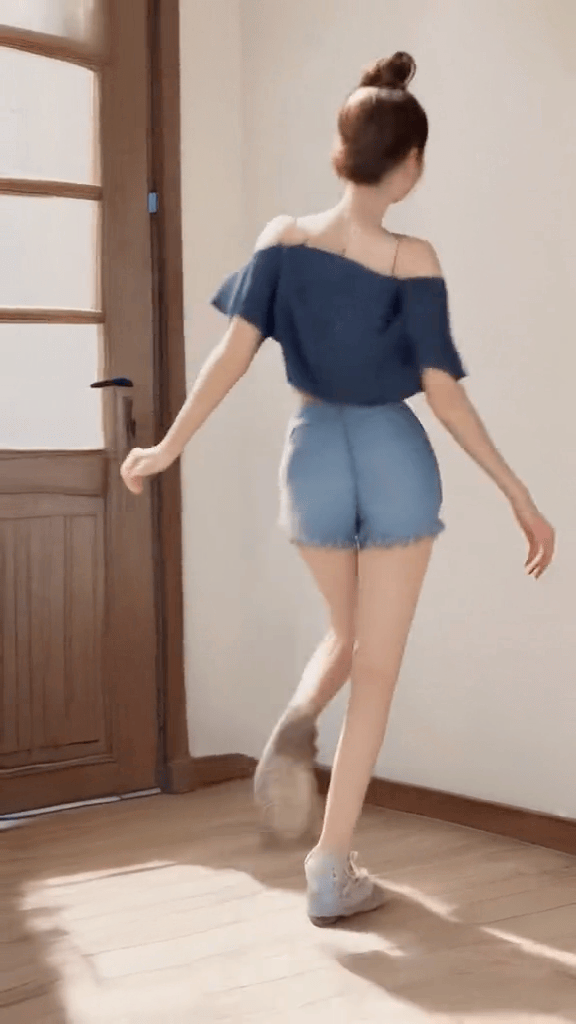
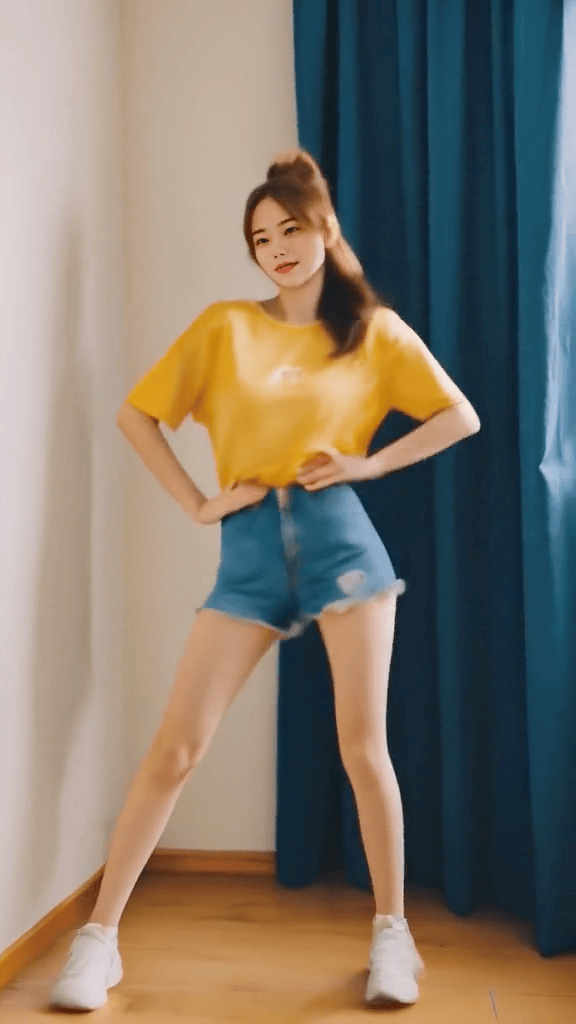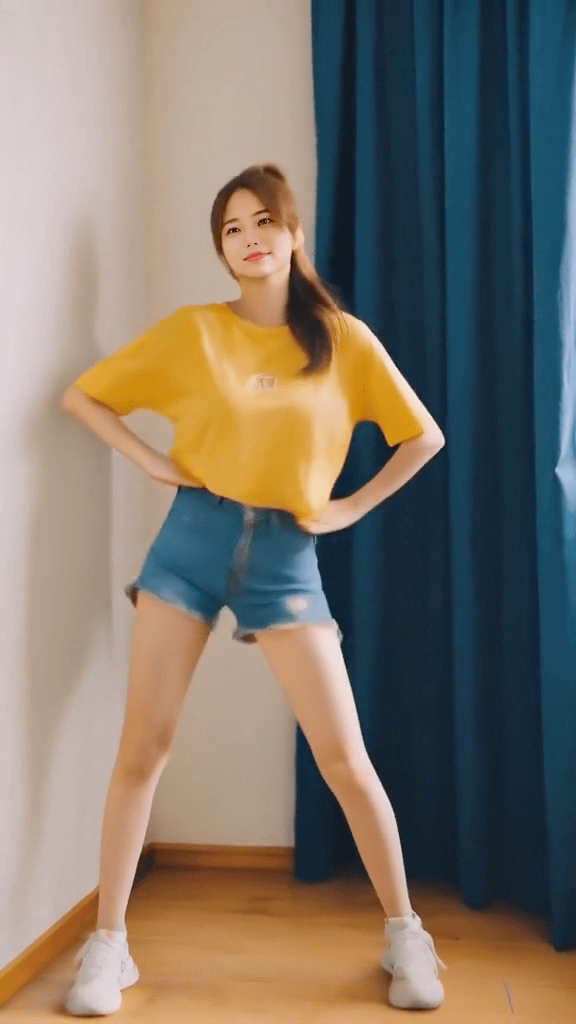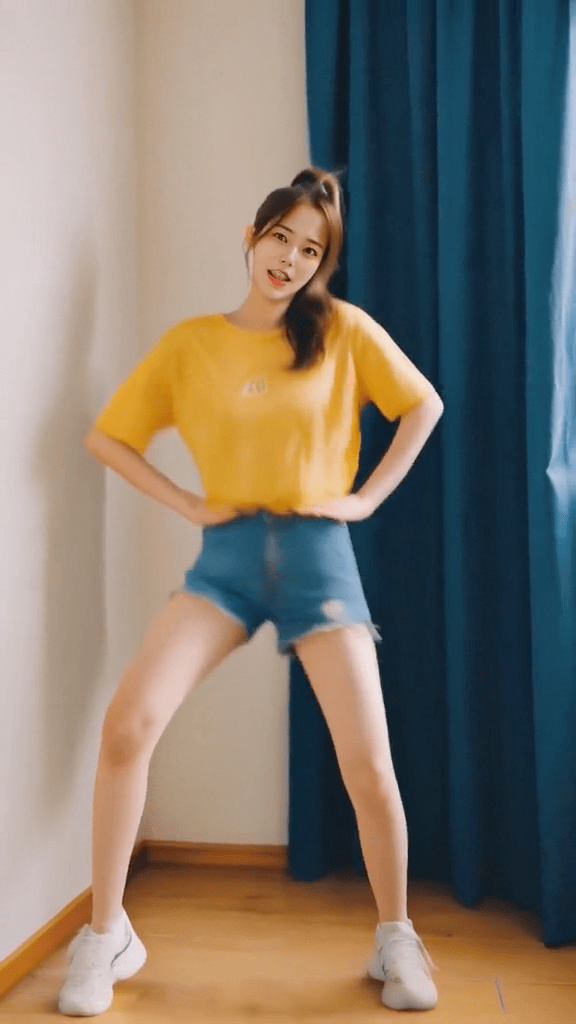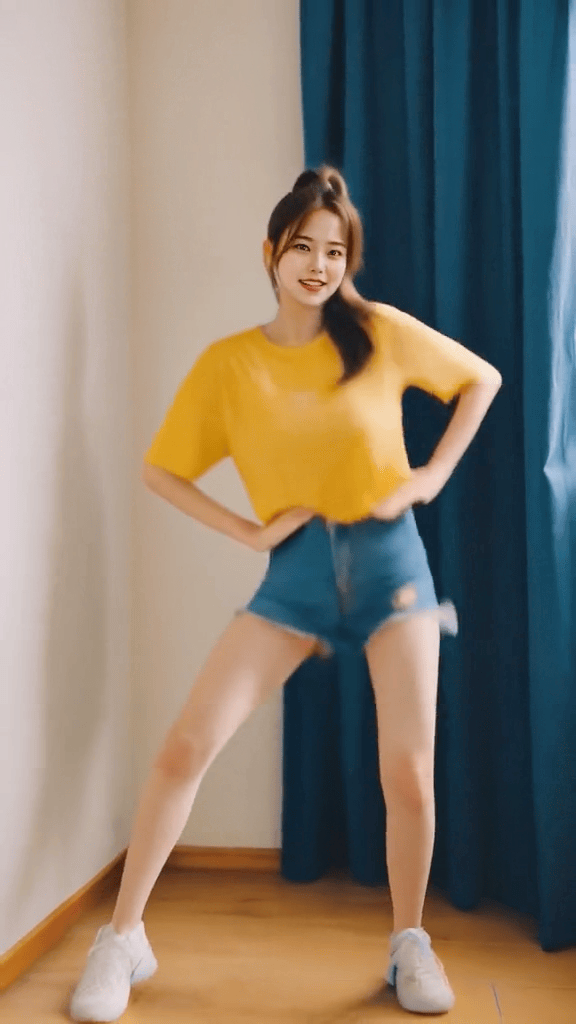
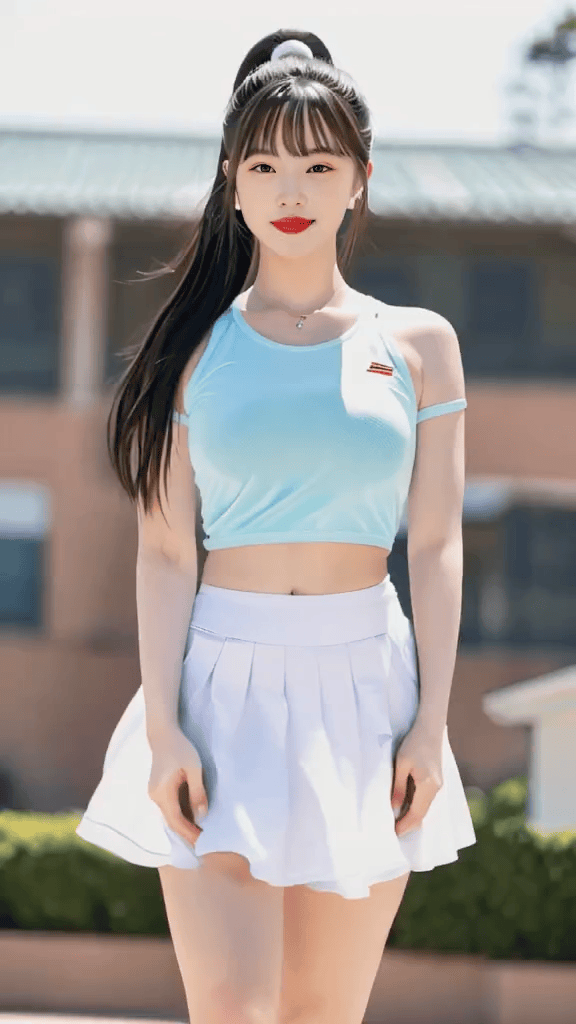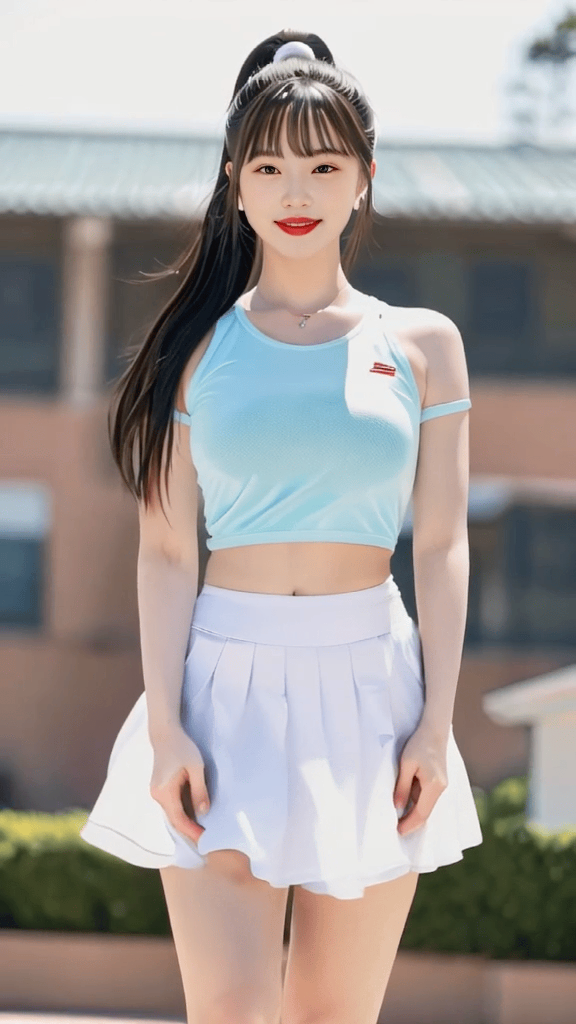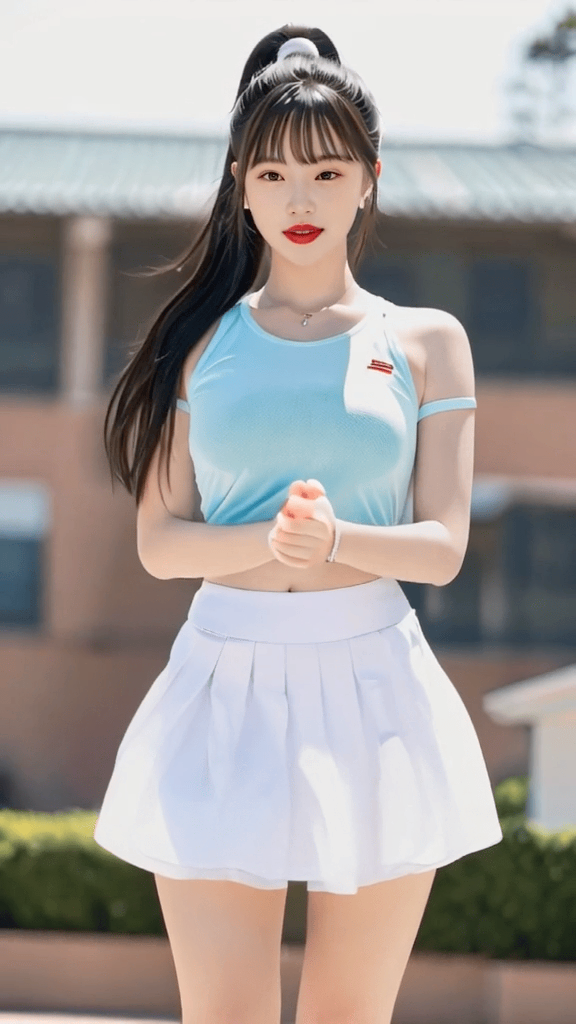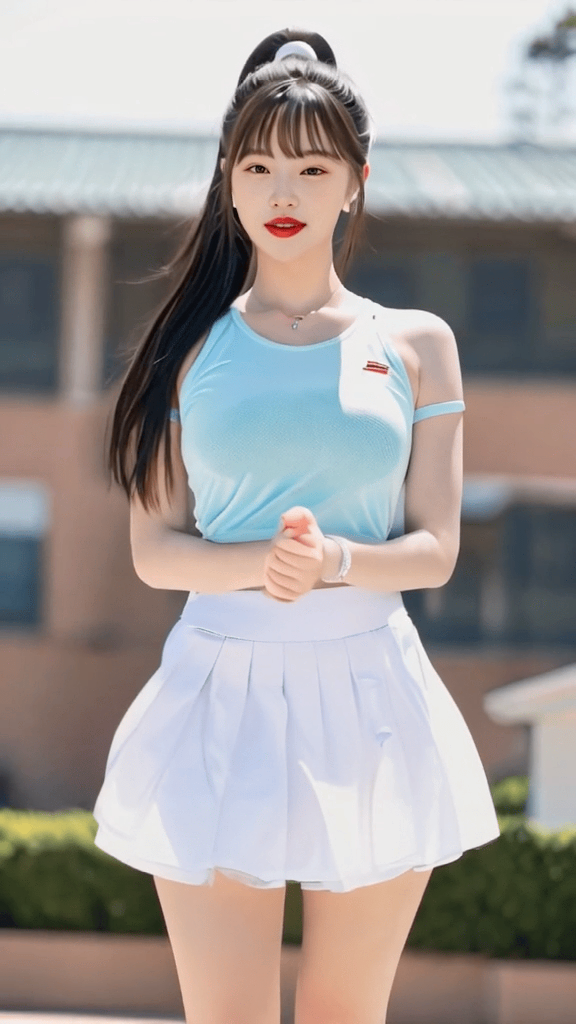
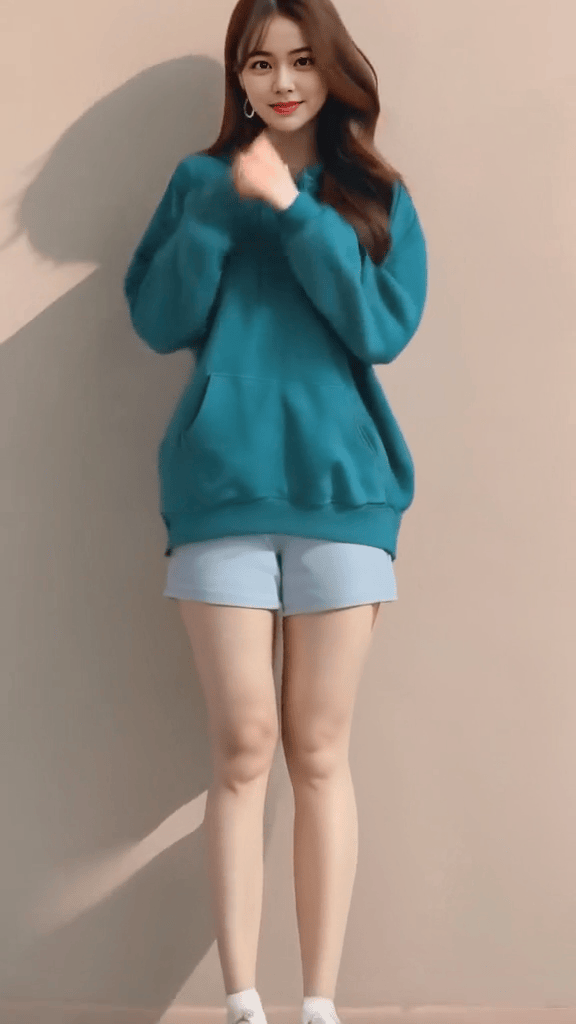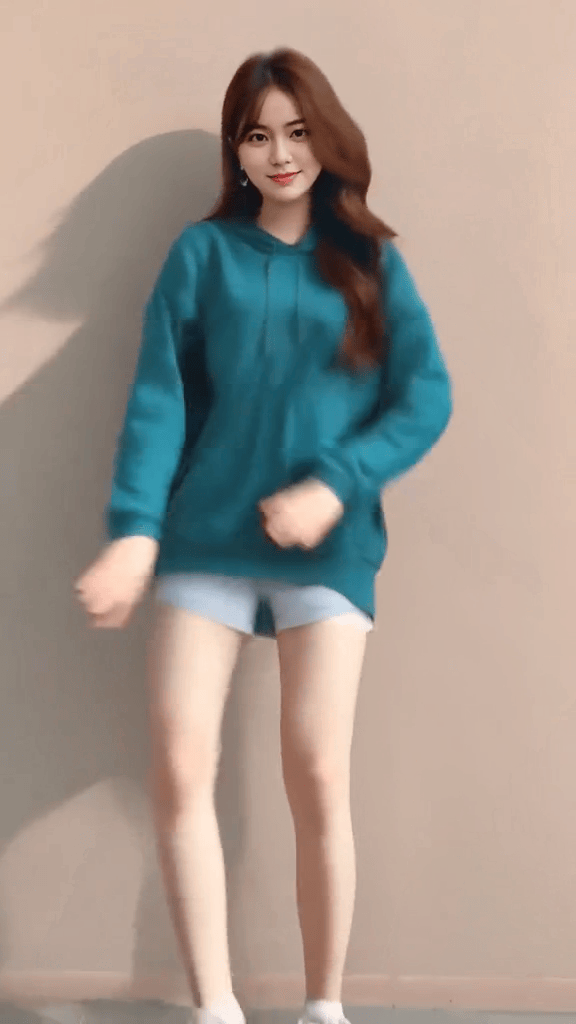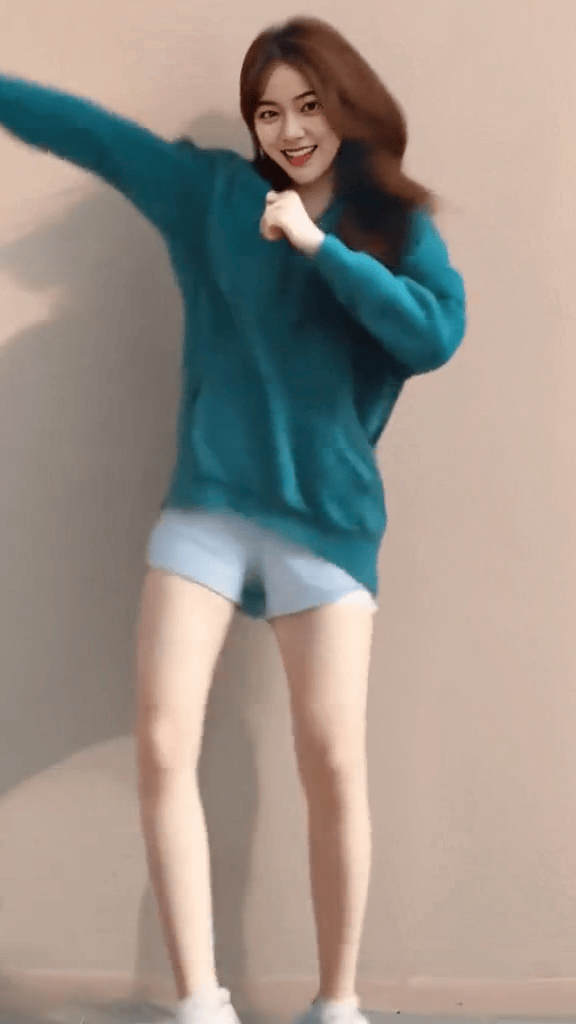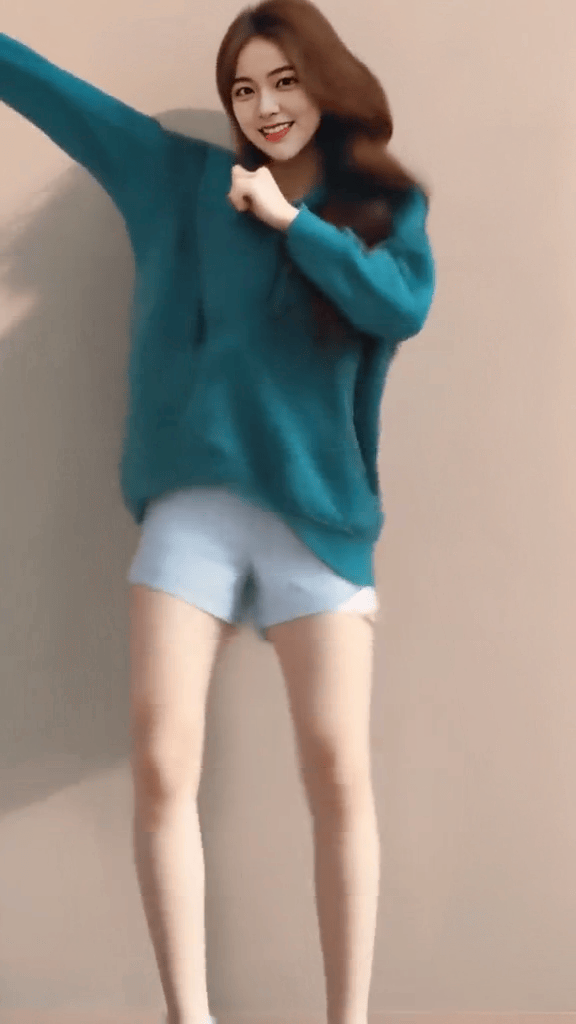
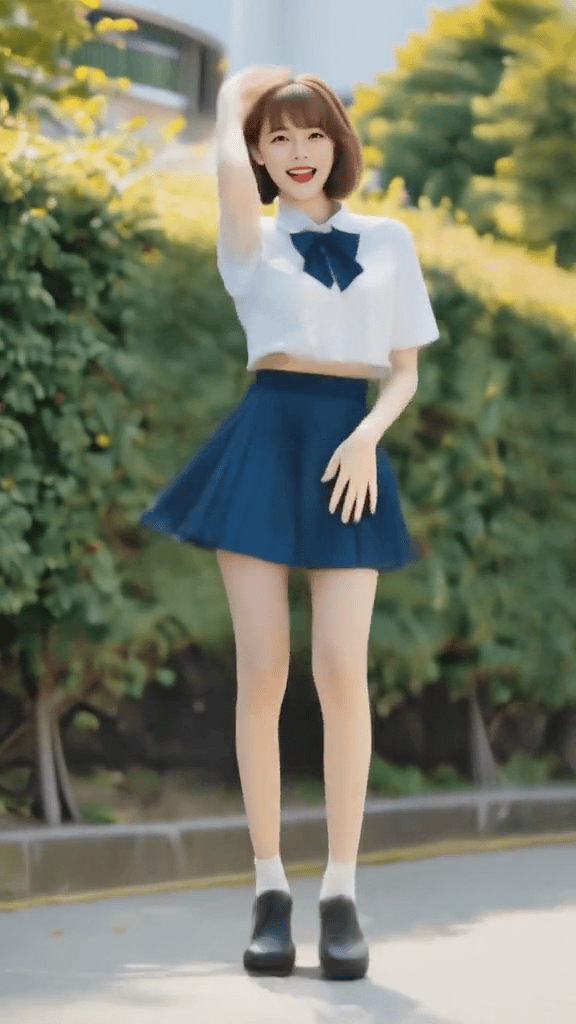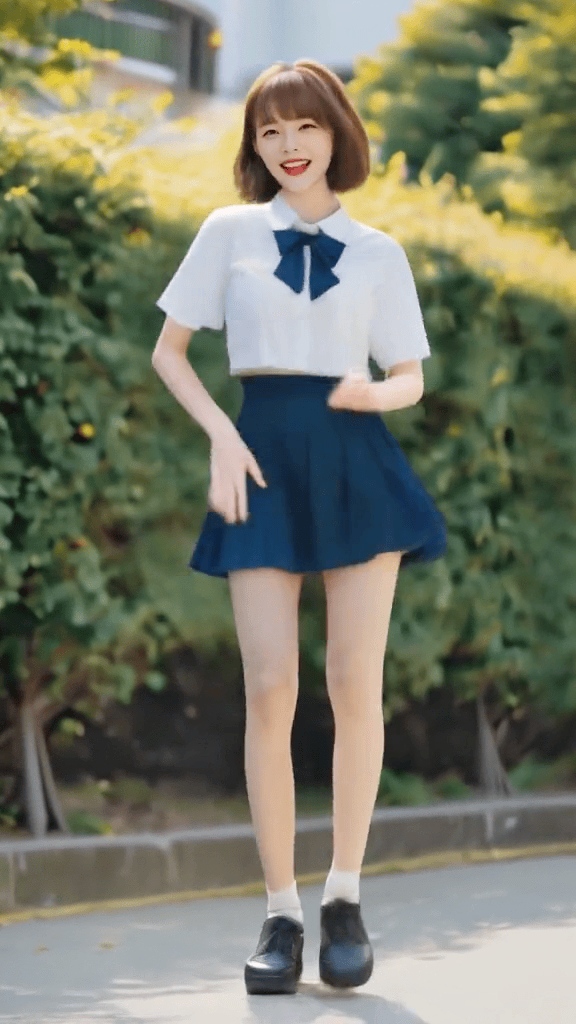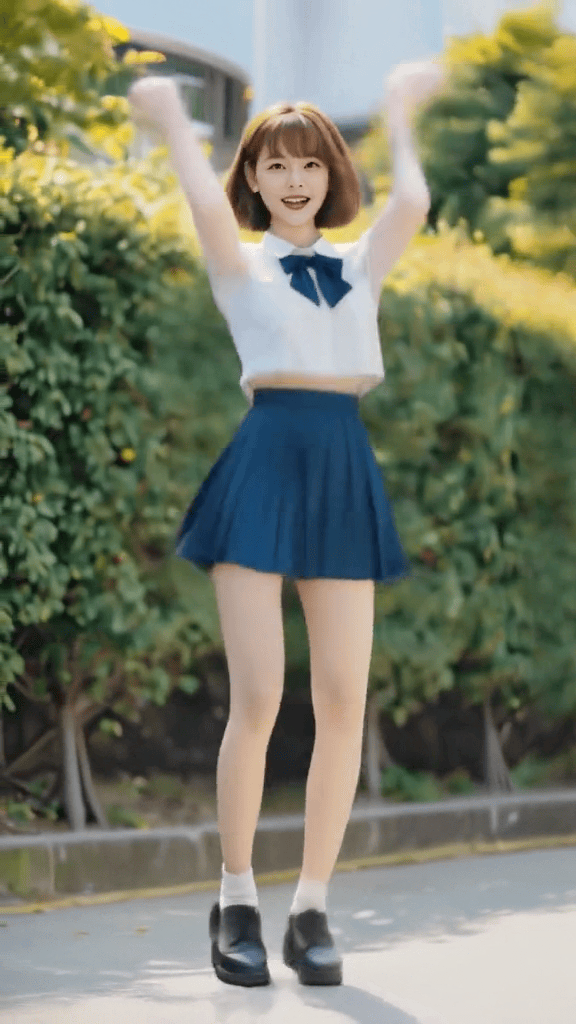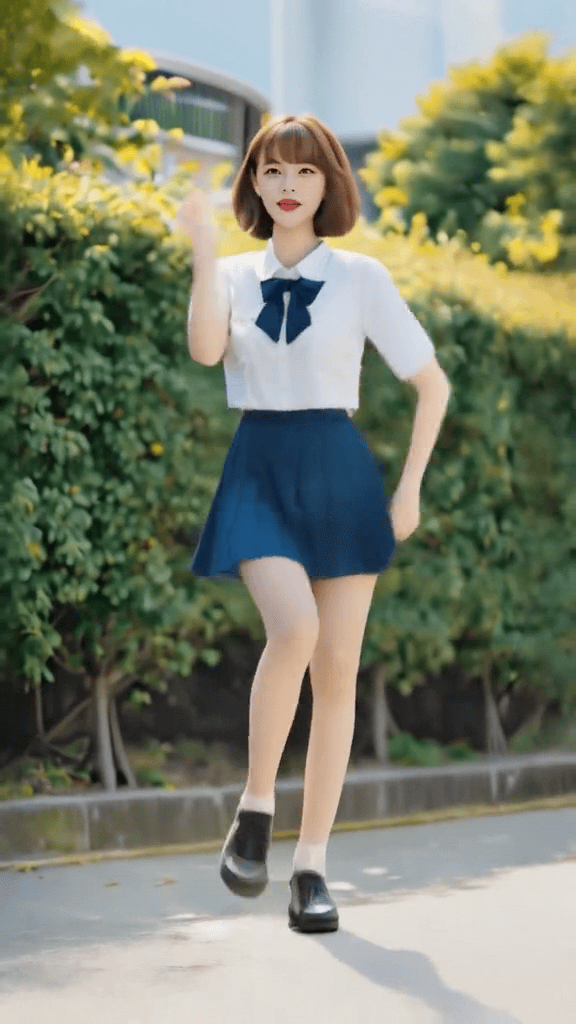
Highlights: rich details, good temporal smoothness, and long video length.
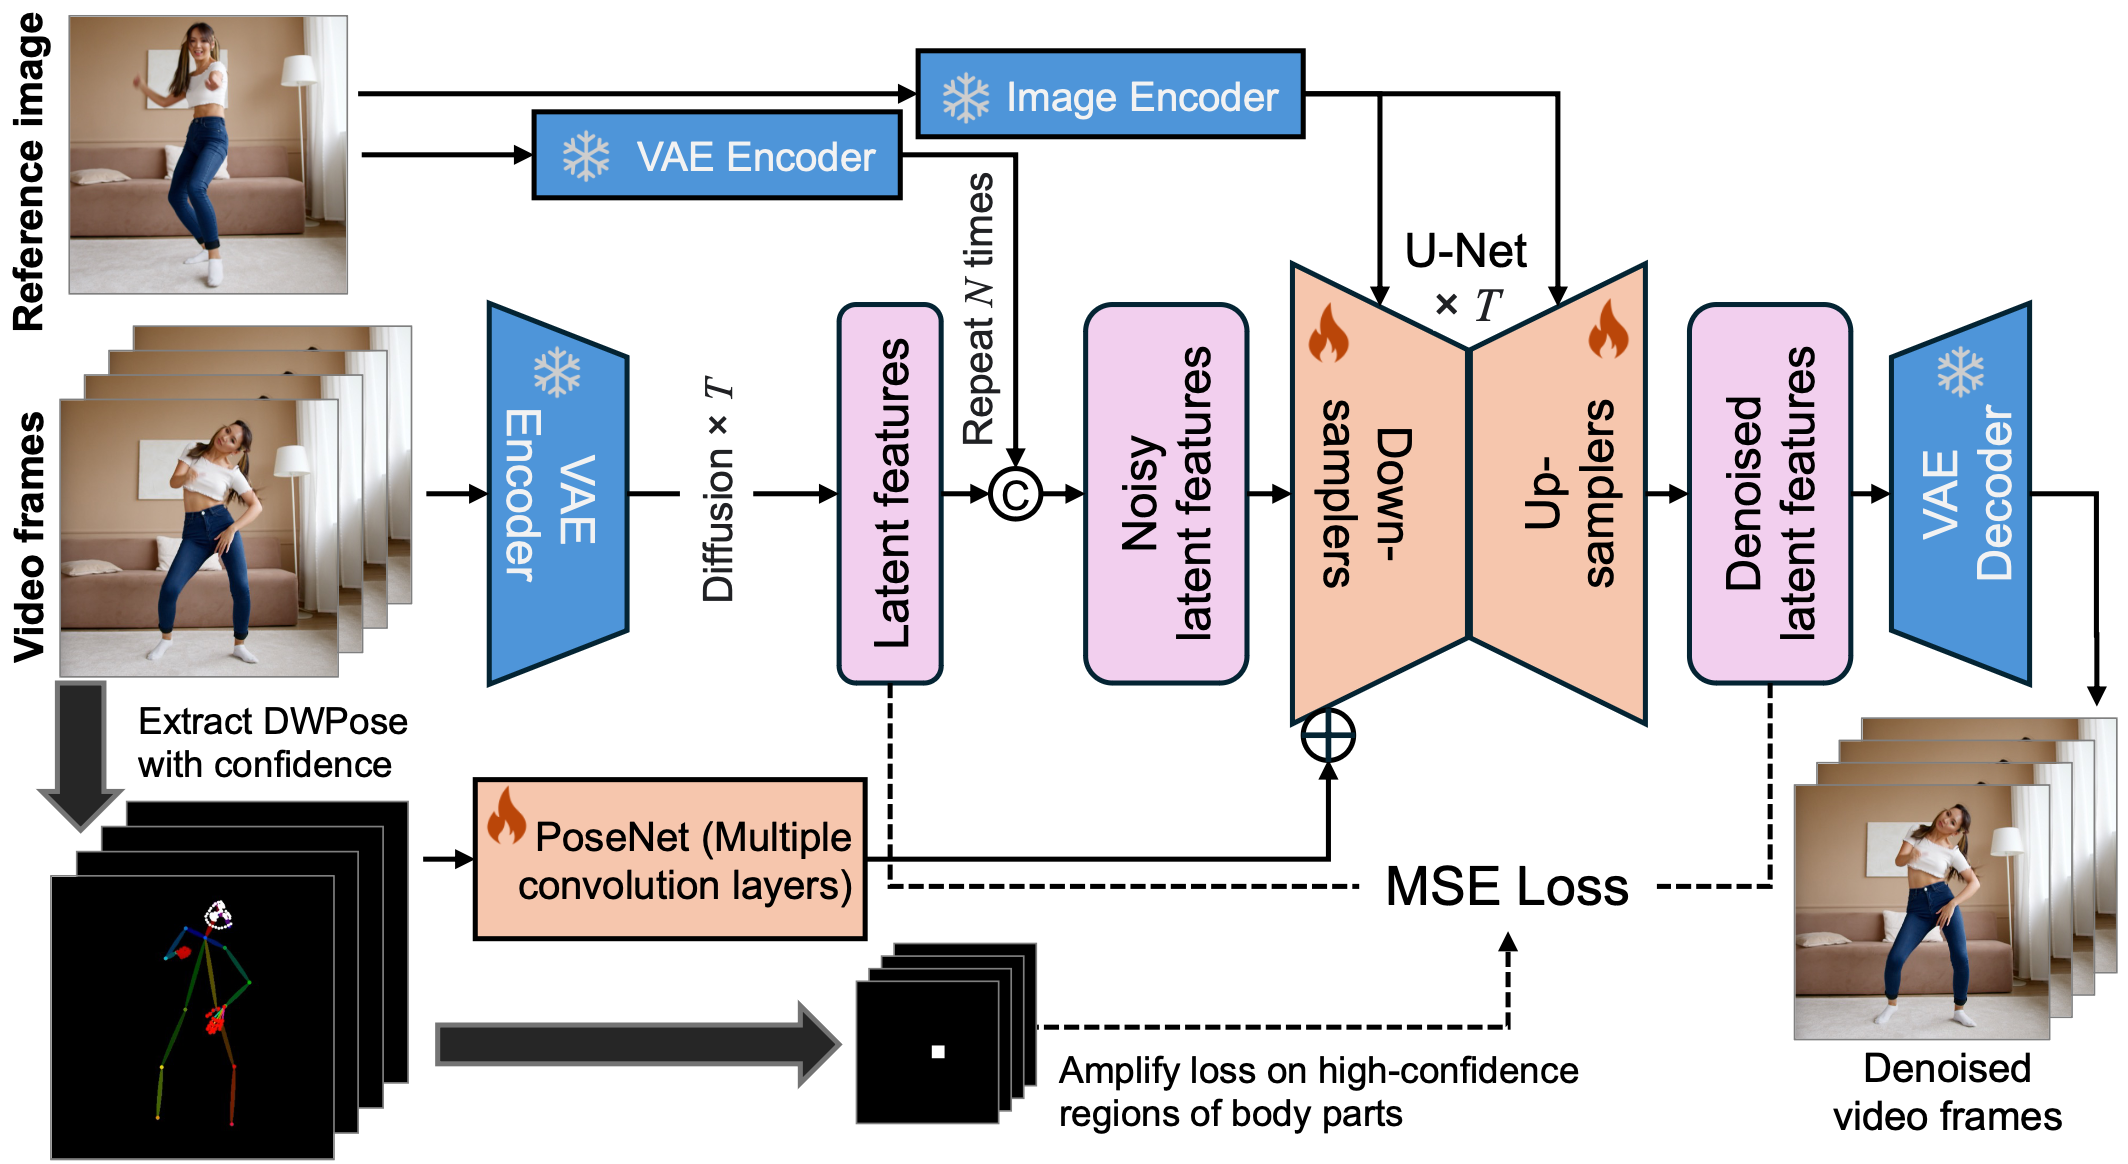 An overview of the framework of MimicMotion.
In recent years, generative artificial intelligence has achieved significant advancements in the field of image generation, spawning a variety of applications. However, video generation still faces considerable challenges in various aspects such as controllability, video length, and richness of details, which hinder the application and popularization of this technology. In this work, we propose a controllable video generation framework, dubbed MimicMotion, which can generate high-quality videos of arbitrary length with any motion guidance. Comparing with previous methods, our approach has several highlights. Firstly, with confidence-aware pose guidance, temporal smoothness can be achieved so model robustness can be enhanced with large-scale training data. Secondly, regional loss amplification based on pose confidence significantly eases the distortion of image significantly. Lastly, for generating long smooth videos, a progressive latent fusion strategy is proposed. By this means, videos of arbitrary length can be generated with acceptable resource consumption. With extensive experiments and user studies, MimicMotion demonstrates significant improvements over previous approaches in multiple aspects.
[2025-05-03]: 🎉 Our paper is accepted by ICML 2025. Congratulations and many thanks to the co-authors![2024-07-08]: 🔥 A superior model checkpoint has been released as version 1.1. The maximum number of video frames has now been expanded from 16 to 72, significantly enhancing the video quality![2024-07-01]: Project page, code, technical report and a basic model checkpoint are released. A better checkpoint supporting higher quality video generation will be released very soon. Stay tuned!For the initial released version of the model checkpoint, it supports generating videos with a maximum of 72 frames at a 576x1024 resolution. If you encounter insufficient memory issues, you can appropriately reduce the number of frames.
Recommend python 3+ with torch 2.x are validated with an Nvidia V100 GPU. Follow the command below to install all the dependencies of python:
conda env create -f environment.yaml
conda activate mimicmotion
export HF_ENDPOINT=https://hf-mirror.com.
Please download weights manually as follows:
cd MimicMotions/
mkdir models
    mkdir -p models/DWPose
    wget https://huggingface.co/yzd-v/DWPose/resolve/main/yolox_l.onnx?download=true -O models/DWPose/yolox_l.onnx
    wget https://huggingface.co/yzd-v/DWPose/resolve/main/dw-ll_ucoco_384.onnx?download=true -O models/DWPose/dw-ll_ucoco_384.onnx
wget -P models/ https://huggingface.co/tencent/MimicMotion/resolve/main/MimicMotion_1-1.pth
Finally, all the weights should be organized in models as follows
models/
├── DWPose
│   ├── dw-ll_ucoco_384.onnx
│   └── yolox_l.onnx
└── MimicMotion_1-1.pth
A sample configuration for testing is provided as test.yaml. You can also easily modify the various configurations according to your needs.
python inference.py --inference_config configs/test.yaml
Tips: if your GPU memory is limited, try set env PYTORCH_CUDA_ALLOC_CONF=max_split_size_mb:256.
For the 35s demo video, the 72-frame model requires 16GB VRAM (4060ti) and finishes in 20 minutes on a 4090 GPU.
The minimum VRAM requirement for the 16-frame U-Net model is 8GB; however, the VAE decoder demands 16GB. You have the option to run the VAE decoder on CPU.
@inproceedings{zhang2025mimicmotion,
  title={MimicMotion: High-Quality Human Motion Video Generation with Confidence-aware Pose Guidance},
  author={Yuang Zhang and Jiaxi Gu and Li-Wen Wang and Han Wang and Junqi Cheng and Yuefeng Zhu and Fangyuan Zou},
  booktitle={International Conference on Machine Learning},
  year={2025}
}
 →
 →
 →
 →
 →
 →
 →