NVlabs/Sana is an open-source project on GitHub, mainly written in Python. SANA: Efficient High-Resolution Image Synthesis with Linear Diffusion Transformer It currently holds 9,096 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).

Demo | 🎬 SANA-Video 2.0 Demo | 🤗 HuggingFace | ComfyUI | SGLang | Cosmos-RL



ICLR 2025 Oral | ICML 2025 | ICCV 2025 Highlight | ICLR 2026 Oral
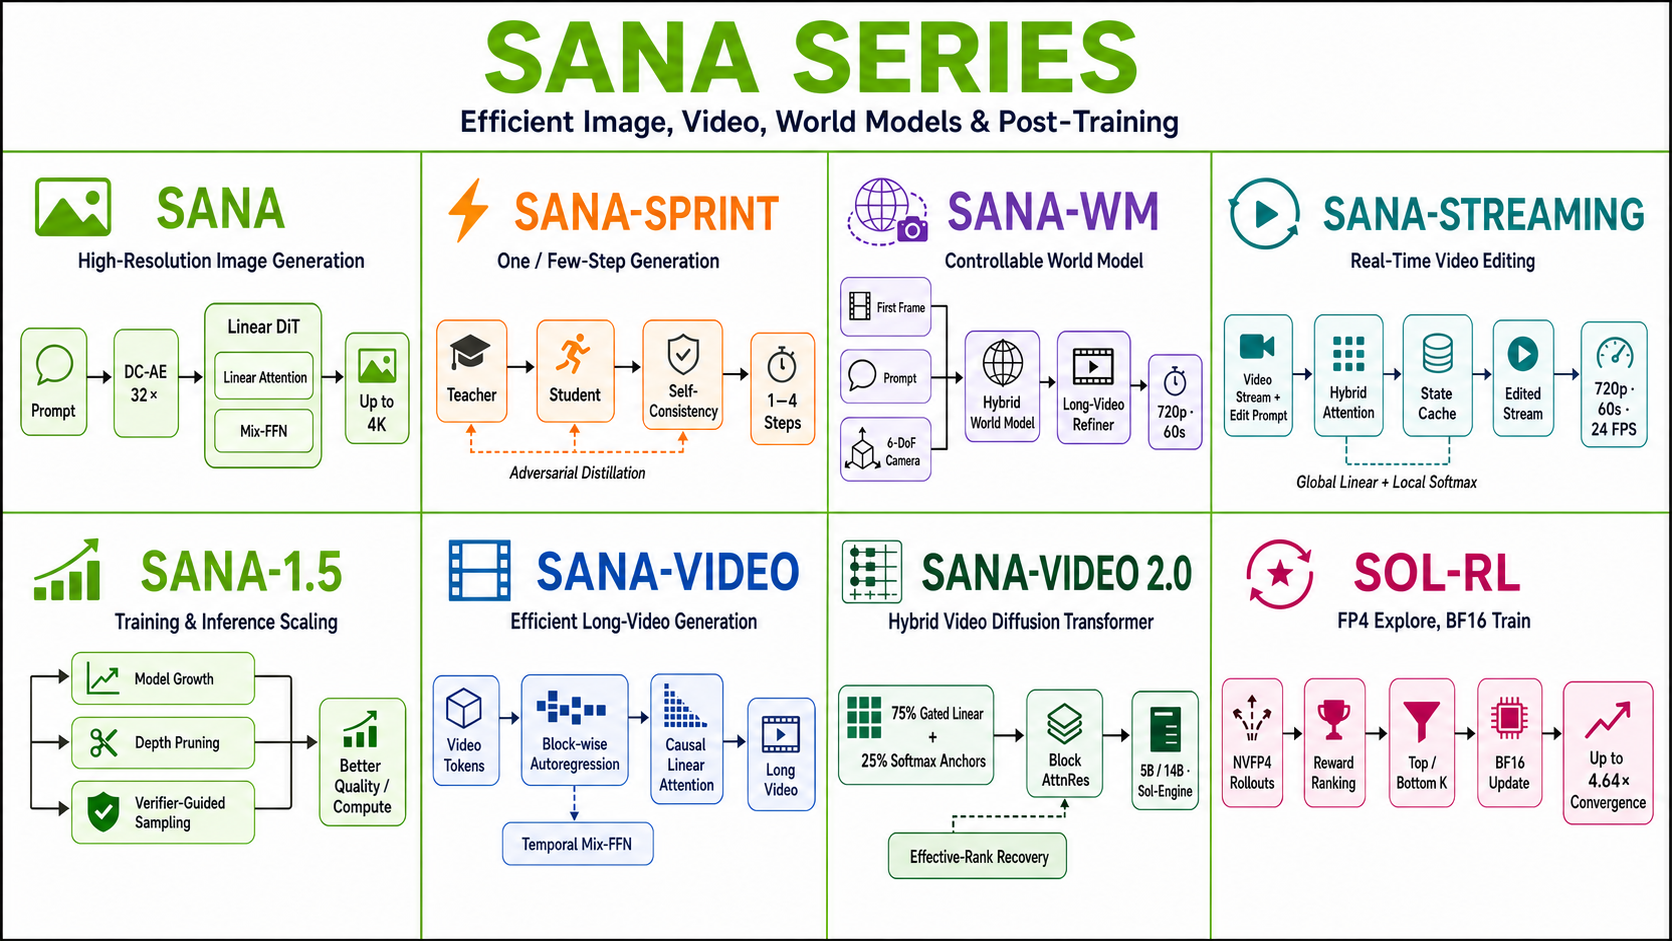
SANA is an efficiency-oriented codebase for high-resolution image and video generation, providing complete training and inference pipelines. This repository contains code for SANA, SANA-1.5, SANA-Sprint, SANA-Video, SANA-Video 2.0, SANA-WM, SANA-Streaming, and Sol-RL. More details can be found in our 📚 documentation.
Join our Discord to engage in discussions with the community! If you have any questions, run into issues, or are interested in contributing, don't hesitate to reach out!

News
- 🔥 [2026/09] ⚡ SANA-Video 2.0 5B 4-Step Preview is released! The DMD preview generates 720p videos in four denoising steps and supports 5-second and 8-second outputs. See Online Demo | 4-Step Weights | Doc | Project.
- 🔥 [2026/08] 🎬 SANA-Video 2.0 training, inference, model architecture, and 5B 720p checkpoint are released! The 8-second model supports both text-to-video and text-image-to-video generation, with hybrid linear/softmax attention and Attention Residuals. See Online Demo | Project | Doc | Model Zoo | Weights.
- 🔥 [2026/08] ⚡ Sol Engine: Day-One MiniMax-H3 Acceleration is available! The 33B omni-modal audio+video DiT runs 3.95× faster on GB200, reached in 4.5 hours of optimization, and up to 4.52× on hardware that sits on a desk — 3.92× on DGX Spark, 4.52× on GeForce RTX 5090 — with no distillation, no LoRA, and no calibration pass. See GB200 Blog | On-Device Blog.
- 🔥 [2026/07] 🌍 SANA-Streaming training is released! Includes bidirectional and distillation training. See Doc.
- 🔥 [2026/07] 🌍 SANA-WM Stage-1 training is released! Includes bidirectional, chunk-causal, and distillation training. See Doc.
- 🔥 [2026/06] 🎬 SANA-Streaming: 2B Model for Real-time Streaming Editing is released! Supports 720p, 1-min video editing. A pioneer work for streaming editing. See Project | Doc | Paper | Reactor Demo.
- 🔥 [2026/05] 🌍 SANA-WM: 2.6B Controllable World Model is released! Supports 720p, 1-min video generation with 6-DoF camera control. A new baseline for World Modeling and Embodied AI. See Project | Doc | Paper | Reactor Demo.
- 🔥 [2026/04] ⚡ Sol-RL: NVFP4 Rollout, BF16 Training RL is available! All training recipes for SANA, FLUX.1, and SD3.5-L, together with bundled post-training datasets, are released. See Sol-RL doc | Page | Paper.
- 🔥 [2026/03] 📺 SANA-Video 720p model with LTX-VAE is released. Use it with LTX2 Refiner to upscale the videos to 2K resolution! See Model Zoo, SANA-Video doc and Blog about refiner.
- 🔥 [2026/03] 💪 Post Training Infra: SANA × Cosmos-RL — We partner with Cosmos-RL to provide a complete RL infrastructure for SANA. You can now post-train (SFT/RL) SANA-Image and SANA-Video with state-of-the-art algorithms (e.g. Diffusion-NFT, Flow-GRPO), preset configs, reward services, and flexible datasets. See SANA on Cosmos-RL and our Cosmos-RL integration doc.
- 🔥 [2026/02] 🚀 SANA is now supported in SGLang! High-performance serving with OpenAI-compatible API. [[Guidance]](https://nvlabs.github.io/Sana/docs/sglang/)
- 🔥 [2026/01/26] SANA-Video is accepted as Oral by ICLR-2026. 🎉🎉🎉
- 🔥 [2025/12/09] 🎬 LongSANA: 27FPS real-time minute-length video generation model, training and inference code are all released. Thanks to LongLive Team. Refer to: [[Train]](https://nvlabs.github.io/Sana/docs/longsana/#how-to-train) | [[Test]](https://nvlabs.github.io/Sana/docs/longsana/#how-to-inference) | [[Weight]](https://nvlabs.github.io/Sana/docs/model_zoo/#sana-video)
- 🔥 [2025/11/24] 🪶 Blog: how Causal Linear Attention unlocks infinite context for LLMs and long video generation.
- 🔥 [2025/11/9] 🎬 Introduction video shows how Block Causal Linear Attention and Causal Mix-FFN work?
- 🔥 [2025/11/6] 📺SANA-Video is merged into diffusers. How to use.
- 🔥 [2025/10/27] 📺SANA-Video is released. [[README]](https://nvlabs.github.io/Sana/docs/sana_video/) | [[Weights]](https://nvlabs.github.io/Sana/docs/model_zoo/#sana-video) support Text-to-Video, TextImage-to-Video.
- 🔥 [2025/10/13] 📺SANA-Video is coming, 1). a 5s Linear DiT Video model, and 2). real-time minute-length video generation (with LongLive). [[paper]](https://www.arxiv.org/pdf/2509.24695) | [[Page]](https://nvlabs.github.io/Sana/Video/)
Click to show all updates
- ✅ [2025/8/20] We release a new DC-AE-Lite for faster inference and smaller memory. [[How to config]](https://github.com/NVlabs/Sana/blob/main/configs/sana_sprint_config/1024ms/SanaSprint_1600M_1024px_allqknorm_bf16_scm_ladd_dc_ae_lite.yaml#L52) | [[diffusers PR]](https://github.com/huggingface/diffusers/pull/12169) | [[Weight]](https://huggingface.co/mit-han-lab/dc-ae-lite-f32c32-sana-1.1-diffusers)
- ✅ [2025/6/25] SANA-Sprint was accepted to ICCV'25 🏖️
- ✅ [2025/6/4] SANA-Sprint ComfyUI Node is released [[Example]](docs/ComfyUI/SANA-Sprint.json).
- ✅ [2025/5/8] SANA-Sprint (One-step diffusion) diffusers training code is released [[Guidance]](https://github.com/huggingface/diffusers/blob/main/examples/research_projects/sana/README.md).
- ✅ [2025/5/4] SANA-1.5 (Inference-time scaling) is accepted by ICML-2025. 🎉🎉🎉
- ✅ [2025/3/22] 🔥SANA-Sprint demo is hosted on Huggingface, try it! 🎉 [[Demo Link]](https://huggingface.co/spaces/Efficient-Large-Model/SanaSprint)
- ✅ [2025/3/22] 🔥SANA-1.5 is supported in ComfyUI! 🎉: ComfyUI Guidance | ComfyUI Work Flow SANA-1.5 4.8B
- ✅ [2025/3/22] 🔥SANA-Sprint code & weights are released! 🎉 Include: Training & Inference code and Weights / HF are all released. [[Guidance]](https://nvlabs.github.io/Sana/docs/sana_sprint/)
- ✅ [2025/3/21] 🚀Sana + Inference Scaling is released. [[Guidance]](https://nvlabs.github.io/Sana/docs/inference_scaling/)
- ✅ [2025/3/16] 🔥SANA-1.5 code & weights are released! 🎉 Include: DDP/FSDP | TAR file WebDataset | Multi-Scale Training code and Weights | HF are all released.
- ✅ [2025/3/14] 🏃SANA-Sprint is coming out! 🎉 A new one/few-step generator of Sana. 0.1s per 1024px image on H100, 0.3s on RTX 4090. Find out more details: [[Page]](https://nvlabs.github.io/Sana/Sprint/) | [[Arxiv]](https://arxiv.org/abs/2503.09641). Code is coming very soon along with
diffusers
- ✅ [2025/2/10] 🚀Sana + ControlNet is released. [[Guidance]](https://nvlabs.github.io/Sana/docs/sana_controlnet/) | [[Model]](https://nvlabs.github.io/Sana/docs/model_zoo/#sana) | [[Demo]](https://nv-sana.mit.edu/ctrlnet/)
- ✅ [2025/1/30] Release CAME-8bit optimizer code. Saving more GPU memory during training. [[How to config]](https://github.com/NVlabs/Sana/blob/main/configs/sana_config/1024ms/Sana_1600M_img1024_CAME8bit.yaml#L86)
- ✅ [2025/1/29] 🎉 🎉 🎉SANA 1.5 is out! Figure out how to do efficient training & inference scaling! 🚀[[Tech Report]](https://arxiv.org/abs/2501.18427)
- ✅ [2025/1/24] 4bit-Sana is released, powered by SVDQuant and Nunchaku inference engine. Now run your Sana within 8GB GPU VRAM [[Guidance]](https://nvlabs.github.io/Sana/docs/4bit_sana/) [[Demo]](https://svdquant.mit.edu/) [[Model]](https://nvlabs.github.io/Sana/docs/model_zoo/#sana)
- ✅ [2025/1/24] DCAE-1.1 is released, better reconstruction quality. [[Model]](https://huggingface.co/mit-han-lab/dc-ae-f32c32-sana-1.1) [[diffusers]](https://huggingface.co/mit-han-lab/dc-ae-f32c32-sana-1.1-diffusers)
- ✅ [2025/1/23] Sana is accepted as Oral by ICLR-2025. 🎉🎉🎉
- ✅ [2025/1/12] DC-AE tiling makes Sana-4K inferences 4096x4096px images within 22GB GPU memory. With model offload and 8bit/4bit quantize. The 4K Sana run within 8GB GPU VRAM. [[Guidance]](https://nvlabs.github.io/Sana/docs/model_zoo/#3-2k-4k-models)
- ✅ [2025/1/11] Sana code-base license changed to Apache 2.0.
- ✅ [2025/1/10] Inference Sana with 8bit quantization.[[Guidance]](https://nvlabs.github.io/Sana/docs/8bit_sana/#quantization)
- ✅ [2025/1/8] 4K resolution Sana models is supported in Sana-ComfyUI and work flow is also prepared. [[4K guidance]](https://nvlabs.github.io/Sana/docs/ComfyUI/comfyui/#a-sample-workflow-for-sana-4096x4096-image-18gb-gpu-is-needed)
- ✅ [2025/1/8] 1.6B 4K resolution Sana models are released: [[BF16 pth]](https://huggingface.co/Efficient-Large-Model/Sana_1600M_4Kpx_BF16) or [[BF16 diffusers]](https://huggingface.co/Efficient-Large-Model/Sana_1600M_4Kpx_BF16_diffusers). 🚀 Get your 4096x4096 resolution images within 20 seconds! Find more samples in Sana page. Thanks SUPIR for their wonderful work and support.
- ✅ [2025/1/2] Bug in the
diffusers pipeline is solved. Solved PR
- ✅ [2025/1/2] 2K resolution Sana models is supported in Sana-ComfyUI and work flow is also prepared.
- ✅ [2024/12] 1.6B 2K resolution Sana models are released: [[BF16 pth]](https://huggingface.co/Efficient-Large-Model/Sana_1600M_2Kpx_BF16) or [[BF16 diffusers]](https://huggingface.co/Efficient-Large-Model/Sana_1600M_2Kpx_BF16_diffusers). 🚀 Get your 2K resolution images within 4 seconds! Find more samples in Sana page. Thanks SUPIR for their wonderful work and support.
- ✅ [2024/12]
diffusers supports Sana-LoRA fine-tuning! Sana-LoRA's training and convergence speed is super fast. [[Guidance]](https://nvlabs.github.io/Sana/docs/sana_lora_dreambooth/) or [[diffusers docs]](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/README_sana.md).
- ✅ [2024/12]
diffusers has Sana! All Sana models in diffusers safetensors are released and diffusers pipeline SanaPipeline, SanaPAGPipeline, DPMSolverMultistepScheduler(with FlowMatching) are all supported now. We prepare a Model Card for you to choose.
- ✅ [2024/12] 1.6B BF16 Sana model is released for stable fine-tuning.
- ✅ [2024/12] We release the ComfyUI node for Sana. [[Guidance]](https://nvlabs.github.io/Sana/docs/ComfyUI/comfyui/)
- ✅ [2024/11] All multi-linguistic (Emoji & Chinese & English) SFT models are released: 1.6B-512px, 1.6B-1024px, 600M-512px, 600M-1024px. The metric performance is shown here
- ✅ [2024/11] Sana Replicate API is launching at Sana-API.
- ✅ [2024/11] 1.6B Sana models are released.
- ✅ [2024/11] Training & Inference & Metrics code are released.
- ✅ [2024/11] Working on
diffusers.
- [2024/10] Demo is released.
- [2024/10] DC-AE Code and weights are released!
- [2024/10] Paper is on Arxiv!
💡 Introduction
We introduce SANA, a series of efficient diffusion models for high-resolution image and video generation:
- SANA: Text-to-image generation up to 4K resolution, 20× smaller and 100× faster than Flux-12B.
- SANA-1.5: Efficient training-time and inference-time compute scaling for better quality.
- SANA-Sprint: One/few-step generation via sCM distillation, 0.1s per 1024px image on H100.
- SANA-Video/LongSANA: Efficient video generation with Block Linear Attention / with LongLive.
- SANA-Video 2.0: 5B and 14B text-to-video/text-image-to-video architectures with hybrid linear/softmax attention and Attention Residuals. Try the 5B 720p 4-step preview, or download the 50-step and 4-step preview checkpoints; the 14B config and checkpoint are not included yet.
- Sol-RL: NVFP4 Rollout, BF16 Training RL achieves 4.64× faster convergence.
- SANA-WM: 2.6B parameter controllable world model, generating 720p, 1-minute video worlds with 6-DoF camera control.
- SANA-Streaming: 2B real-time streaming video-to-video editing for 720p, minute-scale videos.
Key Techniques:
- Linear Attention: Replace vanilla attention in DiT with linear attention for efficiency at high resolutions.
- DC-AE: 32× image compression (vs. traditional 8×) to reduce latent tokens.
- Decoder-only Text Encoder: Modern decoder-only LLM with in-context learning for better text-image alignment.
- Block Causal Linear Attention & Causal Mix-FFN: Efficient attention and feedforward for long video generation.
- Hybrid Attention & Attention Residuals: Combine gated linear attention with periodic softmax anchors and shared depth-wise residual aggregation.
- Flow-DPM-Solver: Reduce sampling steps with efficient training and sampling.
- sCM Distillation: One/few-step generation with continuous-time consistency distillation.
- Sol-RL: Low precision(NVFP4) rollout selection, high precesion(BF16) optimization for faster RL training.
- Controllable World Modeling: Efficient long-context modeling and camera trajectory control for consistent world generation.
- Streaming Video Editing: Real-time long-form video-to-video editing with stable temporal consistency.
In summary, SANA is a fully open-source framework integrating
efficient training, fast inference, and flexible deployment for both image and video generation. Deployable on laptop GPUs with
< 8GB VRAM via 4-bit quantization.
Quick Start
git clone https://github.com/NVlabs/Sana.git
cd Sana && ./environment_setup.sh sana
SANA-Video 2.0 5B release demo
This sample was generated from the public 5B checkpoint with seed 4. The result
contains 193 frames at 24 FPS in a 1280 × 736 bucket (8.04 seconds).
Try your own prompt in the SANA-Video 2.0 5B 720p 4-step preview, or reproduce the original 50-step sample below with its exact release command.

▶ Watch or download the generated video
Prompt: In a cozy, vintage room adorned with floral wallpaper, a cartoon
rooster sits comfortably in a floral-patterned armchair, sipping from a bottle
of beer. The rooster, with its vibrant red comb and wattle, displays a range of
expressions—smiling, nodding, and opening its beak wide in a cheerful manner.
The setting includes wooden furniture and another beer bottle on the table,
adding to the relaxed atmosphere. The camera captures the rooster from a
close-up angle, emphasizing its animated movements and lively demeanor.
Run the exact release command used for the video above:
bash inference_video_scripts/inference_sana_video.sh \
  --np 1 \
  --config configs/sana_video2/SanaVideo2_5B_720p.yaml \
  --model_path hf://Efficient-Large-Model/SANA-Video_2.0_5B_720p/checkpoints/SANA_Video_2.0_5B_720p.pth \
  --txt_file=asset/samples/sana_video2_5b_720p_demo.txt \
  --cfg_scale 8 \
  --flow_shift 12 \
  --step 50 \
  --fps 24 \
  --motion_score 20 \
  --seed 4 \
  --work_dir output/sana_video2_t2v_720p_demo
The online preview supports 5-second (81 frames at 16 FPS) and 8-second
(193 frames at 24 FPS) out
 →

 →
 →
 →
 →
 →
 →
 →