MoonInTheRiver/DiffSinger is an open-source project on GitHub, mainly written in Python. DiffSinger: Singing Voice Synthesis via Shallow Diffusion Mechanism (SVS & TTS); AAAI 2022; Official code It currently holds 4,876 stars and 833 forks with 53 open issues, and was last pushed on 2026-07-24 (repository created 2021-12-17).
DiffSinger: Singing Voice Synthesis via Shallow Diffusion Mechanism

This repository is the official PyTorch implementation of our AAAI-2022 paper, in which we propose DiffSinger (for Singing-Voice-Synthesis) and DiffSpeech (for Text-to-Speech).
:tada: :tada: :tada: Updates:
- Sep.11, 2022: :electric_plug: DiffSinger-PN. Add plug-in PNDM, ICLR 2022 in our laboratory, to accelerate DiffSinger freely.
- Jul.27, 2022: Update documents for SVS. Add easy inference A & B; Add Interactive SVS running on HuggingFace🤗 SVS.
- Mar.2, 2022: MIDI-B-version.
- Mar.1, 2022: NeuralSVB, for singing voice beautifying, has been released.
- Feb.13, 2022: NATSpeech, the improved code framework, which contains the implementations of DiffSpeech and our NeurIPS-2021 work PortaSpeech has been released.
- Jan.29, 2022: support MIDI-A-version SVS.
- Jan.13, 2022: support SVS, release PopCS dataset.
- Dec.19, 2021: support TTS. HuggingFace🤗 TTS
:rocket:
News:
- Feb.24, 2022: Our new work, NeuralSVB was accepted by ACL-2022 . Demo Page.
- Dec.01, 2021: DiffSinger was accepted by AAAI-2022.
- Sep.29, 2021: Our recent work
PortaSpeech: Portable and High-Quality Generative Text-to-Speech was accepted by NeurIPS-2021 .
- May.06, 2021: We submitted DiffSinger to Arxiv .
Environments
1. If you want to use env of anaconda:
    conda create -n your_env_name python=3.8
    source activate your_env_name
    pip install -r requirements_2080.txt   (GPU 2080Ti, CUDA 10.2)
    or pip install -r requirements_3090.txt   (GPU 3090, CUDA 11.4)
2. Or, if you want to use virtual env of python:
    ## Install Python 3.8 first.
    python -m venv venv
    source venv/bin/activate
    # install requirements.
    pip install -U pip
    pip install Cython numpy==1.19.1
    pip install torch==1.9.0
    pip install -r requirements.txt
Documents
Overview
| Mel Pipeline | Dataset | Pitch Input | F0 Prediction | Acceleration Method | Vocoder |
| ------------------------------------------------------------------------------------------- | ---------------------------------------------------------| ----------------- | ------------- | --------------------------- | ----------------------------- |
|
DiffSpeech (Text->F0, Text+F0->Mel, Mel->Wav) |
Ljspeech | None | Explicit | Shallow Diffusion | HiFiGAN |
|
DiffSinger (Lyric+F0->Mel, Mel->Wav) |
PopCS | Ground-Truth F0 | None | Shallow Diffusion | NSF-HiFiGAN |
|
DiffSinger (Lyric+MIDI->F0, Lyric+F0->Mel, Mel->Wav) |
OpenCpop | MIDI | Explicit | Shallow Diffusion | NSF-HiFiGAN |
|
FFT-Singer (Lyric+MIDI->F0, Lyric+F0->Mel, Mel->Wav) |
OpenCpop | MIDI | Explicit | Invalid | NSF-HiFiGAN |
|
DiffSinger (Lyric+MIDI->Mel, Mel->Wav) |
OpenCpop | MIDI | Implicit | None | Pitch-Extractor + NSF-HiFiGAN |
|
DiffSinger+PNDM (Lyric+MIDI->Mel, Mel->Wav) |
OpenCpop | MIDI | Implicit | PLMS | Pitch-Extractor + NSF-HiFiGAN |
|
DiffSpeech+PNDM (Text->Mel, Mel->Wav) |
Ljspeech | None | Implicit | PLMS | HiFiGAN |
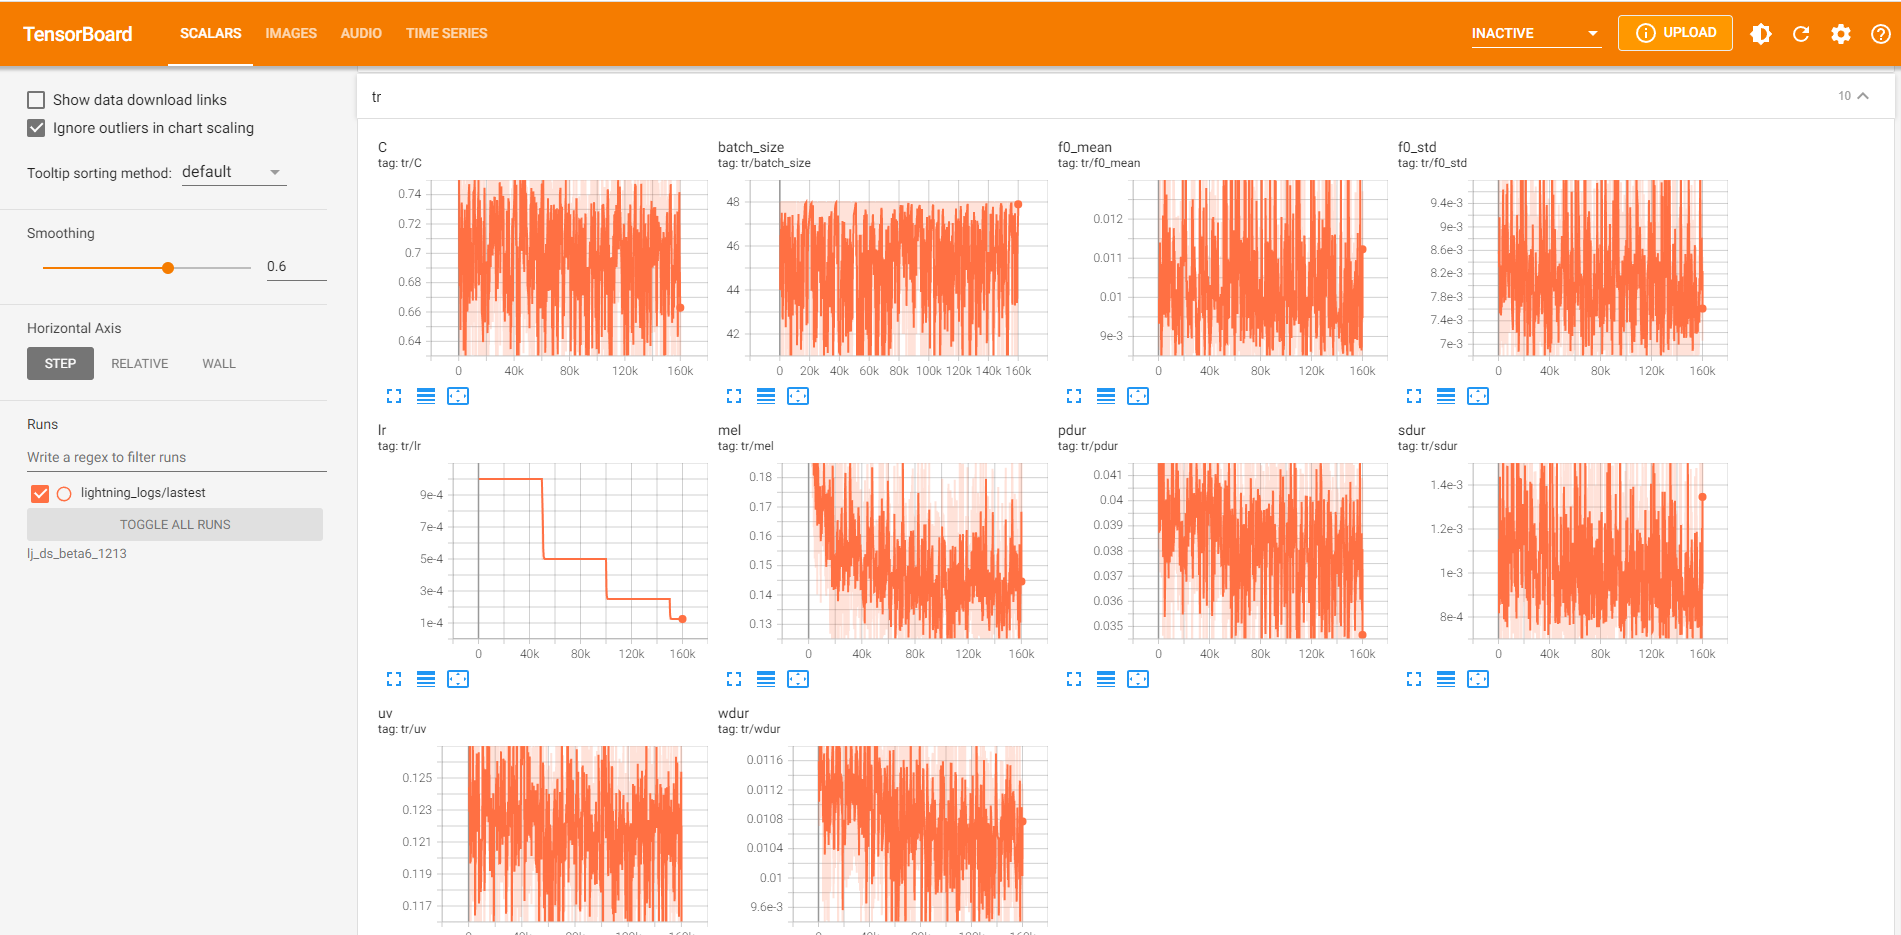
Tensorboard
tensorboard --logdir_spec exp_name
Citation
@article{liu2021diffsinger,
title={Diffsinger: Singing voice synthesis via shallow diffusion mechanism},
author={Liu, Jinglin and Li, Chengxi and Ren, Yi and Chen, Feiyang and Liu, Peng and Zhao, Zhou},
journal={arXiv preprint arXiv:2105.02446},
volume={2},
year={2021}}
Acknowledgements
Especially thanks to:
- Team Openvpi's maintenance: DiffSinger.
- Your re-creation and sharing.
 →

 →
 →
 →
 →
 →
 →
 →