1
 →

Local Laya typed decisions on Apple Core ML and Neural Engine. Validated ports, ~5 ms short decisions on M3 Max, reproducible speed and energy benchmarks.
mizorewww/laya-coreml is an open-source project on GitHub, mainly written in Python. Local Laya typed decisions on Apple Core ML and Neural Engine. Validated ports, ~5 ms short decisions on M3 Max, reproducible speed and energy benchmarks. It currently holds 105 stars and 9 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the Today's Trending board, currently at rank #97 with 0 new stars today.
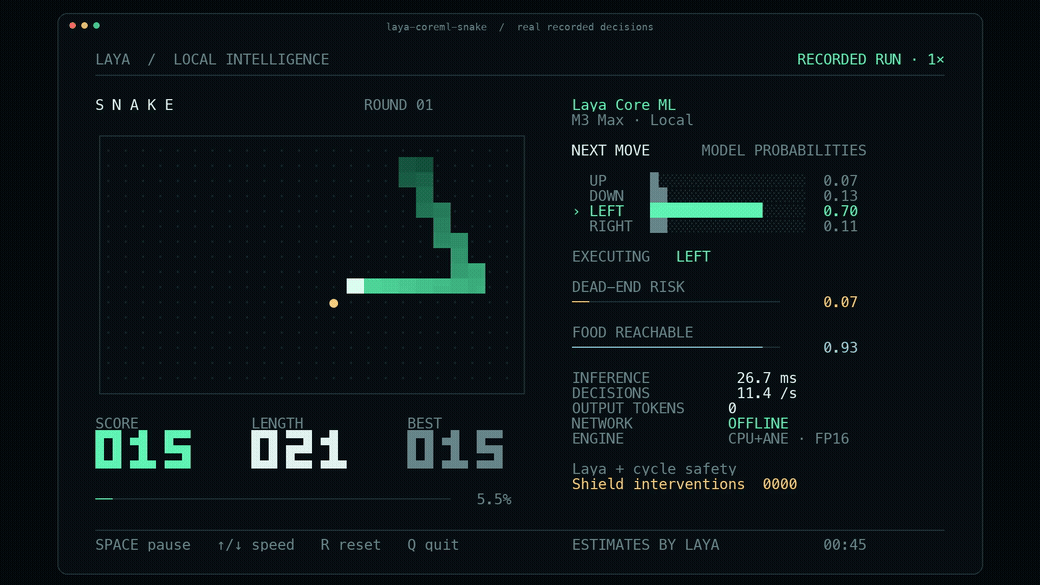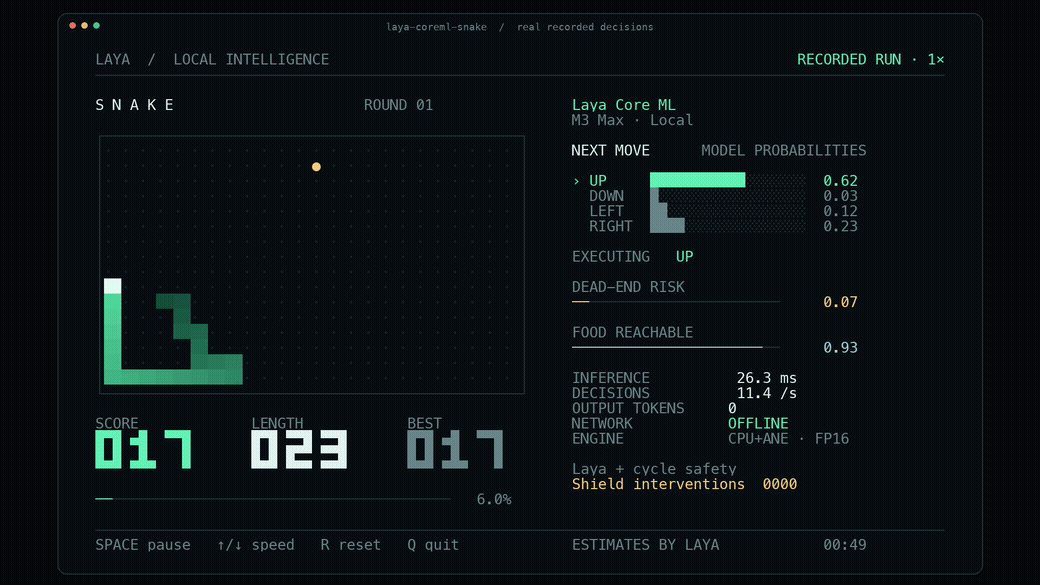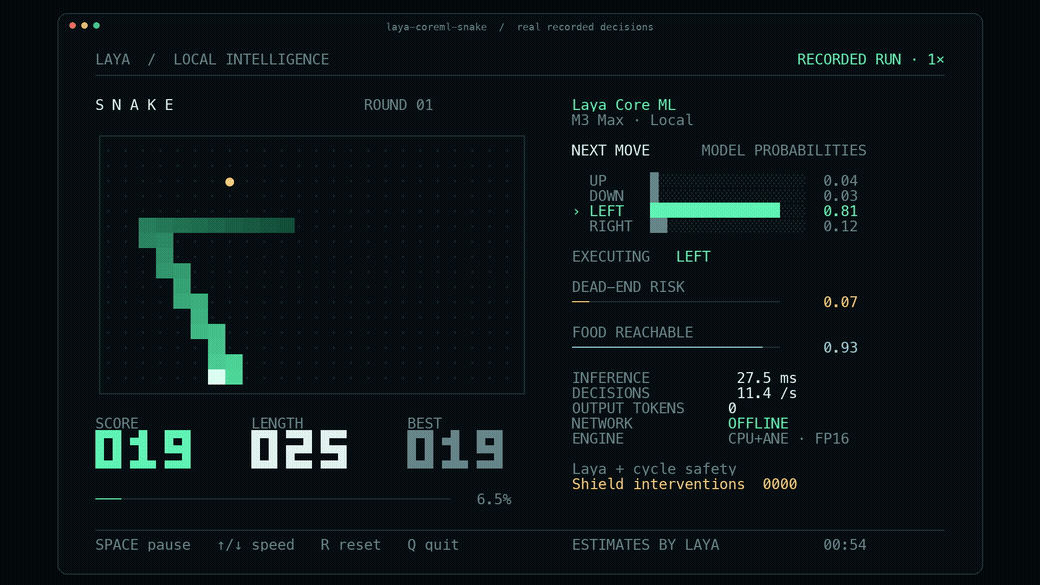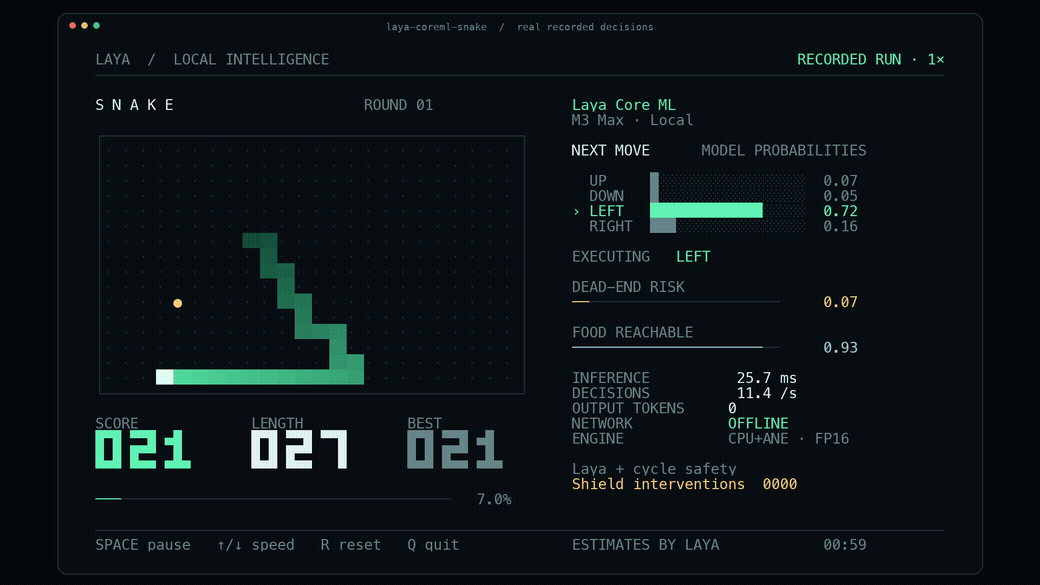
Open-weight typed decisions on Apple Silicon. Core ML, Neural Engine, zero generated tokens.
PyPI · Hugging Face weights · 中文
A real Laya model plays Snake locally, with visible probabilities, score, length, latency and safety interventions. The GIF replays a recorded Core ML run at 1× speed. The game uses explicit planner features and a visible cycle safety layer.
The complete active Snake loop sustained 49.1–50.0 decisions/s across three uncapped 600-step episodes, with zero deaths and two safety interventions. Game-loop timings and paced-rate limits include rendering serialization; terminal painting is excluded.
One short multilingual decision: 4.98 ms P50 / 5.31 ms P95 on M3 Max with ANE FP16. The same experiment measured 2.78× better whole-system energy per decision than compiled MLX FP16. A separately validated W8 palette variant reached 4.88 ms and 3.19× energy improvement. These are single-question results, not full Snake frame times; the requested 10× improvement was not achieved.
Apple Silicon · macOS 15+ · Python 3.11–3.13.
pip install 'laya-coreml[demo]'
hf download aac6fef/laya-multilingual-coreml-ane --local-dir models/snake
laya-coreml-snake --model ./models/snake
Download once, then play offline. No PyTorch, Transformers or MLX is needed for inference. The terminal needs 104 columns × 35 rows. Space pauses; ↑/↓ changes speed; R resets; Q quits. First-time Core ML initialization can take tens of seconds.
Controls, recording and video export · Measured stable decision rates · Shareable video and recording provenance
pip install laya-coreml
import laya_coreml as laya
agent = laya.load("aac6fef/laya-multilingual-coreml-ane")
result = agent.predict(
    "The customer requests a refund of a duplicate payment.",
    {
        "refund": {
            "type": "noul",
            "instructions": "Does the customer request a refund?",
        }
    },
)
print(result["answers"]["refund"])
Laya returns probabilities for choice, ordinal score, and boolean noul
questions. There is no autoregressive decoding or generated JSON to parse. Hub
models download before initialization; subsequent predictions stay local. Pass
local_files_only=True to require an existing cache, or load a local directory.
The ANE bundle has a 96-token total limit, including question, options and
state. Longer requests raise a capacity error. Use
aac6fef/laya-multilingual-coreml for the general-purpose 1024-token model.
Full API, model selection and offline usage.
40-core GPU, 128 GiB, macOS 27.2. One 91-token question padded to 96, including prompt preparation, tokenization, arrays, synchronous inference, calibration and formatting. Loading and warmup are excluded. MLX enables compile, prefix caching and shape buckets. Six alternating 20-second blocks per implementation produced 65,598 stable calls.
| Metric | Compiled MLX FP16 | Core ML ANE FP16 | Core ML ANE W8 | |---|---:|---:|---:| | P50 / P95 | 6.94 / 7.39 ms | 4.98 / 5.31 ms | 4.88 / 5.23 ms | | Mean system power estimate | 61.39 W | 30.75 W | 27.39 W | | System energy / decision | 0.4288 J | 0.1540 J | 0.1344 J | | Speed gain | 1× | 1.39× | 1.42× | | System energy gain | 1× | 2.78× | 3.19× |
Energy uses direct SMC PSTR sensor readings, with raw samples and explicit anomaly rejection. This is an estimate with sensor and background-load uncertainty. Speed gain × average power ratio = energy gain; multiplying energy by speed again would double-count time. The W8 variant compresses weights while retaining FP16 compute. It is approximate, and its package-size reduction is not a speed ratio.
Speed, energy and hardware evidence · Raw measurements.
| Hugging Face bundle | Default engine | Capacity | Purpose | |---|---|---:|---| | Laya 421M | CPU + GPU | 512 tokens | Original English model | | Multilingual 322M | CPU + GPU | 1024 tokens | General multilingual decisions | | Typed Decisions 421M | CPU + GPU | 1024 tokens | Original specialized checkpoint | | Snake GPU | CPU + GPU | B3 / L64 | Batches the three compact game questions | | Multilingual ANE | CPU + ANE | B1 / L96 | Short decisions, FP16 | | Multilingual ANE W8 | CPU + ANE | B1 / L96 | Optional approximate palette compression |
Every bundle includes tokenizer/configuration, model card, provenance, checksums and packaging-time validation. ANE bundles also include the exact original host embedding/action tensors they need. No original training checkout is required.
The three general-purpose FP16 checkpoints match upstream selected answers on 189/189 validation questions. Each passes 100 repeated calls. ANE FP16 L96 passes 59/59 fitting questions, with maximum calibrated-probability drift 0.002925; W8 passes the same subset with drift 0.014393 under an unchanged 0.02 gate. Six- and four-bit experiments failed that gate and are not published weights. These are conversion-fidelity fixtures, not proof of general task accuracy.
A separately exported FP16 ANE L1024 graph passes the complete 63/63 fixture, but an actual 1024-token request takes about 91.7 ms in its serial screen. The short ANE result does not establish a long-context advantage. A 600-step paired Snake check matches 600/600 actions, with zero deaths and zero shield interventions; the current ANE adapter's three sequential calls do not establish a consistent full-game speedup over compiled MLX.
The ordinary SDPA Core ML export and the ANE graph are different implementations. The ordinary export defaults to CPU+GPU after unrestricted RangeDim GPU shapes failed local fidelity checks. Changing its device setting alone does not reproduce the ANE result. The ANE rewrite uses BC1L activations, 1×1 projections and per-head attention; its plan and a separate Instruments trace support Neural Engine work. CPU still handles input/output boundaries.
laya-coreml[convert] and run
laya-coreml convert laya-multilingual models/custom. ANE research conversion,
compression and benchmark scripts live in the Git checkout. The inference wheel
contains the portable runtime and optional terminal demo.
Apache-2.0. Independent port of Laya, by Convai Innovations and contributors, building on the MLX sibling project. Not an official Convai Innovations or Apple release. See NOTICE.
→ →
 →
 →
 →
 →
 →
 →