1
 →

Implementation of Make-A-Video, new SOTA text to video generator from Meta AI, in Pytorch
lucidrains/make-a-video-pytorch is an open-source project on GitHub, mainly written in Python. Implementation of Make-A-Video, new SOTA text to video generator from Meta AI, in Pytorch It currently holds 1,987 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Video Projects board and on the AI AI Video Projects list.
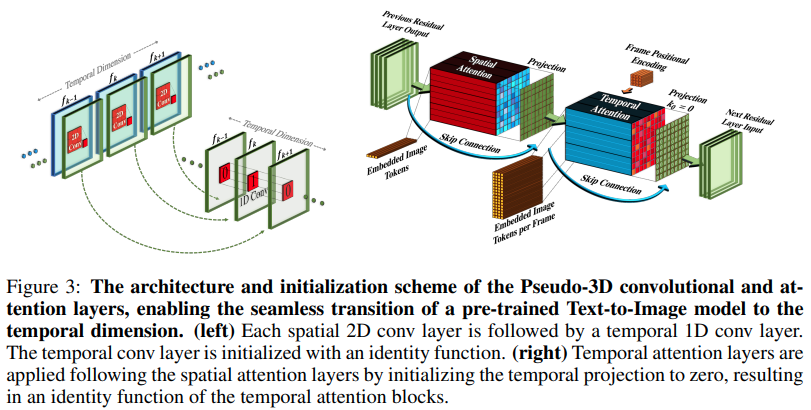
Implementation of Make-A-Video, new SOTA text to video generator from Meta AI, in Pytorch. They combine pseudo-3d convolutions (axial convolutions) and temporal attention and show much better temporal fusion.
The pseudo-3d convolutions isn't a new concept. It has been explored before in other contexts, say for protein contact prediction as "dimensional hybrid residual networks".
The gist of the paper comes down to, take a SOTA text-to-image model (here they use DALL-E2, but the same learning points would easily apply to Imagen), make a few minor modifications for attention across time and other ways to skimp on the compute cost, do frame interpolation correctly, get a great video model out.
$ pip install make-a-video-pytorch
Passing in video features
import torch
from make_a_video_pytorch import PseudoConv3d, SpatioTemporalAttention
conv = PseudoConv3d(
    dim = 256,
    kernel_size = 3
)
attn = SpatioTemporalAttention(
    dim = 256,
    dim_head = 64,
    heads = 8
)
video = torch.randn(1, 256, 8, 16, 16) # (batch, features, frames, height, width)
conv_out = conv(video) # (1, 256, 8, 16, 16)
attn_out = attn(video) # (1, 256, 8, 16, 16)
Passing in images (if one were to pretrain on images first), both temporal convolution and attention will be automatically skipped. In other words, you can use this straightforwardly in your 2d Unet and then port it over to a 3d Unet once that phase of the training is done. The temporal modules are initialized to output identity as the paper had done.
import torch
from make_a_video_pytorch import PseudoConv3d, SpatioTemporalAttention
conv = PseudoConv3d(
    dim = 256,
    kernel_size = 3
)
attn = SpatioTemporalAttention(
    dim = 256,
    dim_head = 64,
    heads = 8
)
images = torch.randn(1, 256, 16, 16) # (batch, features, height, width)
conv_out = conv(images) # (1, 256, 16, 16)
attn_out = attn(images) # (1, 256, 16, 16)
You can also control the two modules so that when fed 3-dimensional features, it only does training spatially
import torch
from make_a_video_pytorch import PseudoConv3d, SpatioTemporalAttention
conv = PseudoConv3d(
    dim = 256,
    kernel_size = 3
)
attn = SpatioTemporalAttention(
    dim = 256,
    dim_head = 64,
    heads = 8
)
video = torch.randn(1, 256, 8, 16, 16) # (batch, features, frames, height, width)
below it will not train across time
conv_out = conv(video, enable_time = False) # (1, 256, 8, 16, 16)
attn_out = attn(video, enable_time = False) # (1, 256, 8, 16, 16)
Full SpaceTimeUnet that is agnostic to images or video training, and where even if video is passed in, time can be ignored
import torch
from make_a_video_pytorch import SpaceTimeUnet
unet = SpaceTimeUnet(
    dim = 64,
    channels = 3,
    dim_mult = (1, 2, 4, 8),
    resnet_block_depths = (1, 1, 1, 2),
    temporal_compression = (False, False, False, True),
    self_attns = (False, False, False, True),
    condition_on_timestep = False,
    attn_pos_bias = False,
    flash_attn = True
).cuda()
train on images
images = torch.randn(1, 3, 128, 128).cuda()
images_out  = unet(images)
assert images.shape == images_out.shape
then train on videos
video = torch.randn(1, 3, 16, 128, 128).cuda()
video_out = unet(video)
assert video_out.shape == video.shape
or even treat your videos as images
video_as_images_out = unet(video, enable_time = False)
SpaceTimeUnet for training@misc{Singer2022,
author = {Uriel Singer},
url = {https://makeavideo.studio/Make-A-Video.pdf}
}
@inproceedings{rogozhnikov2022einops,
    title   = {Einops: Clear and Reliable Tensor Manipulations with Einstein-like Notation},
    author  = {Alex Rogozhnikov},
    booktitle = {International Conference on Learning Representations},
    year    = {2022},
    url     = {https://openreview.net/forum?id=oapKSVM2bcj}
}
@article{Dong2021AttentionIN,
    title   = {Attention is Not All You Need: Pure Attention Loses Rank Doubly Exponentially with Depth},
    author  = {Yihe Dong and Jean-Baptiste Cordonnier and Andreas Loukas},
    journal = {ArXiv},
    year    = {2021},
    volume  = {abs/2103.03404}
}
@article{Zhang2021TokenST,
    title   = {Token Shift Transformer for Video Classification},
    author  = {Hao Zhang and Y. Hao and Chong-Wah Ngo},
    journal = {Proceedings of the 29th ACM International Conference on Multimedia},
    year    = {2021}
}
@inproceedings{shleifer2022normformer,
    title   = {NormFormer: Improved Transformer Pretraining with Extra Normalization},
    author  = {Sam Shleifer and Myle Ott},
    booktitle = {Submitted to The Tenth International Conference on Learning Representations },
    year    = {2022},
    url     = {https://openreview.net/forum?id=GMYWzWztDx5},
}
@inproceedings{dao2022flashattention,
    title   = {Flash{A}ttention: Fast and Memory-Efficient Exact Attention with {IO}-Awareness},
    author  = {Dao, Tri and Fu, Daniel Y. and Ermon, Stefano and Rudra, Atri and R{\'e}, Christopher},
    booktitle = {Advances in Neural Information Processing Systems},
    year    = {2022}
}
 →
 →
 →
 →
 →
 →
 →