llm-d/llm-d is an open-source project on GitHub, mainly written in Shell. Achieve state of the art inference performance with modern accelerators on Kubernetes It currently holds 4,550 stars and 770 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
Achieve SOTA Inference Performance On Any Accelerator
llm-d is a high-performance distributed inference serving stack optimized for production deployments on Kubernetes. We help you achieve the fastest "time to state-of-the-art (SOTA) performance" for key OSS large language models across most hardware accelerators and infrastructure providers with well-tested guides and real-world benchmarks.
Model servers like vLLM and SGLang handle efficiently running large language models on accelerators. llm-d provides state-of-the-art orchestration and optimizations above model servers to serve high-scale real-world traffic efficiently and reliably. Our offerings are organized into the following themes:
Intelligent Routing: Maximize performance with prefix-cache and load-aware balancing, including experimental predicted latency-based scheduling to decrease latency and increase throughput.
Advanced KV-Cache Management: Increase the effective "working set size" for multi-turn requests with tiered offloading to CPU or disk and precise global indexing of the KV cache state.
Serving Large Models: Optimize massive models (e.g., DeepSeek-R1, GPT-OSS) using prefill/decode disaggregation and wide expert-parallelism over fast accelerator interconnects.
Operational Excellence: Ensure production stability with intelligent flow control for multi-tenant serving and proactive, SLO-aware autoscaling based on real-time inference signals.
Batch Processing: Efficiently manage large-scale offline inference with OpenAI-compatible Batch APIs and asynchronous processing to maximize hardware utilization.
For a complete list of tested recipes and architectural patterns, see our well-lit path guides. These guides provide benchmarked recipes and Helm charts to start serving quickly with best practices common to production deployments. Our intent is to eliminate the heavy lifting common in tuning and deploying generative AI inference on modern accelerators.
Performance Highlights
Validated performance gains from production deployments and partner benchmarks:
3x higher output throughput and 2x faster TTFT with prefix-cache-aware routing vs round-robin — Llama 3.1 70B on 4× AMD MI300X, Tesla / Red Hat (blog)
40% reduction in TTFT and ITL with predicted-latency scheduling vs heuristics on NVIDIA GPUs, Google (blog)
Up to 70% higher tokens/sec with prefill/decode disaggregation vs standard vLLM — GPT-OSS on NVIDIA B200 (p6-b200), AWS (blog)
10–30% throughput improvement with disaggregated serving on identical infrastructure — GPT-OSS-120B and Llama 3.3 70B on AMD MI300X, Oracle (blog)
50k tokens/sec cluster throughput with Wide Expert-Parallelism — 16×16 NVIDIA B200, ~3.1k tok/s per GPU (blog)
13.9x throughput improvement with hierarchical KV offloading at 250 concurrent users vs GPU-only — 4× NVIDIA H100 (blog)
Explore detailed, reproducible benchmarks on Prism.
Get Started Now
Ready to achieve SOTA performance? Follow our Quickstart Guide to deploy your first optimized inference service on Kubernetes. You'll learn how to set up the llm-d stack, configure the intelligent router, and validate performance with production-ready benchmarks.
[!TIP]
Most users begin with our Optimized Baseline, which provides a high-performance foundation for a wide range of LLM serving use cases.
Latest News 🔥
[2026-05] The v0.7 release introduces an optimized baseline renamed and stabilized, kustomize-first migrated guides, expanded nightly CI (OpenShift, GKE, CoreWeave), predicted-latency scheduling GA, batch gateway (experimental), and revamped project-wide documentation.
[2026-03] llm-d joins the CNCF as a Sandbox project! Founded by Red Hat, Google Cloud, IBM Research, CoreWeave, and NVIDIA, with support from AMD, Cisco, Hugging Face, Intel, Lambda, Mistral AI, UC Berkeley, and University of Chicago. We're excited to collaborate openly on building flexible, future-proof AI infrastructure.
[2026-02] The v0.5 introduces reproducible benchmark workflows, hierarchical KV offloading, cache-aware LoRA routing, active-active HA, UCCL-based transport resilience, and scale-to-zero autoscaling; validated ~3.1k tok/s per B200 decode GPU (wide-EP) and up to 50k output tok/s on a 16×16 B200 prefill/decode topology with order-of-magnitude TTFT reduction vs round-robin baseline.
[2025-12] The v0.4 release demonstrates 40% reduction in per output token latency for DeepSeek V3.1 on H200 GPUs, Intel XPU and Google TPU disaggregation support for lower time to first token, a new well-lit path for prefix cache offload to vLLM-native CPU memory tiering, and a preview of the workload variant autoscaler improving model-as-a-service efficiency.
🧱 Architecture
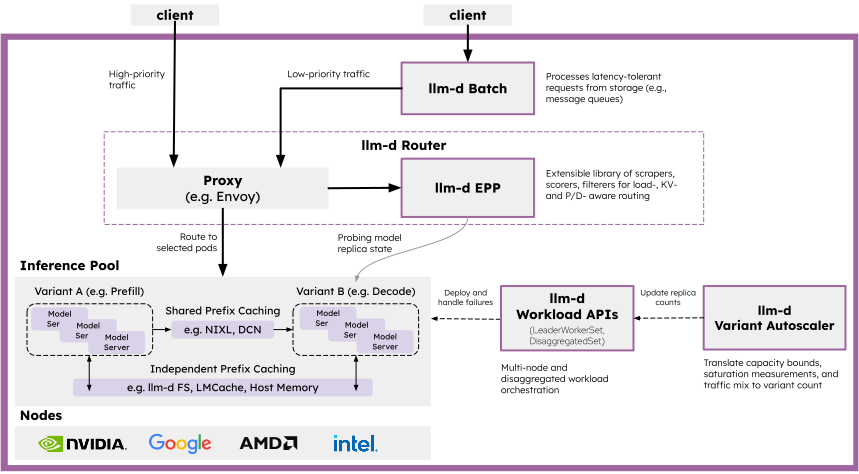
llm-d accelerates distributed inference by integrating industry-standard open technologies like vLLM and Kubernetes. For more details, see our full Architecture Documentation.
📦 Releases
Our guides are living docs and kept current. For details about the Helm charts and component releases, visit our GitHub Releases page to review release notes.
See the accelerator docs for points of contact and more details about the accelerators, networks, and configurations tested.
Join one of our Special Interest Groups (SIGs) to contribute to specific areas of the project and collaborate with domain experts.
We use Slack to discuss development across organizations. Please join: Slack
We host a bi-weekly standup for contributors every other Wednesday at 12:30 PM ET, as well as meetings for various SIGs. You can find them in the shared llm-d calendar
We use Google Groups to share architecture diagrams and other content. Please join: Google Group
License
This project is licensed under Apache License 2.0. See the LICENSE file for details.
 →



 →
 →
 →
 →
 →
 →
 →