
1
 →
lightseekorg/tokenspeed is an open-source project on GitHub, mainly written in Python. TokenSpeed is a speed-of-light LLM inference engine. It currently holds 2,424 stars and 331 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the Today's Trending board, currently at rank #61 with 25 new stars today.
TokenSpeed is a speed-of-light LLM inference engine designed for agentic workloads, with TensorRT-LLM-level performance and vLLM-level usability. The goal is to be the most performant inference engine for production agentic workloads.
Core components:
TokenSpeed takes a fundamentally different architectural approach from existing LLM inference engines. The PyTorch Foundation highlighted these architectural differentiators when welcoming TokenSpeed to the PyTorch Ecosystem Landscape:
TokenSpeed is an open source LLM inference engine and the first to separate the control plane from the execution plane. The control plane is implemented in C++ as a finite-state machine, using the type system to enforce safe resource management, including request lifecycles and KV cache state, at compile time rather than runtime. The execution plane is implemented in Python, enabling fast iteration and lowering the cognitive load for researchers and engineers. This architecture combines strong correctness guarantees in the core scheduling system with the development velocity of a high-level execution layer.
> TokenSpeed also treats kernels as a first-class, modular subsystem, separating them from the core engine through a portable public API, centralized registry and selection model, and an extensible plugin mechanism for heterogeneous accelerators.
More importantly, TokenSpeed is the Switzerland of open-source LLM inference engines: neutral because it's backed by the non-profit LightSeek Foundation rather than a commercial company, with serious hardware and engineering support from vendors like NVIDIA and AMD.
For technical blogs, conference talks, and engineering articles from LightSeek Foundation, visit the LightSeek Blog.
LightSeek's work is advanced by the support of sponsors and partners across the AI ecosystem.
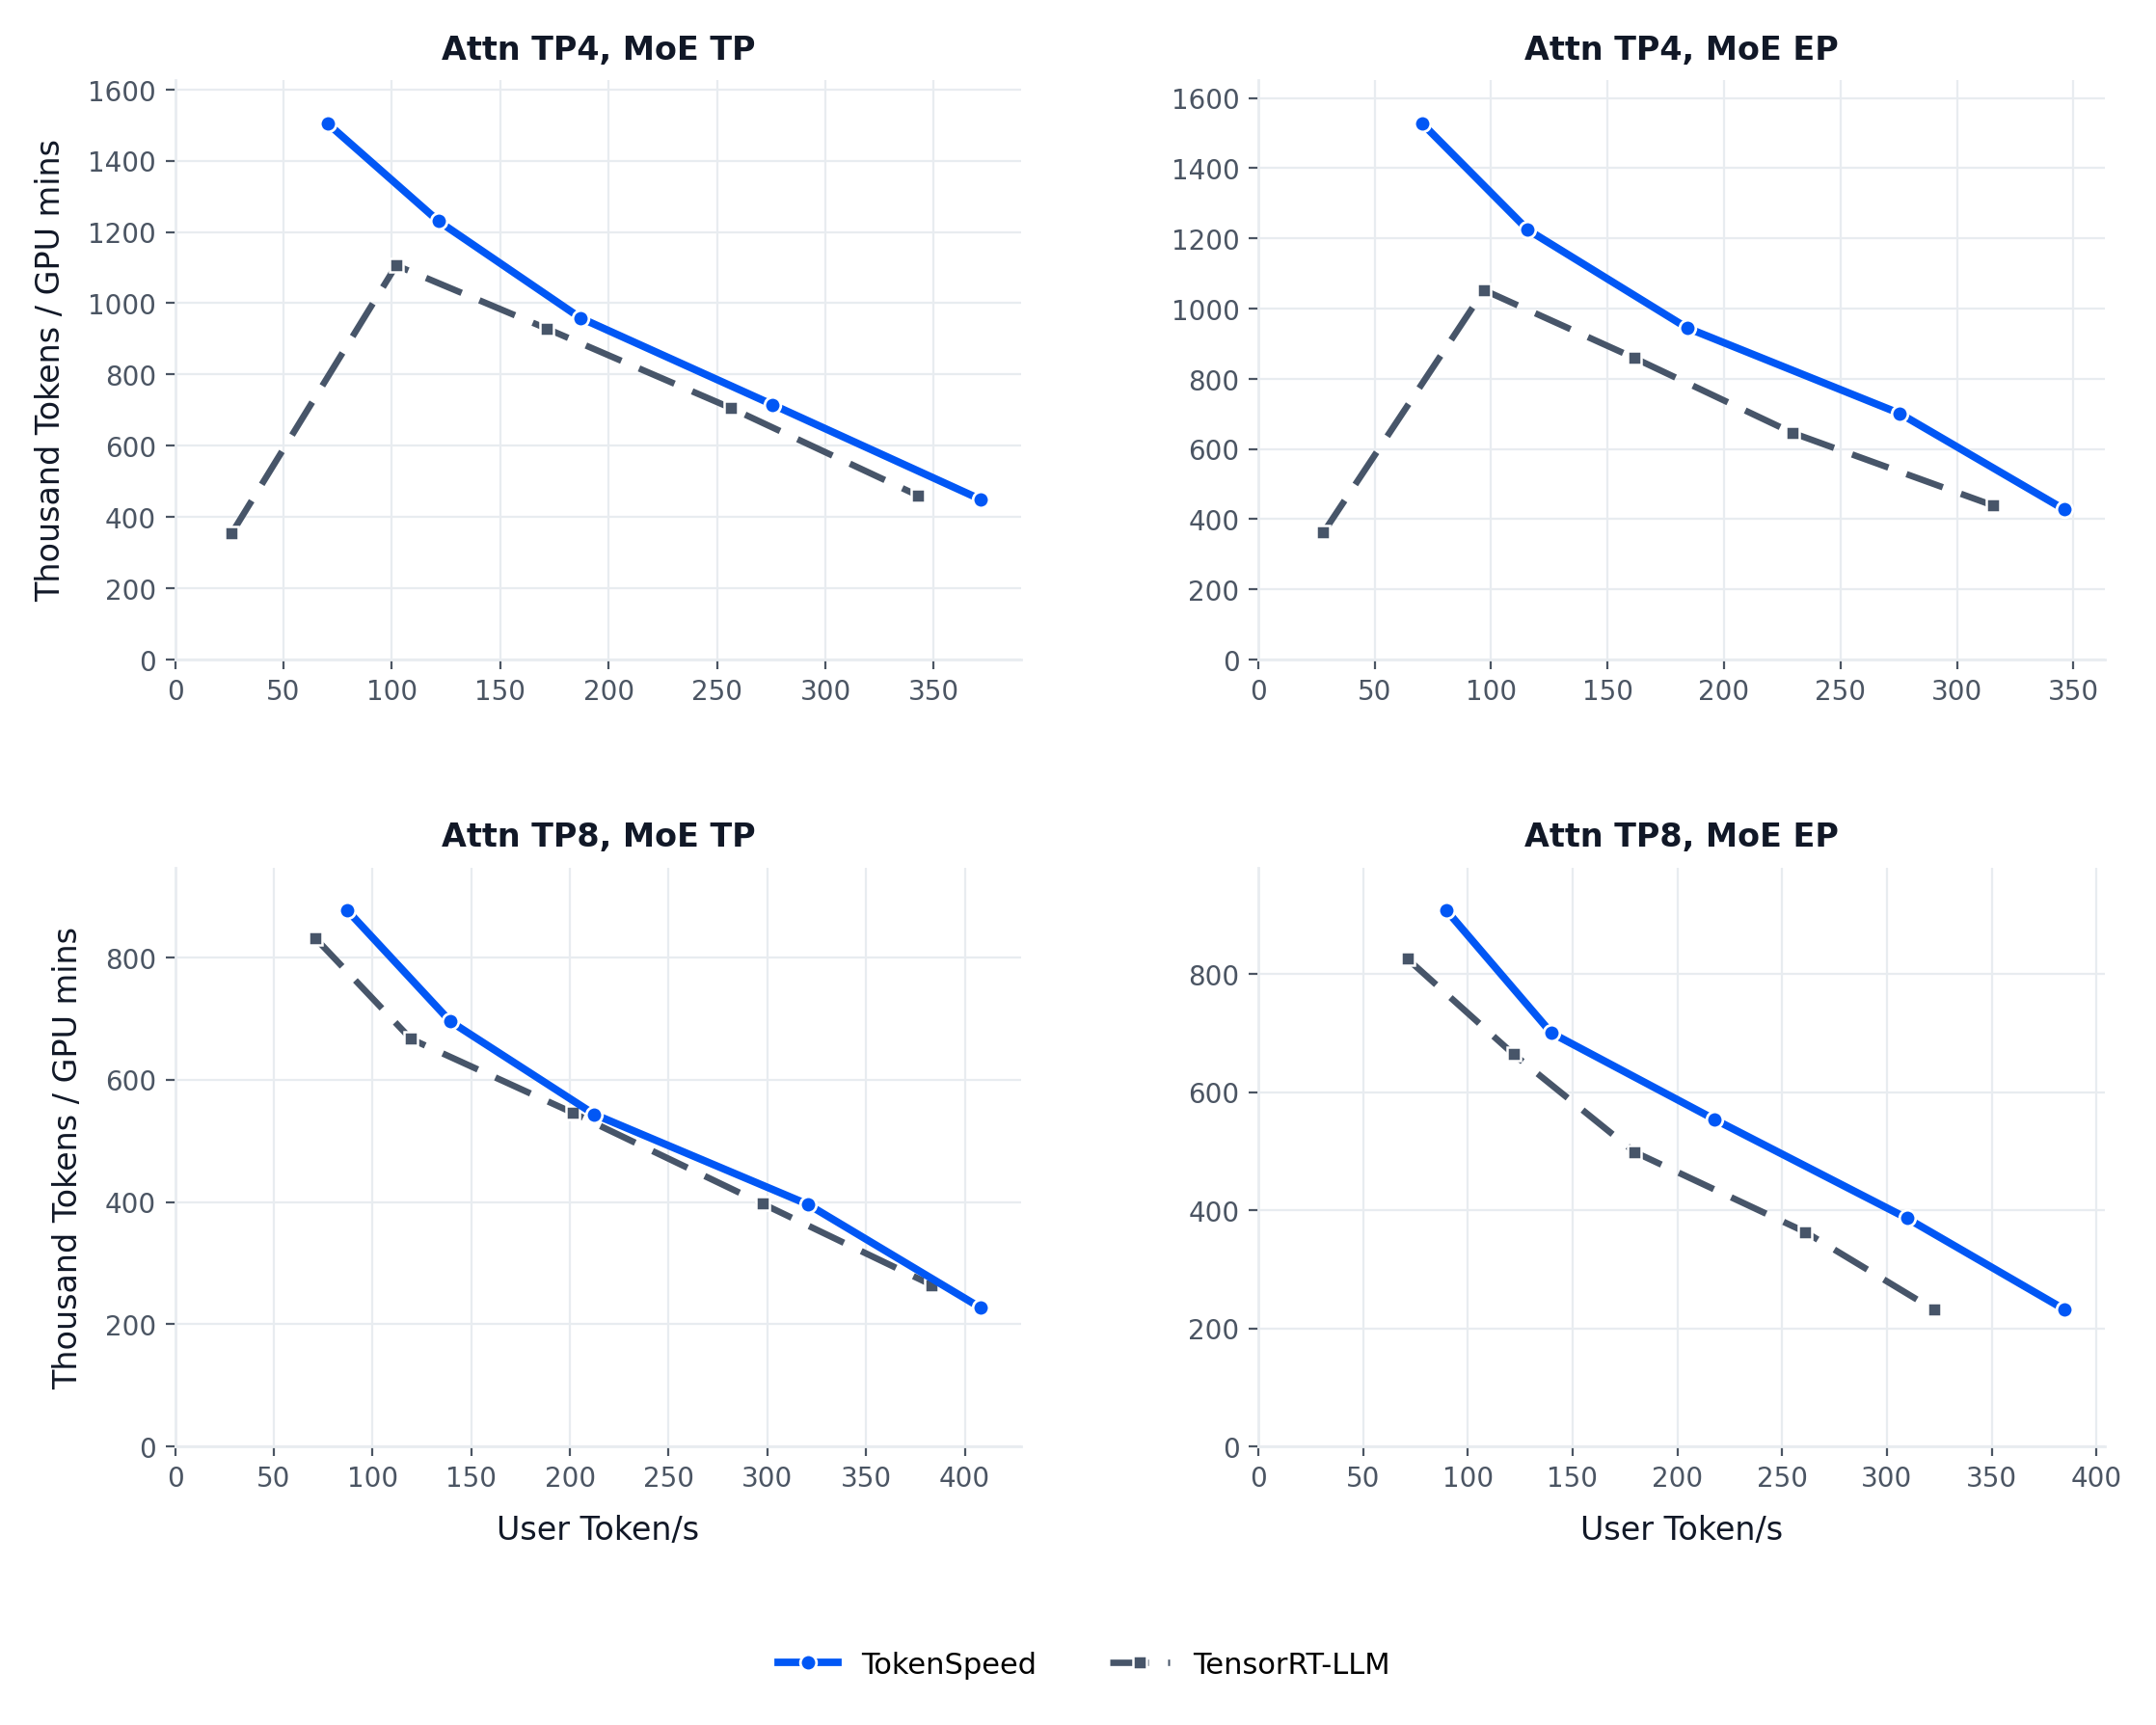
TokenSpeed vs. TensorRT-LLM Pareto curves on agentic workloads (Kimi K2.5, B200)
Start here:
@misc{tokenspeed2026,
  author       = {{TokenSpeed Team}},
  title        = {{TokenSpeed}: A Speed-of-Light {LLM} Inference Engine},
  year         = {2026},
  howpublished = {\url{https://github.com/lightseekorg/tokenspeed}}
}
 →
 →
 →
 →
 →
 →
 →