
1
 →
lehduong/OneDiffusion is an open-source project on GitHub, mainly written in Python. Official implementation of OneDiffusion paper (CVPR 2025) It currently holds 666 stars and 19 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Image Projects board and on the AI AI Image Projects list.
News | Quick start | Prompt guide & Supported tasks | Qualitative results | License | Citation
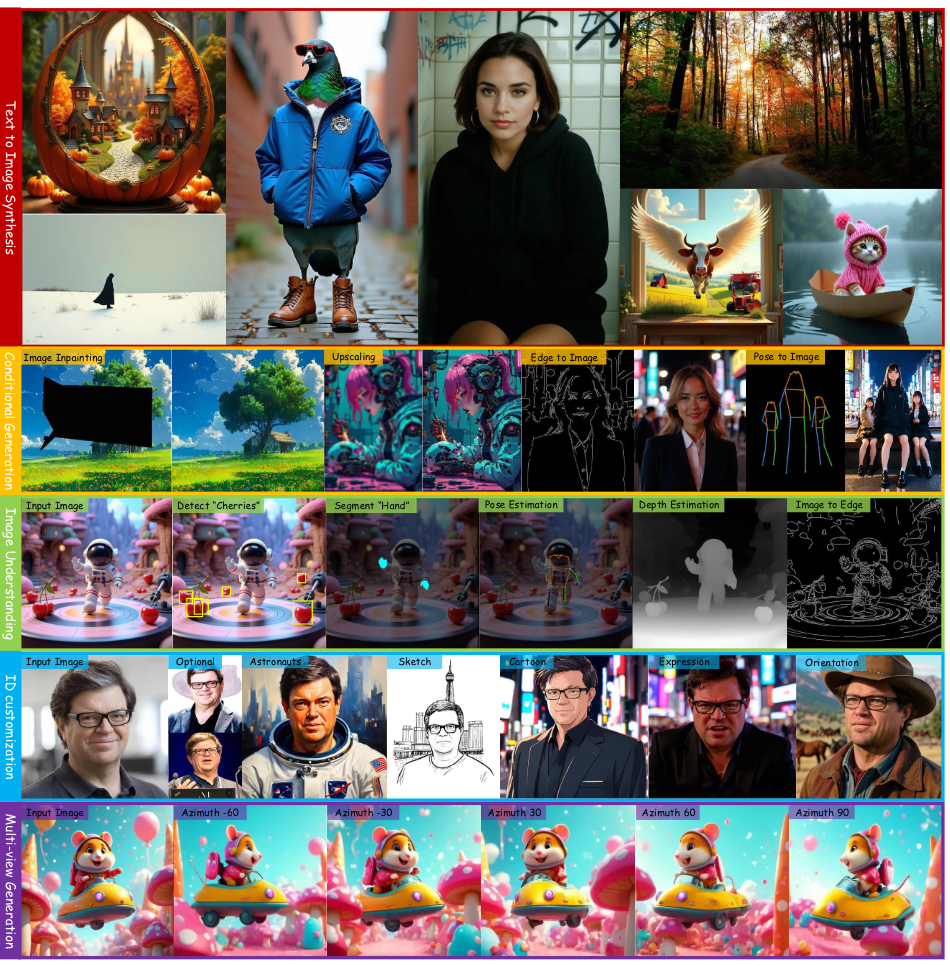
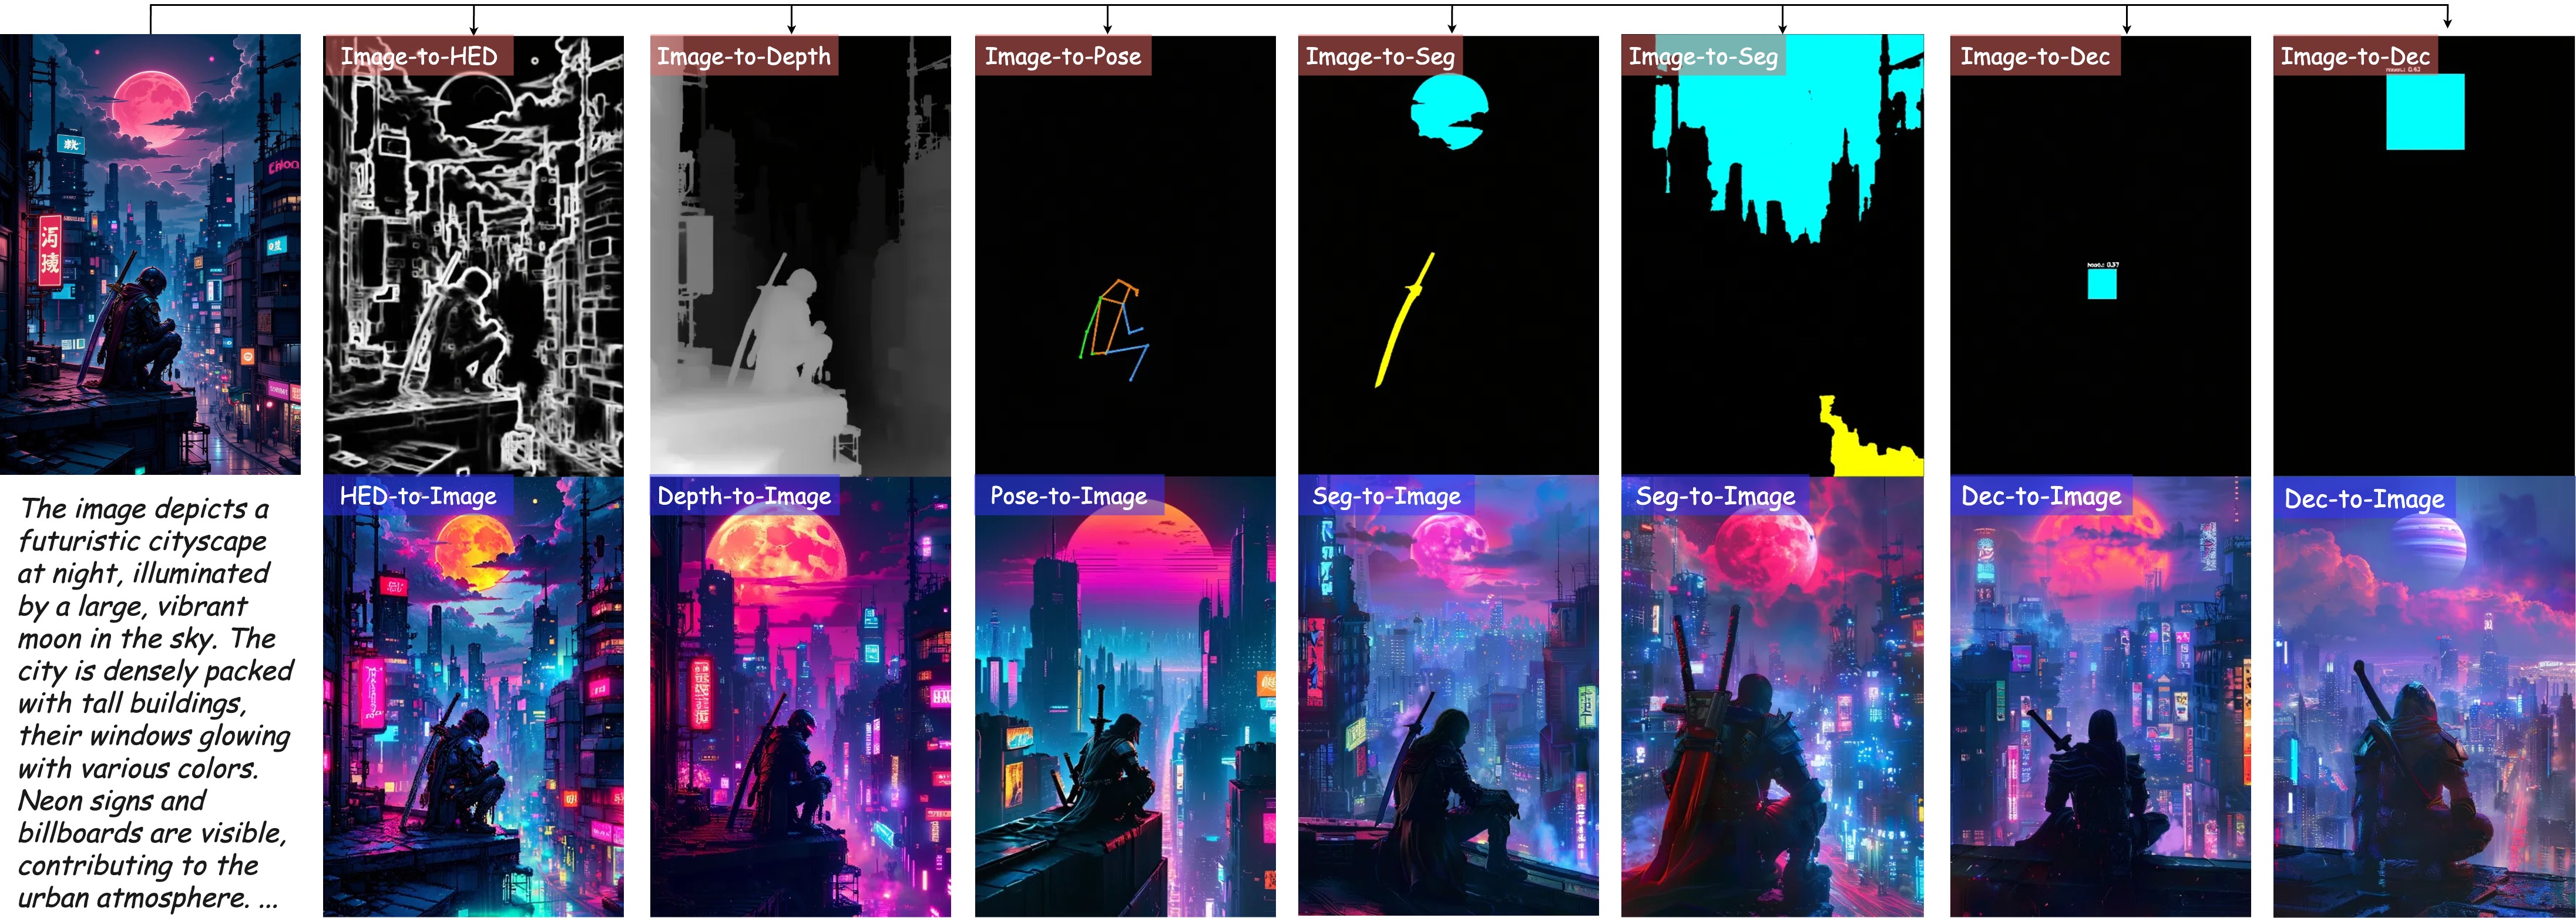
This is official repo of OneDiffusion, a versatile, large-scale diffusion model that seamlessly supports bidirectional image synthesis and understanding across diverse tasks.
For more detail, read our paper here.
conda create -n onediffusion_env python=3.8 &&
conda activate onediffusion_env &&
pip install torch==2.3.1 torchvision==0.18.1 torchaudio==2.3.1 --index-url https://download.pytorch.org/whl/cu118 &&
pip install "git+https://github.com/facebookresearch/pytorch3d.git" &&
pip install -r requirements.txt
Check inference.py for more detailed. For text-to-image, you can use below code snipe.
import torch
from onediffusion.diffusion.pipelines.onediffusion import OneDiffusionPipeline
device = torch.device('cuda:0')
pipeline = OneDiffusionPipeline.from_pretrained("lehduong/OneDiffusion").to(device=device, dtype=torch.bfloat16)
NEGATIVE_PROMPT = "monochrome, greyscale, low-res, bad anatomy, bad hands, text, error, missing fingers, extra digit, fewer digits, cropped, worst quality, low quality, normal quality, jpeg artifacts, signature, watermark, username, blurry, artist name, poorly drawn, bad anatomy, wrong anatomy, extra limb, missing limb, floating limbs, disconnected limbs, mutation, mutated, ugly, disgusting, blurry, amputation"
output = pipeline(
    prompt="[[text2image]] A bipedal black cat wearing a huge oversized witch hat, a wizards robe, casting a spell,in an enchanted forest. The scene is filled with fireflies and moss on surrounding rocks and trees",
    negative_prompt=NEGATIVE_PROMPT,
    num_inference_steps=50,
    guidance_scale=4,
    height=1024,
    width=1024,
)
output.images[0].save('text2image_output.jpg')
You can run the gradio demo with:
python gradio_demo.py --captioner molmo # [molmo, llava, disable]
disable mode. In this mode, the returned caption is an empty string, but you should still press the Generate Caption button so that the code formats the input text properly. The memory requirement for this mode is $\approx 12$ GB.
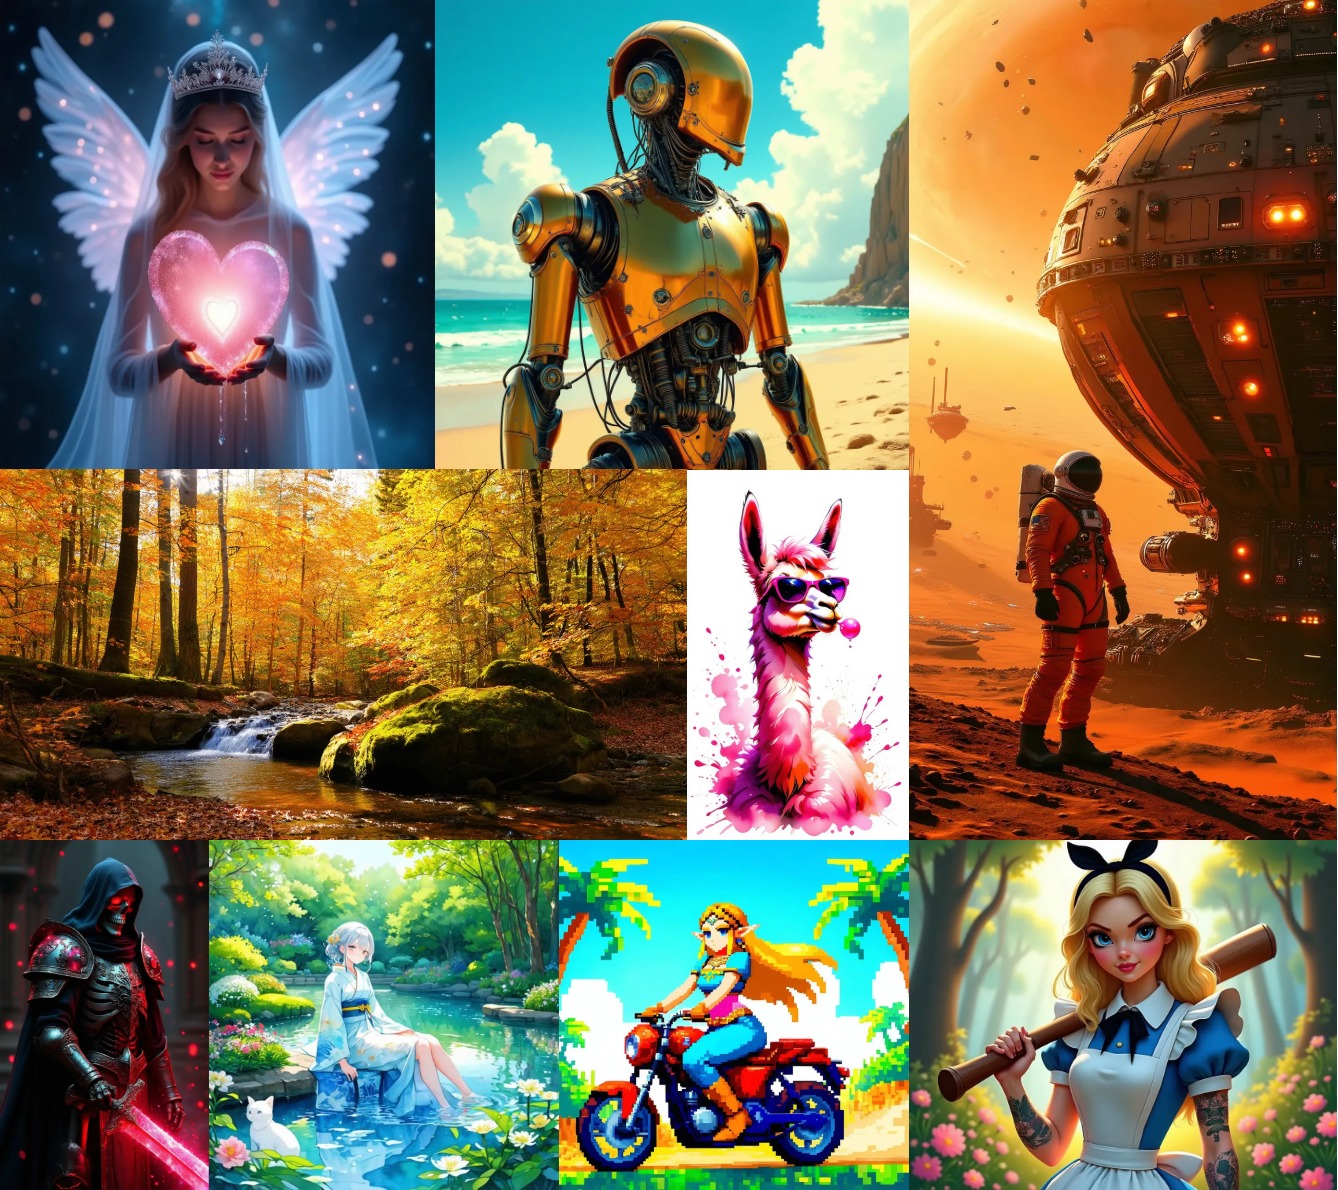
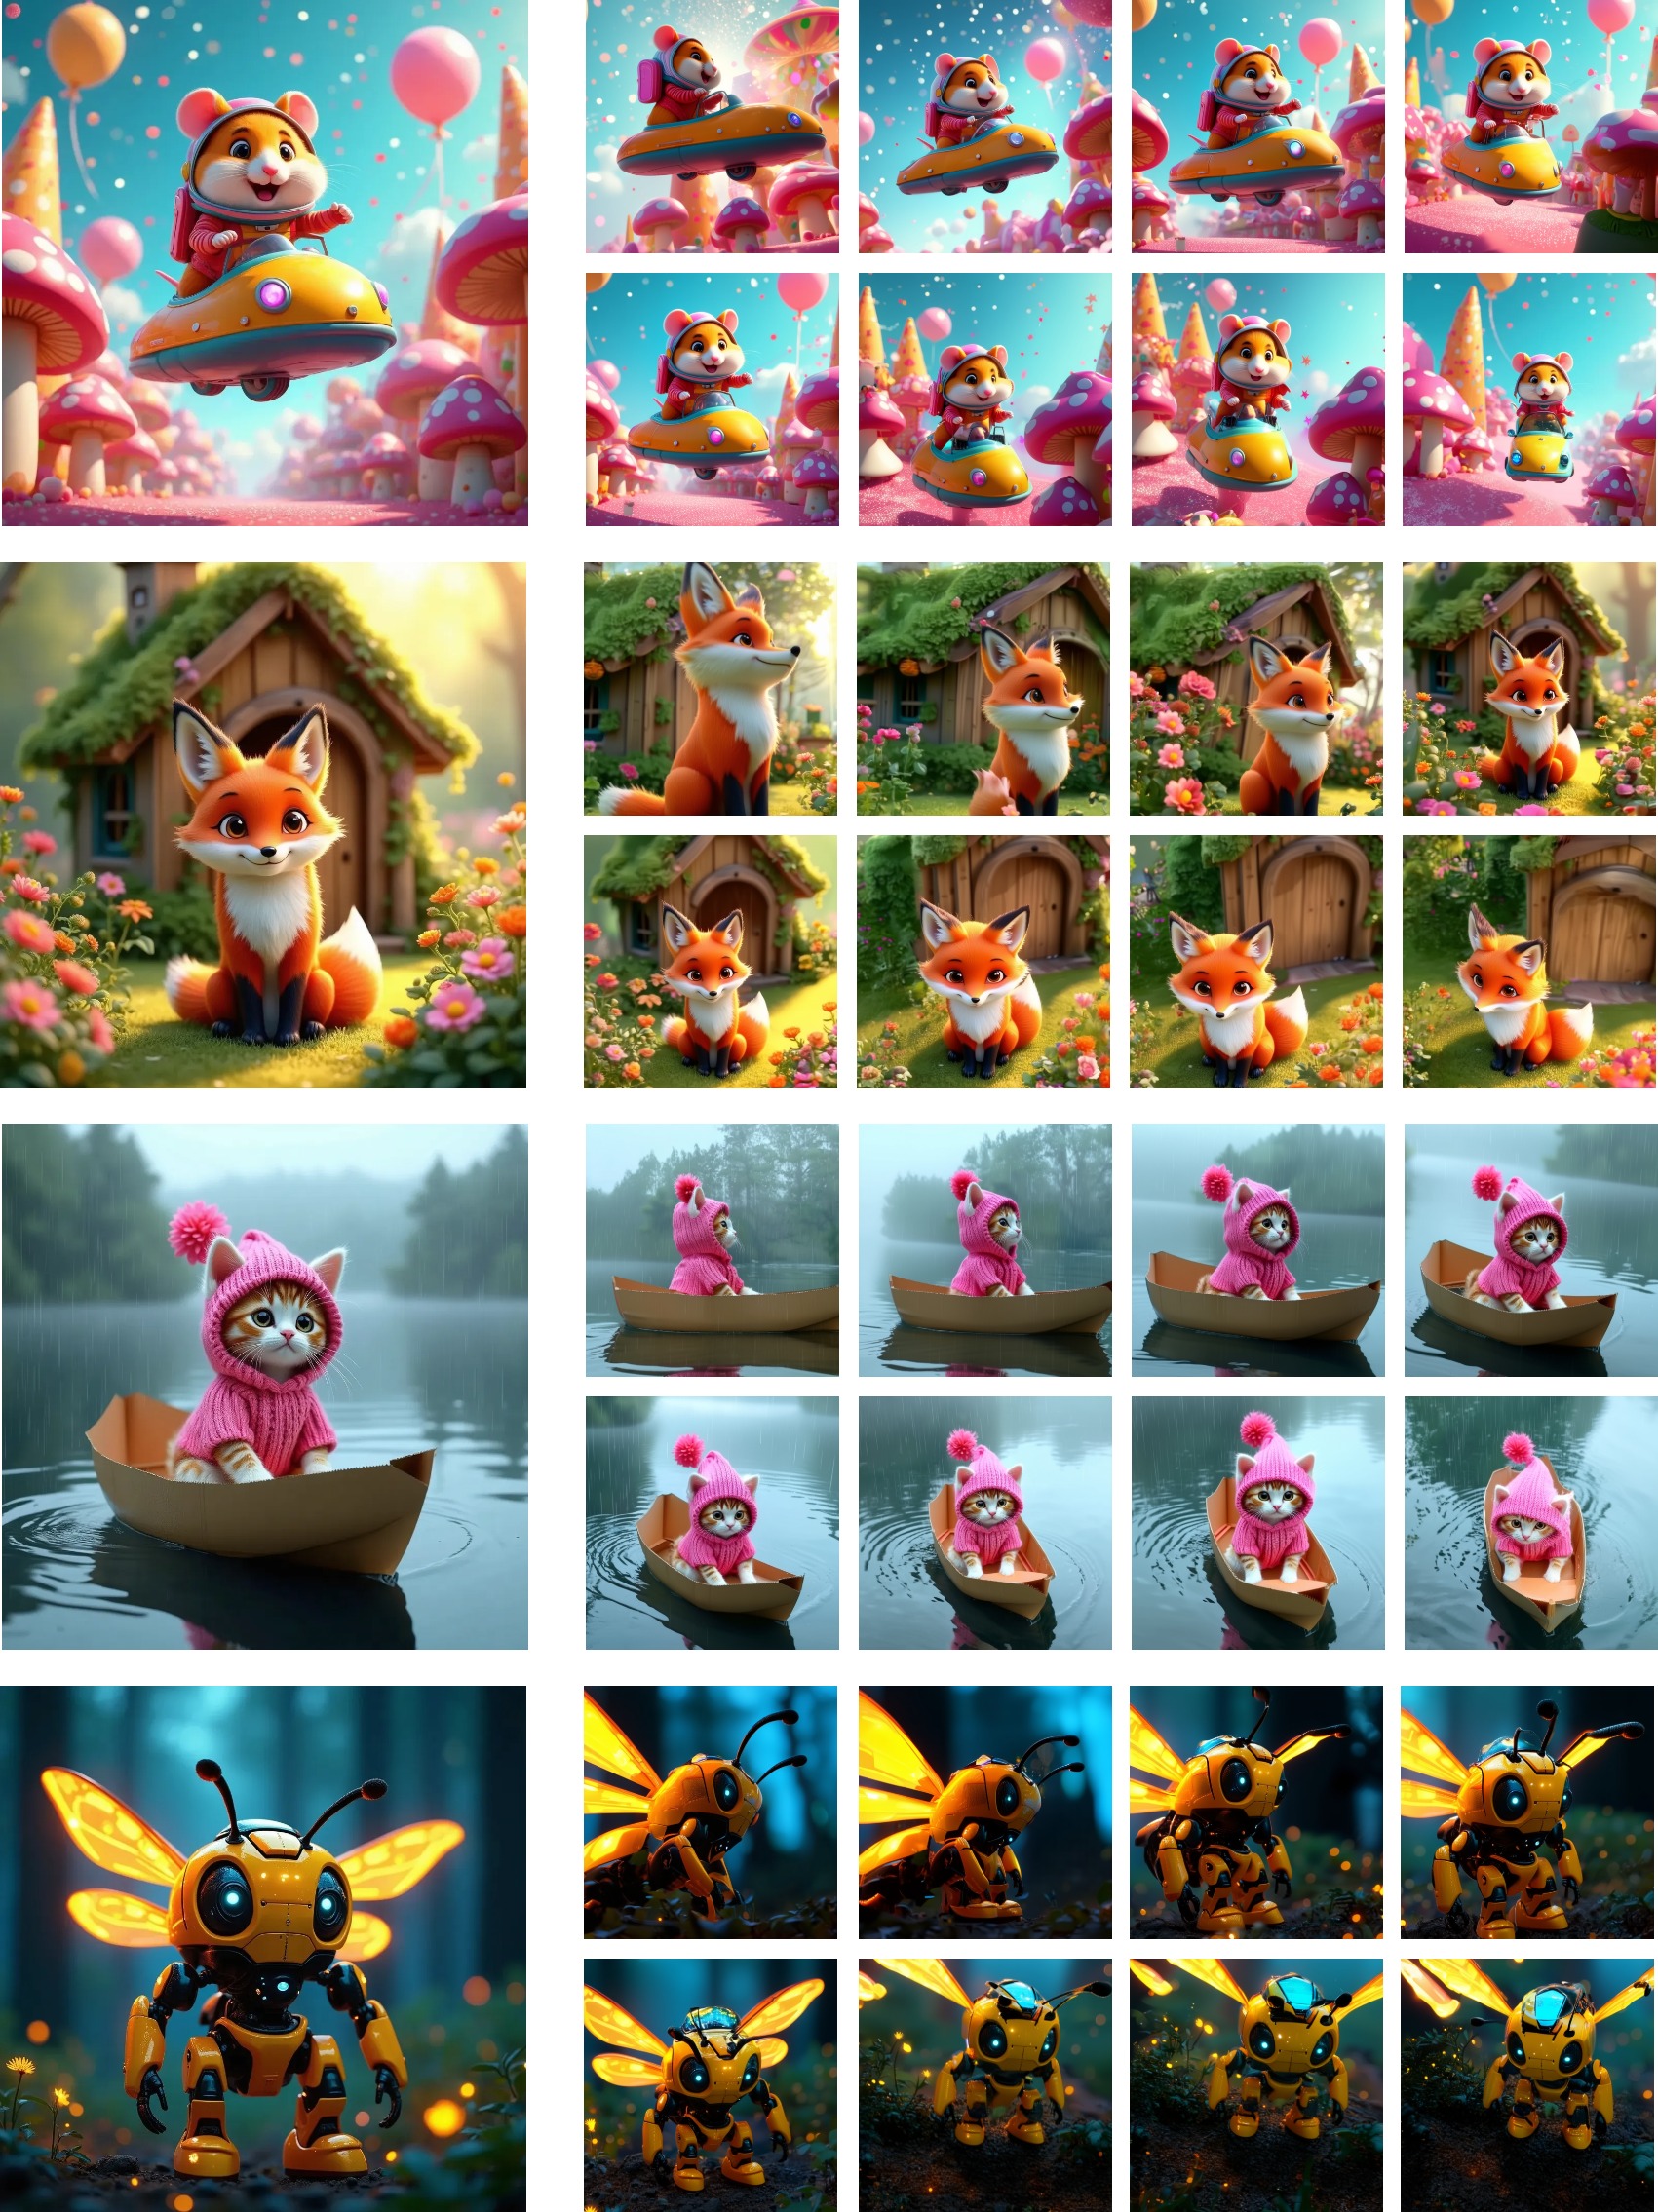
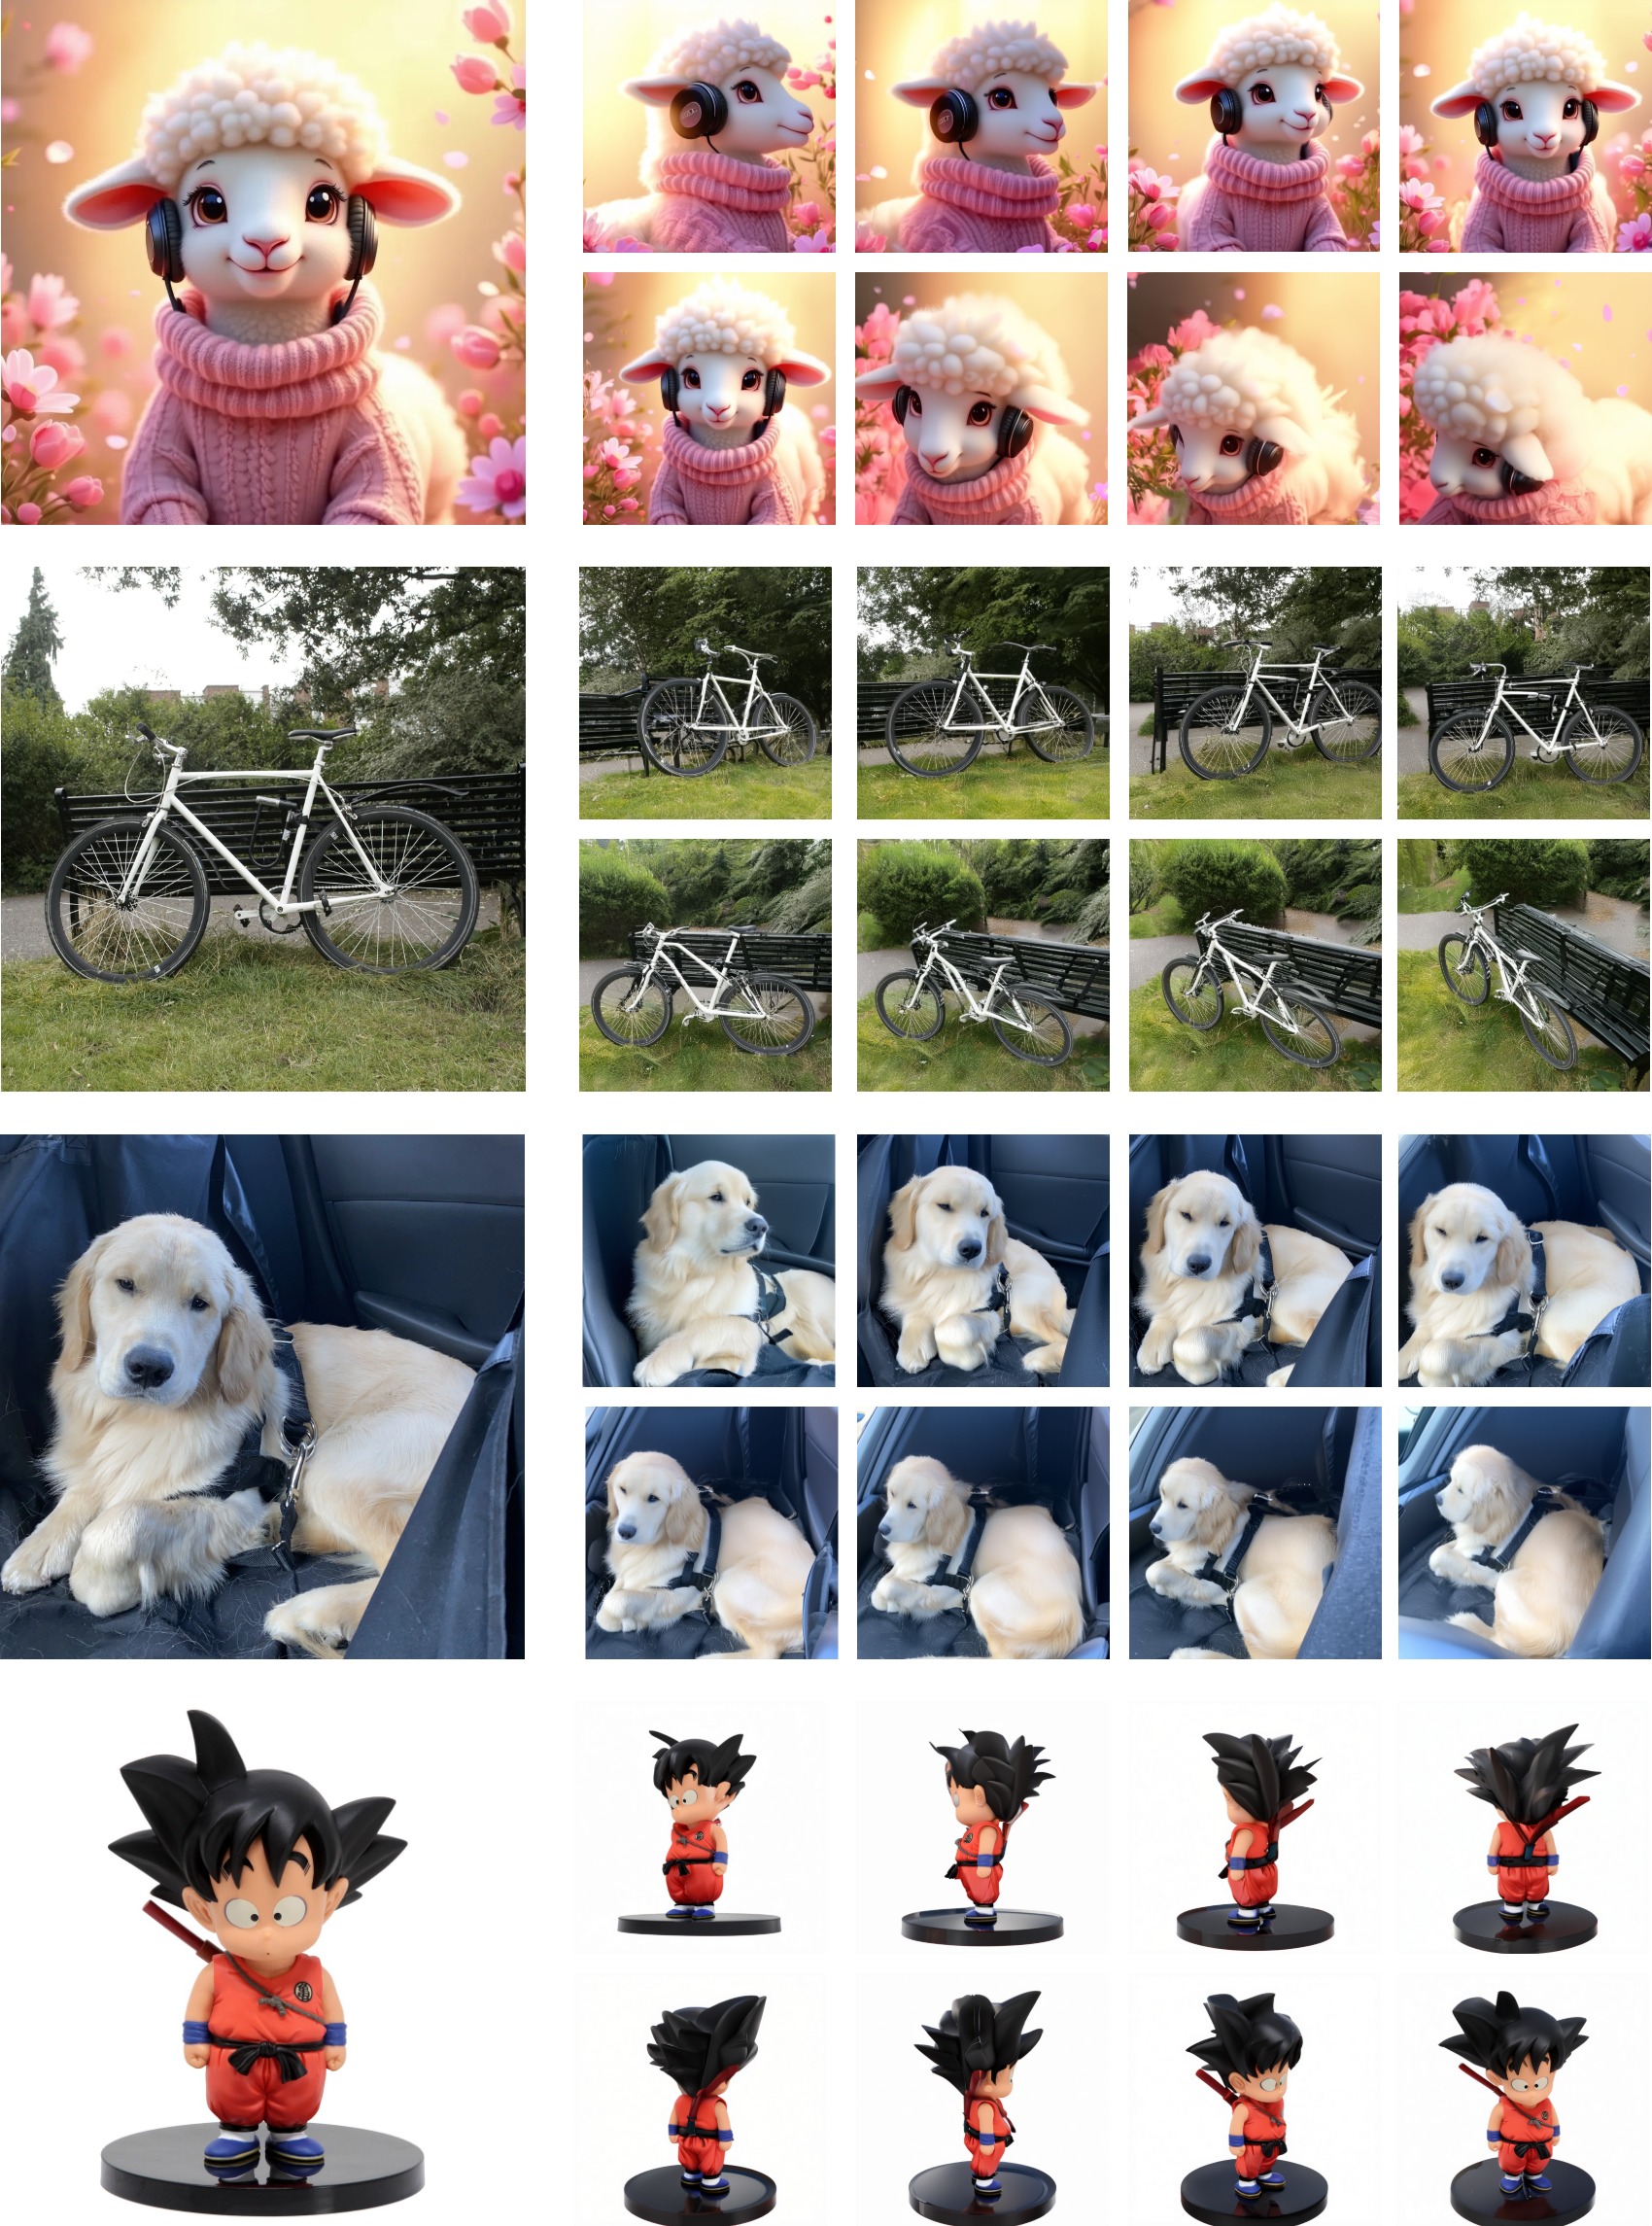
Single image to multiview:
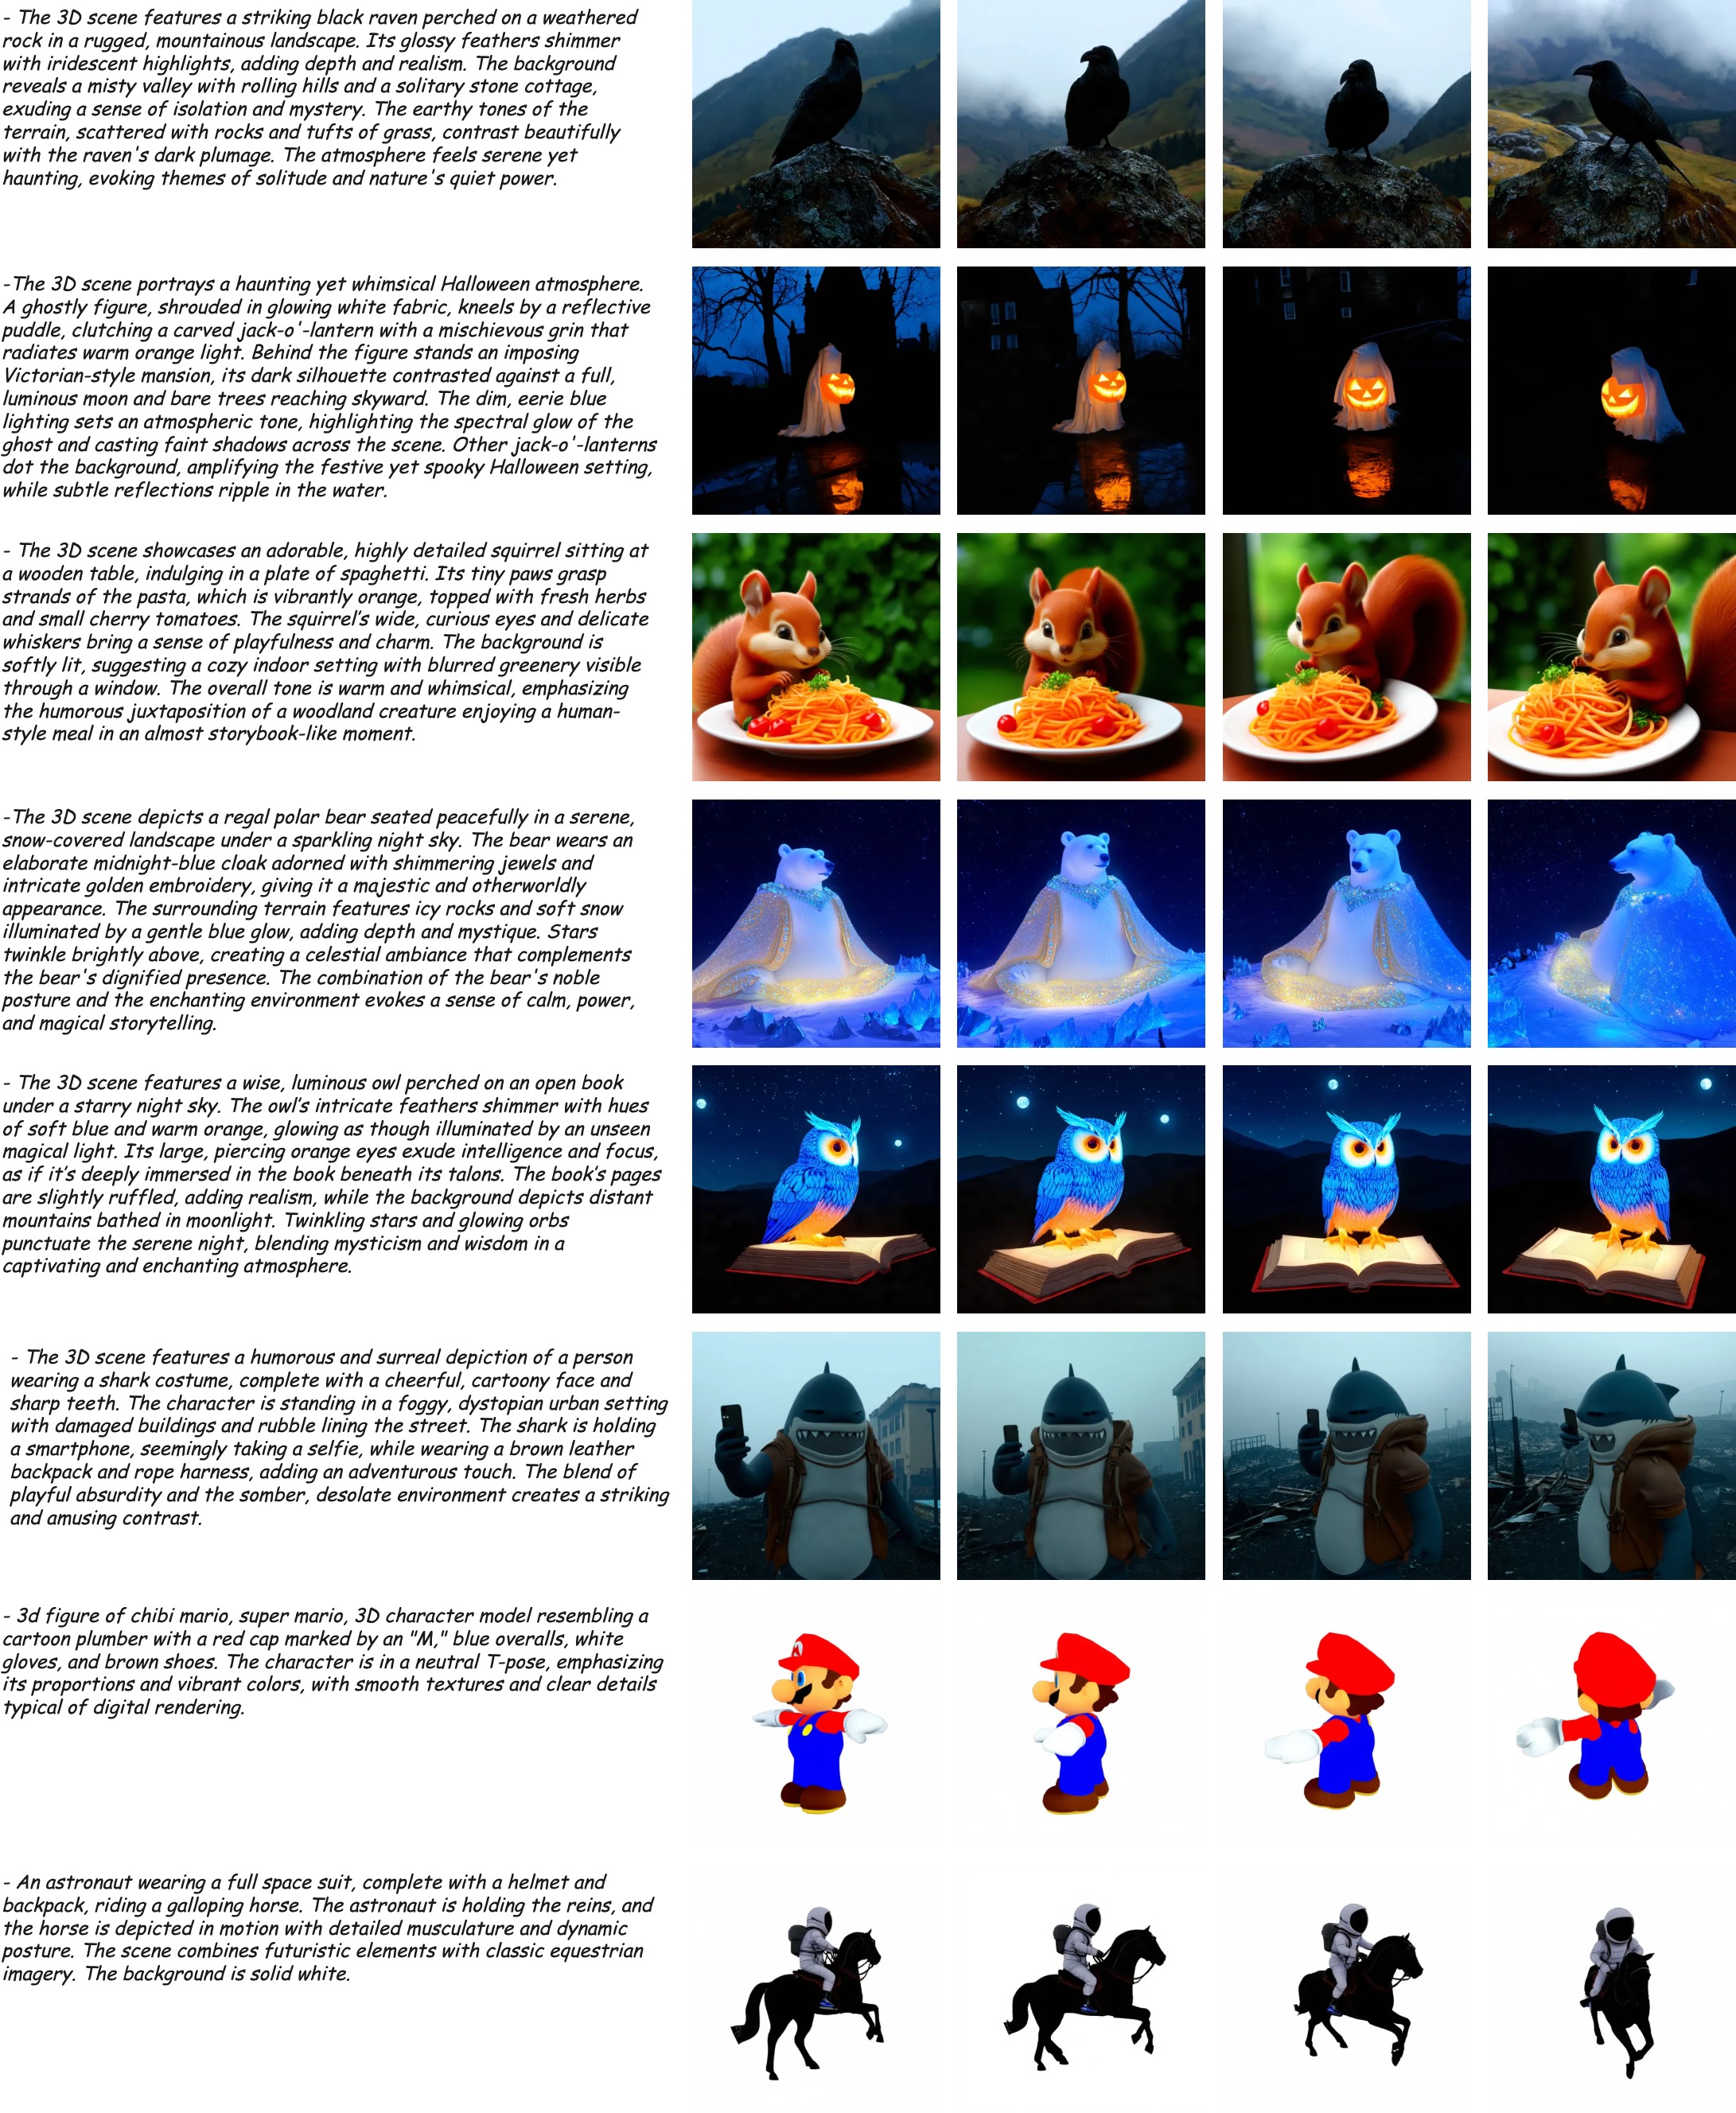
Text to multiview:
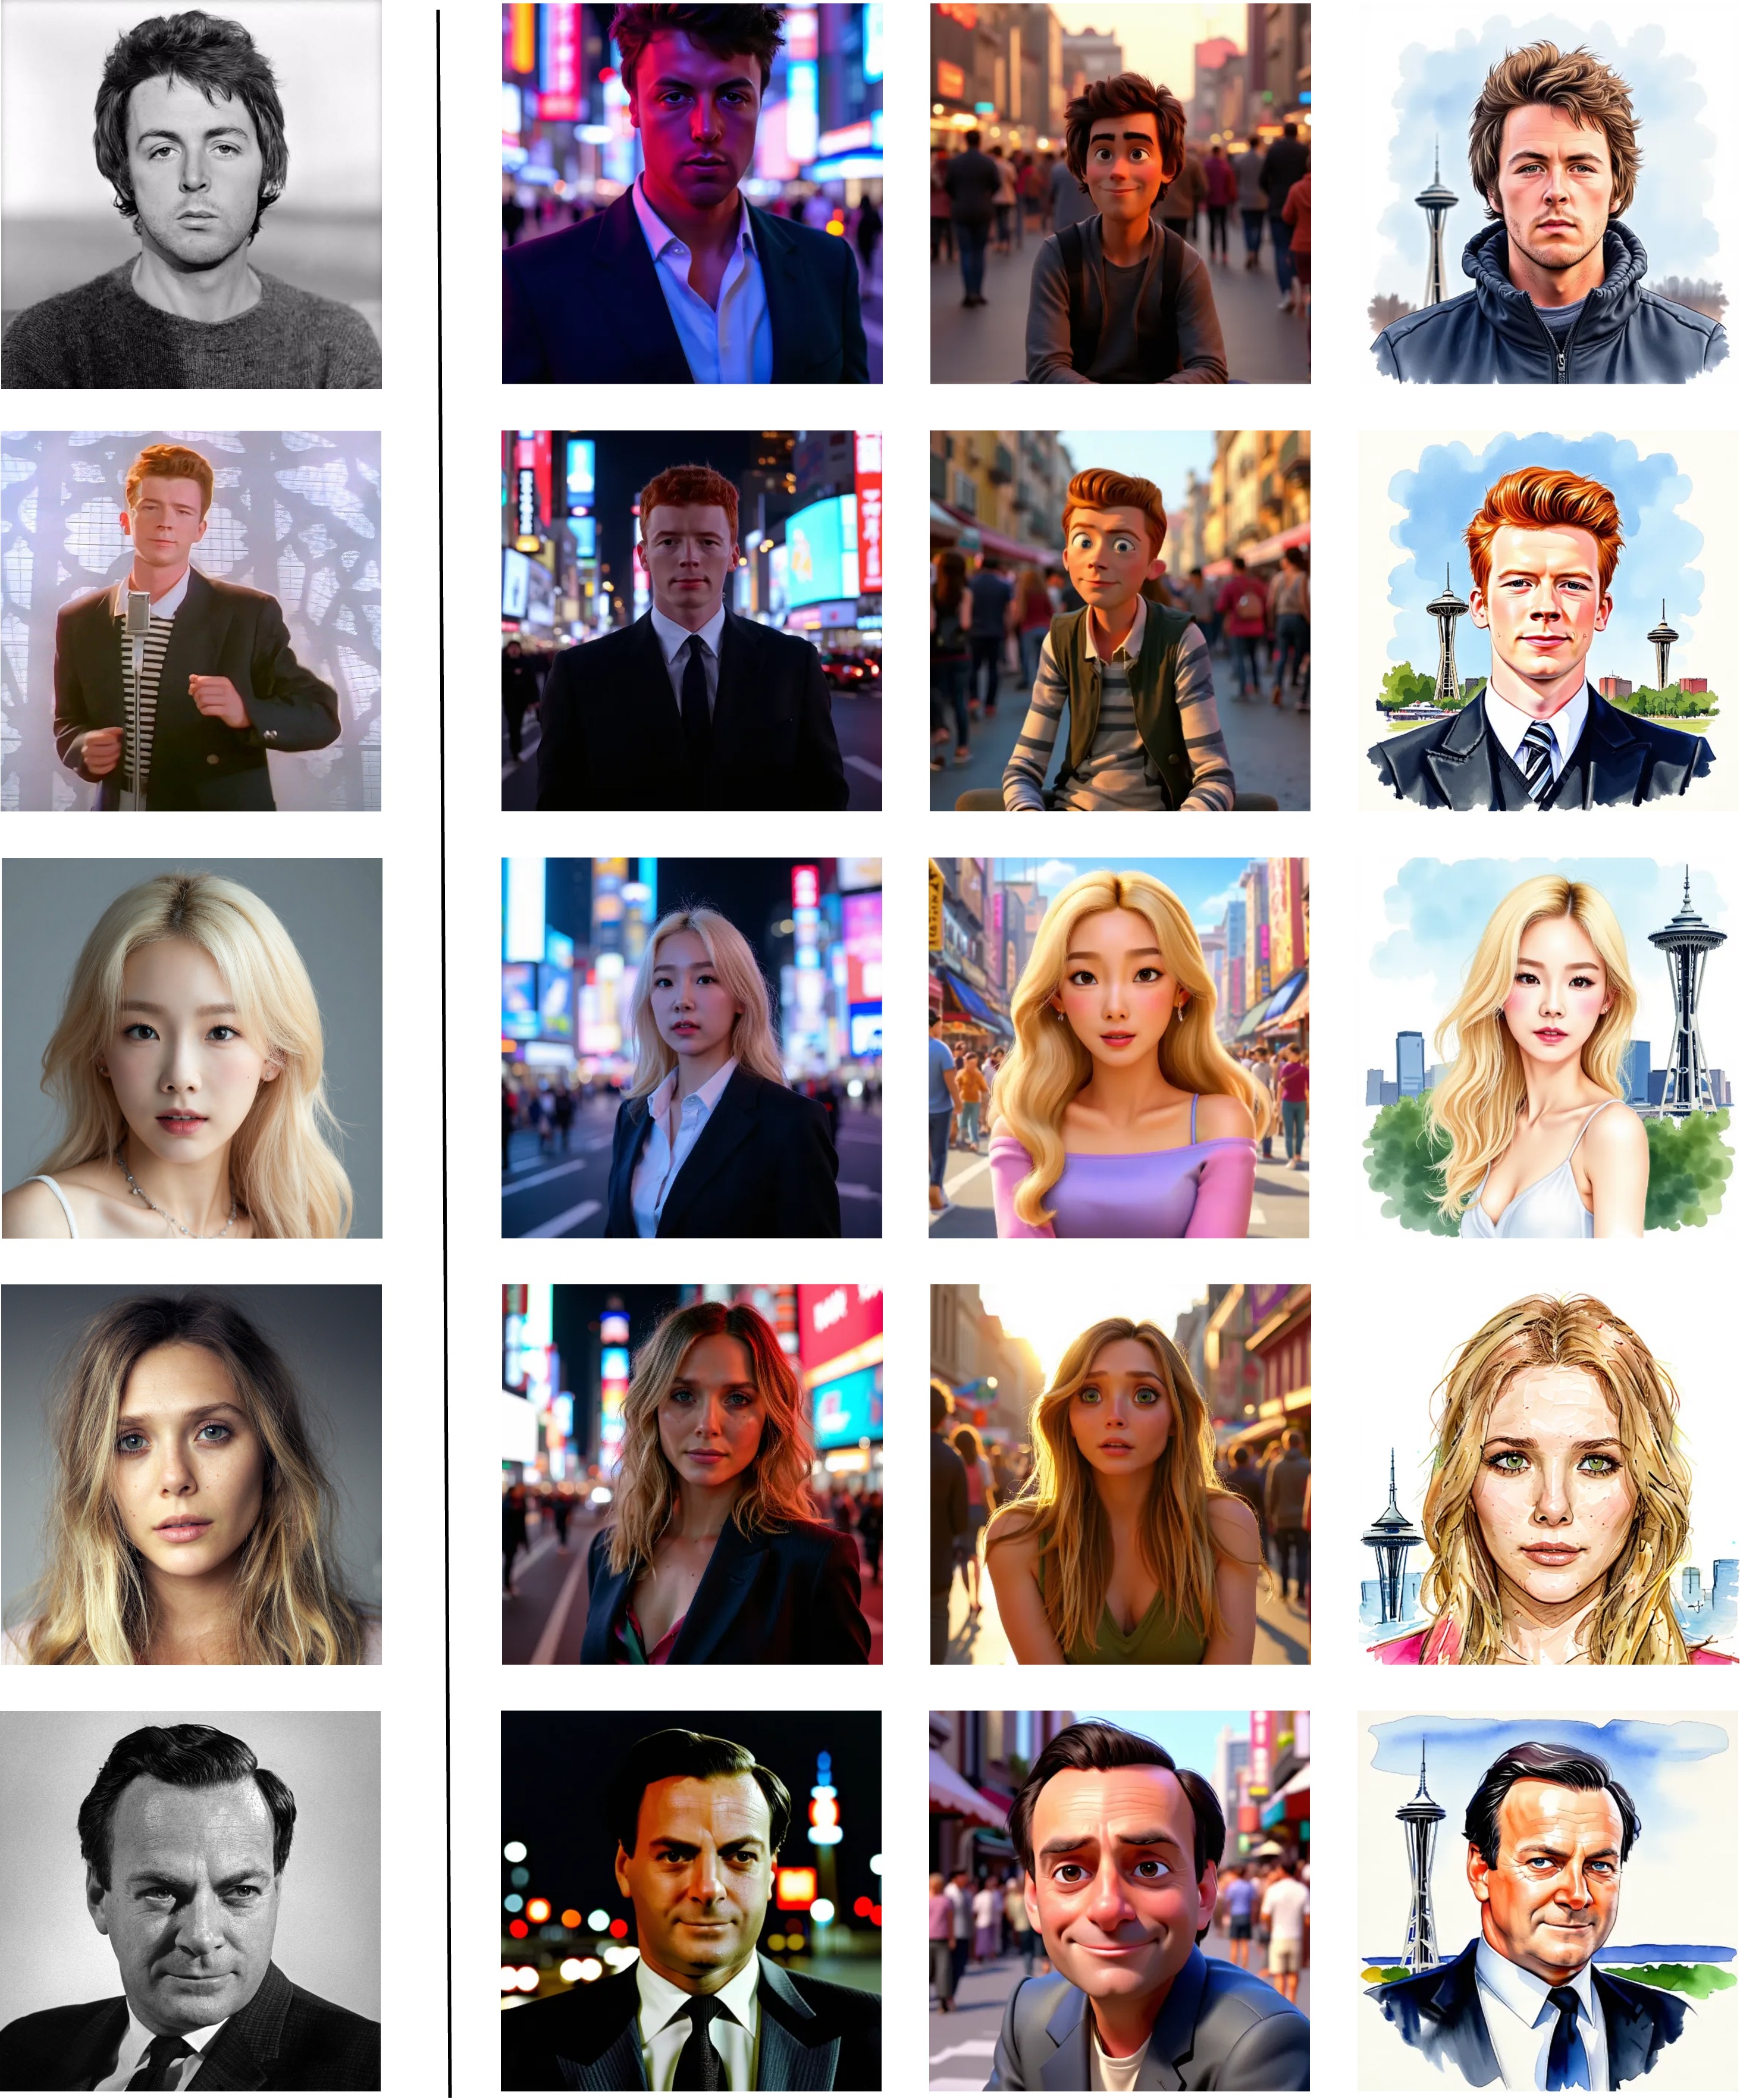
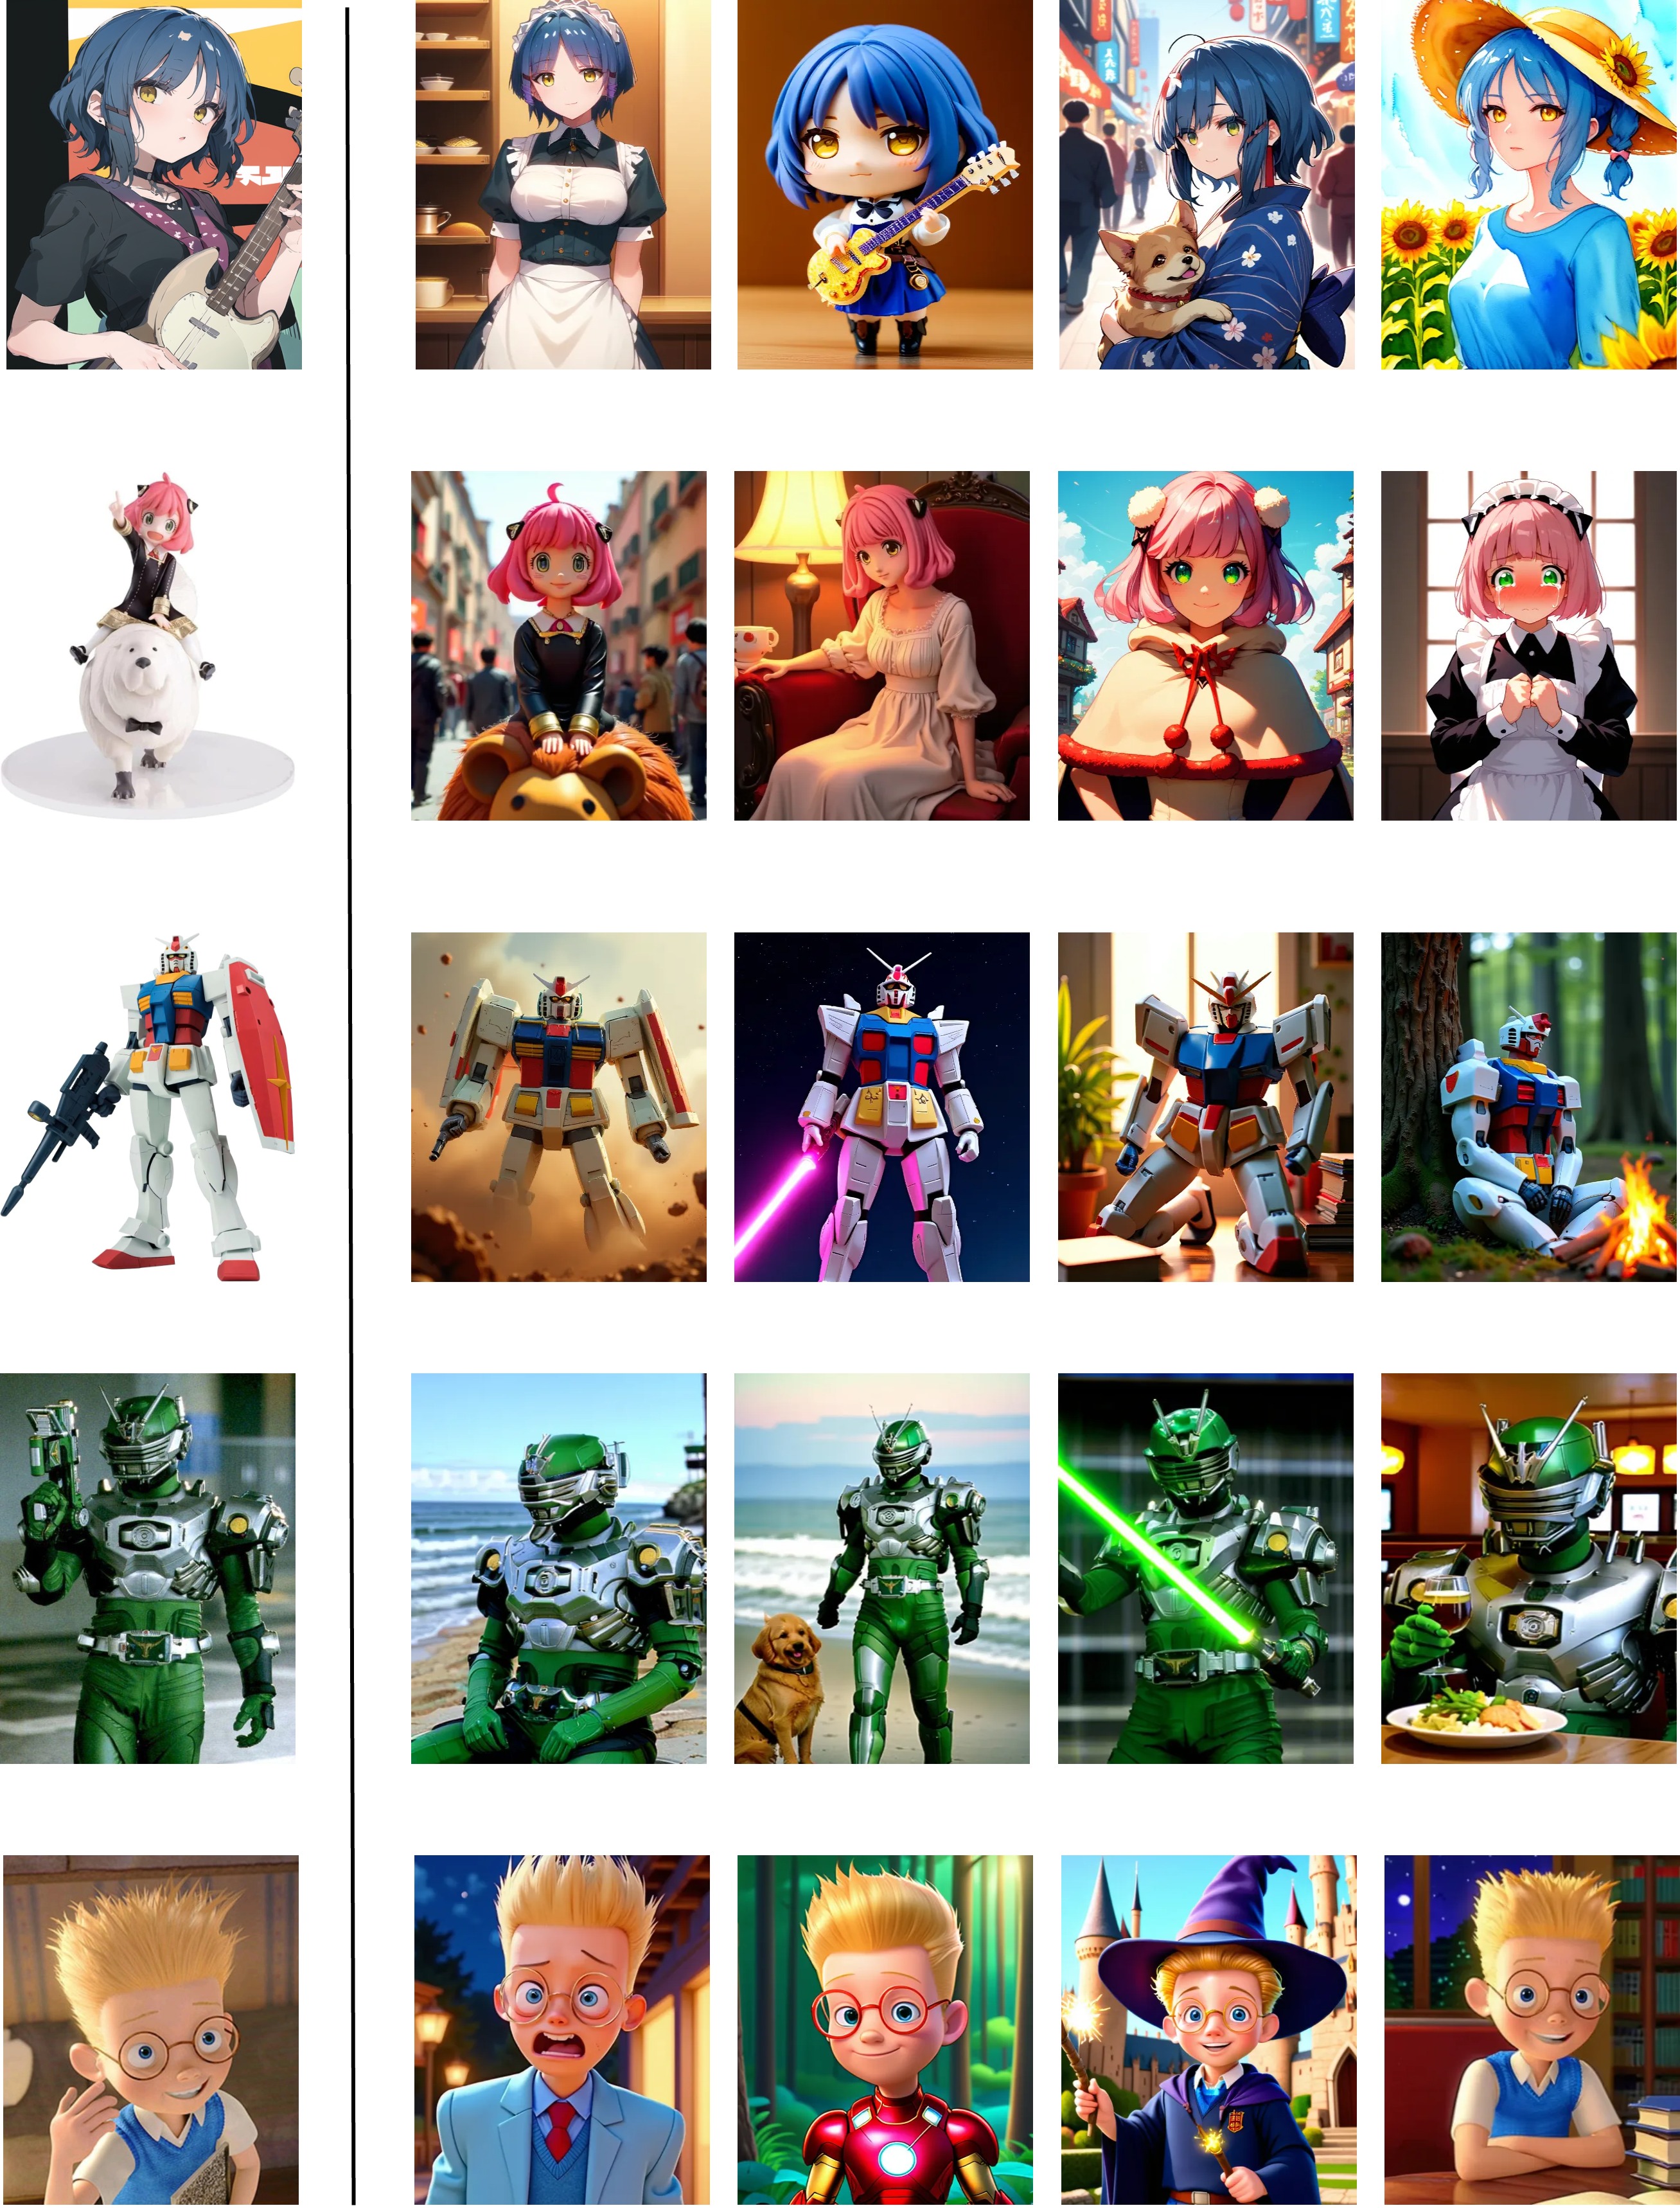
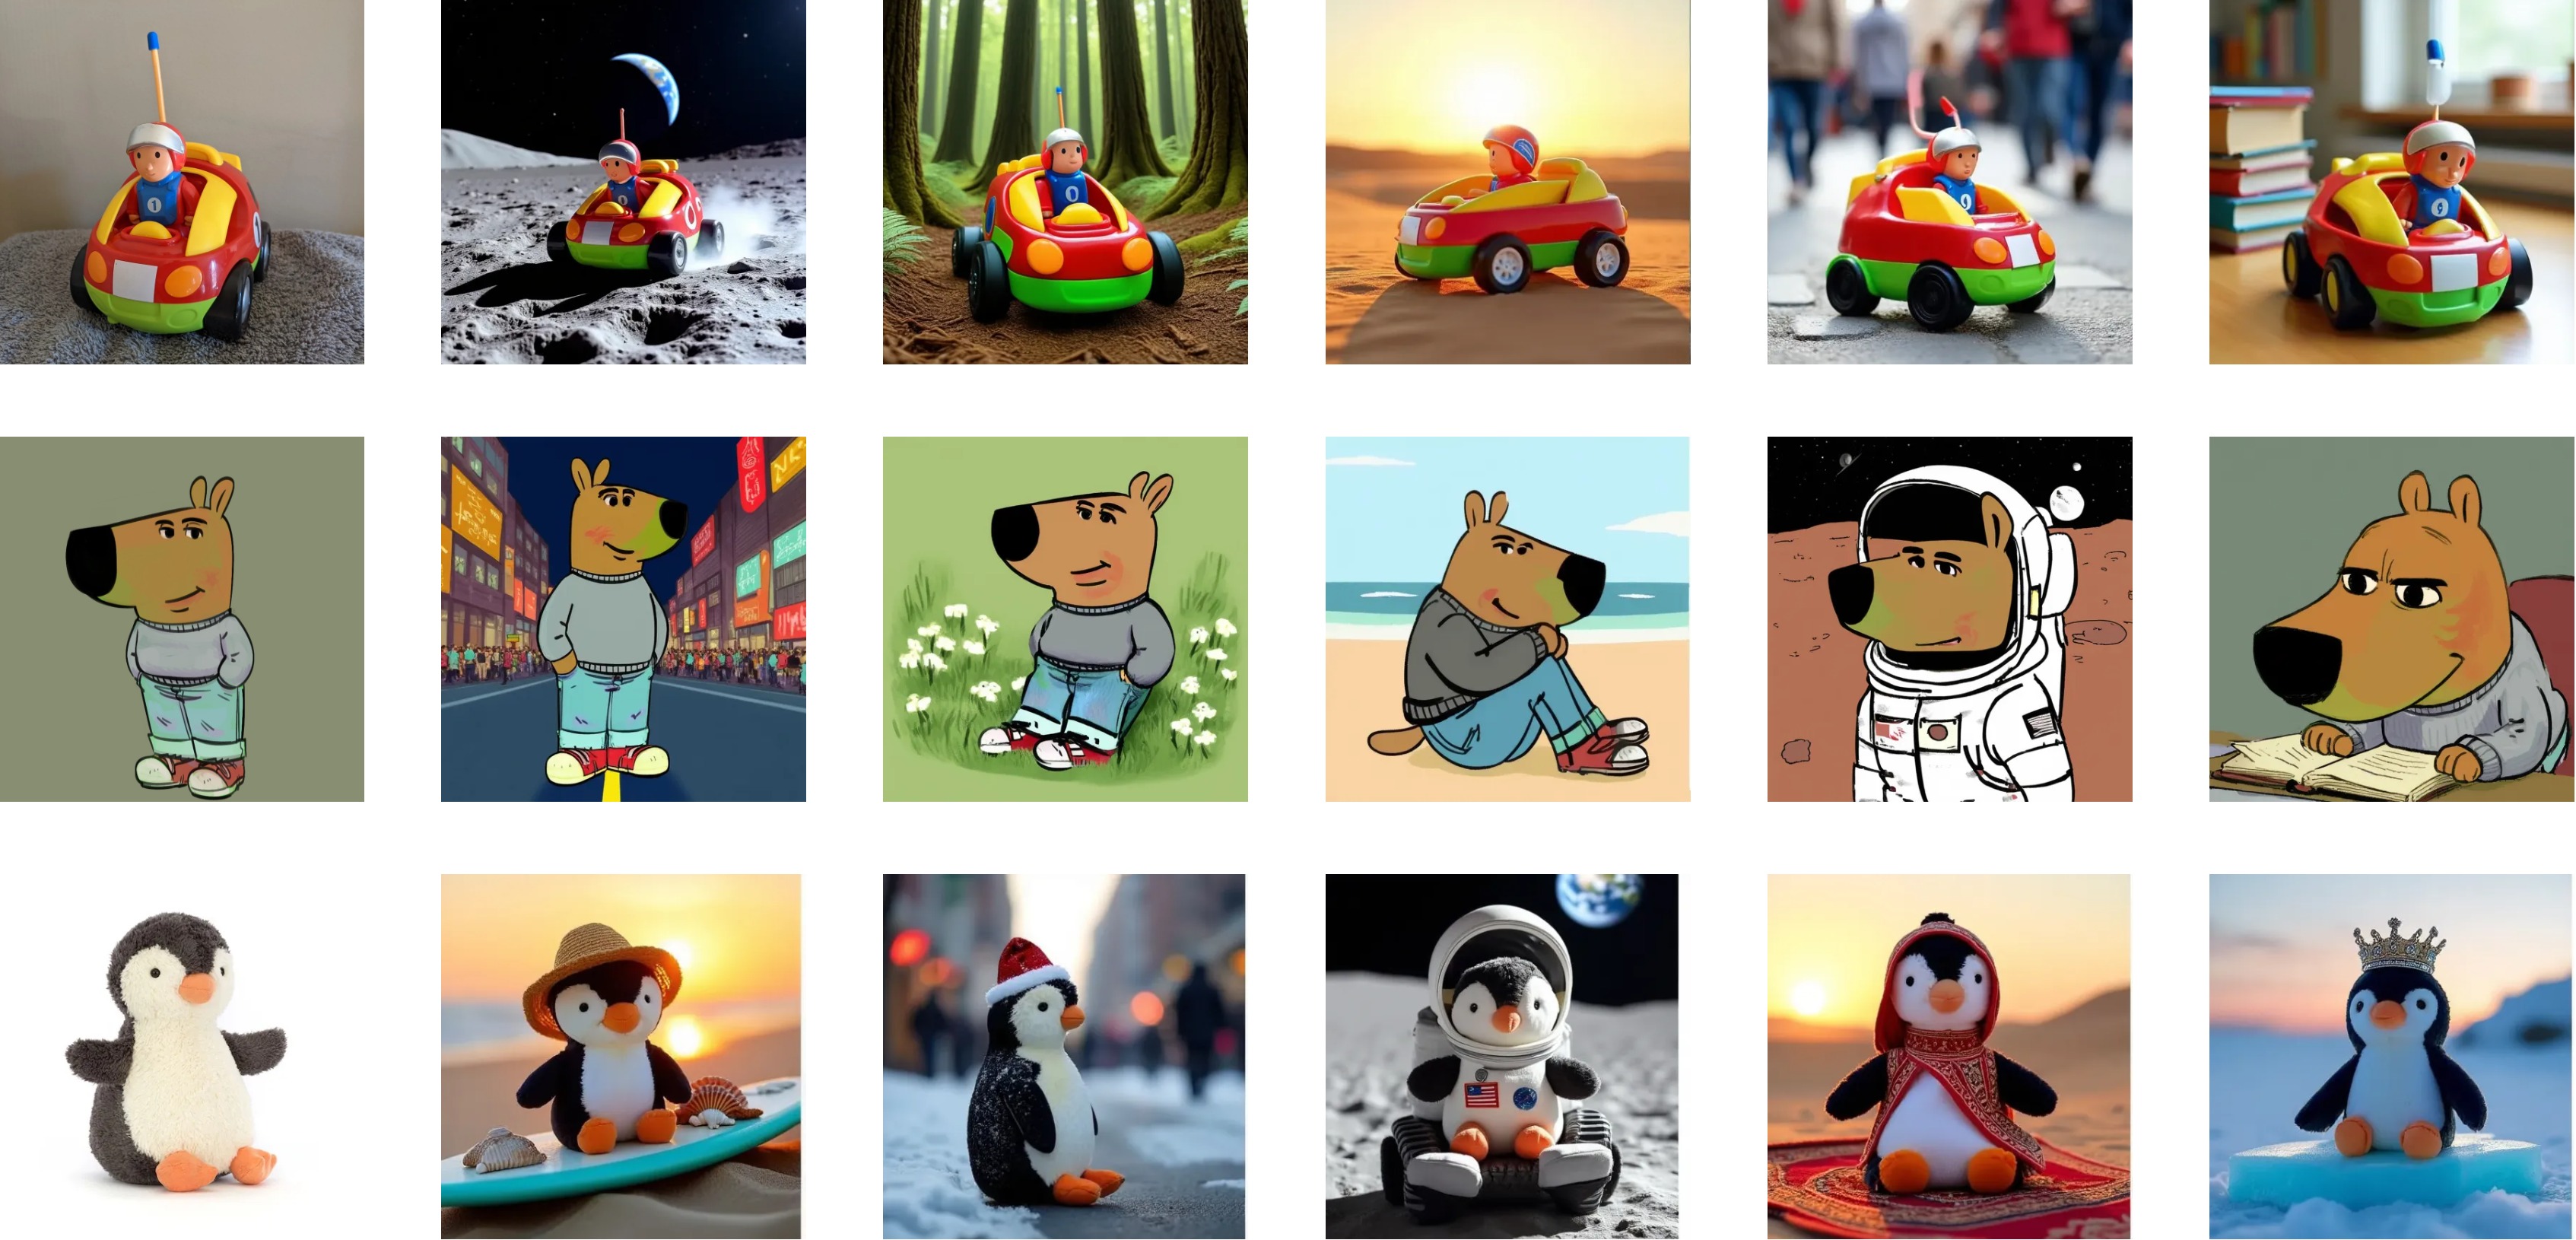
We finetuned the model on Subject-200K dataset (along with all other tasks) for additional 40k steps. The model is now capable of subject-driven generation.
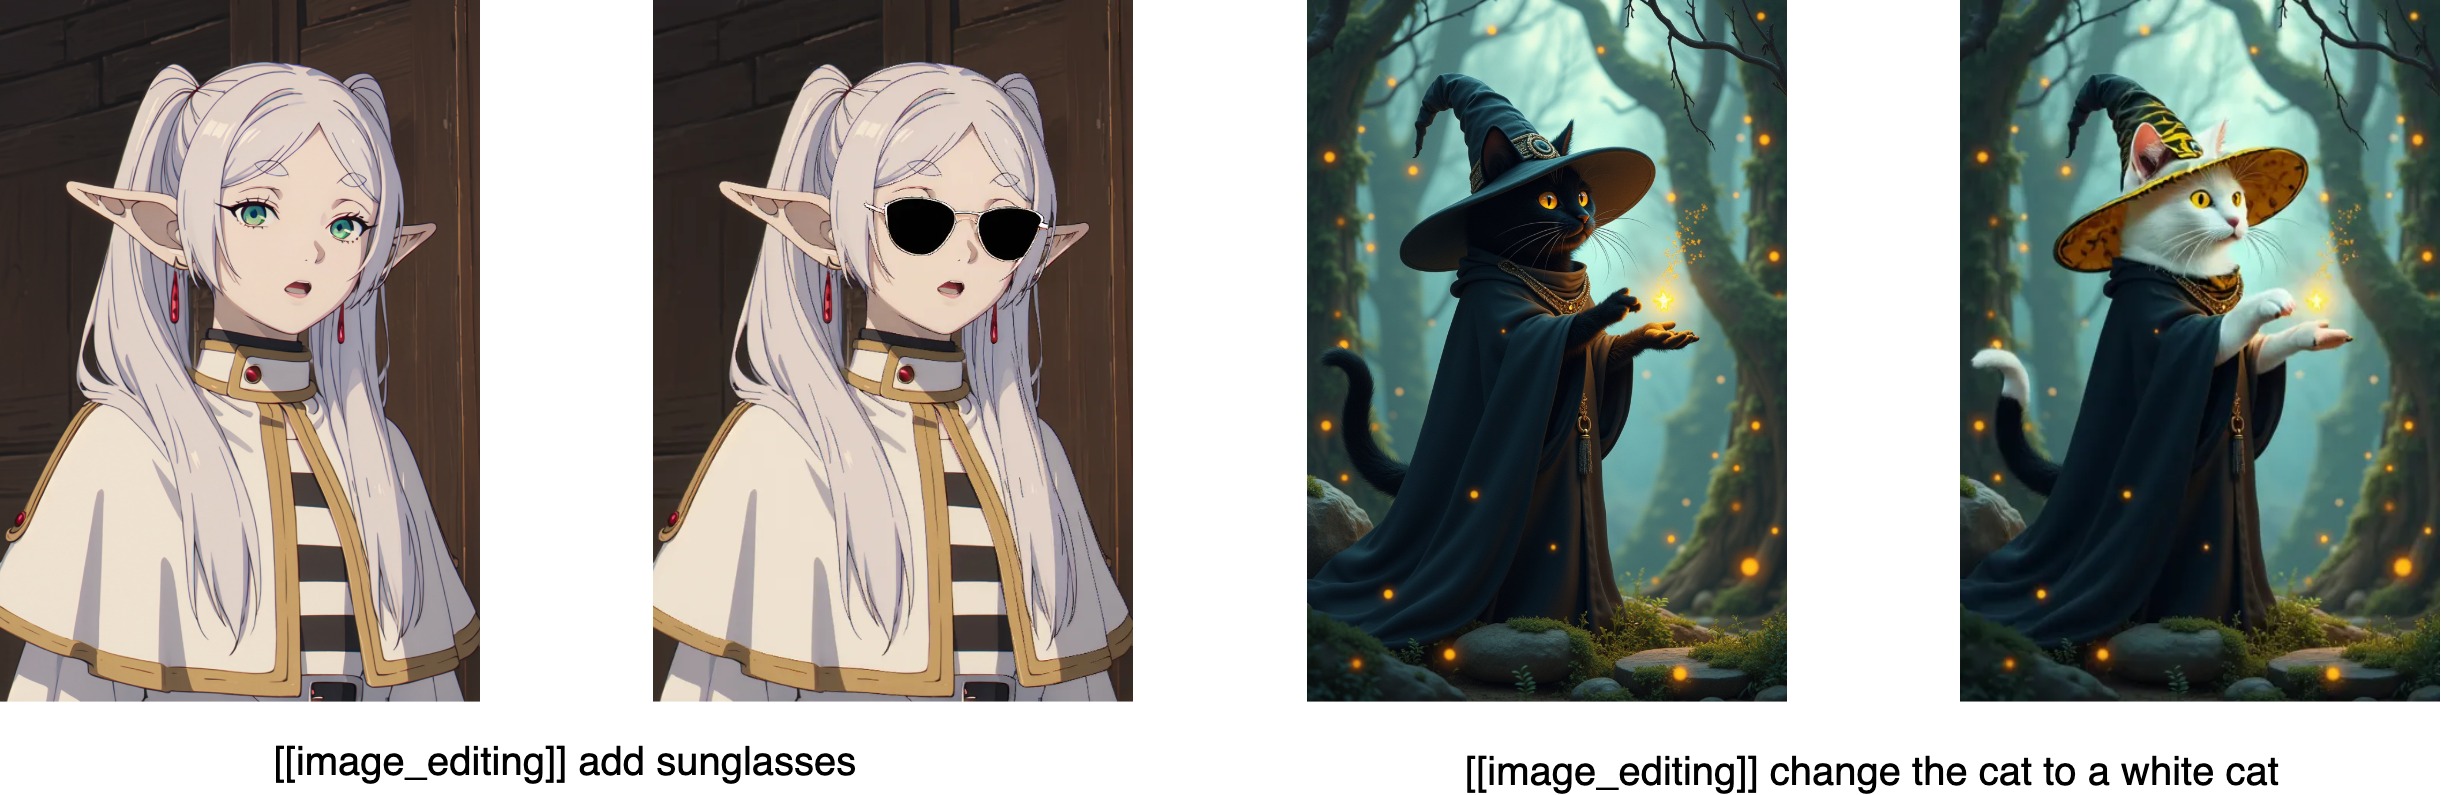
We finetuned the model on OmniEdit dataset for additional 30K steps.
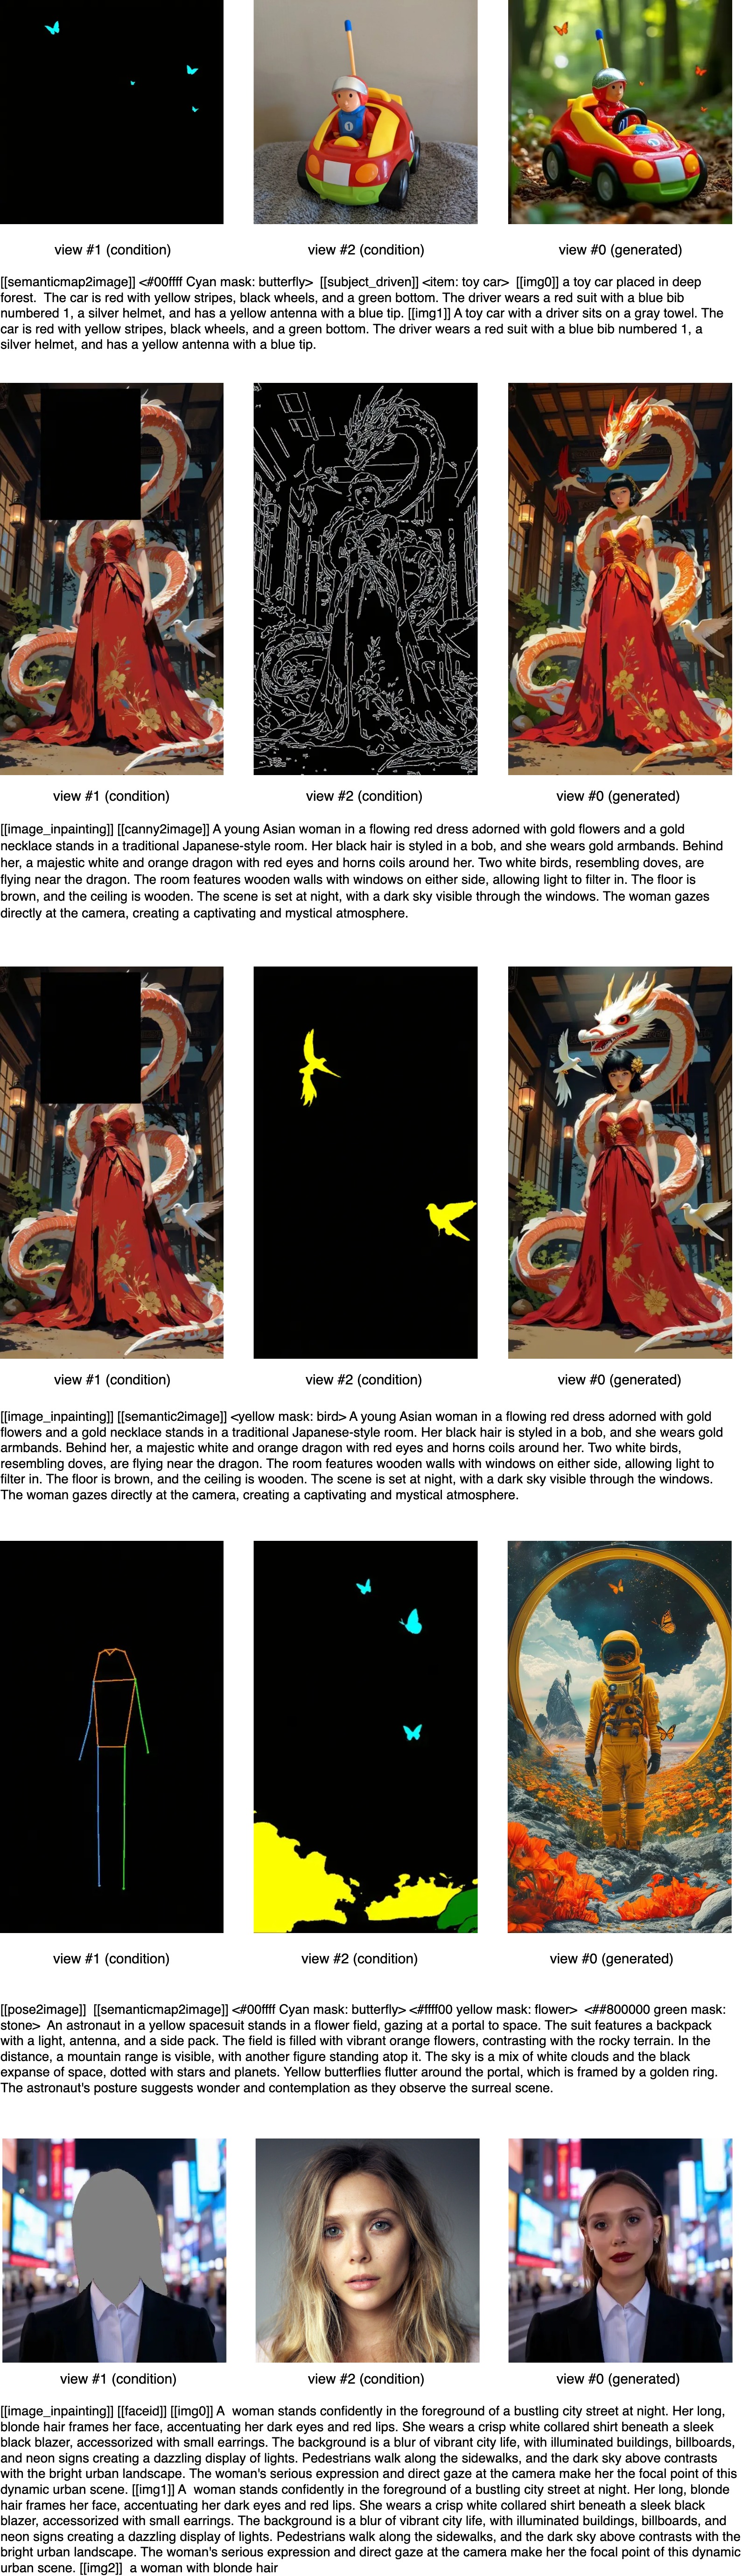
We found that the model can handle multiple tasks in a zero-shot setting by combining condition images and task tokens without any fine-tuning, as shown in the examples below. However, its performance on these combined tasks might not be robust, and the model’s behavior may change if the order of task tokens or captions is altered. For example, when using both image inpainting and ID customization together, the target prompt and the caption of the masked image must be identical. If you plan to use such combinations, we recommend fine-tuning the model on these tasks to achieve better performance and simpler usage.
The model is trained on several non-commercially licensed datasets (e.g., DL3DV, Unsplash), thus, model weights are released under a CC BY-NC license as described in LICENSE.
@misc{le2024diffusiongenerate,
      title={One Diffusion to Generate Them All},
      author={Duong H. Le and Tuan Pham and Sangho Lee and Christopher Clark and Aniruddha Kembhavi and Stephan Mandt and Ranjay Krishna and Jiasen Lu},
      year={2024},
      eprint={2411.16318},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2411.16318},
}
 →
 →
 →
 →
 →
 →