1
 →

A hierarchical inference engine for frontier MoE models: hot experts on the GPU (CUDA, Vulkan), warm ones in RAM, cold ones streamed from NVMe. Written in C, runs on the hardware you already own.
JustVugg/colibri is an open-source project on GitHub, mainly written in C. A hierarchical inference engine for frontier MoE models: hot experts on the GPU (CUDA, Vulkan), warm ones in RAM, cold ones streamed from NVMe. It currently holds 47,146 stars and 5,453 forks with 170 open issues, and was last pushed on 2026-11-03 (repository created 2026-07-01).
AI Homed tracks it on the Today's Trending board, currently at rank #6 with 803 new stars today.
Website · Discord · English · 简体中文 · 繁體中文 · Italiano · 日本語 · Bahasa Indonesia · Português (Brasil)
Tiny engine, immense model. colibri runs very large open models on the machine you already have. A mixture-of-experts model of hundreds of billions of parameters uses only a small part of itself for each token, so colibri keeps that part in RAM and reads the rest, the experts, from the disk when the model asks for them. Pure C, one file per model family, no GPU required.
Thirteen engines run today. Ten are for language models: GLM-5.2/5.3 (which also runs Mistral-Large-4), GLM-5.3-Flash, Inkling, Kimi K3, DeepSeek V4 Flash, DeepSeek V4.1 Flash, MiMo-V2.6 Flash (and Pro), Qwen3.8-Flash-Next, Qwen3.6 (which also runs Qwen3-Coder, the dense Qwen3.8-27B, Flint, Muse Spark Open and LFM3-VL) and OLMoE. One draws pictures: Qwen-Image-2.1. Two answer decisions: Laya and GLiNER2.5-Decide, with a third decision model, Clef, on the Qwen3.6 engine. The language models also run from the GGUF files already published, read as they are (GGUF), on the CPU, on any GPU through Vulkan and on NVIDIA cards through CUDA. Which one for my machine
$ ./coli chat
  colibri v2.1.0 · GLM-5.2 · 744B MoE · int4 · streaming CPU
  ✓ ready in 32s · resident 9.9 GB
  › ciao!
  ◆ Ciao! Come posso aiutarti oggi?

colibri is free and open source. If it has earned a place on your machine, a coffee helps pay for the next engine and the next speedup.
You need a computer with 8 GB of RAM at the very least (16 GB or more is better), 22 GB free on the disk for the smallest model, and an internet connection. A graphics card is optional.
Windows
1. On this page click Code, then Download ZIP, and unzip it.
2. Double-click START-HERE.bat in the unzipped folder. If Python is
missing, it offers to install it for you.
Linux (Ubuntu and Debian; other distributions have the same packages under their own names)
sudo apt install git python3 build-essential
git clone https://github.com/JustVugg/colibri
cd colibri
./start-here.sh
macOS (with Homebrew)
xcode-select --install
brew install libomp git python
git clone https://github.com/JustVugg/colibri
cd colibri
./start-here.sh
You answer one question, which model, and Enter takes the recommendation. Then the setup:
1. looks at your machine: RAM, free disk, CPU and GPUs; 2. recommends a model that fits: the part of the model that always stays in RAM, plus a minimum cache of experts, must fit in your RAM, and the download on your disk; 3. gets the engine: it builds it for your machine when a compiler is there, otherwise it downloads the prebuilt one, which runs on the CPU and, on Linux and Windows, on a Vulkan GPU too. It builds for your GPU when that pays: CUDA for an NVIDIA card on Linux when the CUDA toolkit is installed, otherwise Vulkan. On a discrete GPU it always does; on an integrated GPU, which shares the CPU's RAM, only for the models measured faster there (Qwen3.6, Qwen3-Coder and Qwen3.8-Flash-Next). If a package is missing it prints the exact command to install it and carries on with the CPU; run the setup again afterwards and it rebuilds for the GPU; 4. downloads the model with progress and resume: stop it whenever you like, run it again and it continues where it stopped; 5. starts colibri and opens the dashboard in your browser, and prints the addresses other apps can use:
Starting colibri
  Browser:             http://127.0.0.1:8000/
  OpenAI base URL:     http://127.0.0.1:8000/v1
  Anthropic base URL:  http://127.0.0.1:8000
  stop: press Ctrl+C here (or close this window)
Next time, run START-HERE.bat or ./start-here.sh again: colibri starts
straight away, with no download and no build. c/coli status shows what is
installed and whether it runs, c/coli stop stops it (c\coli.cmd status and
c\coli.cmd stop on Windows).
Options go after ./start-here.sh or START-HERE.bat:
| Option | What it does |
|---|---|
| --list | every model against this machine, and why one does not fit |
| --model ID | install that model (the ids are in the tables below) |
| --yes | no questions: take the recommendation |
| --dir DIR | put the models on another disk (default ~/colibri-models) |
| --backend vulkan, cuda or cpu | choose the engine build yourself; --no-gpu is --backend cpu |
| --model-dir DIR | use a model you already downloaded |
| --reconfigure | choose another model |
What each step does, in detail: docs/quickstart.md.
| What you see | What to do |
|---|---|
| it stopped during the download | run the same command again: it resumes from the bytes already on disk |
| to use the GPU through ..., first run: | run that command, then the setup again: it rebuilds for the GPU and does not download again |
| the ... build failed, for example Unsupported gpu architecture when the installed CUDA toolkit no longer supports the card | the setup checks the toolkit against the card first and picks Vulkan by itself, saying why; if a build still fails it offers the next one (Vulkan, then the CPU). ./start-here.sh --backend vulkan forces Vulkan; --no-gpu stays on the CPU |
| needs N GB free for the download | --dir with a folder on a bigger disk |
| on WSL, the model folder is under /mnt/c | keep it on the Linux disk (the default, ~/colibri-models): /mnt/c is many times slower |
| you updated the checkout (git pull) | run ./start-here.sh again: it rebuilds the engine when the sources changed, then starts it |
| anything else | c/coli logs -n 50 shows the log of a server started in the background (one started in the foreground prints to its own terminal) and c/coli logs --install the setup's; open an issue with the last lines the setup printed |
If you use an AI coding assistant, it can do all of this for you. Ask it:
Set up colibri on this machine following docs/AI_SETUP.md from https://github.com/JustVugg/colibri
docs/AI_SETUP.md gives the assistant every step as a
command with a machine-readable result, and tells it to ask you before it
downloads a model or installs a system package. Assistants that speak the Model
Context Protocol can use colibri's MCP server instead: coli mcp offers tools
to detect the hardware, recommend a model, install, start, stop and check it
(docs/MCP_SERVER.md).
To choose each step yourself (a prebuilt release or a source build, any model
from the tables below, then coli chat, coli web or coli serve), see
Install by hand, or the
Quick Start guide for every platform step by step.
A mixture-of-experts model is huge on disk and small per token. GLM-5.2 has 744B parameters, uses about 40B for each token, and only about 11 GB of those change from one token to the next: the routed experts.
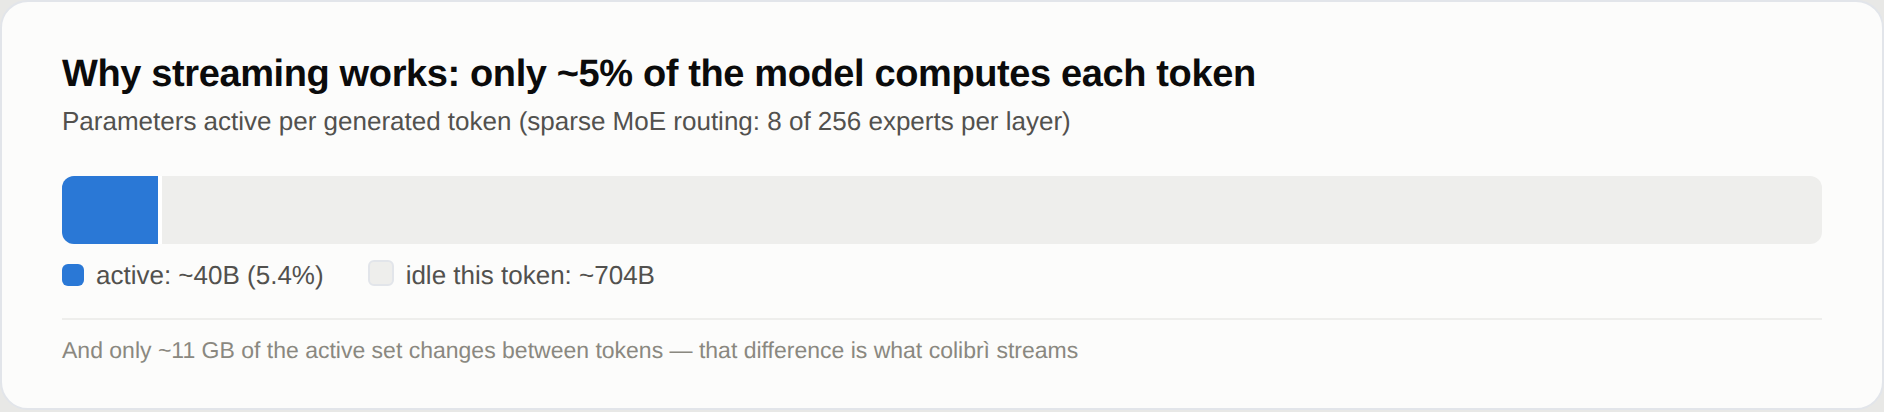
So the model does not have to fit in fast memory; it has to be placed. The dense part (attention, shared experts, embeddings) stays in RAM. The routed experts stay on the disk and are read when the router asks for them, through a cache that learns which experts your work uses. A GPU, when there is one, holds the hottest experts and the dense layers. Where a weight sits changes how fast the answer comes, not which weights or which router decisions produce it.
Why: to run models of this size on hardware people already own, to watch them work (the dashboard shows every expert as it fires), and to keep the engine small enough that anyone can measure it and make it faster. colibri is also an open research platform: an optimisation earns its place with a reproducible end-to-end measurement, and the default policy never silently changes model precision or router semantics. Less fast memory may cost speed; it must not quietly redefine the model. How it works has the details.
The setup recommends the most capable model that runs from RAM on your
machine, and lists the larger ones that stream from the disk right below it.
./start-here.sh --list shows them all against your machine. The tables follow
the setup's own catalog (c/setup_catalog.py); the
downloads are the sizes Hugging Face lists for each repository.
Small models, which run from RAM
| Model | --model | Download | RAM | GPU | Measured |
|---|---|---|---|---|---|
| Qwen3.6-35B-A3B: chat with thinking and tools | qwen36-35b | 23 GB | 10 / 20 GB | CUDA, Vulkan (integrated too) | 6.0 tok/s on the CPU, 9.9 with Vulkan on the integrated GPU (A); 30.0 with CUDA (C) |
| Qwen3-Coder-30B-A3B: code and tool calls, no thinking | qwen3-coder-30b | 19 GB | 8 / 18 GB | CUDA, Vulkan (integrated too) | 8.5-9.6 tok/s with every expert in RAM, 5.1 with 32 per layer (A, CPU) |
| Qwen-Image-2.1: text to picture, non-commercial licence | qwen-image-2.1 | 33 GB | 12 / 18 GB | Vulkan | one 768x512 picture in 2 min 40 s (8 Zen 4 cores, CPU) |
Large models, whose experts stream from the disk (the disk sets the speed: a fast NVMe drive helps most)
| Model | --model | Download | RAM | GPU | Measured |
|---|---|---|---|---|---|
| DeepSeek V4 Flash REAP 150B: 132 of the 256 experts | deepseek-v4-flash-reap | 85 GB | 16 / 32 GB | CUDA, Vulkan | |
| DeepSeek V4 Flash (284B): tools | deepseek-v4-flash | 167 GB | 16 / 32 GB | CUDA, Vulkan | 0.93 tok/s with 32 GB (Ryzen 7 5800X), 1.24 with 63 GB (Ryzen 9 5950X), CPU only; 1.5-1.6 with CUDA (RTX 5080, 32 GB, two NVMe) |
| MiMo-V2.6 Flash (309B): vision and tools | mimo-v2.6-flash | 172 GB | 32 / 52 GB | Vulkan | 2.34-3.37 tok/s (A, CPU) |
| Qwen3.8-Flash-Next (125B + 51B n-gram): vision and tools | qwen38-flash-next | 186 GB | 24 / 32 GB | CUDA, Vulkan (integrated too) | 1.91-2.56 tok/s with 32-96 experts per layer; 3.99 with the optional int4 experts (A, CPU) |
| GLM-5.2 (744B): the reference model, with the MTP head | glm-5.2 | 429 GB | 16 / 24 GB | CUDA, Vulkan | 0.05-0.1 tok/s cold on a 25 GB laptop; 1.83 on a 128 GB Ryzen AI Max+ 395; 9.0-9.2 on 6x RTX 5090 |
| GLM-5.3 (744B): the same engine, no MTP head | glm-5.3 | 419 GB | 16 / 24 GB | CUDA, Vulkan | |
| Inkling (975B): int4 experts, bf16 dense weights | inkling | 514 GB | 120 / 128 GB as downloaded; 25 GB after a dense conversion | CUDA, Vulkan | 0.25 tok/s (Ryzen 9 7900, 187 GB, RTX A6000) |
| MiMo-V2.6 Pro (1.02T): vision and tools | mimo-v2.6-pro | 564 GB | 54 / 64 GB | Vulkan | 0.66-0.79 tok/s (A, CPU) |
| Kimi K3 (2.8T): the largest | kimi-k3 | 1.56 TB | 32 / 64 GB | CUDA, Vulkan | about 9.4 s per token, experts read at 6.3 GB/s |
By hand: a conversion or preparation step after the download
| Model | Download, then on disk | RAM | GPU | Measured | |---|---|---|---|---| | OLMoE (7B): small, to learn the tools on | 14 GB, 7 GB after conversion to int8 | 8 GB | Vulkan | 22-23 tok/s (A, CPU) | | Qwen3.8-27B (dense): text and images | 56 GB, 51 GB after conversion | 20 GB in int4, 30 GB in int8 | Vulkan | 3.45 tok/s in int4, 2.1 in int8 (16-thread CPU server) | | GLM-5.3-Flash (321B): vision and tools | 328 GB, converted shard by shard to 195 GB | 25 GB | CUDA, Vulkan | about 20 s per token warm, 44 s cold (6 cores, 25 GB, ordinary disk) | | DeepSeek V4.1 Flash (552B): vision and tools, no conversion but a one-off preparation | 510 GB | about 18 GB plus the expert cache (24.8 GB peak with 8 per layer) | Vulkan | 0.21-0.24 tok/s (16-thread CPU server holding 68% of the experts) |
From a GGUF: the published files, read as they are
./coli import takes the first file of a GGUF (its other parts next to it) and writes a model
directory beside it; --model that directory, as any other (gguf.md). Nothing is
converted or quantized again: the blocks run as the file holds them, from IQ1_S to Q8_0, F16, BF16
and MXFP4. The engines of every chat model above read GGUFs too
(the architectures); these four models come as GGUFs:
| Model | GGUF | GPU | Measured | |---|---|---|---| | Mistral-Large-4 (1T, 52B active): text, pictures, reasoning and tools | unsloth, UD-IQ1_S 233 GB | CUDA, Vulkan | 1.34-1.36 tok/s with CUDA, 1.16-1.17 with Vulkan (D) | | Muse Spark Open (816B, 42B active): text and tools, under Meta's licence agreement | unsloth, UD-IQ1_S 176 GB to UD-Q4_K_XL 505 GB | CUDA, Vulkan | 1.55-1.58 tok/s with Vulkan, 1.34-1.40 with CUDA, 0.83-0.89 on the CPU (D) | | Flint (40B, 2.5B active): text and tools, Apache 2.0 | unsloth, UD-IQ1_M 11.4 GB to BF16 79.6 GB | CUDA, Vulkan | UD-Q4_K_XL: 77.4 tok/s with CUDA, 77.7 with Vulkan, 15.8 on the CPU (D) | | LFM3-VL-2B: text, pictures and tools, LFM Open License | LiquidAI, QAD-Q4_0 to BF16 (or the checkpoint, converted) | CUDA, Vulkan | Q4_K_M: 235.1 tok/s with CUDA, 214.1 with Vulkan, 34.5 on the CPU (D) |
The larger models of the tables above from their GGUFs, on the same machine: Benchmarks.
Decision models (they answer System One questions, they do not chat)
| Model | Download, then on disk | RAM | GPU | Measured | |---|---|---|---|---| | Laya (Convai Innovations), English | 0.85 GB | 1.7 GB | CPU, CUDA | 219 ms for one question, 882 ms for three (B); twelve in 0.69 s with CUDA, 11.4-13.0 s on the CPU (D) | | GLiNER2.5-Decide (fastino), English | 1.95 GB | 1.9 GB | CPU, CUDA | 294 ms for one question, 897 ms for three (B, under load); twelve in 0.16-0.21 s with CUDA, 2.0-2.6 s on the CPU (D) | | Clef (Cloudflare): Qwen3.8-27B with a decision head, it also chats | 55 GB, 52 GB after conversion | 19 GB in int4 to 55 GB in f16 | CPU | 20.4 s per request in int8 (A) |
The machines: A a Ryzen 7 PRO 8700GE desktop (8 cores, 61-64 GB DDR5, NVMe, integrated Radeon 780M); B an i7-1355U laptop; C an RTX 3070 8 GB in a Threadripper 3945WX box, with the dense layers and the DeltaNet layers on the card (per-row int4 container); D an i5-13500 with 62 GB of RAM, an RTX PRO 4000 Blackwell SFF (24 GB) and two NVMe drives in an md array: the machine of the benchmark tables. Each number comes from its model's page in docs/ or from the benchmark tables, with the exact settings.
Each family has its page: qwen36.md (Qwen3.6, Qwen3-Coder, Qwen3.8-27B, Flint, Muse Spark Open, LFM3-VL), mistral-large4.md, gguf.md, qwen38.md, deepseek-v4.md, deepseek-v41.md, mimo.md, glm53-flash.md, inkling.md, kimi_k3.md, qwen-image.md, laya.md, gliner_decide.md, clef.md, and GLM-5.2 in the Quick Start. Checkpoints with the same architecture as a supported one, such as KAT-Coder v2.5 on the Qwen3.6 engine, run unchanged.
Every engine runs on the CPU with nothing else installed. A GPU is a faster place to keep weights, not a requirement: for the large models the disk sets the speed, for the small ones the RAM.
Every MoE engine can use any GPU with a Vulkan 1.2 driver (AMD, Intel, NVIDIA, integrated or discrete) in two ways:
Measured on the integrated Radeon 780M of machine A, the model files dropped from the page cache before each run, 100 tokens decoded (vulkan.md):
| | CPU | Vulkan, expert tier | Vulkan, tier and dense chain | |---|---|---|---| | Qwen3.6-35B-A3B, decode | 6.0 tok/s | 8.0 tok/s | 9.9 tok/s | | Qwen3.6-35B-A3B, a 512-token prompt | 35.7 s | 12.2 s | 9.5 s | | Qwen3.8-Flash-Next (int4 experts), decode | 3.5 tok/s | 3.8 tok/s | 3.2 tok/s | | Qwen3.8-Flash-Next, a 512-token prompt | 43.6 s | 38.7 s | 30.1 s | | OLMoE, decode (warm) | 23.1 tok/s | 12.8 tok/s | 17.3 tok/s |
An integrated GPU shares the CPU's RAM. What it saves is the work and the disk
reads of the experts it holds, so it pays on a model like Qwen3.6, and a small
model whose experts already sit in RAM, like OLMoE, can lose. That is why the
setup turns Vulkan on for an integrated GPU only for Qwen3.6, Qwen3-Coder and
Qwen3.8-Flash-Next, and why each engine decides for itself whether to run the
dense chain there (Qwen3.6 yes, Qwen3.8 no). --backend vulkan asks for Vulkan
anyway.
Turning the GPU on or off. coli setup --backend vulkan uses the GPU for any
model, and coli setup --backend cpu (or --no-gpu) keeps everything on the
CPU. An engine built with Vulkan uses the GPU only with COLI_VULKAN=1 in the
environment of coli chat, serve or web (the setup sets it when it chose
Vulkan); without it, the engine runs on the CPU. With the GPU on, COLI_VK_CHAIN=0
keeps the expert tier and runs the dense layers on the CPU. On an integrated GPU,
try both: on a laptop with an Intel Iris Xe (Core i7-1355U), Qwen3.6 decoded
2.1 tok/s on the CPU, 1.7 to 1.9 with Vulkan, and 2.1 with the dense chain off.
On a discrete GPU the setup builds Vulkan for every engine (CUDA first, where the engine has it and the toolkit is installed), with the dense layers on the card. That is the case the design is for. On an RTX PRO 4000 (24 GB, machine D) Qwen3.6-35B-A3B decodes at 92.9 tok/s and reads a prompt at 2,076, OLMoE at 299.4 and 6,867 (the table). A model larger than the card keeps the experts the card cannot hold in a host pool in RAM, and in every step the CPU computes those while the card computes its own, in the same frame: Qwen3.8-Flash-Next IQ2_XS (68 GB) decodes at 50.6 tok/s there (vulkan.md). A user measured Qwen3.6 at 17 to 19 tok/s on a Tesla V100 16 GB (#1852). Numbers from your card are welcome.
Cards without Resizable BAR now work. Such a card (every Turing card, Ampere cards on their launch firmware, older AMD cards with the option off) lets the CPU write only about 256 MB of its memory directly; colibri now copies the weights in through a staging buffer, on its own. The path is tested by forcing it and by emulating the small window on three devices, and it costs nothing measurable on the 780M; it has not been measured on a card without Resizable BAR (vulkan.md).
CI checks every engine's Vulkan path against the CPU's tokens on a software driver. The GPU adds numbers in a different order, and keeps some activations in f32 where the CPU rounds them, so a long answer can drift from the CPU's by a word (vulkan.md).
The setup builds CUDA on Linux when the CUDA toolkit is installed, for the
engines that have a CUDA path: GLM-5.2/5.3 and Mistral-Large-4, GLM-5.3-Flash,
Inkling, Kimi K3, DeepSeek V4 Flash, DeepSeek V4.1 Flash, MiMo-V2.6,
Qwen3.8-Flash-Next, and Qwen3.6 with the models it runs; OLMoE and the decision
engines build with make CUDA=1. On
Windows the CUDA engine is a separate DLL (windows.md), and
every release ships it built: colibri--windows-x86_64-cuda.zip has
coli_cuda.dll (cards of compute capability 8.0 and newer) and the colibri,
qwen36 and kimi_k3 engines that load it, with DeepSeek V4's own CUDA DLLs. Unpack it
over the main archive and the setup picks CUDA.
cu_tier.h), and thecu_dense.h).
cuda_bd.cuh): every ggml block type of 32Q36_DN_GPU=1,→ →
 →
 →
 →
 →
 →
 →