
1
 →

🚀 Lightweight Python library for building production LLM applications with smart context management and automatic token optimization.
JacobHuang91/prompt-refiner is an open-source project on GitHub, mainly written in Python. 🚀 Lightweight Python library for building production LLM applications with smart context management and automatic token optimization. It currently holds 40 stars and 3 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Prompt Engineering board.



---
This project is no longer maintained. Token optimization is less critical now due to:
---
🚀 Lightweight Python library for AI Agents, RAG apps, and chatbots with smart context management and automatic token optimization.
Save 5-70% on API costs - 57% average reduction on function calling, 5-15% on RAG contexts.
---
RAG Applications • AI Agents • Chatbots • Document Processing • Cost Optimization
---
Build AI agents, RAG applications, and chatbots with automatic token optimization and smart context management. Here's a complete example (see examples/quickstart.py for full code):
from prompt_refiner import MessagesPacker, SchemaCompressor, ResponseCompressor, StripHTML, NormalizeWhitespace
1. Pack messages (automatic refining with default strategies)
packer = MessagesPacker(
track_tokens=True,
system="You are a helpful AI assistant.
",
context=(["Installation Guide..."], StripHTML() | NormalizeWhitespace()),
query="Search for Python books."
)
messages = packer.pack()
2. Compress tool schema
tool_schema = pydantic_function_tool(SearchBooksInput, name="search_books")
compressed_schema = SchemaCompressor().process(tool_schema)
3. Call LLM with compressed schema
response = client.chat.completions.create(
model="gpt-4o-mini", messages=messages, tools=[compressed_schema]
)
4. Compress tool response
tool_response = search_books(json.loads(tool_call.function.arguments))
compressed_response = ResponseCompressor().process(tool_response)
💡 Run python examples/quickstart.py to see the complete workflow with real OpenAI API verification.
Key benefits:
Default strategies - Automatic refining (MinimalStrategy for system/query, StandardStrategy for context/history)
Tool schema compression - Save 10-70% tokens on AI agent function definitions (avg: 57%)
Tool response compression - Save 30-70% tokens on agent tool outputs
Compose operations with
| - Chain multiple cleaners into a pipeline
Save 5-15% tokens on RAG contexts - Remove HTML, whitespace, duplicates automatically
All items included - No token budget limits, let LLM APIs handle final truncation
Track savings - Measure token optimization impact with built-in savings tracking
Production ready - Output goes directly to OpenAI without extra steps
✨ Key Features
| Module | Description | Components |
|--------|-------------|------------|
| Cleaner | Remove noise and save tokens | StripHTML(), NormalizeWhitespace(), FixUnicode(), JsonCleaner() |
| Compressor | Reduce size aggressively | TruncateTokens(), Deduplicate() |
| Scrubber | Protect sensitive data | RedactPII() |
| Tools | Optimize AI agent function calling (tool schemas & responses) | SchemaCompressor(), ResponseCompressor() |
| Packer | Smart message composition with priority-based ordering | MessagesPacker (chat APIs), TextPacker (completion APIs) |
| Strategy | Benchmark-tested presets for quick setup | MinimalStrategy, StandardStrategy, AggressiveStrategy |
# Basic installation (lightweight, zero dependencies)
pip install llm-prompt-refiner
With precise token counting (optional, installs tiktoken)
pip install llm-prompt-refiner[token]
Check out the examples/ folder for detailed examples:
strategy/ - Preset strategies (Minimal, Standard, Aggressive) with benchmark resultscleaner/ - HTML cleaning, JSON compression, whitespace normalization, Unicode fixingcompressor/ - Smart truncation, deduplicationscrubber/ - PII redaction (emails, phones, credit cards, etc.)tools/ - Tool/API output cleaning for agent systemspacker/ - Context budget management with OpenAI integrationanalyzer/ - Token counting and cost savings tracking📖 Full documentation: examples/README.md
Prompt Refiner has been rigorously tested across 3 comprehensive benchmark suites covering function calling, RAG applications, and performance. Here's what the data shows:
SchemaCompressor was tested on 20 real-world API schemas from Stripe, Salesforce, HubSpot, Slack, OpenAI, Anthropic, and more:
| Category | Schemas | Avg Reduction | Top Performer | |----------|---------|---------------|---------------| | Very Verbose (Enterprise APIs) | 11 | 67.4% | HubSpot: 73.2% | | Complex (Rich APIs) | 6 | 61.7% | Slack: 70.8% | | Medium (Standard APIs) | 2 | 13.1% | Weather: 20.1% | | Simple (Minimal APIs) | 1 | 0.0% | Calculator (already minimal) | | Overall Average | 20 | 56.9% | — |
Key Highlights:
56.9% average reduction across all schemas (15,342 tokens saved)
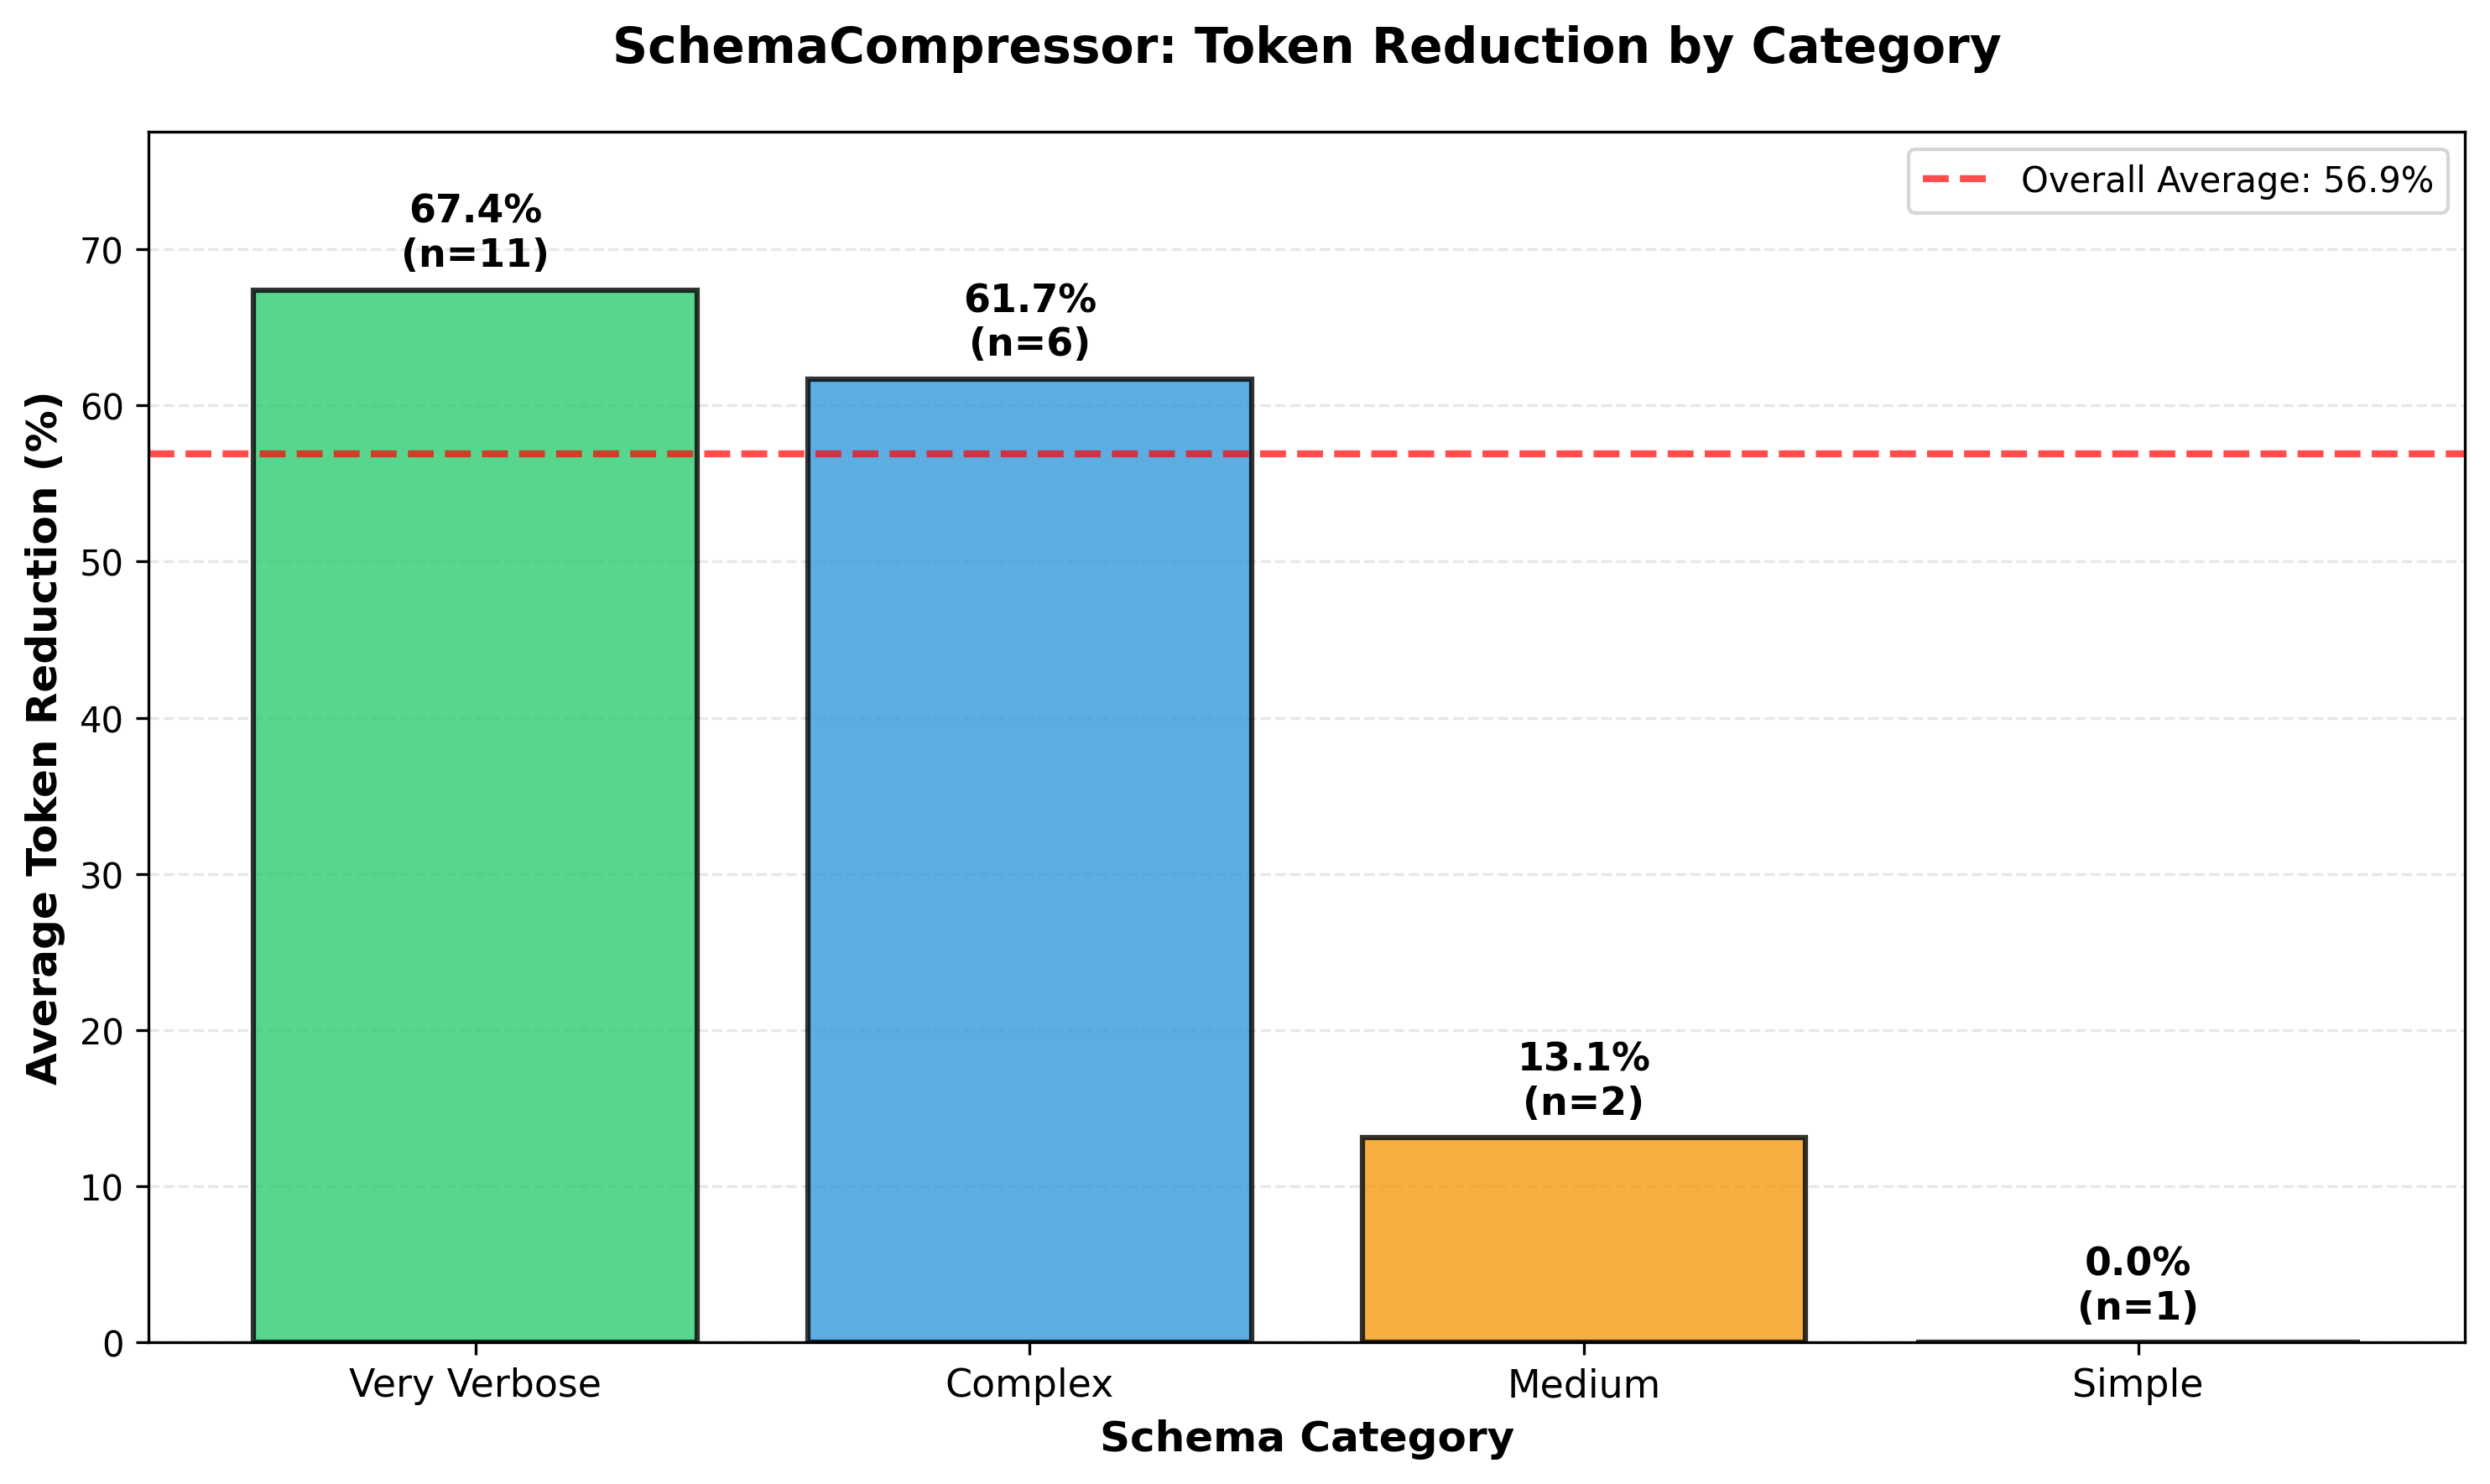 SchemaCompressor achieves 60%+ reduction on complex APIs
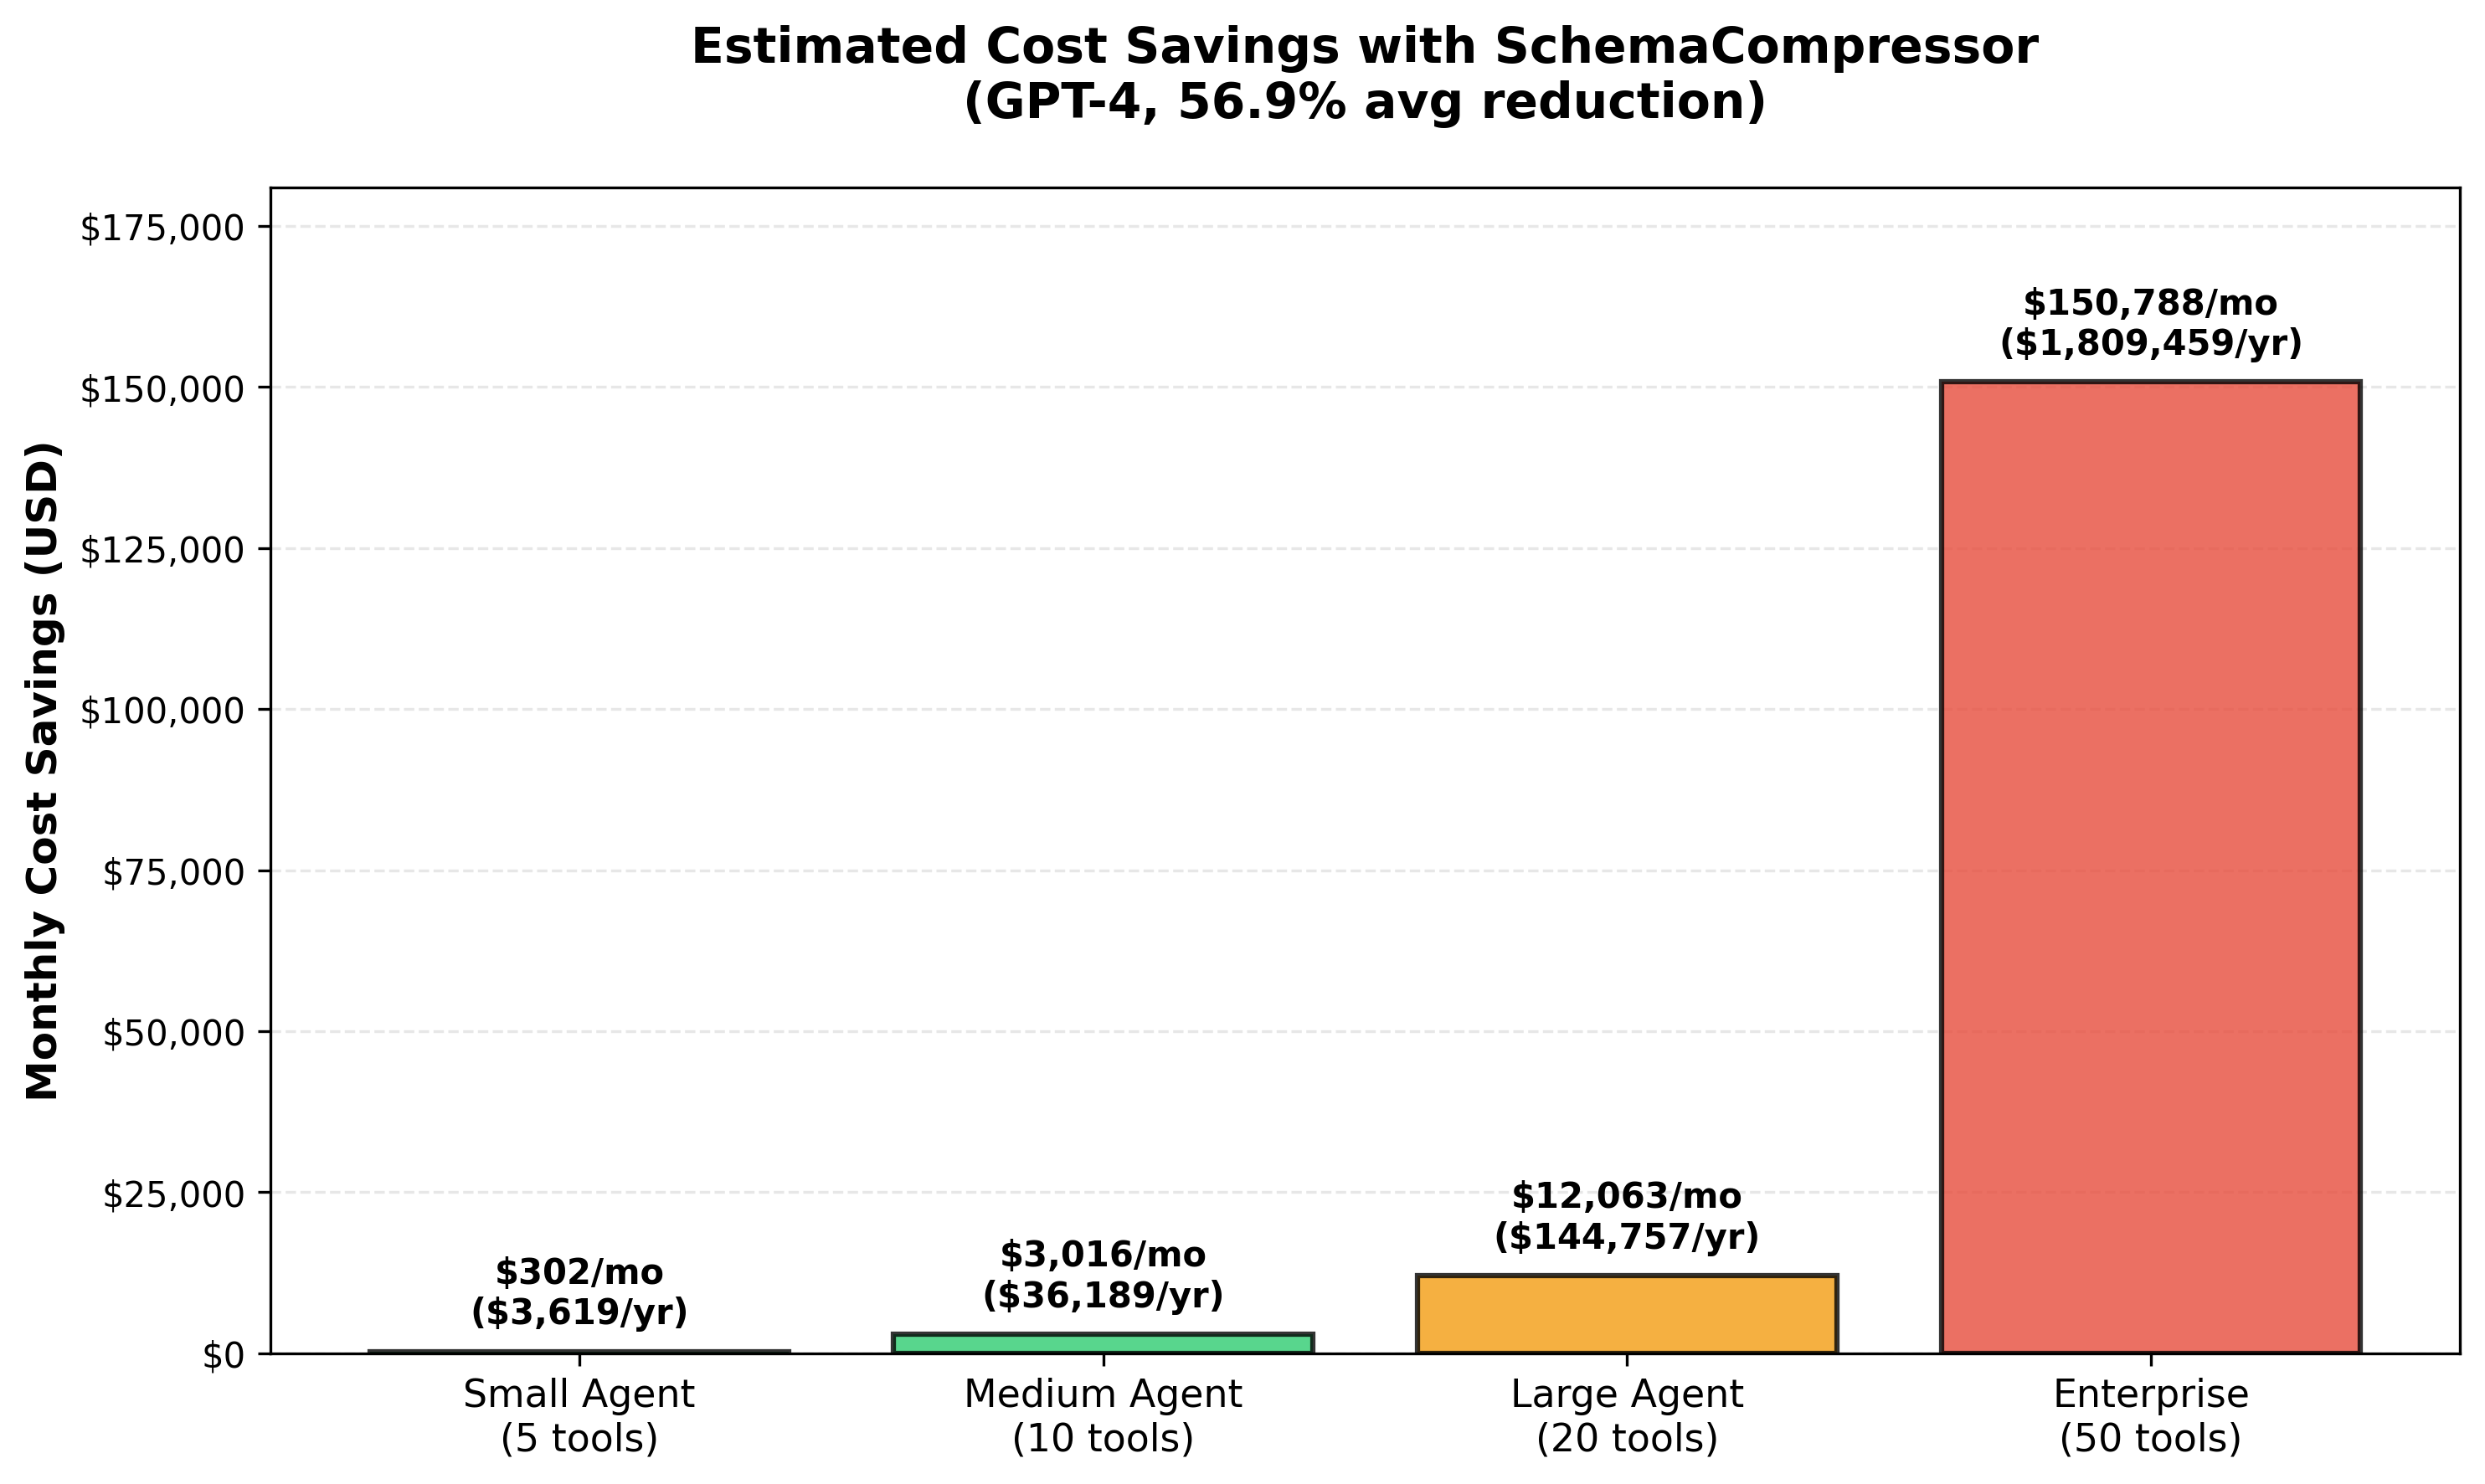 Estimated monthly savings for different agent sizes (GPT-4 pricing)
✅ Functional Validation:
We tested all 20 compressed schemas with real OpenAI function calling to prove they work correctly:
💰 Cost Savings Example: A medium agent (10 tools, 500 calls/day) saves $541/month with SchemaCompressor.
> 📖 See full benchmark: benchmark/README.md#function-calling-benchmark
---
Tested on 30 real-world test cases (SQuAD + RAG scenarios) to measure token reduction and quality preservation:
| Strategy | Token Reduction | Quality (Cosine) | Judge Approval | |----------|----------------|------------------|----------------| | Minimal | 4.3% | 0.987 | 86.7% | | Standard | 4.8% | 0.984 | 90.0% | | Aggressive | 15.0% | 0.964 | 80.0% |
Key Insights:
💰 Cost Savings: At 1M tokens/month, 15% reduction saves $54/month on GPT-4 input tokens.
> 📖 See full benchmark: benchmark/README.md#rag-quality-benchmark
"What's the latency overhead?" - Negligible. Prompt Refiner adds < 0.5ms per 1k tokens of overhead.
| Strategy | @ 1k tokens | @ 10k tokens | @ 50k tokens | Overhead per 1k tokens | |----------|------------|--------------|--------------|------------------------| | Minimal (HTML + Whitespace) | 0.05ms | 0.48ms | 2.39ms | 0.05ms | | Standard (+ Deduplicate) | 0.26ms | 2.47ms | 12.27ms | 0.25ms | | Aggressive (+ Truncate) | 0.26ms | 2.46ms | 12.38ms | 0.25ms |
Key Insights:
10k token RAG context refining: ~2.5ms overhead
Network latency: ~100ms
LLM Processing (TTFT): ~500ms+
Total overhead: < 0.5% of request time
🔬 Run yourself: python benchmark/latency/benchmark.py (no API keys needed)
Try prompt-refiner in your browser - no installation required!
Play with different strategies, see real-time token savings, and find the perfect configuration for your use case. Features:
MIT
→ →
 →
 →
 →
 →
 →
 →