1
 →

We introduce new zero-shot prompting magic words that improves the reasoning ability of language models: panel discussion!
holarissun/PanelGPT is an open-source project on GitHub, mainly written in Python. We introduce new zero-shot prompting magic words that improves the reasoning ability of language models: panel discussion! It currently holds 174 stars and 12 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Prompt Engineering board.
Three cobblers with their wits combined equal Zhuge Liang the mastermind. --- an old saying in China.
We introduce new zero-shot prompting magic words that improve language models' reasoning ability: Panel Discussion!
In conferences and workshops, there are always penal discussions among experts, and people exchange their opinions on a given topic, improving the understanding of new concepts, changing perspectives of thinking, and reaching a more comprehensive understanding of prevailing debates or discussions.
Figure 1: A panel discussion between Jack Ma and Elon Musk, WAIC, 2019:
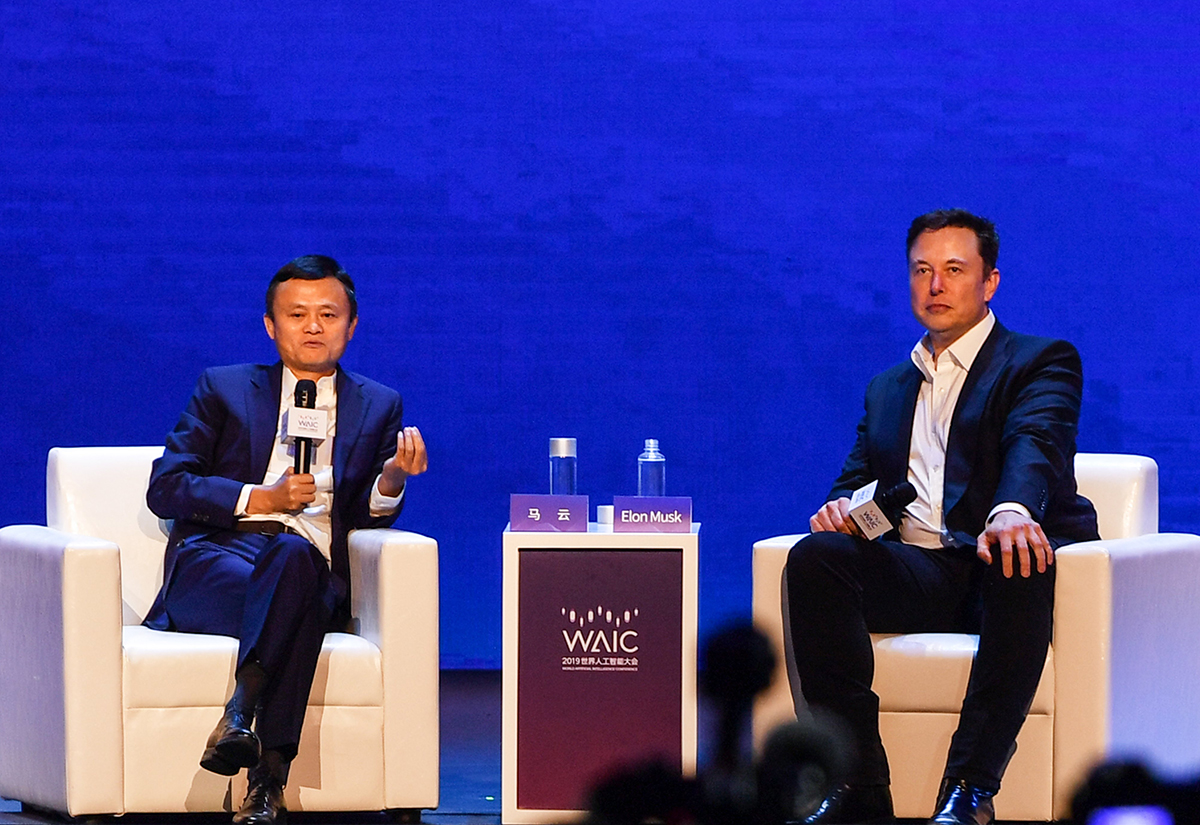
This idea is related to the work of self-consistency (Wang, Xuezhi, et al.) (as multiple experts may disagree with each other during the panel discussion.)
We evaluate the effectiveness of the proposed prompt method on the GSM8K dataset, using gpt-3.5-turbo api.
The cost for evaluating each prompt on the 1k GSM8k test dataset is less than 2 USD.
Our panel discussion prompt achieves the Best Performance, and ablation studies show the importance of each element's benefit. Second Best, and _Third Best_ are denoted by underline and _italic_ formats, respectively.
| Method\Dataset | GSM8K (test 1k) | Prompt Content | Reference | |---------|---------|---------|-----------| | No-Prompt | 0.789 | The answer is:| - | | Zero-Shot CoT | 0.854 | Let's think step by step: | (Kojima, Takeshi, et al. 2022) | | APE Improved CoT | 0.845 | Let’s work this out in a step by step way to be sure we have the right answer:| (Zhou, Yongchao, et al. 2023) | | ToT Prompting | 0.842 | Imagine three different experts are answering this question. All experts will write down 1 step of their thinking, then share it with the group. Then all experts will go on to the next step, etc. If any expert realises they're wrong at any point then they leave | (Dave Hulbert's Repo 2023) | | PanelGPT | 0.899 | 3 experts are discussing the question with a _panel_ discussion, trying to solve it step by step, and make sure the result is correct _and avoid penalty_: | (This Repo, July 18, 2023) | | PanelGPT w/o AE and EA | 0.878 | 3 experts are discussing the question with a discussion, trying to solve it step by step, and make sure the result is correct: | (Ours, Ablation Study) | PanelGPT w/o AE| 0.84 | 3 experts are discussing the question with a discussion, trying to solve it step by step, and make sure the result is correct and avoid penalty: | (Ours, Ablation Study) | PanelGPT w/o EA | 0.894 | 3 experts are discussing the question with a panel discussion, trying to solve it step by step, and make sure the result is correct: | (Ours, Ablation Study) | PenalGPT (Mis-spelled) | _0.883_ | 3 experts are discussing the question with a penal discussion, trying to solve it step by step, and make sure the result is correct: | (Ours, Ablation Study)
Notwithstanding the impressive zero-shot performance exhibited by large language models, these models often exhibit suboptimal performance in executing more complex tasks under a zero-shot setting. Leveraging few-shot prompting presents a viable approach for facilitating in-context learning (Brown et al., 2020; Min et al., 2022). This technique necessitates the inclusion of demonstrations within the prompt, effectively guiding the model toward enhanced performance. These demonstrations act as conditioning mechanisms for succeeding examples, leading the model to generate better responses.
In some more challenging tasks like complex arithmetic, commonsense, and symbolic reasoning tasks, the chain-of-thought (CoT) prompting is shown to be more effective in helping the language models to get correct answers (Wei et al., 2022). CoT includes additional reasoning steps in the few-shot prompting examples. Kojima et al. (2022) further introduces zero-shot CoT, showing that adding task-agnostic instruction can improve the model performance in specific tasks. In Zhang et al. (2022b), Auto-CoT combines the universality of zero-shot CoT and the capability of original CoT driven by demonstrations and proposes to automatically construct demonstrations based on clustering and diversity-based sampling that are beneficial for CoT reasoning.
If you use our code and prompt, please consider citing our paper:
```bibtex @inproceedings{sun2023query, title={Query-Dependent Prompt Evaluation and Optimization with Offline Inverse RL}, author={Sun, Hao and H{\"u}y{\"u}k, Alihan and van der Schaar, Mihaela}, booktitle={The Twelfth International Conference on Learning Representations}, year={2023} }
@article{sun2023reinforcement, title={Reinforcement Learning in the Era of LLMs: What is Essential? What is needed? An RL Perspective on RLHF, Prompting, and Beyond}, author={Sun, Hao}, journal={arXiv preprint arXiv:2310.06147}, year={2023} }
→ →
 →
 →
 →
 →
 →
 →