1
 →

Fault-tolerant, highly scalable GPU orchestration, and a machine learning framework designed for training models with billions to trillions of parameters
higgsfield-ai/higgsfield is an open-source project on GitHub, mainly written in Jupyter Notebook. Fault-tolerant, highly scalable GPU orchestration, and a machine learning framework designed for training models with billions to trillions of parameters It currently holds 4,213 stars and 714 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the Today's Trending board, currently at rank #78 with 8 new stars today.
Higgsfield is an open-source, fault-tolerant, highly scalable GPU orchestration, and a machine learning framework designed for training models with billions to trillions of parameters, such as Large Language Models (LLMs).

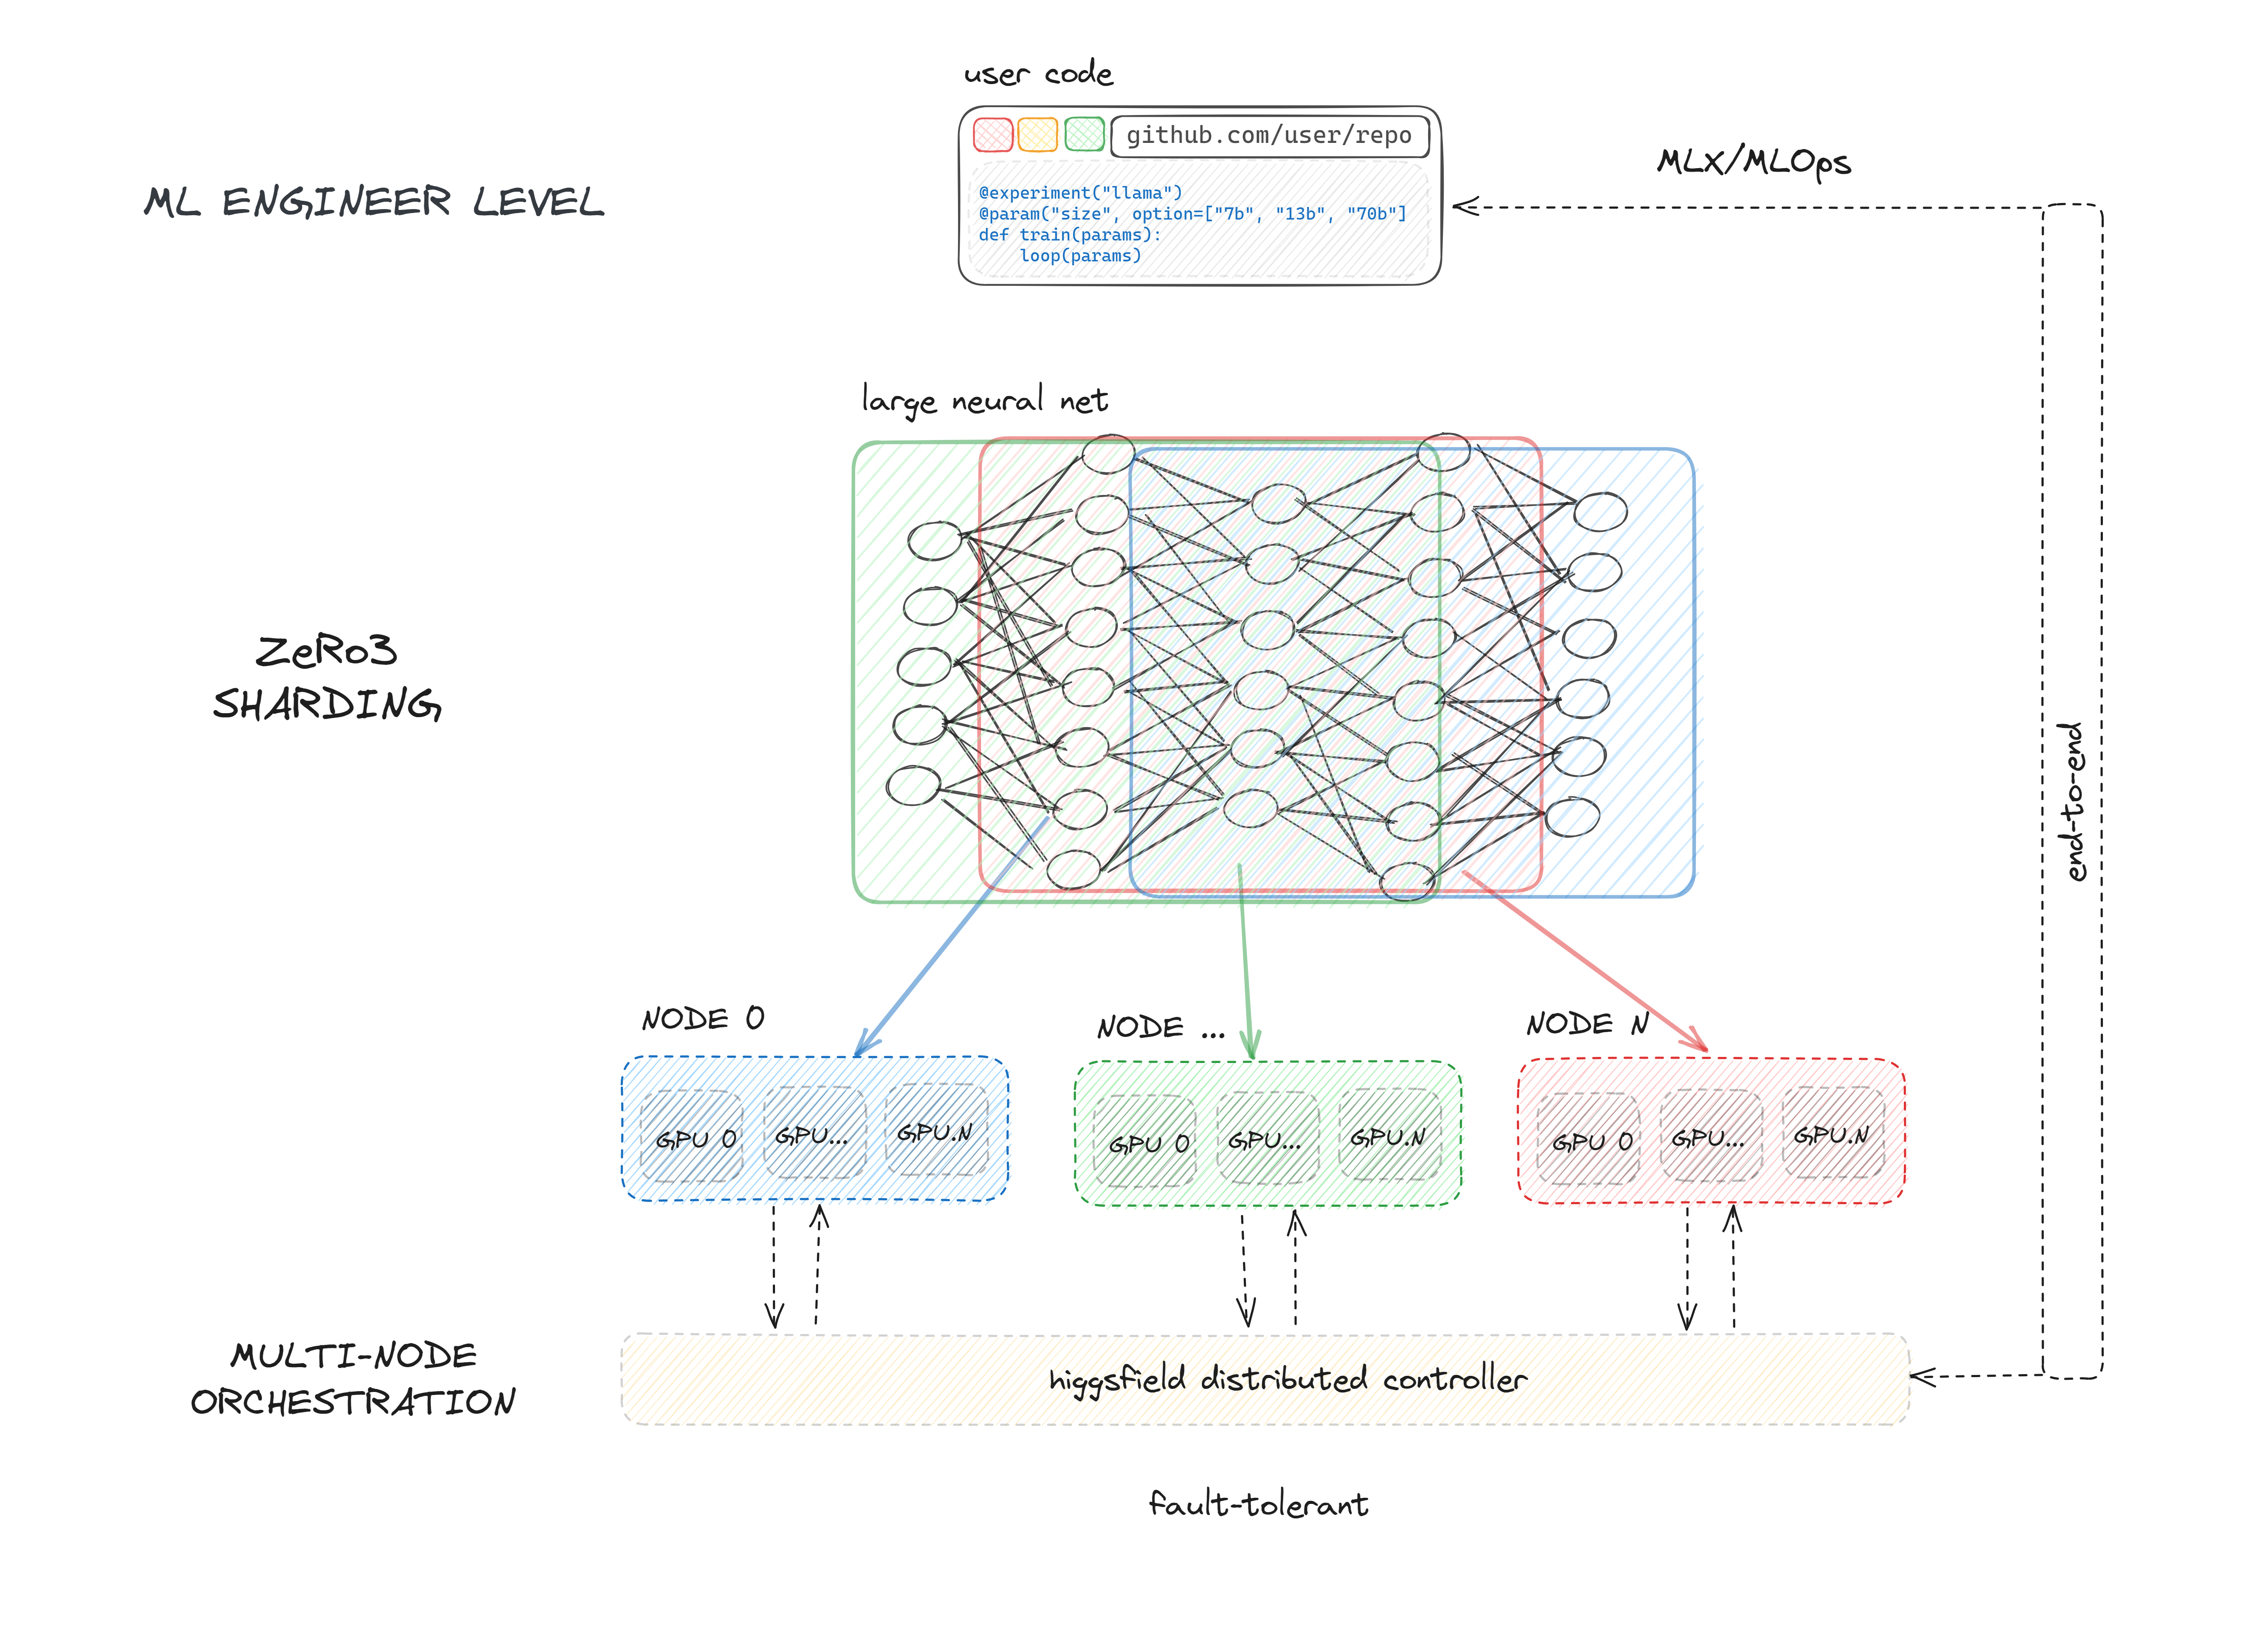
Higgsfield serves as a GPU workload manager and machine learning framework with five primary functions:
1. Allocating exclusive and non-exclusive access to compute resources (nodes) to users for their training tasks. 2. Supporting ZeRO-3 deepspeed API and fully sharded data parallel API of PyTorch, enabling efficient sharding for trillion-parameter models. 3. Offering a framework for initiating, executing, and monitoring the training of large neural networks on allocated nodes. 4. Managing resource contention by maintaining a queue for running experiments. 5. Facilitating continuous integration of machine learning development through seamless integration with GitHub and GitHub Actions. Higgsfield streamlines the process of training massive models and empowers developers with a versatile and robust toolset.
$ pip install higgsfield==0.0.3
That's all you have to do in order to train LLaMa in a distributed setting:
from higgsfield.llama import Llama70b
from higgsfield.loaders import LlamaLoader
from higgsfield.experiment import experiment
import torch.optim as optim
from alpaca import get_alpaca_data
@experiment("alpaca")
def train(params):
    model = Llama70b(zero_stage=3, fast_attn=False, precision="bf16")
optimizer = optim.AdamW(model.parameters(), lr=1e-5, weight_decay=0.0)
dataset = get_alpaca_data(split="train")
    train_loader = LlamaLoader(dataset, max_words=2048)
for batch in train_loader:
        optimizer.zero_grad()
        loss = model(batch)
        loss.backward()
        optimizer.step()
model.push_to_hub('alpaca-70b')
1. We install all the required tools in your server (Docker, your project's deploy keys, higgsfield binary). 2. Then we generate deploy & run workflows for your experiments. 3. As soon as it gets into Github, it will automatically deploy your code on your nodes. 4. Then you access your experiments' run UI through Github, which will launch experiments and save the checkpoints.
We follow the standard pytorch workflow. Thus you can incorporate anything besides what we provide, deepspeed, accelerate, or just implement your custom pytorch sharding from scratch.
Enviroment hell
No more different versions of pytorch, nvidia drivers, data processing libraries. You can easily orchestrate experiments and their environments, document and track the specific versions and configurations of all dependencies to ensure reproducibility.
Config hell
No need to define 600 arguments for your experiment. No more yaml witchcraft. You can use whatever you want, whenever you want. We just introduce a simple interface to define your experiments. We have even taken it further, now you only need to design the way to interact.
We need you to have nodes with:
Here you can find the quick start guide on how to setup your nodes and start training.
API for common tasks in Large Language Models training.
→→ →
 →
 →
 →
 →
 →