1
 →

Turn one image of anything into a 3D sculpt measured against that image: registered views, map-fitting passes, Blender replay and timelapse. A skill for coding agents.
gokayfem/image-to-sculpt is an open-source project on GitHub, mainly written in Python. Turn one image of anything into a 3D sculpt measured against that image: registered views, map-fitting passes, Blender replay and timelapse. It currently holds 227 stars and 14 forks with 0 open issues, and was last pushed on 2026-11-08 (repository created 2026-11-08).
AI Homed tracks it on the Today's Trending board, currently at rank #80 with 0 new stars today.
Turn one image of anything into a 3D sculpt that is measured against that image. A skill for coding agents (Claude Code, Codex, Cursor, Copilot, Gemini) that fits a watertight sculpt to the image's own normals, outline and depth in the image's own camera, completes the unseen sides from generated views that must first agree with each other, and records every step of the build so Blender can replay it as a timelapse.
The next step after Video 2 GLSL, Video 2 Blender Nodes, Video 2 Physics and Video to CSS. Those rebuild how a clip looks, moves and animates. This one rebuilds the shape of what is in a picture, and shows the work.
Ask an agent for "a 3D model of this" and it either calls a black-box image-to-3D model or sculpts blind. Either way nobody can say how well the result matches the picture, and the usual failures go unnoticed:
build/steps/.
.blend with the photo as the camera background, and GLB/OBJ/STL.
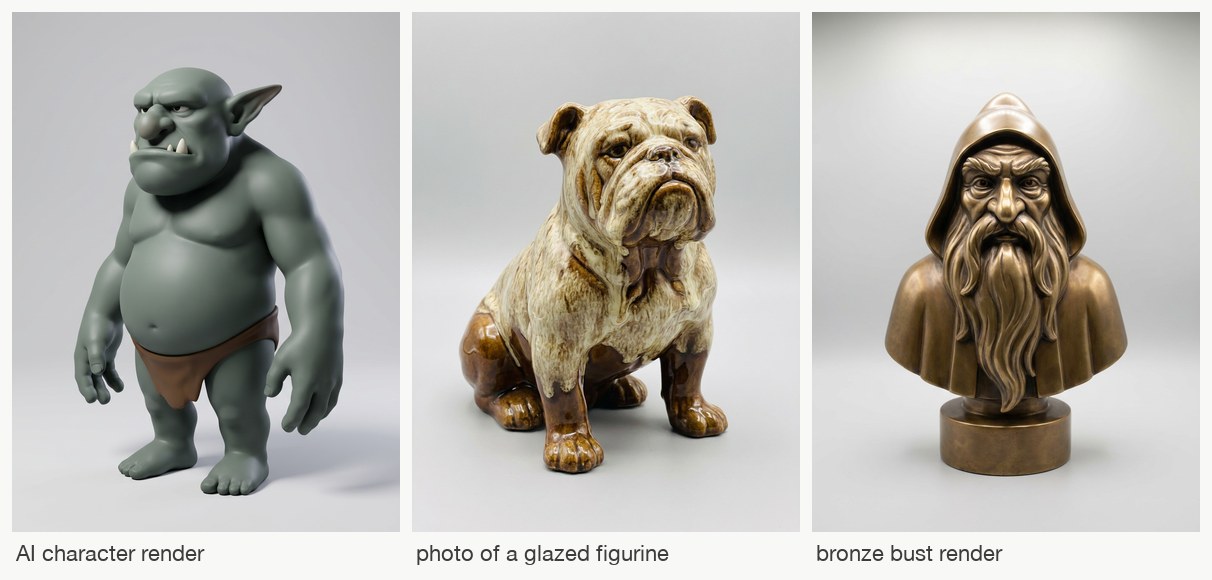
Three inputs the toolkit was developed on: an AI character render, a photo of a glazed figurine (reflective), a bronze bust render. One pipeline, no per-subject code.
| Input | What happens |
|---|---|
| An AI image or a 3D render of a character, creature, figurine or product | the main path |
| A photo of a real object (figurine, toy, statue, product) | MoGe's metric focal length and depth anchor the scale |
| A cut-out PNG with transparency | the alpha channel is the mask; no mask call |
| A busy image with several things in it | prep --select "the red dragon": SAM-3 picks the subject |
| A drawing, sketch or flat illustration | prep --restyle: turned into a 3D render first, same pose and silhouette |
| Several photos of the same object | views --import DIR: they replace generated views; angles from file names or found by registration |
| Only an idea | imagine OUT.png "idea" makes a clean full-figure image to start from |
| No API key | a cut-out PNG plus your own views; front-only works too (an inflated silhouette, depth guessed) |
Any aspect ratio and size: the input is padded (never cropped) to the nearest aspect ratio the view generator supports, so every view shares one lens. Units are normalised to the subject, so every tolerance transfers from a 2 cm figurine photo to a 2 m statue render. Scenes and rooms, hair-thin structures and transparent or mirror materials are out of scope, and the skill says so before starting.
Claude Code (plugin marketplace):
claude plugin marketplace add gokayfem/image-to-sculpt
claude plugin install image-to-sculpt@image-to-sculpt
Or copy the skill: cp -R skills/image-to-sculpt ~/.claude/skills/.
Codex, Cursor, Gemini CLI, Copilot and other agents (via skills):
npx skills add gokayfem/image-to-sculpt
Or install by hand:
skills/image-to-sculpt to ~/.agents/skills/.~/.cursor/skills/, plus the rule in adapters/cursor/.gh skill install gokayfem/image-to-sculpt image-to-sculpt, plus adapters/copilot/.gemini extensions install https://github.com/gokayfem/image-to-sculpt.skills/image-to-sculpt and upload it under Settings > Capabilities > Skills.
ChatGPT, Gemini Gems and other chat tools: see adapters/.
Requirements: Python 3.10+ with numpy, scipy, scikit-image and Pillow (pip install -r requirements.txt
adds fal-client and matplotlib), Blender 5.2+ ($BLENDER, blender on PATH, or the macOS app) and ffmpeg
for the replay and films, and a fal API key in FAL_KEY for masks, depth, normals and generated views.
python3 skills/image-to-sculpt/scripts/i2s.py doctor checks all of it (the key is never printed).
Ask naturally, for example:
owl.jpg."python3 skills/image-to-sculpt/scripts/i2s.py new cases/owl --input owl.jpg --subject "carved wooden owl figurine"
python3 skills/image-to-sculpt/scripts/i2s.py run cases/owl
run does everything after new. Each stage also runs on its own:
| Command | What it does |
|---|---|
| new | scaffold a case: the input copied with its sha256, padded to a generator aspect ratio, contract and targets |
| prep | front maps: mask, metric depth and focal length, normals; units normalised to the subject |
| views | generated views (9 + 1 held out by default) with masks and normals, or --import your own |
| parts | front-image regions from text prompts ("hands", "face") or boxes, for focused passes |
| hull | register every view, re-centre, screen, carve the visual hull (every cut recorded), find the mirror plane |
| fit | recorded map-fit passes: forms, surface, detail, polish, or focus --region R |
| cut, smooth | open gaps the views show; remove webs, flaps and specks (optionally in a region) |
| check | the map sheet and metrics for every view, the held-out view included |
| finish, blender, film | final surface; Blender replay, turntable and views; timelapse, turntable, views sheet, hero image |
| report | REPORT.md, the per-step chart and a static review page |
| demo | the whole pipeline offline on a synthetic subject with known shape |
Every paid call goes through a per-case budget (--budget, estimated per call) and its request id is written to
case.json before the result is awaited. A typical case costs about $2: 10 generated views with their masks and
normals, plus the photo's depth, normals and mask.
| Phase | Deliverable | Checked by |
|---|---|---|
| Scaffold | case.json, CONTRACT.md, acceptance.json, the padded working image | written before any view exists |
| Front maps | mask, metric depth, focal length, normals | a person looks at the mask and normal map |
| Views | generated or imported views with masks and normals | a person looks at every view; screening |
| Hull | registered cameras, the recorded carve, the mirror plane | IoU of every view against the hull of the others |
| Fit | 38 recorded passes, a silhouette cut, an opening, 4 polish passes | every view's maps, every pass; the held-out view |
| Check | map sheets, metrics per view | the targets in acceptance.json; a person reads the sheets |
| Blender | replayed steps, turntable, view renders, .blend, GLB/OBJ/STL | the views sheet: each view beside the sculpt from its camera |
| Deliver | timelapse ending in a 360° turn, report, review page | a person decides whether to iterate |
The timelapse puts the reference beside the sculpt for every recorded step, from the first block through each carve and pass, holds on the result, then turns the finished sculpt a full 360°. Its first frame is a finished thumbnail.
| Check | Where | What it proves |
|---|---|---|
| Cameras and rasteriser | tests/test_geom.py | projection round trips, orbits about the centre, rigid Blender cameras; a rasterised sphere matches the analytic depth (0.1/1000) and normals (0.3°) |
| Distance fields | tests/test_sdf.py | fields stay exact (median 0.07 voxel, gradient norm 1); offsets move the surface by exactly the offset; opening removes a one-voxel web and keeps the ball; resampling keeps the surface |
| Registration | tests/test_register.py | a view asked for at 30° but taken at 72° is found at 72.0°; a back view stays a back view; a symmetric subject seen from behind and above is not taken for its front from below; the mirror plane is found at any yaw (25.0° for 25°); a changed pose scores 0.68 against 0.98 for a consistent view |
| End to end | tests/test_pipeline.py (--slow) | a synthetic figure with views 10° off their asked angles, noisy normals and one view with the arms raised: the bad view is rejected, every camera is recovered, the fit ends closer to the true shape than the hull, the held-out view agrees |
python3 tests/run_tests.py           # fast tests (~1 min)
python3 tests/run_tests.py --slow    # + the end-to-end pipeline
CI (.github/workflows/checks.yml) runs both on Linux without fal, Blender or ffmpeg.
skills/image-to-sculpt/   the skill: SKILL.md, references/, templates/, scripts/ (i2s CLI, library, Blender script)
tests/                    python3 tests/run_tests.py [--slow] (synthetic subjects with known shape)
adapters/                 prompts for assistants without skill support
gallery/                  README input images
Cases and everything they produce live outside the repository (cases/ is git-ignored).
See CREDITS.md. MIT licensed.
→ →
 →
 →
 →
 →
 →
 →