
1
 →
getzep/graphiti is an open-source project on GitHub, mainly written in Python. Build Real-Time Knowledge Graphs for AI Agents It currently holds 30,913 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Models & LLM Tools board.


[!NOTE]
We're Hiring! Build context graphs that power reliable, personalized, fast production AI agents.
Come build with us — we're hiring Engineers and Developer Relations folks. View open roles.
⭐ Help us reach more developers and grow the Graphiti community. Star this repo!
Graphiti is a framework for building and querying temporal context graphs for AI agents. Unlike static knowledge graphs, Graphiti's context graphs track how facts change over time, maintain provenance to source data, and support both prescribed and learned ontology — making them purpose-built for agents operating on evolving, real-world data.
Unlike traditional retrieval-augmented generation (RAG) methods, Graphiti continuously integrates user interactions, structured and unstructured enterprise data, and external information into a coherent, queryable graph. The framework supports incremental data updates, efficient retrieval, and precise historical queries without requiring complete graph recomputation, making it suitable for developing interactive, context-aware AI applications.
Use Graphiti to:
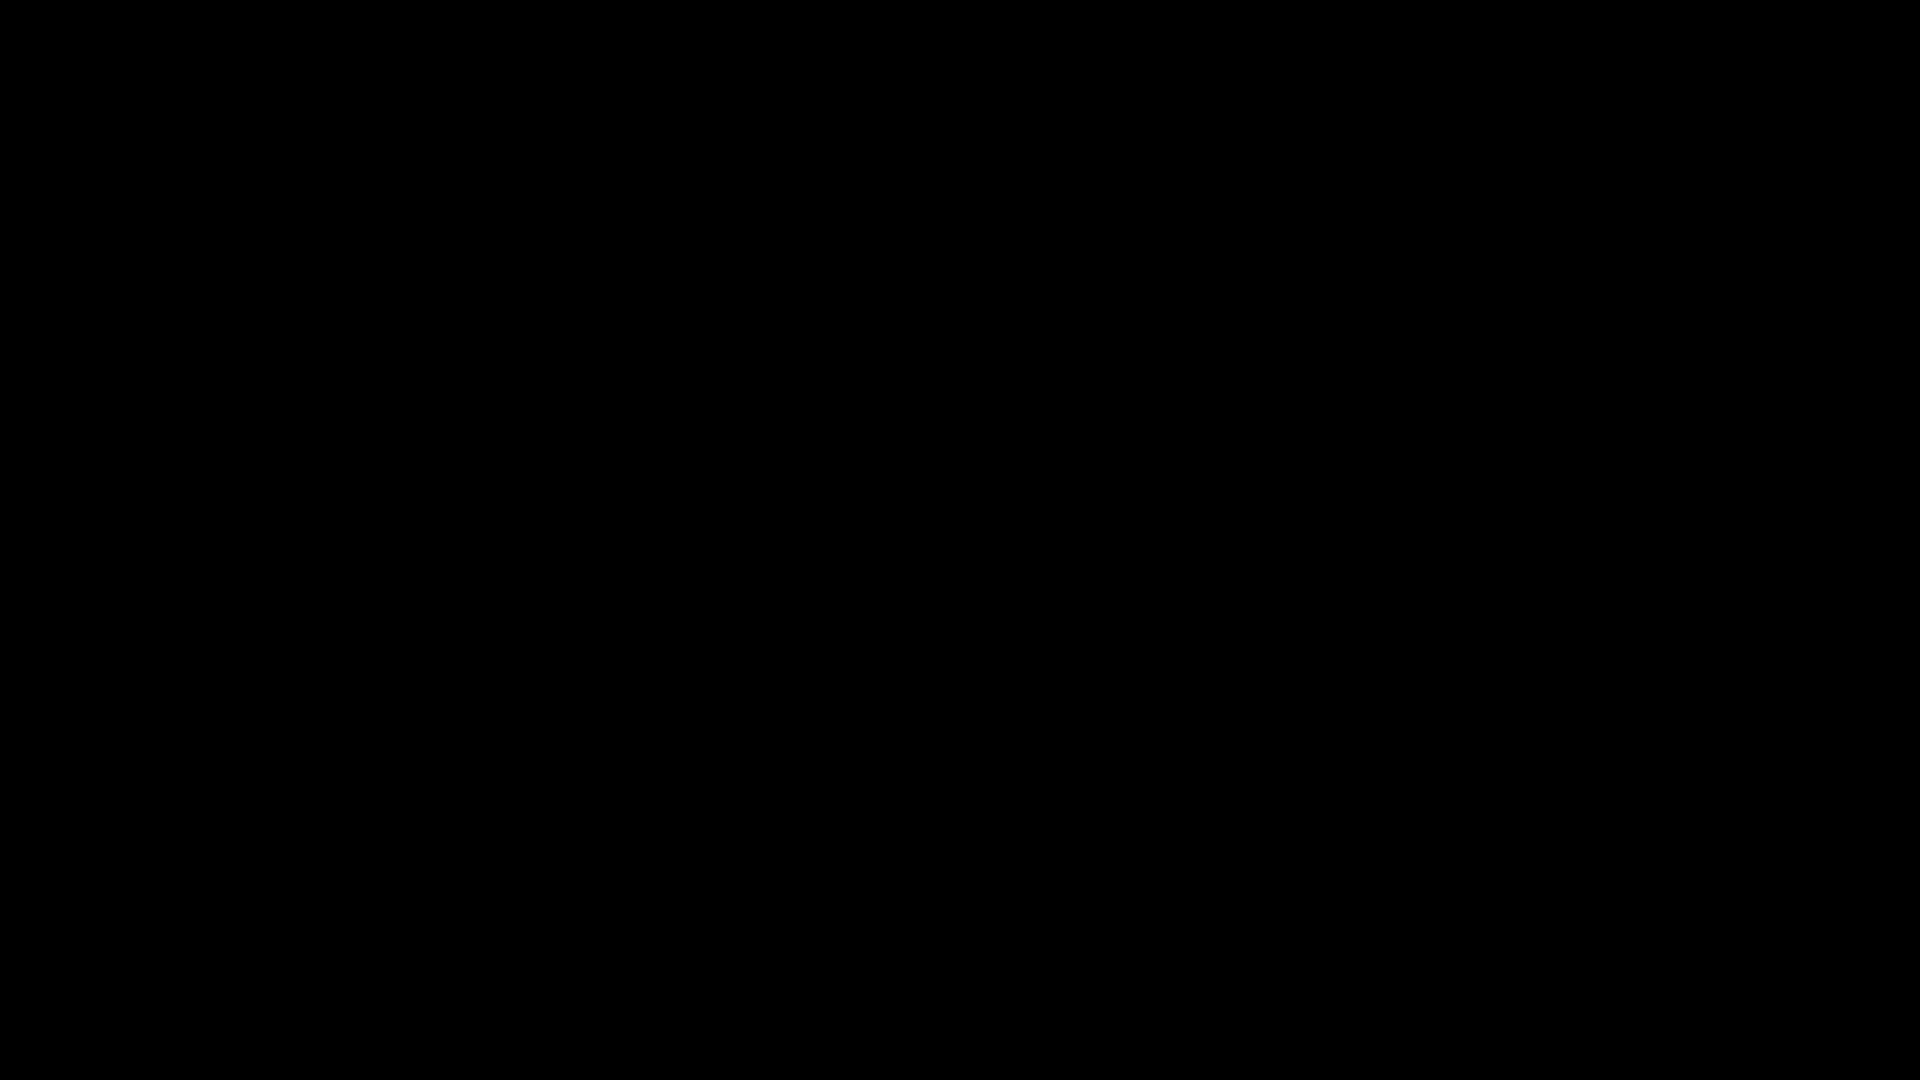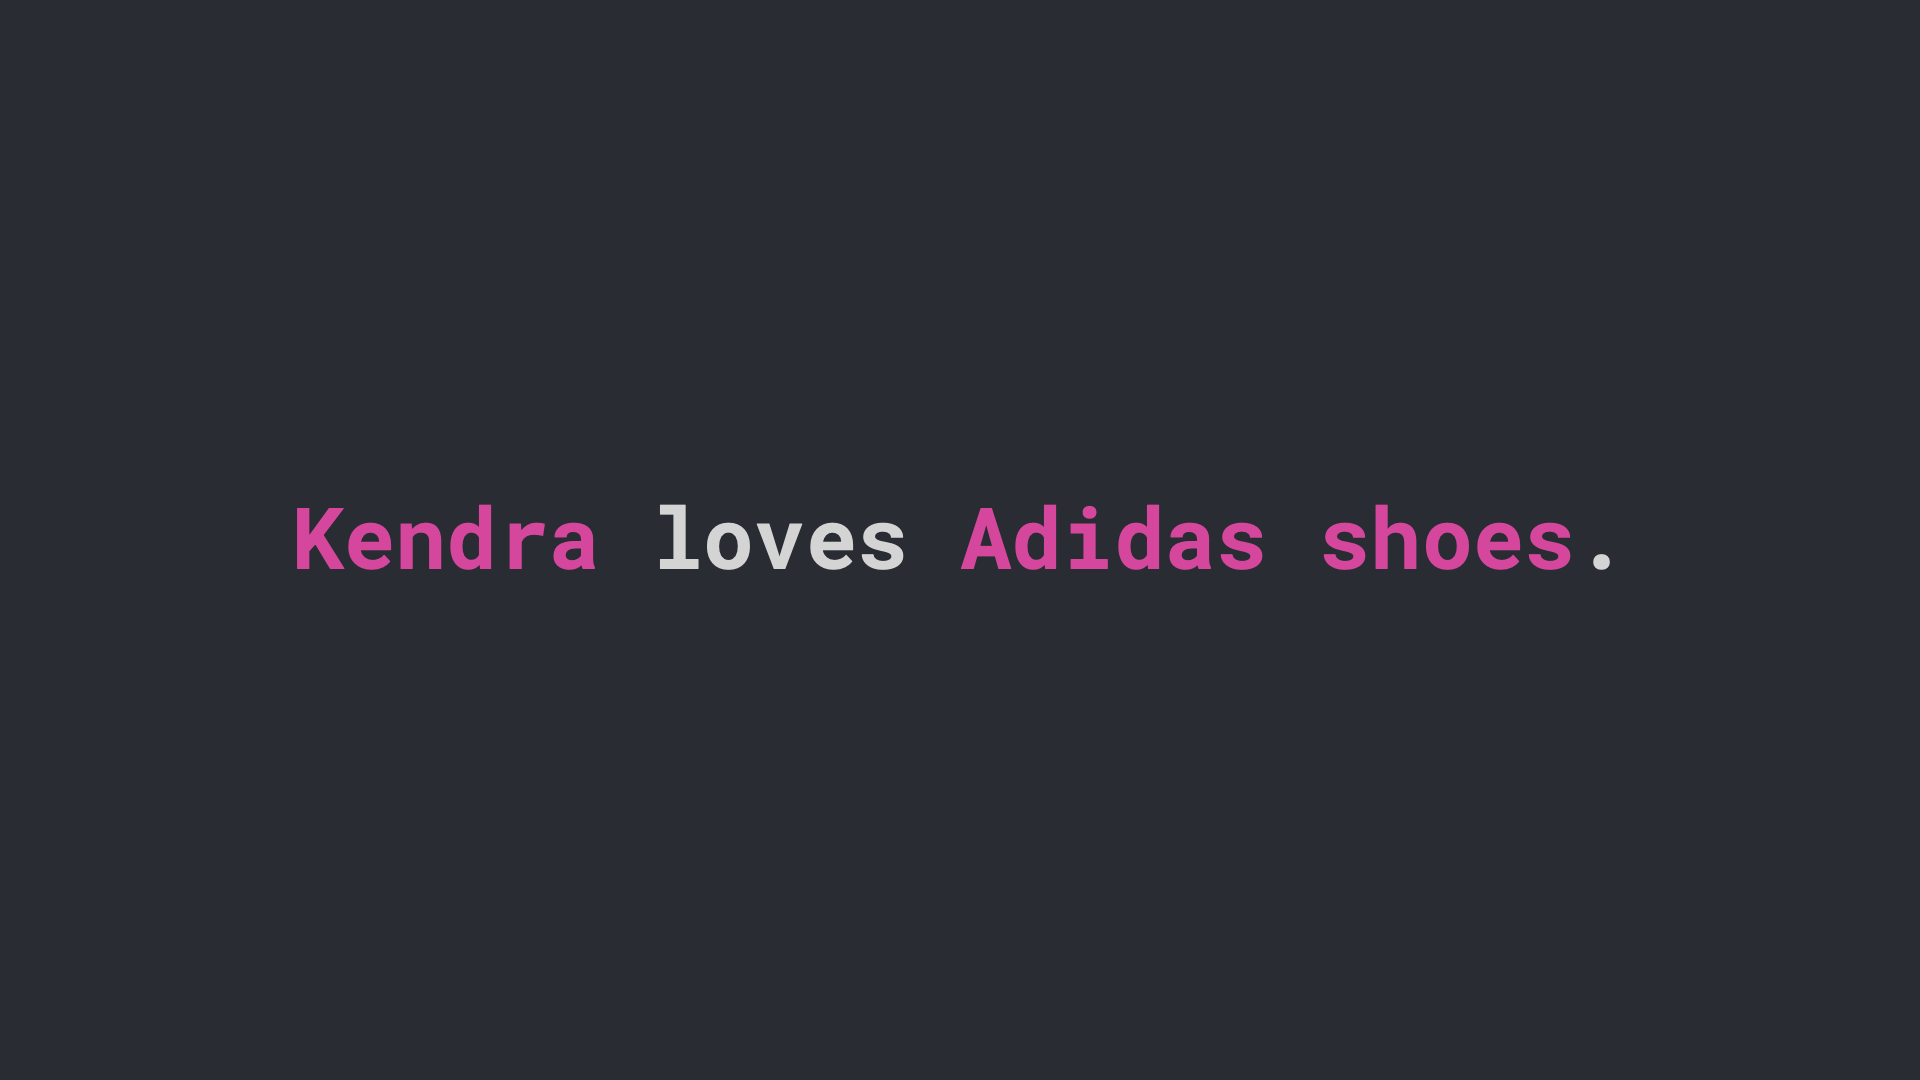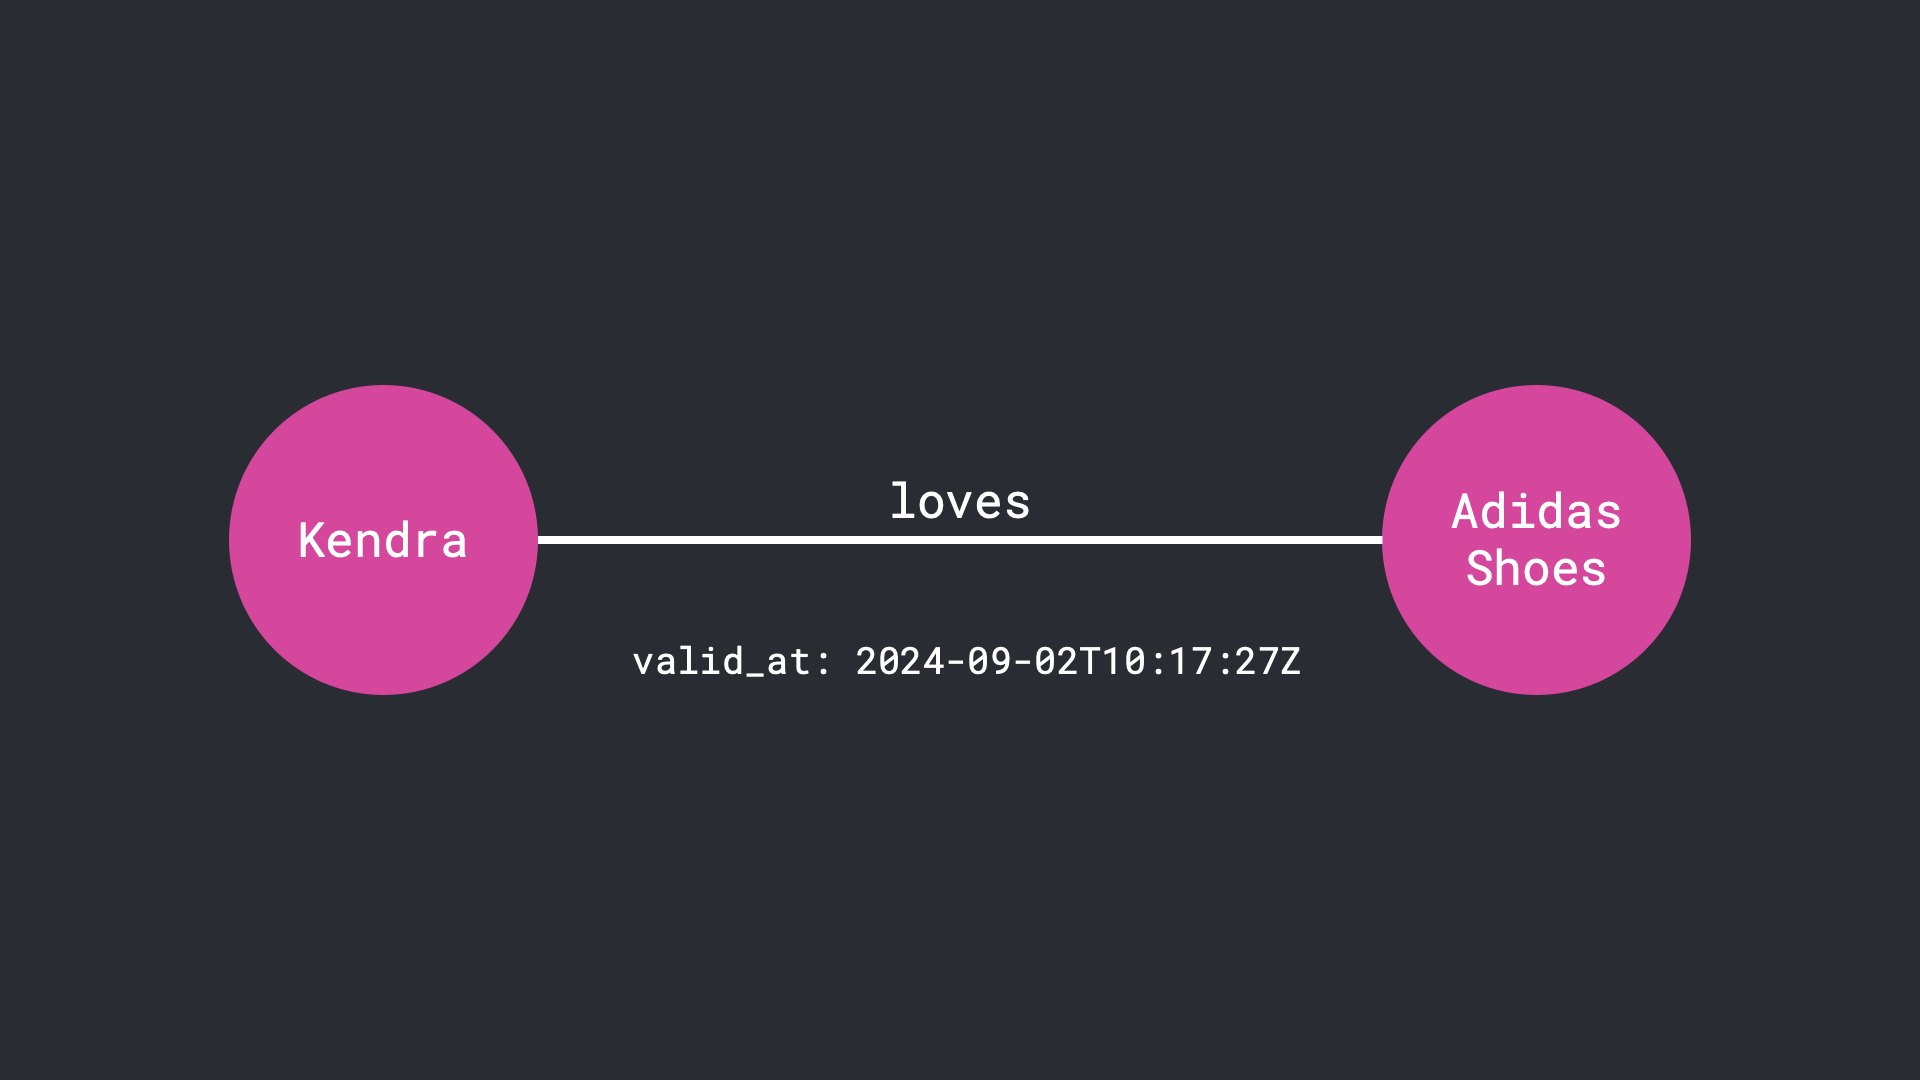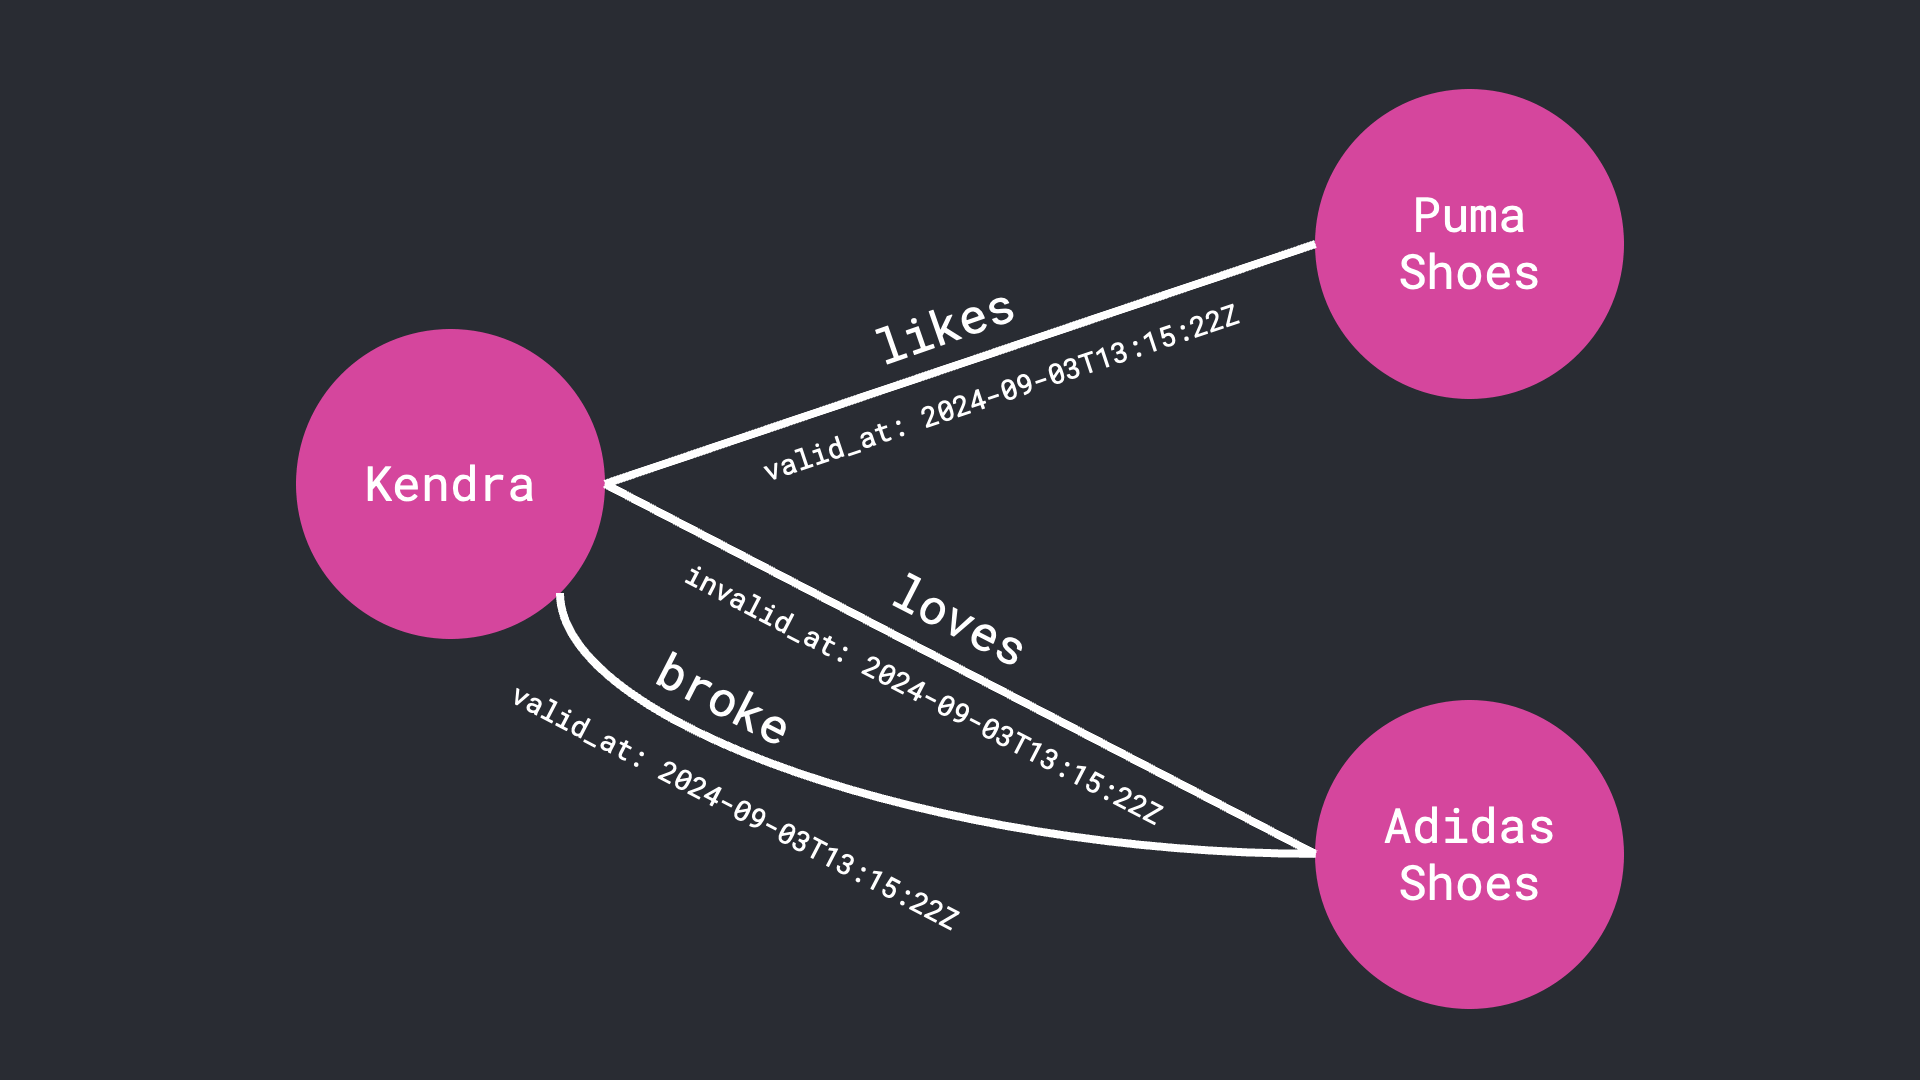
A context graph is a temporal graph of entities, relationships, and facts — like *"Kendra loves Adidas shoes (as of March 2026)."* Unlike traditional knowledge graphs, each fact in a context graph has a validity window: when it became true, and when (if ever) it was superseded. Entities evolve over time with updated summaries. Everything traces back to episodes — the raw data that produced it.
What makes Graphiti unique is its ability to autonomously build context graphs from unstructured and structured data, handling changing relationships while preserving full temporal history.
A context graph contains:
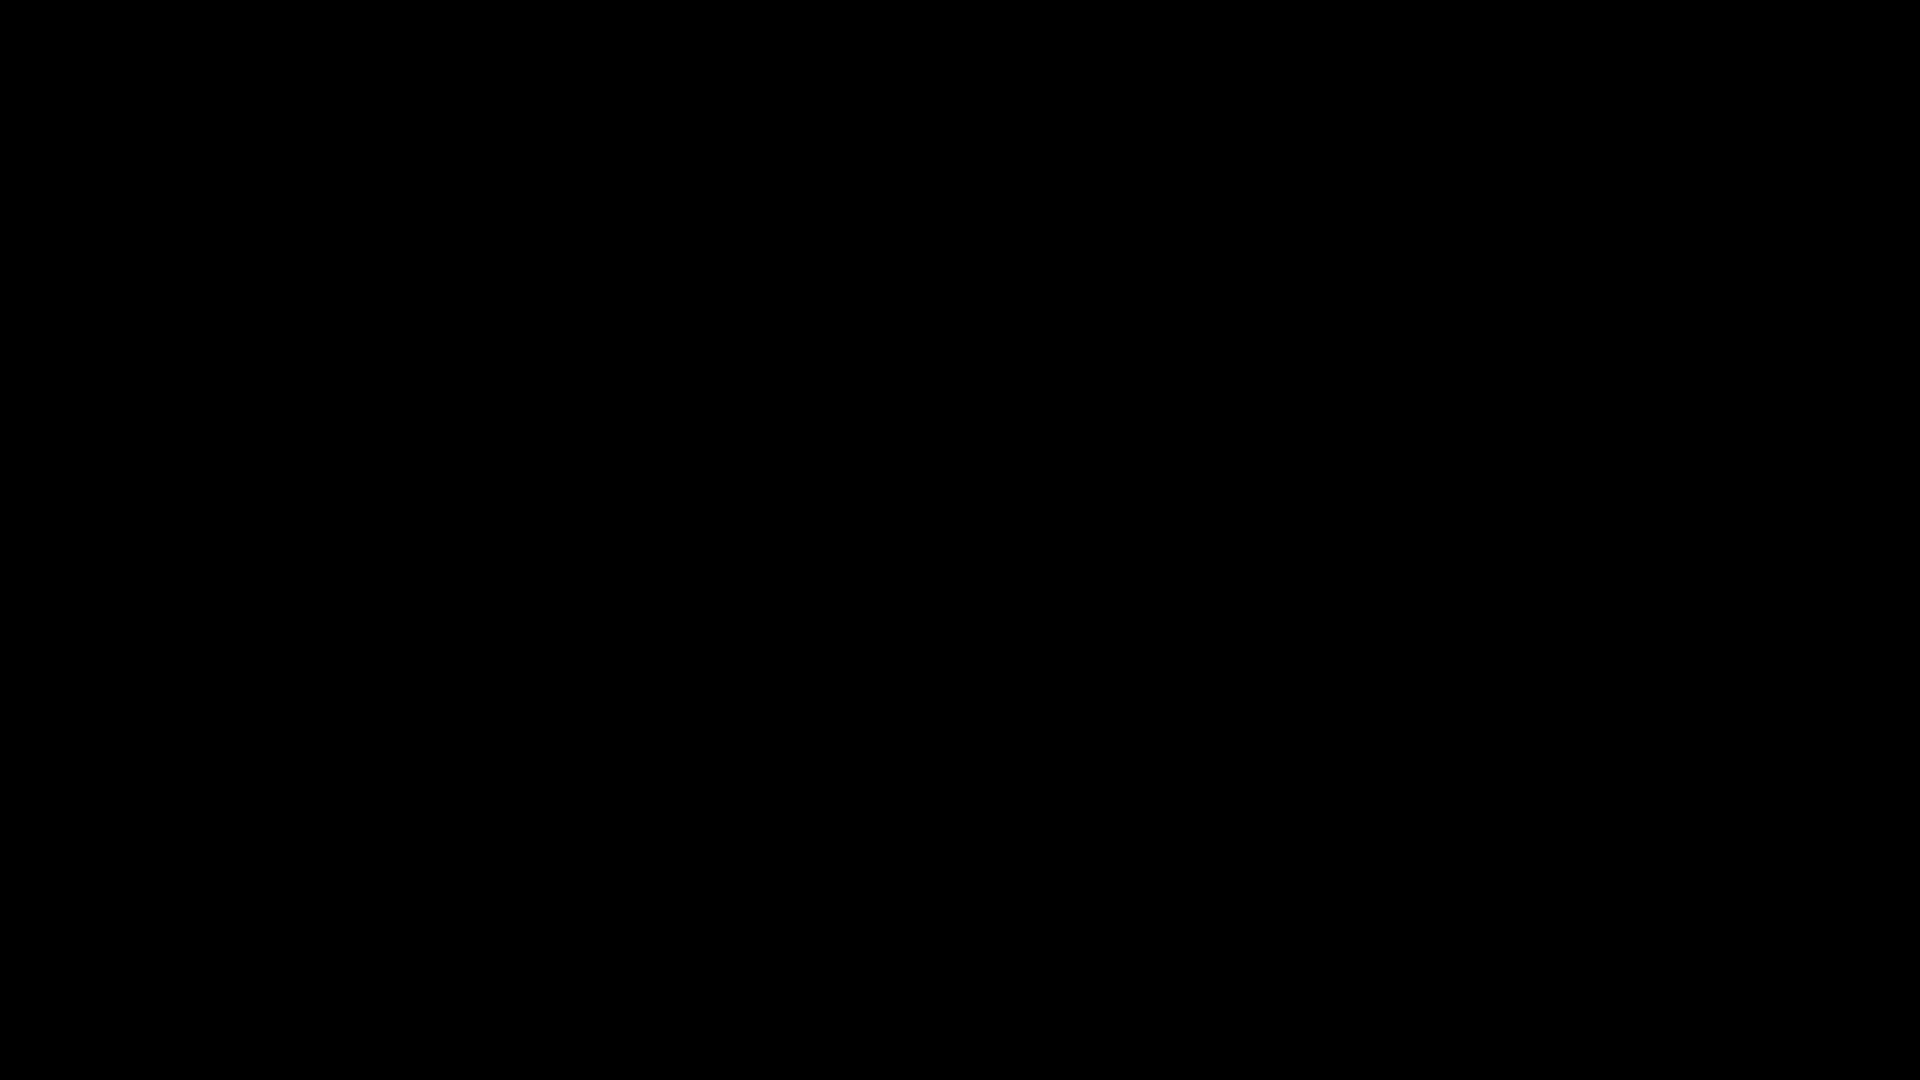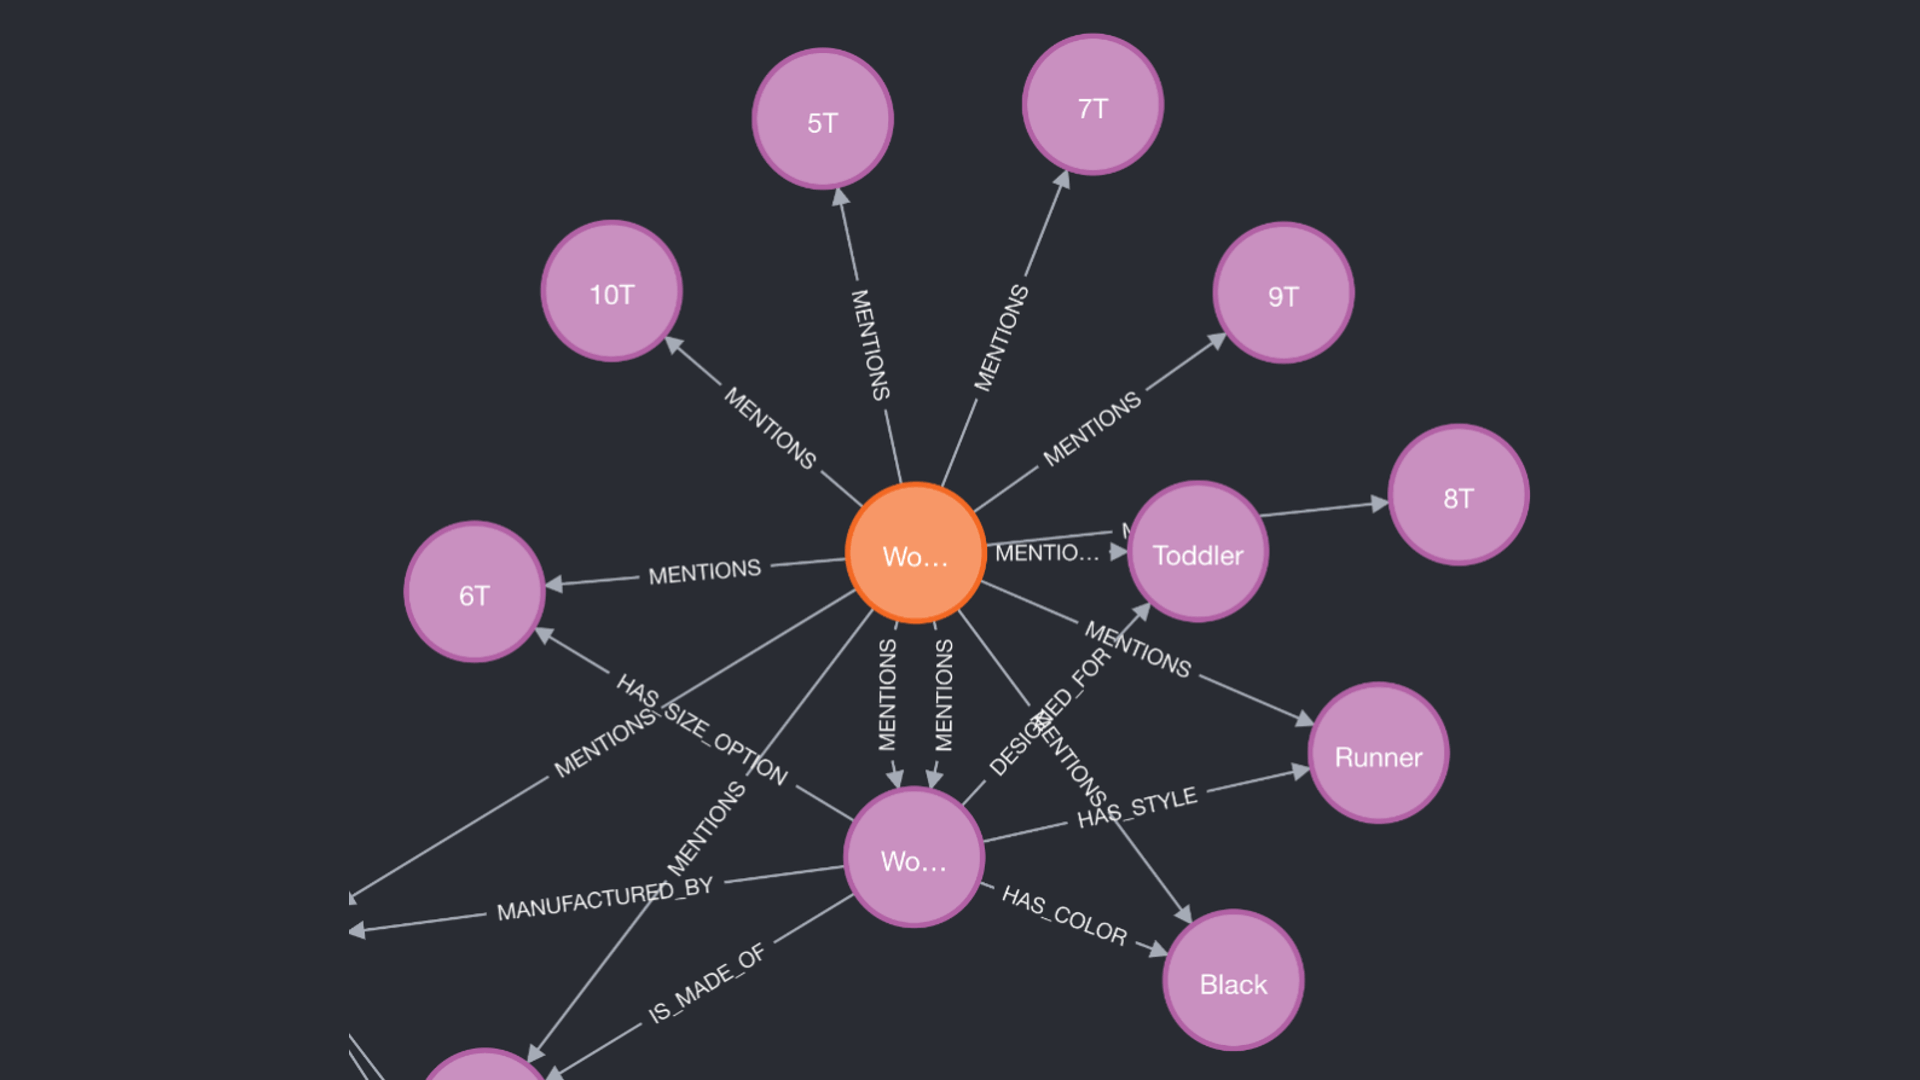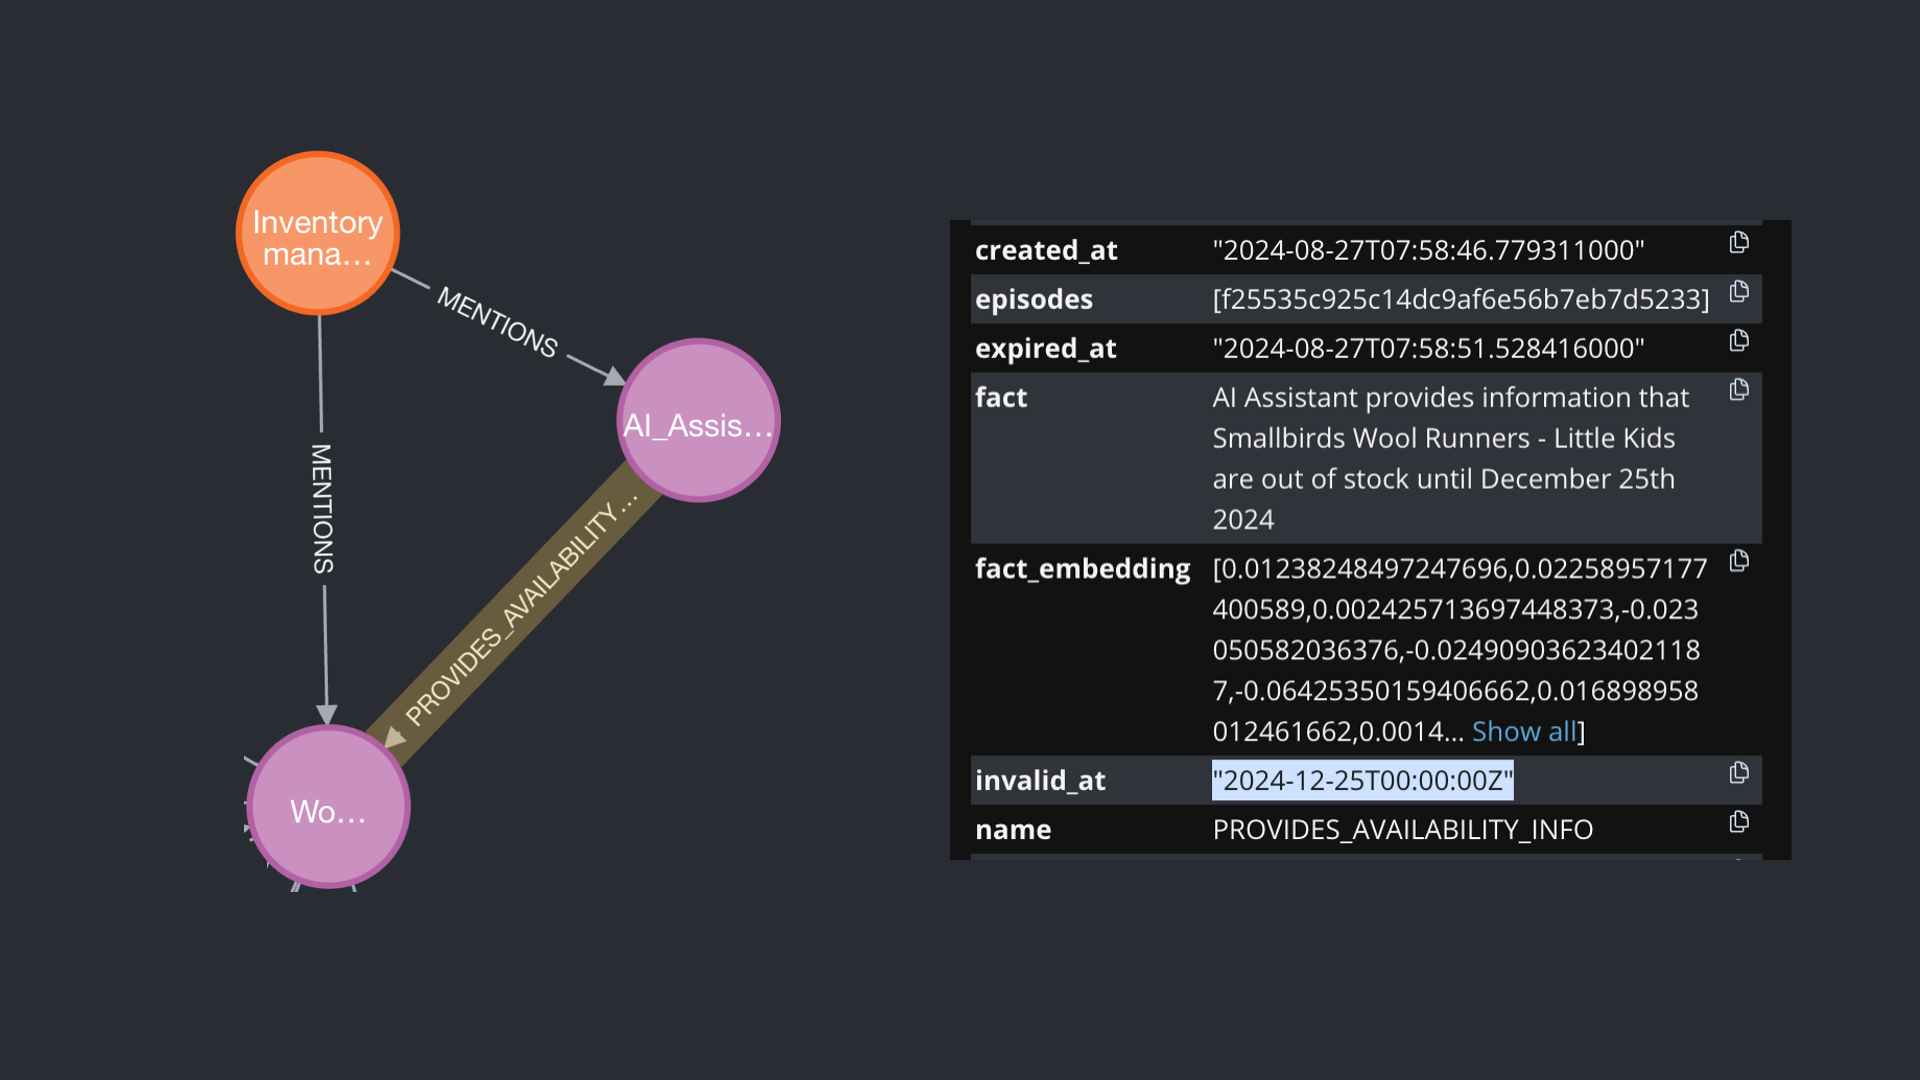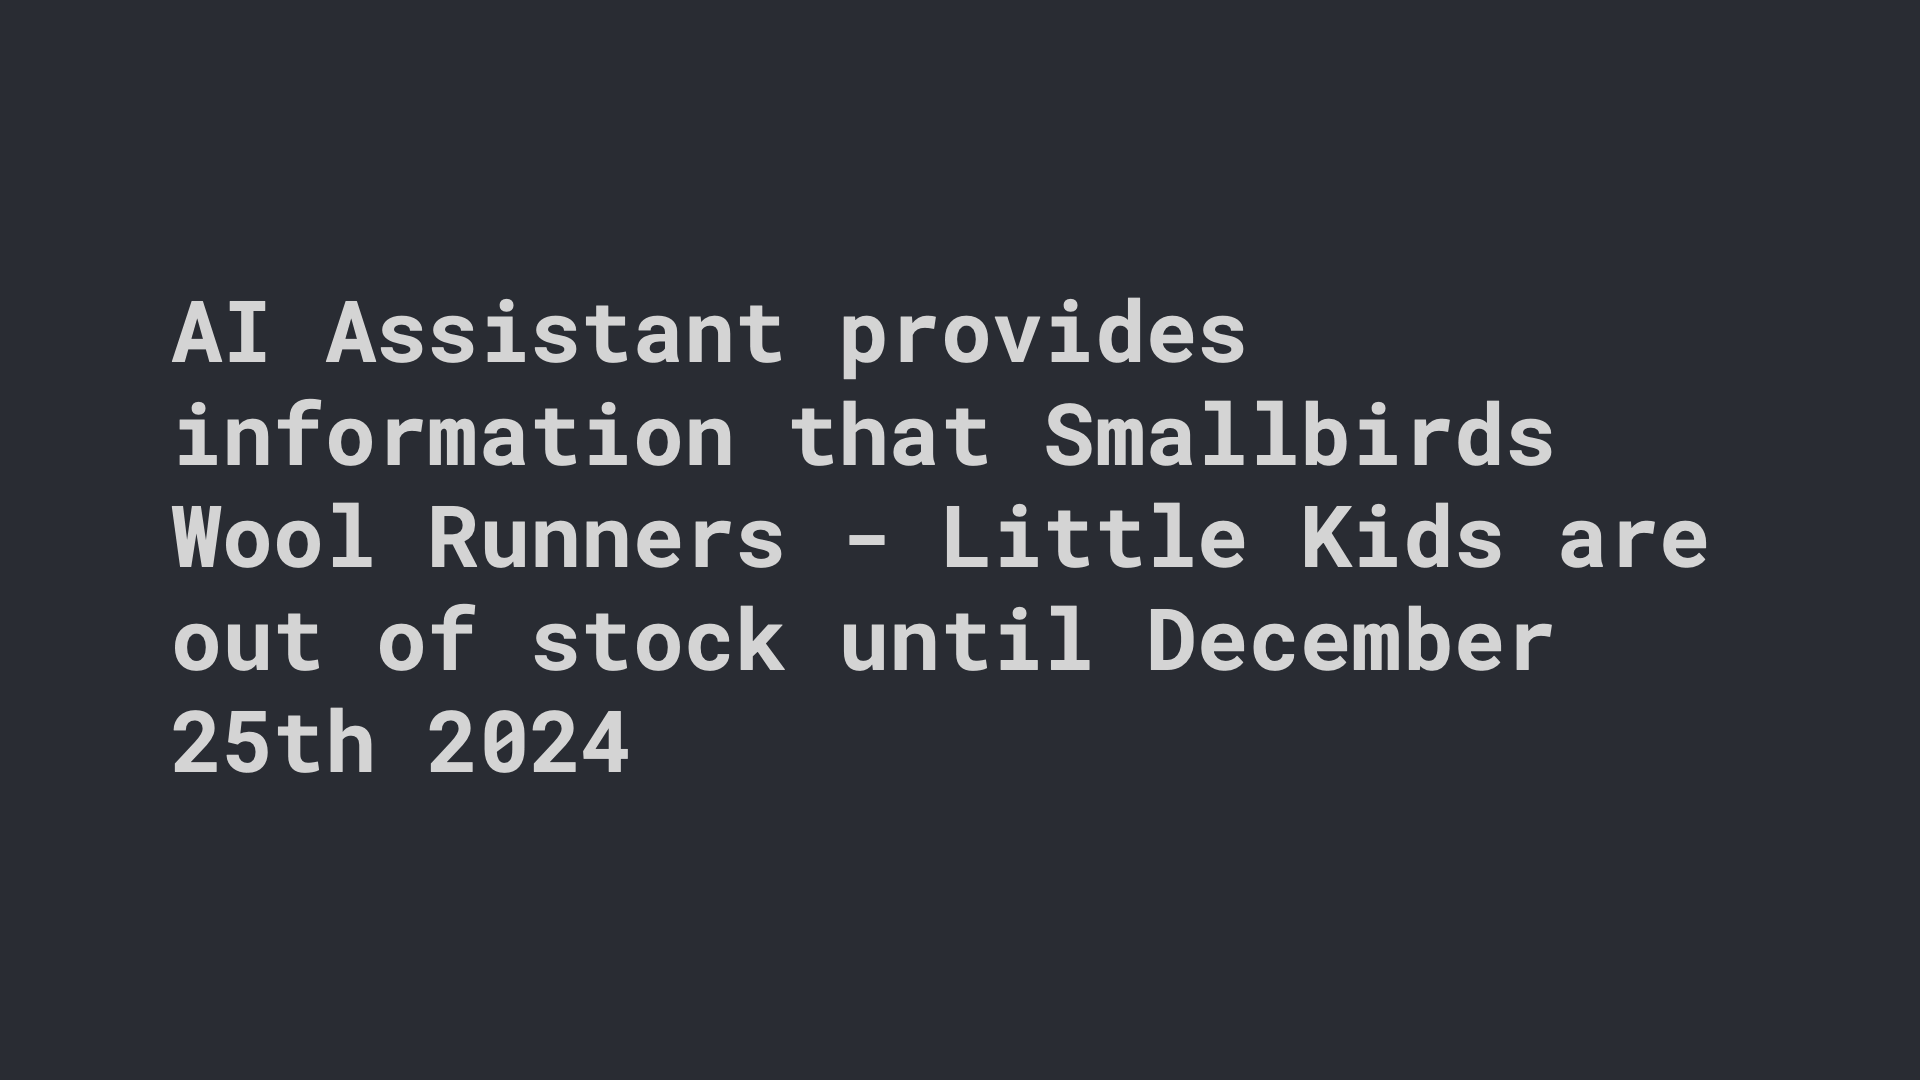
| Component | What it stores | |-----------|---------------| | Entities (nodes) | People, products, policies, concepts — with summaries that evolve over time | | Facts / Relationships (edges) | Triplets (Entity → Relationship → Entity) with temporal validity windows | | Episodes (provenance) | Raw data as ingested — the ground truth stream. Every derived fact traces back here | | Custom Types (ontology) | Developer-defined entity and edge types via Pydantic models |
Graphiti is the open-source framework for building temporal knowledge graphs at the core of Zep's context infrastructure. Zep manages context graphs at scale, providing governed, low-latency context retrieval and assembly for production deployments.
Under the hood, Zep is powered by a proprietary graph database — the Context Graph Engine — built for millions of context graphs with low-latency retrieval, so production deployments don't require a separate third-party graph database.
Read our paper: Zep: A Temporal Knowledge Graph Architecture.
| Aspect | Zep | Graphiti | |--------|-----|---------| | What they are | Managed context graph infrastructure | Open-source framework for building temporal knowledge graphs | | Context graphs | Manages vast numbers of per-user/entity context graphs with governance | Build and query individual context graphs | | Graph database | Proprietary Context Graph Engine — built for millions of context graphs with low-latency retrieval; no third-party graph database vendor required | Bring your own third-party graph database | | User & conversation management | Built-in users, threads, and message storage | Build your own | | Retrieval & performance | Pre-configured, production-ready retrieval with sub-200ms performance at scale | Custom implementation required; performance depends on your setup | | Developer tools | Dashboard with graph visualization, debug logs, API logs; SDKs for Python, TypeScript, and Go | Build your own tools | | Enterprise features | SLAs, support, security guarantees | Self-managed | | Deployment | Fully managed or in your cloud | Self-hosted only |
Choose Zep if you want a turnkey, enterprise-grade platform with security, performance, and support baked in.
Choose Graphiti if you want a flexible OSS core and you're comfortable building/operating the surrounding system.
Traditional RAG approaches often rely on batch processing and static data summarization, making them inefficient for frequently changing data. Graphiti addresses these challenges by providing:
| Aspect | GraphRAG | Graphiti | |--------|----------|---------| | Primary Use | Static document summarization | Dynamic, evolving temporal knowledge graphs | | Data Handling | Batch-oriented processing | Continuous, incremental updates | | Knowledge Structure | Entity clusters & community summaries | Temporal context graph — entities, facts with validity windows, episodes, communities | | Retrieval Method | Sequential LLM summarization | Hybrid semantic, keyword, and graph-based search | | Adaptability | Low | High | | Temporal Handling | Basic timestamp tracking | Explicit bi-temporal tracking with automatic fact invalidation | | Contradiction Handling | LLM-driven summarization judgments | Automatic fact invalidation with temporal history preserved | | Query Latency | Seconds to tens of seconds | Typically sub-second latency | | Custom Entity Types | No | Yes, customizable via Pydantic models | | Scalability | Moderate | High, optimized for large datasets |
Graphiti is specifically designed to address the challenges of dynamic and frequently updated datasets, making it particularly suitable for applications requiring real-time interaction and precise historical queries.
Requirements:
[!IMPORTANT]
Graphiti works best with LLM services that support Structured Output (such as OpenAI, Anthropic, and Gemini).
Using other services may result in incorrect output schemas and ingestion failures. This is particularly
problematic when using smaller models.
Optional:
[!TIP]
The simplest way to install Neo4j is via Neo4j Desktop. It provides a user-friendly
interface to manage Neo4j instances and databases.
Alternatively, you can use FalkorDB on-premises via Docker and instantly start with the quickstart example:
> docker run -p 6379:6379 -p 3000:3000 -it --rm falkordb/falkordb:latest
pip install graphiti-core
or
uv add graphiti-core
If you plan to use FalkorDB as your graph database backend, install with the FalkorDB extra:
pip install graphiti-core[falkordb]
or with uv
uv add graphiti-core[falkordb]
or embedded version (requires Python 3.12+)
pip install graphiti-core[falkordblite]
or with uv
uv add graphiti-core[falkordblite]
[!WARNING]
Kuzu is deprecated and will be removed in a future release — the upstream Kuzu project is no longer
maintained. New projects should use Neo4j or FalkorDB. The driver still ships for now but emits a
DeprecationWarning.If you plan to use Kuzu as your graph database backend, install with the Kuzu extra:
pip install graphiti-core[kuzu]
or with uv
uv add graphiti-core[kuzu]
If you plan to use Amazon Neptune as your graph database backend, install with the Amazon Neptune extra:
pip install graphiti-core[neptune]
or with uv
uv add graphiti-core[neptune]
# Install with Anthropic support
pip install graphiti-core[anthropic]
Install with Groq support
pip install graphiti-core[groq]
Install with Google Gemini support
pip install graphiti-core[google-genai]
Install with multiple providers
pip install graphiti-core[anthropic,groq,google-genai]
Install with FalkorDB and LLM providers
pip install graphiti-core[falkordb,anthropic,google-genai]
Install with Amazon Neptune
pip install graphiti-core[neptune]
Graphiti's ingestion pipelines are designed for high concurrency. By default, concurrency is set low to avoid LLM Provider 429 Rate Limit Errors. If you find Graphiti slow, please increase concurrency as described below.
Concurrency controlled by the SEMAPHORE_LIMIT environment variable. By default, SEMAPHORE_LIMIT is set to 10
concurrent operations to help prevent 429 rate limit errors from your LLM provider. If you encounter such errors, try
lowering this value.
If your LLM provider allows higher throughput, you can increase SEMAPHORE_LIMIT to boost episode ingestion
performance.
[!IMPORTANT]
Graphiti defaults to using OpenAI for LLM inference and embedding. Ensure that an OPENAI_API_KEY is set in your
environment.
Support for Anthropic, Gemini, and Groq is available, too. Other LLM providers — both hosted OpenAI-compatible APIs
(DeepSeek, Together, OpenRouter, …) and local servers (Ollama, vLLM, llama.cpp, LM Studio) — may be used via their
OpenAI-compatible endpoints; see
Using Graphiti with OpenAI-compatible providers and local LLMs.
For a complete working example, see the Quickstart Example in the examples directory. The quickstart demonstrates:
1. Connecting to a Neo4j, Amazon Neptune, FalkorDB, or Kuzu database 2. Initializing Graphiti indices and constraints 3. Adding episodes to the graph (both text and structured JSON) 4. Searching for relationships (edges) using hybrid search 5. Reranking search results using graph distance 6. Searching for nodes using predefined search recipes
The example is fully documented with clear explanations of each functionality and includes a comprehensive README with setup instructions and next steps.
You can use Docker Compose to quickly start the required services:
docker compose up
This will start the Neo4j Docker service and related components.
docker compose --profile falkordb up
This will start the FalkorDB Docker service and related components.
The mcp_server directory contains a Model Context Protocol (MCP) server implementation for Graphiti. This server
allows AI assistants to interact with Graphiti's context graph capabilities through the MCP protocol.
Key features of the MCP server include:
For detailed setup instructions and usage examples, see the MCP server README.
The server directory contains an API service for interacting with the Graphiti API. It is built using FastAPI.
Please see the server README for more information.
In addition to the Neo4j and OpenAi-compatible credentials, Graphiti also has a few optional environment variables. If you are using one of our supported models, such as Anthropic or Voyage models, the necessary environment variables must be set.
Database names are configured directly in the driver constructors:
neo4j (hardcoded in Neo4jDriver)default_db (hardcoded in FalkorDriver)graph_driver parameter.
from graphiti_core import Graphiti
from graphiti_core.driver.neo4j_driver import Neo4jDriver
Create a Neo4j driver with custom database name
driver = Neo4jDriver(
    uri="bolt://localhost:7687",
    user="neo4j",
    password="password",
    database="my_custom_database"  # Custom database name
)
Pass the driver to Graphiti
graphiti = Graphiti(graph_driver=driver)
from graphiti_core import Graphiti
from graphiti_core.driver.falkordb_driver import FalkorDriver
Create a FalkorDB driver with custom database name
driver = FalkorDriver(
    host="localhost",
    port=6379,
    username="falkor_user",  # Optional
    password="falkor_password",  # Optional
    database="my_custom_graph"  # Custom database name
)
Or use embedded FalkorDB Lite (requires Python 3.12+)
from redislite.async_falkordb_client import AsyncFalkorDB
falkordb_client = AsyncFalkorDB(dbfilename='/path/to/database.db')
driver = FalkorDriver(falkor_db=falkordb_client)
Pass the driver to Graphiti
graphiti = Graphiti(graph_driver=driver)
[!WARNING]
Kuzu is deprecated (upstream project unmaintained) and will be removed in a future release. Prefer Neo4j or
FalkorDB.
from graphiti_core import Graphiti
from graphiti_core.driver.kuzu_driver import KuzuDriver
Create a Kuzu driver
driver = KuzuDriver(db="/tmp/graphiti.kuzu")
Pass the driver to Graphiti
graphiti = Graphiti(graph_driver=driver)
from graphiti_core import Graphiti
from graphiti_core.driver.neptune_driver import NeptuneDriver
Create a Neptune driver
driver = NeptuneDriver(
    host='<NEPTUNE_ENDPOINT>',
    aoss_host='<AMAZON_OPENSEARCH_SERVERLESS_HOST>',
    port=8182,      # Optional, defaults to 8182
    aoss_port=443,  # Optional, defaults to 443
)
Pass the driver to Graphiti
graphiti = Graphiti(graph_driver=driver)
Contributing a new graph backend? See Adding a graph driver.
Graphiti supports Azure OpenAI for both LLM inference and embeddings using Azure's OpenAI v1 API compatibility layer.
from openai import AsyncOpenAI
from graphiti_core import Graphiti
from graphiti_core.llm_client.azure_openai_client import AzureOpenAILLMClient
from graphiti_core.llm_client.config import LLMConfig
from graphiti_core.embedder.azure_openai import AzureOpenAIEmbedderClient
Initialize Azure OpenAI client using the standard OpenAI client
with Azure's v1 API endpoint
azure_client = AsyncOpenAI(
    base_url="https://your-resource-name.openai.azure.com/openai/v1/",
    api_key="your-api-key",
)
Create LLM and Embedder clients
llm_client = AzureOpenAILLMClient(
    azure_client=azure_client,
    config=LLMConfig(model="gpt-5-mini", small_model="gpt-5-mini")  # Your Azure deployment name
)
embedder_client = AzureOpenAIEmbedderClient(
    azure_client=azure_client,
    model="text-embedding-3-small"  # Your Azure embedding deployment name
)
Initialize Graphiti with Azure OpenAI clients
graphiti = Graphiti(
    "bolt://localhost:7687",
    "neo4j",
    "password",
    llm_client=llm_client,
    embedder=embedder_client,
)
Now you can use Graphiti with Azure OpenAI
Key Points:
AsyncOpenAI client with Azure's v1 API endpoint format:https://your-resource-name.openai.azure.com/openai/v1/
gpt-5-mini, text-embedding-3-small) should match your Azure OpenAI deployment namesexamples/azure-openai/ for a complete working exampleGraphiti supports Google's Gemini models for LLM inference, embeddings, and cross-encoding/reranking. To use Gemini, you'll need to configure the LLM client, embedder, and the cross-encoder with your Google API key.
Install Graphiti:
uv add "graphiti-core[google-genai]"
or
pip install "graphiti-core[google-genai]"
from graphiti_core import Graphiti
from graphiti_core.llm_client.gemini_client import GeminiClient, LLMConfig
from graphiti_core.embedder.gemini import GeminiEmbedder, GeminiEmbedderConfig
from graphiti_core.cross_encoder.gemini_reranker_client import GeminiRerankerClient
Google API key configuration
api_key = ""
Initialize Graphiti with Gemini clients
graphiti = Graphiti(
    "bolt://localhost:7687",
    "neo4j",
    "password",
    llm_client=GeminiClient(
        config=LLMConfig(
            api_key=api_key,
            model="gemini-2.0-flash"
        )
    ),
    embedder=GeminiEmbedder(
        config=GeminiEmbedderConfig(
            api_key=api_key,
            embedding_model="embedding-001"
        )
    ),
    cross_encoder=GeminiRerankerClient(
        config=LLMConfig(
            api_key=api_key,
            model="gemini-2.5-flash-lite"
        )
    )
)
Now you can use Graphiti with Google Gemini for all components
The Gemini reranker uses the gemini-2.5-flash-lite model by default, which is optimized for
cost-effective and low-latency classification tasks. It uses the same boolean classification approach as the OpenAI
reranker, leveraging Gemini's log probabilities feature to rank passage relevance.
Graphiti can use any OpenAI-compatible /v1 endpoint for LLM inference via OpenAIGenericClient — both hosted
providers (DeepSeek, Together, OpenRouter, Fireworks, etc.) and local servers (Ollama, vLLM, llama.cpp, LM
Studio). Local servers are ideal for privacy-focused applications or avoiding API costs. The example below uses Ollama;
for any other provider, point base_url at its endpoint and set the appropriate api_key and model.
Note: Use OpenAIGenericClient (not OpenAIClient) for these endpoints. It is optimized for local models with a
higher default max token limit (16K vs 8K) and handles structured outputs across compatible providers.
Install the models:
ollama pull deepseek-r1:7b # LLM
ollama pull nomic-embed-text # embeddings
from graphiti_core import Graphiti
from graphiti_core.llm_client.config import LLMConfig
from graphiti_core.llm_client.openai_generic_client import OpenAIGenericClient
from graphiti_core.embedder.openai import OpenAIEmbedder, OpenAIEmbedderConfig
from graphiti_core.cross_encoder.openai_reranker_client import OpenAIRerankerClient
Configure Ollama LLM client
llm_config = LLMConfig(
    api_key="ollama",  # Ollama doesn't require a real API key, but some placeholder is needed
    model="deepseek-r1:7b",
    small_model="deepseek-r1:7b",
    base_url="http://localhost:11434/v1",  # Ollama's OpenAI-compatible endpoint
)
llm_client = OpenAIGenericClient(config=llm_config)
Initialize Graphiti with Ollama clients
graphiti = Graphiti(
    "bolt://localhost:7687",
    "neo4j",
    "password",
    llm_client=llm_client,
    embedder=OpenAIEmbedder(
        config=OpenAIEmbedderConfig(
            api_key="ollama",  # Placeholder API key
            embedding_model="nomic-embed-text",
            embedding_dim=768,
            base_url="http://localhost:11434/v1",
        )
    ),
    cross_encoder=OpenAIRerankerClient(client=llm_client, config=llm_config),
)
Now you can use Graphiti with local Ollama models
Ensure Ollama is running (ollama serve) and that you have pulled the models you want to use.
Graphiti depends on structured (JSON) output for entity/edge extraction and deduplication, and works best with models
and providers that reliably honor it (OpenAI, Anthropic, Gemini). Reliability varies across OpenAI-compatible providers and
especially on smaller or local models, so OpenAIGenericClient exposes a structured_output_mode:
"json_schema" (default): requests native structured output via response_format. Best on capable models and→ →
 →
 →
 →
 →
 →
 →