FoundationVision/Liquid is an open-source project on GitHub, mainly written in Python. (Accepted by IJCV) Liquid: Language Models are Scalable and Unified Multi-modal Generators It currently holds 640 stars and 36 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
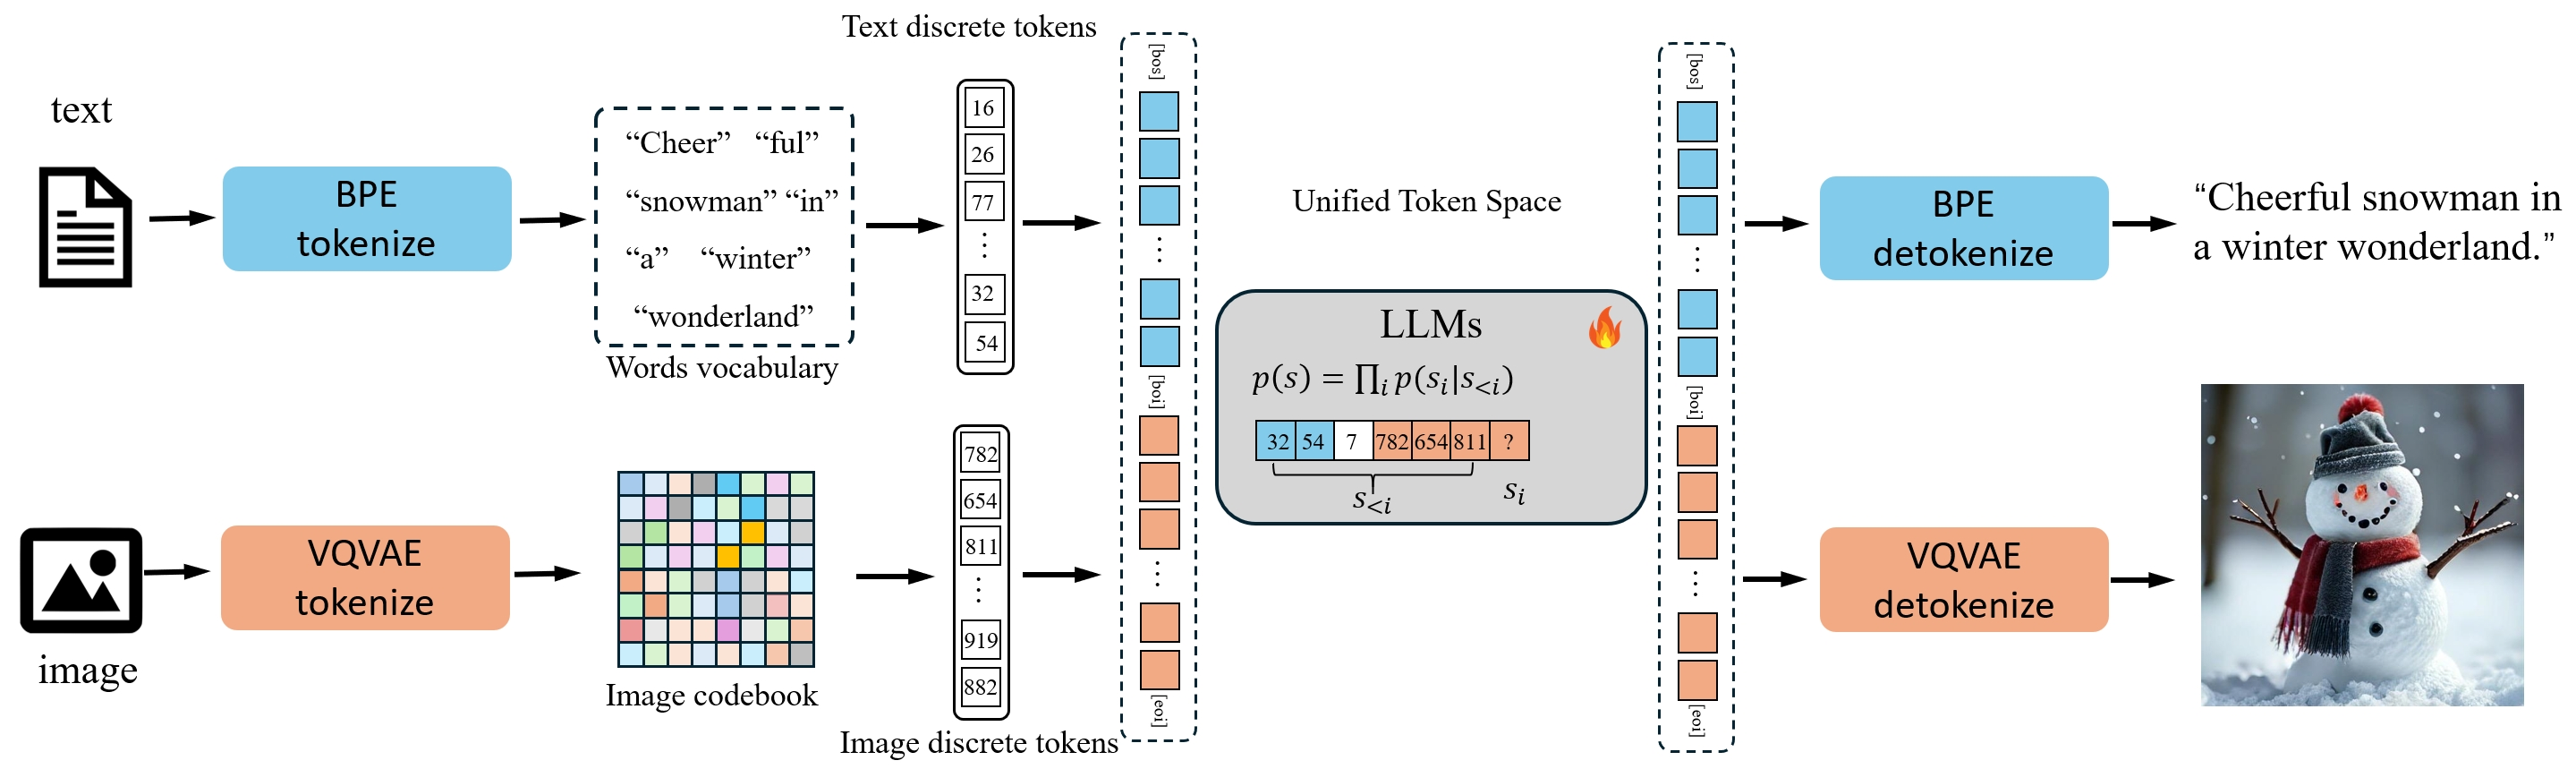
This repo implements Liquid, a scalable and unified autoregressive generation paradigm that seamlessly integrates multimodal comprehension and generation.
📰 News
2025-03-25: Data processing and model pretraining scripts have been updated in
Data.md and
TRAIN.md.
2025-03-04: Text-to-image and visual understanding evaluation scripts for Liquid are released in
EVAL.md.
2025-02-28: Paper, demo, model, and
project page for Liquid are all released.
📑 Open-Source Plan
- Liquid-7B-IT (Instruction Tuned Multimodal Model with Instruction Following Ability)
- [✅] Web Demo
- [✅] Evaluation
- [✅] Checkpoints
- [✅] Training Codes
- Liquid-0.5B~32B-Pretrain (Multimodal extension models of six different scales ranging from 0.5B to 32B across three model families. )
- [ ] Checkpoints
📽️Inference
Using Liquid for inference or evaluation doesn't require complex environment dependencies. Since it's essentially a HuggingFace format language model, you only need the
transformers library and some basic components to run it. Refer to
EVAL.md for recommended versions.
Run the Gradio Demo locally
If deploying on a GPU with less than 30GB VRAM, you may need to enable
load_in_8bit in
AutoModelForCausalLM.from_pretrained in
app.py for image generation to avoid out-of-memory errors.
```bash
pip install gradio==4.44.1
pip install gradio_client==1.3.0
cd evaluation
python app.py
```
Single inference
```bash
Engage in pure language dialogue.
python inference_t2t.py --model_path Junfeng5/Liquid_V1_7B --prompt "Write me a poem about Machine Learning."
image understanding
python inference_i2t.py --model_path Junfeng5/Liquid_V1_7B --image_path samples/baklava.png --prompt 'How to make this pastry?'
image generation, add --load_8bit for GPU with less than 30GB VRAM
python inference_t2i.py --model_path Junfeng5/Liquid_V1_7B --prompt "young blue dragon with horn lightning in the style of dd fantasy full body"
```
⚙️ Installation and Training
See
Data.md and
TRAIN.md.
📖 Introduction
- We present Liquid, an auto-regressive generation paradigm that seamlessly integrates visual comprehension and generation.
- Unlike previous multimodal large language model (MLLM), Liquid achieves this integration using a single large language model (LLM), eliminating the need for external pretrained visual embeddings such as CLIP.
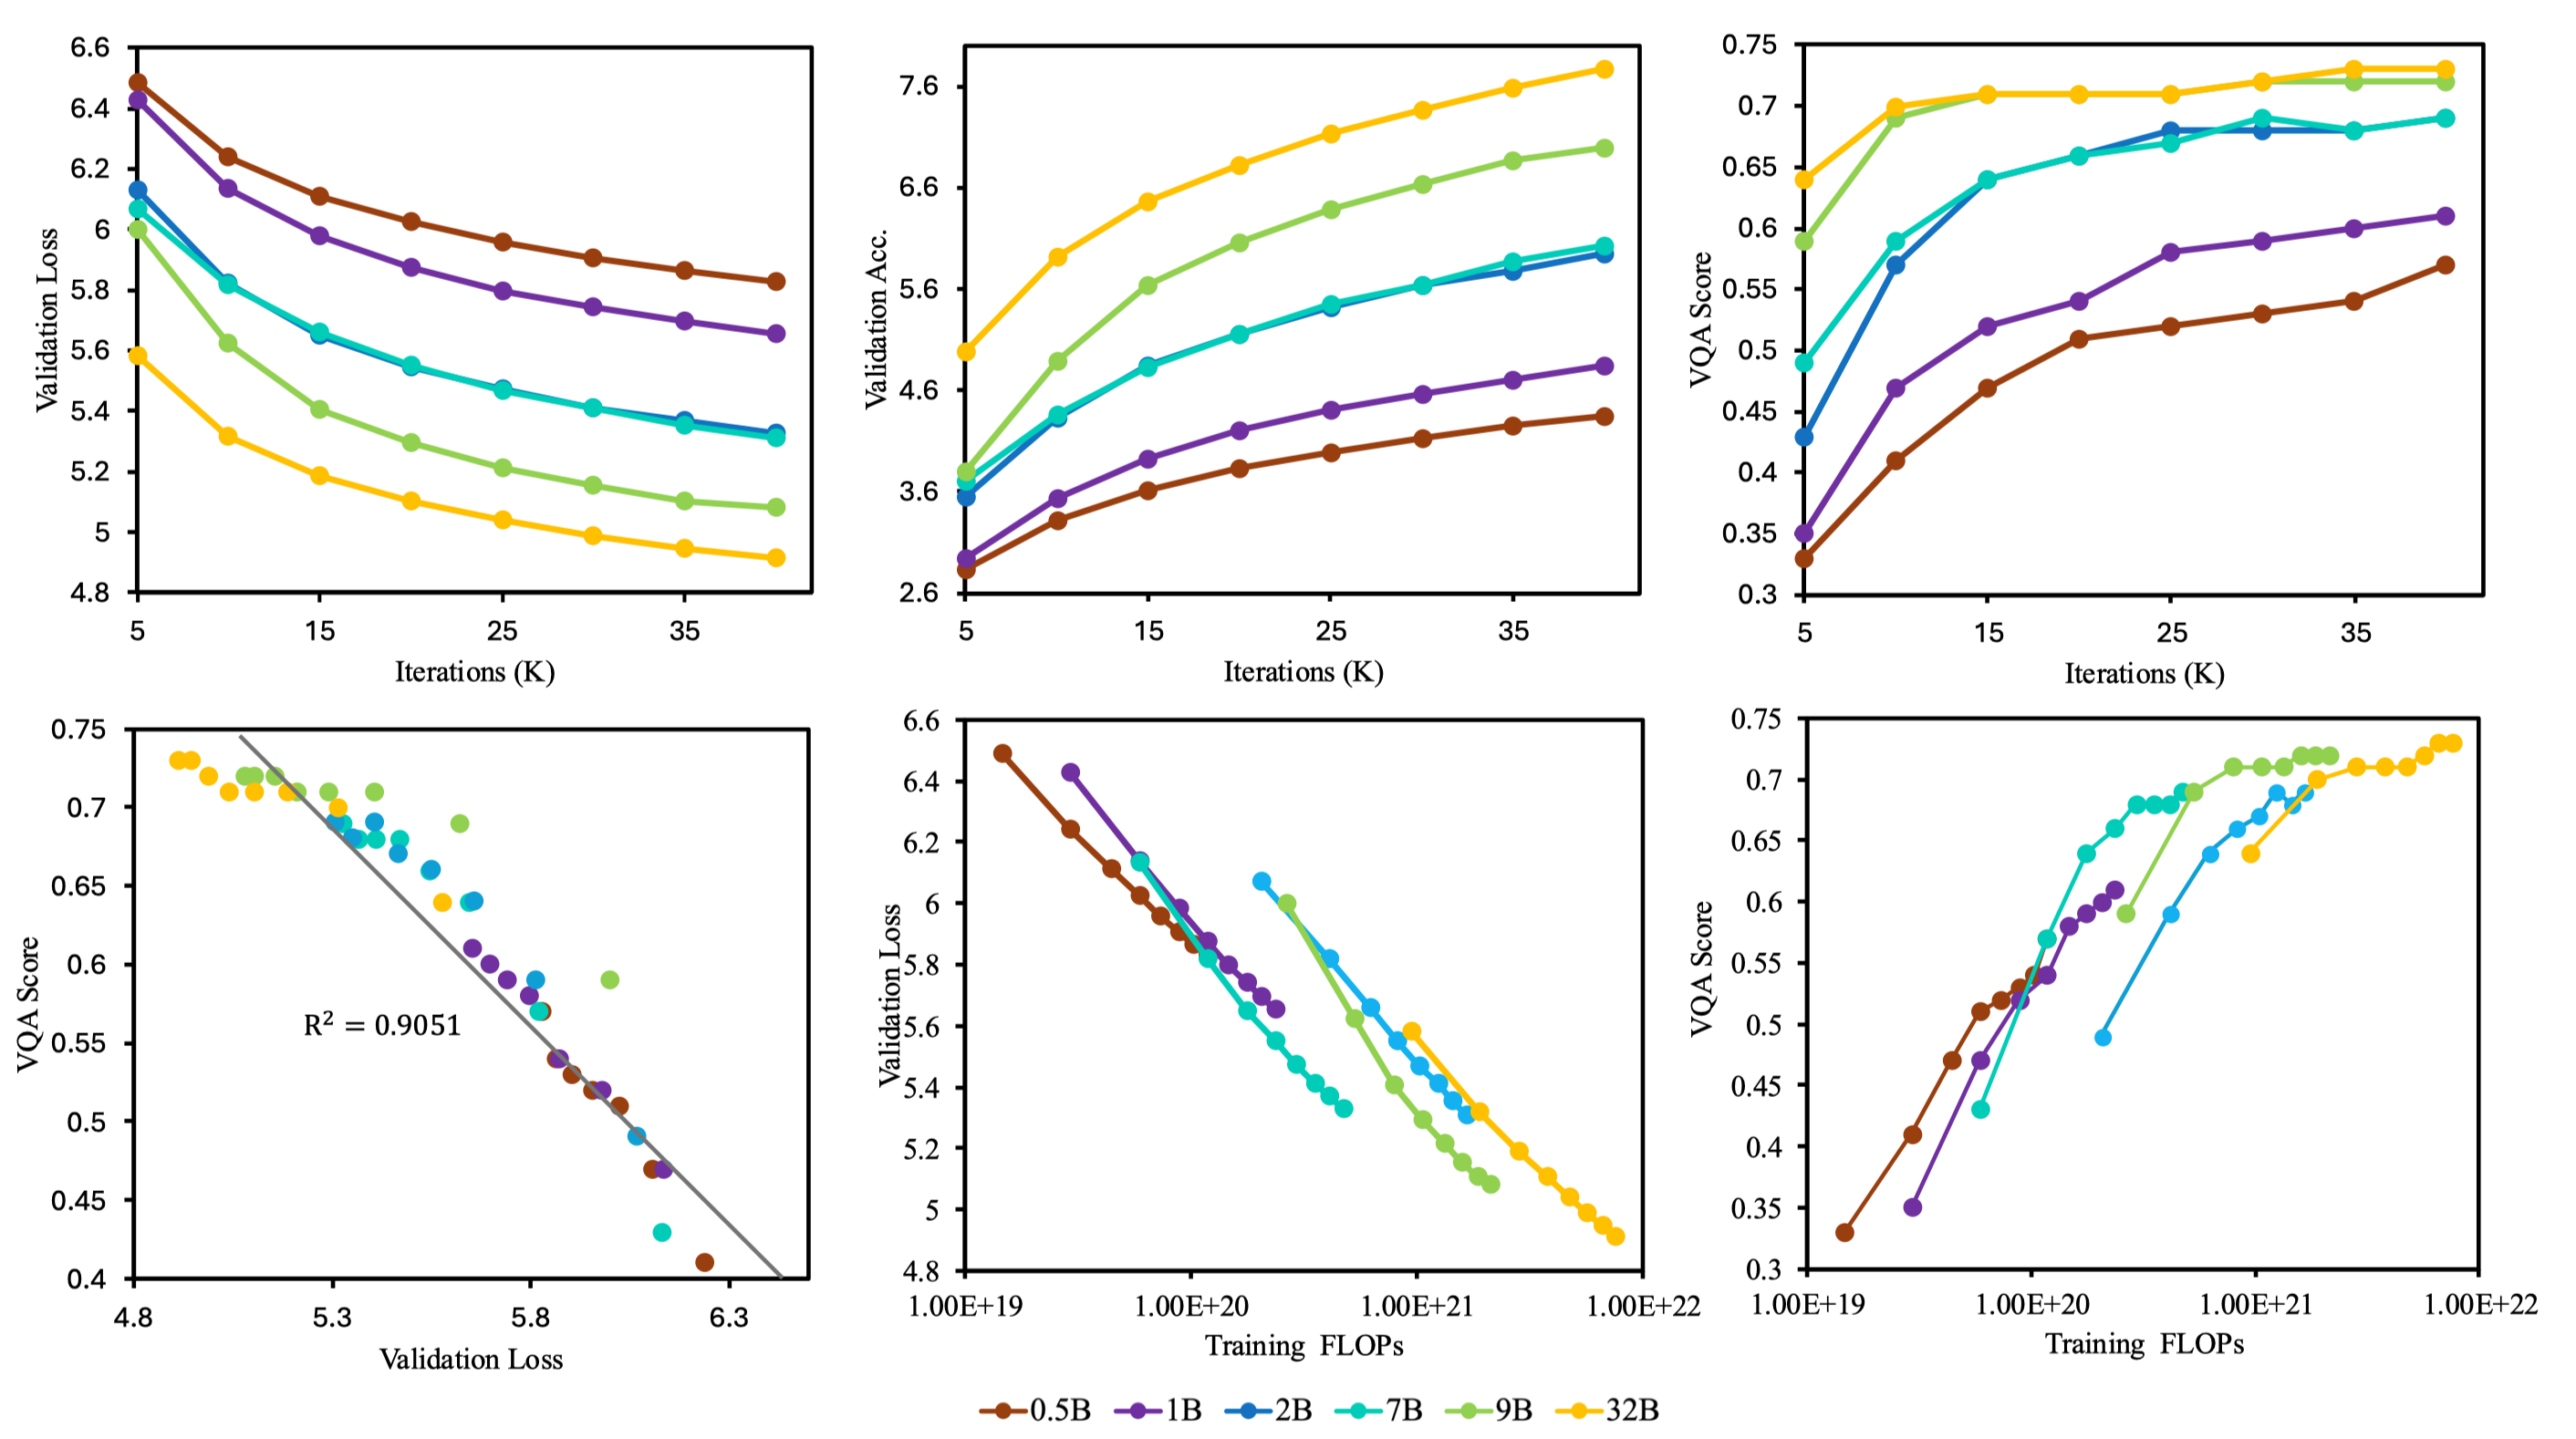
- For the first time, Liquid uncovers a scaling law that performance drop unavoidably brought by the unified training of visual and language tasks diminishes as the model size increases.
- Furthermore, the unified token space enables visual generation and comprehension tasks to mutually enhance each other
🔥 Multimodal Generation
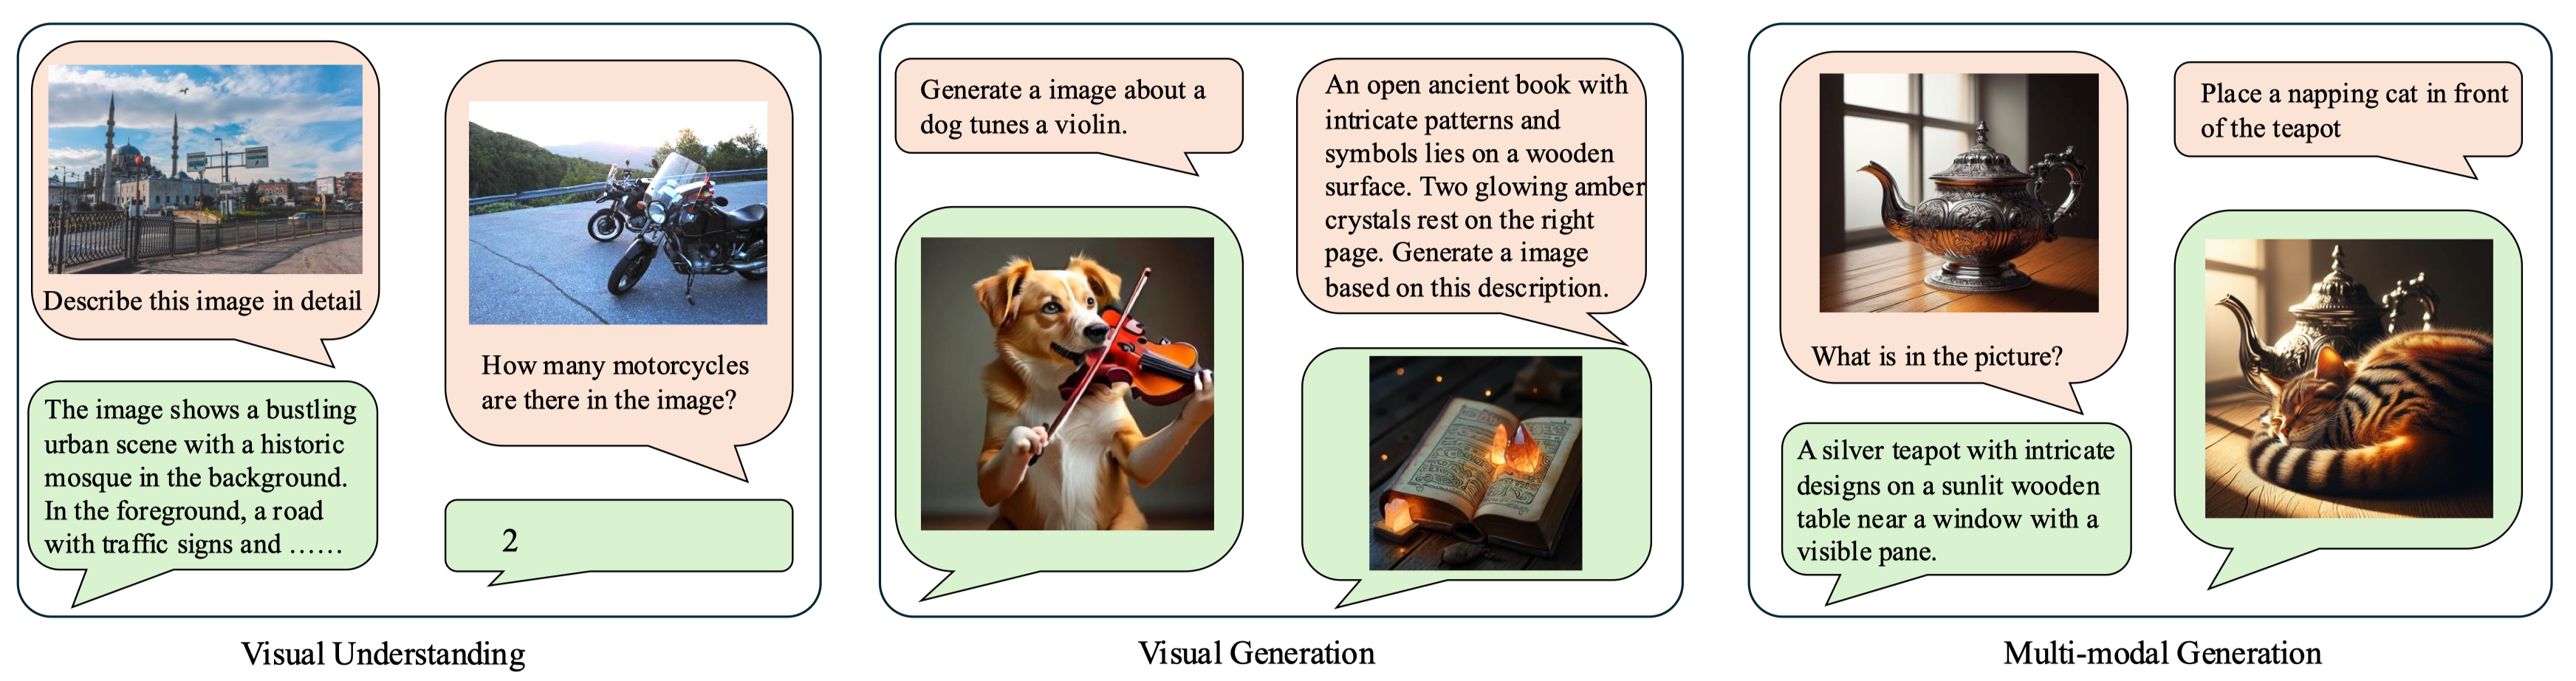
- Liquid : Scalable and Versatile Unified Multimodal Generator which supports Visual Understanding, Visual Generation and Multi-modal Generation
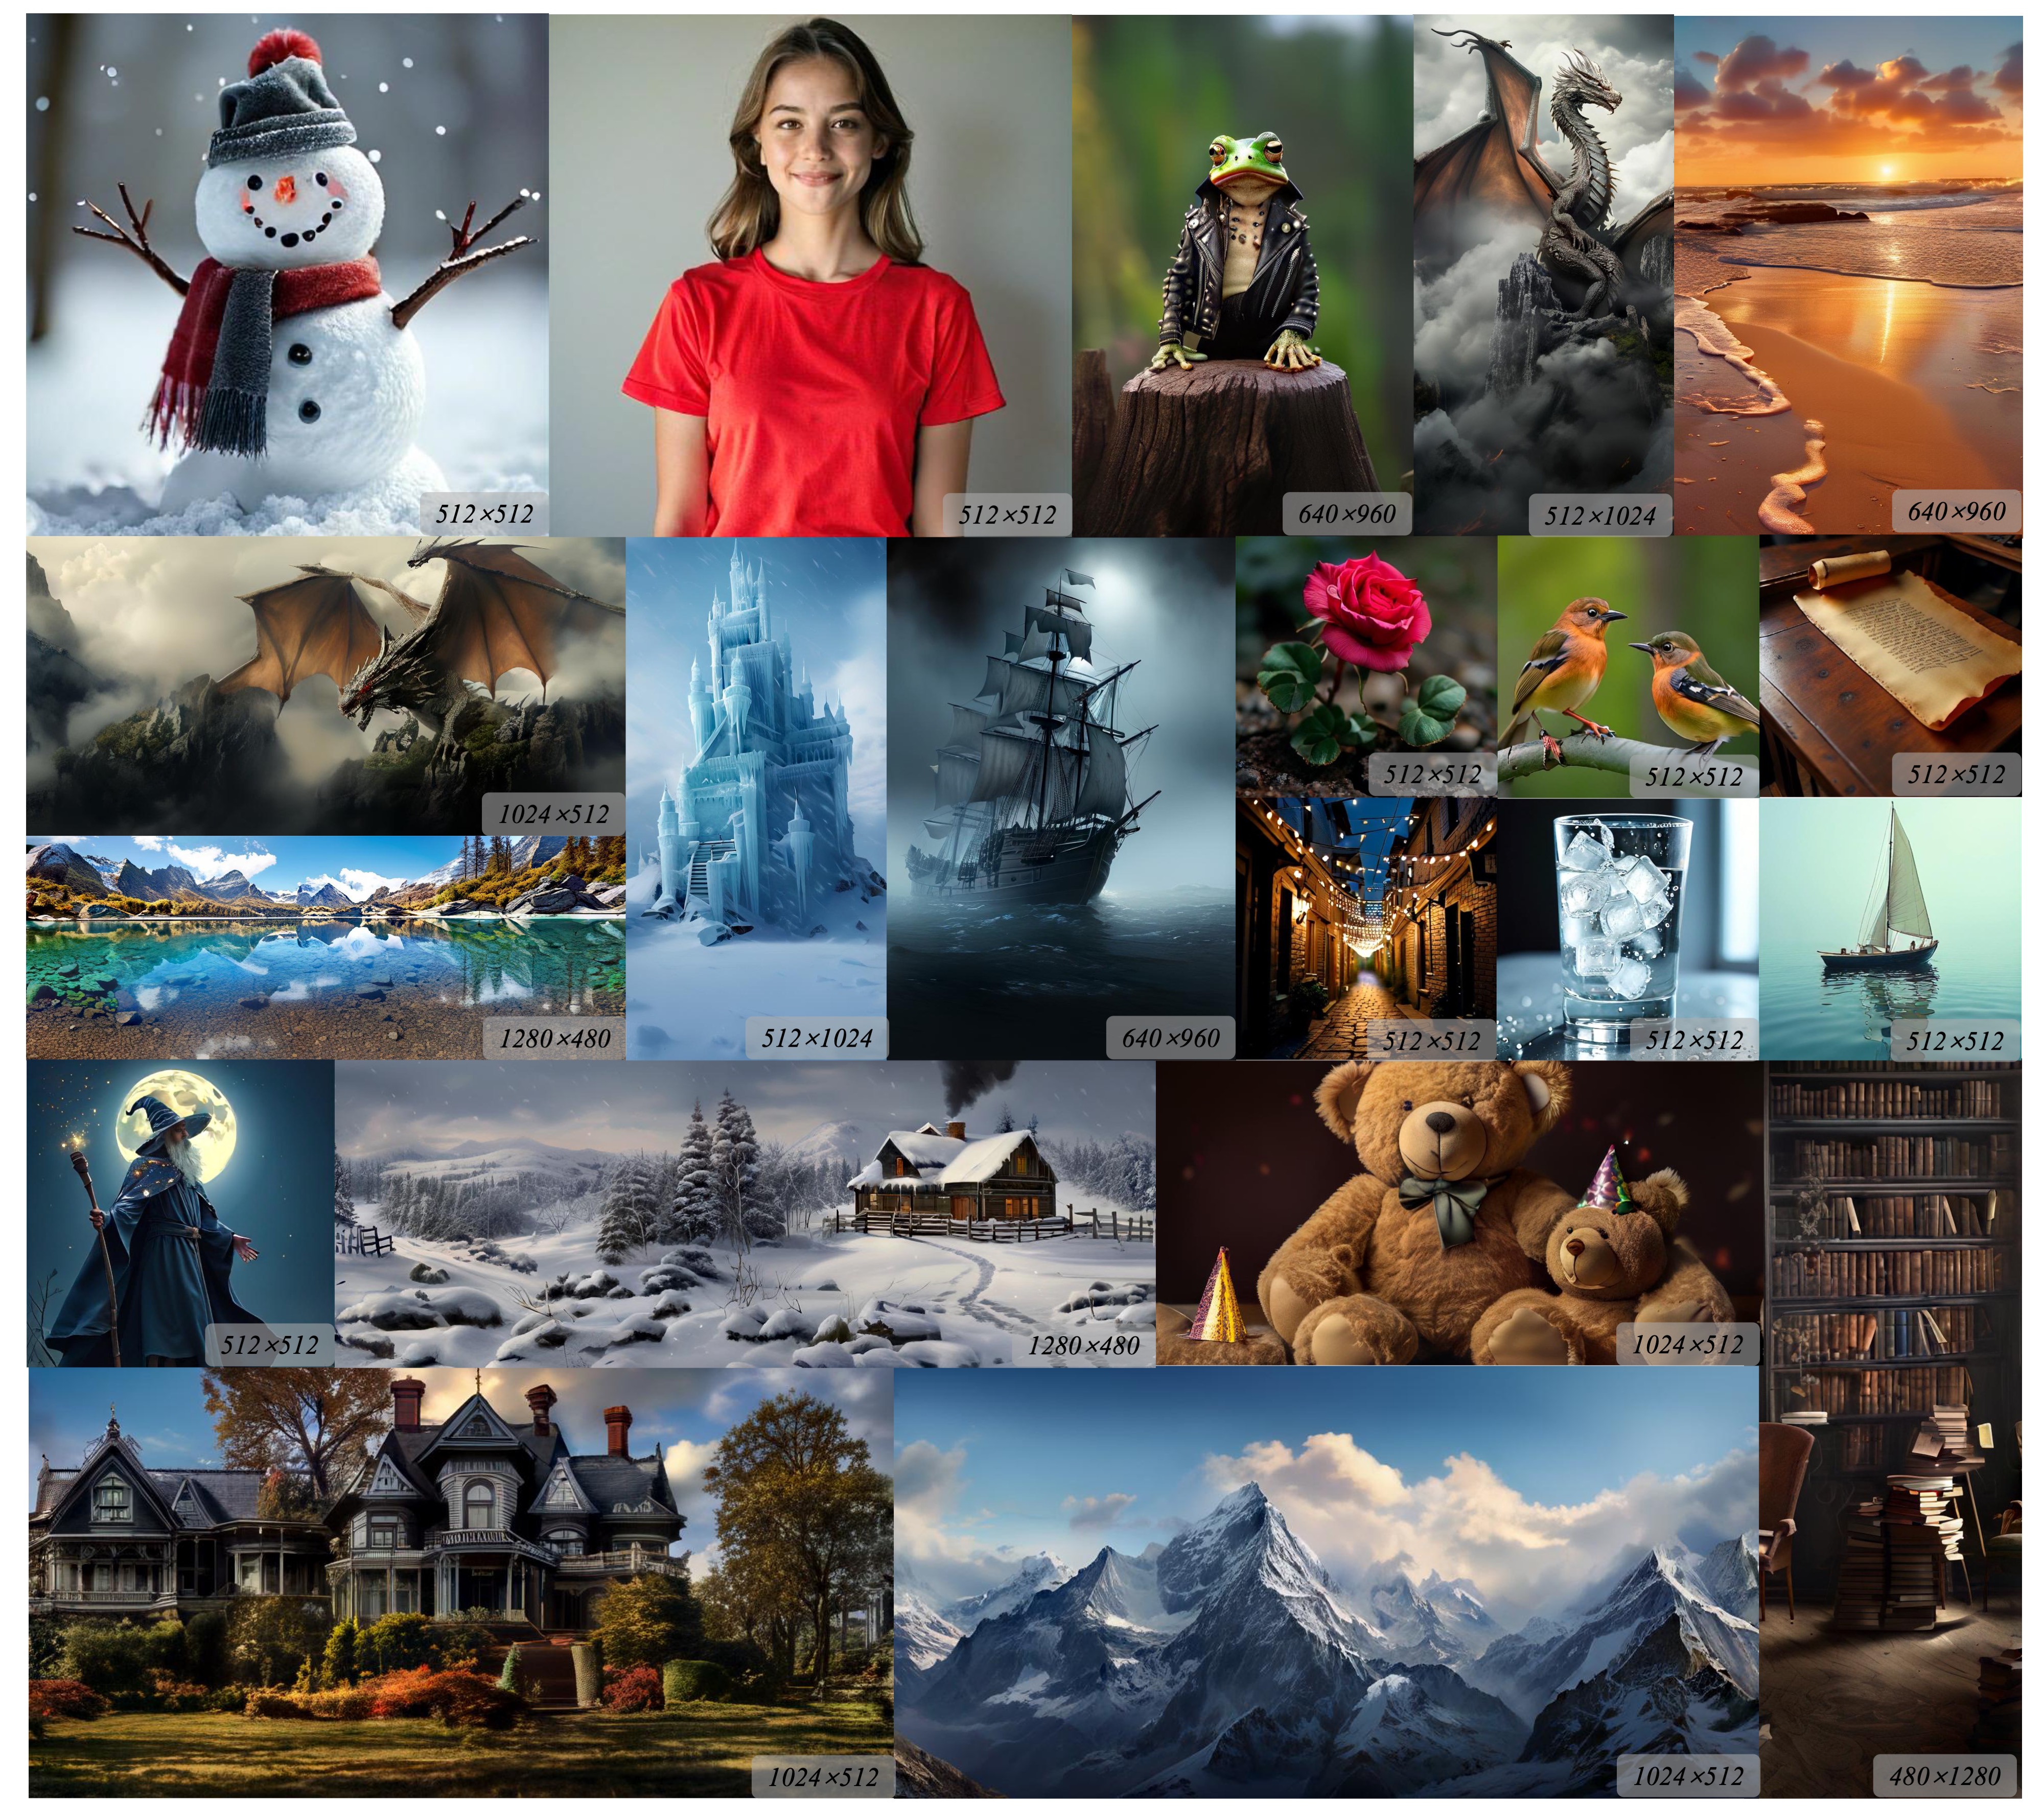
- Liquid can generate high-quality, photorealistic images of any aspect ratio by language in an autoregressive paradigm.
🔥 Scaling Law for multimodal generation
- Liquid shows clear Scaling Law in multimodal generation across different sizes(0.5B to 32B).
License
This project is licensed under the MIT License - see the
LICENSE file for details.
Citation
If you find this project useful, please consider citing:
```bibtex
@article{wu2026liquid,
title={Liquid: Language Models are Scalable and Unified Multi-Modal Generators},
author={Wu, Junfeng and Jiang, Yi and Ma, Chuofan and Liu, Yuliang and Zhao, Hengshuang and Yuan, Zehuan and Bai, Song and Bai, Xiang},
journal={International Journal of Computer Vision},
volume={134},
number={1},
year={2026},
publisher={Springer US New York}
}
```
 →

 →
 →
 →
 →
 →
 →