1
 →

Local proxy that compresses your LLM API requests so you pay less, with no change to the answers. Trims wasted tokens from prompts, history, tool output
fkiene/llmtrim is an open-source project on GitHub, mainly written in Rust. Local proxy that compresses your LLM API requests so you pay less, with no change to the answers. It currently holds 236 stars and 23 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Prompt Engineering board.
Local proxy that compresses LLM API traffic so you pay less. Same answers, smaller bill.
−31% input · −74% output · −66% round-trip cost · 112 live A/B cases · ~5 ms/call · no model to load
Using Claude Code? One install also gets you /sub
to serve it through CLIProxyAPI.
Proxy · CLI · MCP · library (Python · Ruby · Swift · Kotlin · JS/WASM)

What it does • Install • Day to day • In action • Works with • Claude Code • Numbers • Config • CLI & library
---
You run Claude Code, Codex, Cursor, or your own app. Every turn, the tool sends a large request: system prompt, tools, history, raw command output. You pay for every token of that, including the parts that do not help the model.
A 200-line build log with two errors. Tool schemas resent on every call. JSON with hundreds of near-identical rows. That bulk is still billed.
llmtrim sits on your machine as a local proxy, trims the waste, and forwards a smaller request. The reply is unchanged. You keep the same tools and answers; you spend less.
  before:  your tool ───── full request ─────▶  OpenAI / Anthropic / …
                    ◀──────── reply ──────────
after:   your tool ──▶ llmtrim ──smaller──▶  OpenAI / Anthropic / …
                            (on your machine)
                    ◀──────── reply ──────────  (same answer)
Compression cannot raise your bill or break a request; worst case is zero savings. Everything runs locally, nothing is sent to us. In action →
For Claude Code the same install also wires /sub to route sessions through another subscription. Details →
---
npm install -g @llmtrim/cli@latest && llmtrim setup
open a new terminal, then keep working
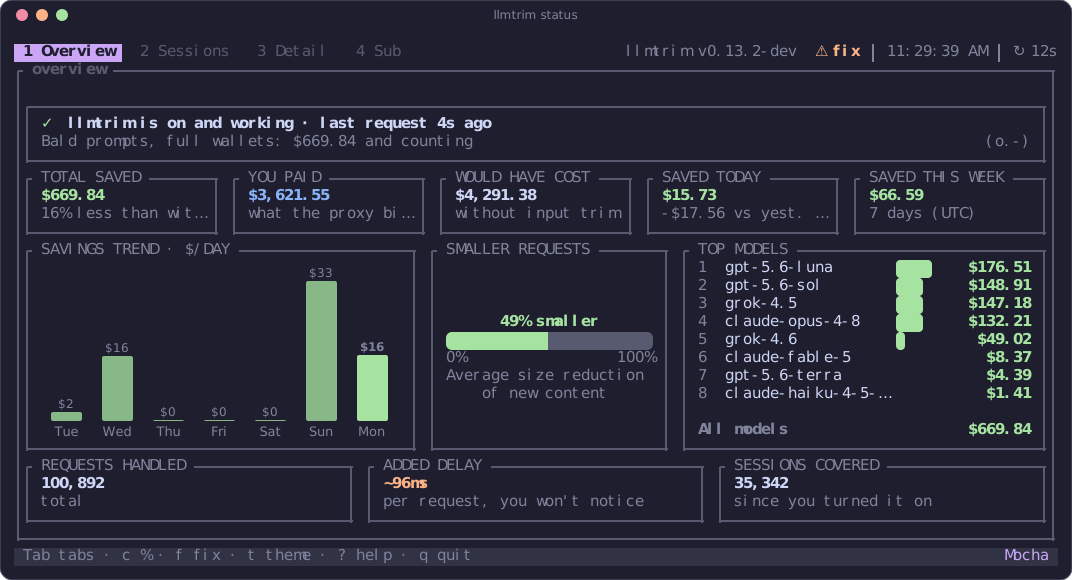
llmtrim status
That's it. setup starts a local proxy and wires your shell. When Claude Code is present, it also turns on /sub. You do not run a separate install for that.
| You want | Run |
|---|---|
| First install | llmtrim setup |
| New version | llmtrim update (then llmtrim ensure after npm/brew/cargo) |
| Something broken | llmtrim ensure · llmtrim doctor --fix · or f in status |
Any tool that honors HTTPS_PROXY works (Claude Code, Codex, Cursor, Aider, your SDK). GitHub Copilot does not (certificate pinning). Full list →
# Linux / macOS
curl -fsSL https://raw.githubusercontent.com/fkiene/llmtrim/main/install.sh | sh
Windows (PowerShell)
irm https://raw.githubusercontent.com/fkiene/llmtrim/main/install.ps1 | iex
Package managers
brew install fkiene/tap/llmtrim
cargo binstall llmtrim
scoop install llmtrim
docker run -d -p 43117:43117 -v llmtrim-state:/data ghcr.io/fkiene/llmtrim
Full options: INSTALL.md.
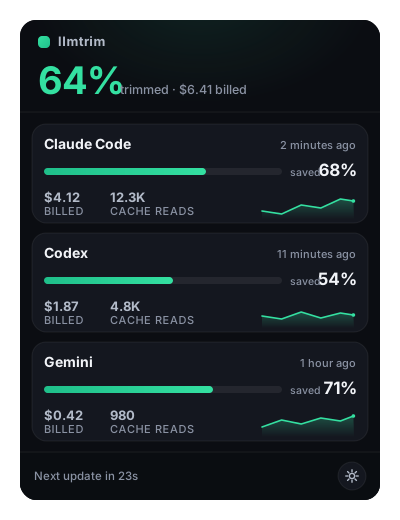
Menu-bar / system-tray popover with the same savings numbers. Bundled in Homebrew, Scoop, and npm; setup can enable open-at-login. Open with llmtrim tray. On Linux desktops, interactive ensure can fetch the tray binary from the latest release (needs libwebkit2gtk-4.1 and libayatana-appindicator3).
Same technique as mitmproxy, scoped to LLM API hosts only. setup changes three things; llmtrim uninstall reverses all three:
1. Private CA in ~/.llmtrim/ (name-constrained; cannot intercept your bank or email)
2. Shell env: HTTPS_PROXY + CA trust
3. Login service: daemon at login
No API keys stored (your tool's auth is forwarded). Prompts never touch disk; only anonymous token counts. Recoverable tool results stay in bounded daemon RAM for five hours by default and disappear on restart. Full threat model: SECURITY.md.
llmtrim ca
openssl x509 -in ~/.llmtrim/ca.pem -noout -text | grep -A3 "Name Constraints"
---
llmtrim status     # savings + health  (aliases: monitor, gain)
llmtrim update     # new release, restart daemon, refresh integrations
llmtrim ensure     # match the recommended install state on this machine
| Situation | Command |
|---|---|
| Watch savings | llmtrim status |
| After npm / brew / cargo upgrade | llmtrim ensure (or f in status) |
| Diagnose | llmtrim doctor · repair with doctor --fix |
| Pause / resume proxy | llmtrim stop · llmtrim start |
| Force one session through llmtrim | llmtrim wrap claude |
| Remove everything | llmtrim uninstall |
After setup, update, or ensure, owned Claude Code /sub stays in sync with the binary.
Time series: llmtrim status --daily · --weekly · --monthly · --json · --csv.
---
An agent ran a build. The tool returned 58 lines; two were errors. All 58 would have been billed.
4,662 chars → 978 (−79%). Errors stay verbatim. Repeated INFO lines fold into a template plus the values (lossless when the range is regular).
# before (noise + signal)
[2026-06-13T10:02:00Z] INFO  compiling module core::worker::task_0 (incremental)
… 28 more near-identical INFO lines …
[2026-06-13T10:02:31Z] ERROR src/worker/pool.rs:214: mismatched types: expected usize, found i64
… 25 more INFO lines …
[2026-06-13T10:03:01Z] ERROR src/net/conn.rs:88: cannot borrow buf as mutable more than once
[2026-06-13T10:03:02Z] INFO  build failed, 2 errors
after (errors verbatim; INFO folded losslessly)
[{}] INFO compiling module core::worker::task_{} (incremental) [×30: (10:02:00Z..10:02:29Z step 1s; 0..29)]
[2026-06-13T10:02:31Z] ERROR src/worker/pool.rs:214: mismatched types: expected usize, found i64
[{}] INFO compiling module core::net::conn_{} (incremental) [×25: 10:02:32Z..10:02:56Z; 0..24]
[2026-06-13T10:03:01Z] ERROR src/net/conn.rs:88: cannot borrow buf as mutable more than once
[2026-06-13T10:03:02Z] INFO  build failed, 2 errors
Try it on a request body of your own:
echo '{"model":"gpt-4o","messages":[...]}' | llmtrim compress --provider openai
Log folding is one stage. Others kick in on different waste:
| Waste | What happens | |---|---| | Build logs, diffs, grep dumps | Keep errors / changes / matches; fold the rest | | Long pasted context | Keep chunks relevant to the question | | Source code | Keep useful bodies; rest → signatures | | Tool schemas every turn | Trim + keep the cache prefix stable | | Huge JSON arrays | Compact table (TOON) or sample | | Verbose model replies | Ask for terser output where safe |
[!IMPORTANT]
Compression cannot raise your bill or break a request. Each stage is re-measured with the provider's real tokenizer and undone if it does not save tokens. If the provider rejects the compressed body, the original is resent. Worst case is zero savings.
Existing prompt-cache prefixes (cache_control) are left alone. First-arrival recoverable shaping (llmtrim recall r_…) is off by default; live-zone tool-output windowing still runs, and a re-run of the same tool ships in full. To skip shaping for a command (verbatim stdout, including a terminal trailer), set toolout_passthrough = ["gpt.sh"] or prefix the command with LLMTRIM_TOOL_OUTPUT=passthrough. Lines starting with LLMTRIM_KEEP: survive windowing even when the rest is clipped.
Stages run in savings order. Nothing under a cache_control marker is rewritten.
| Stage | What it does | When it runs |
|---|---|---|
| tool-output | Lossless template fold first, then window logs · diffs · grep · dumps down to errors / changes / matches; opt-in first-arrival recall can restore omitted cache-boundary results with llmtrim recall | tool results |
| cache discipline | Mark + stabilize the invariant prefix (sort tools/schema · OpenAI prompt_cache_key) so it stays cached | tools |
| lexical retrieval | BM25+ ranking with RM3 feedback · TextTiling topic cuts · budgeted non-redundant selection; question protected | long context |
| skeletonization | tree-sitter keeps relevant function bodies, drops the rest to signatures (14 languages) | code |
| serialize + hygiene | Minify JSON, encode record arrays to TOON or CSV, Unicode-normalize | always · lossless |
| json sample | Down-sample huge record arrays: first/last + outliers + a query-biased diverse sample | big JSON |
| dedup | Collapse duplicate + near-duplicate lines (prose only) | always |
| output control | Terse instruction · Chain-of-Draft · token budget · native JSON schema · anti-overthink directive (quantized reasoning) · agent-loop frugality directive | auto |
| tool layer | Static tool selection + description trimming | tools |
| multimodal | Downscale images to the provider's resolution cap | images |
Default auto enables each stage only where it pays. safe is lossless-only. Config →
---
When ~/.claude exists, setup, update, and ensure wire /sub (and routed subagents). No separate install command for that.
| Feature | What you get |
|---|---|
| /sub | Per-window: /sub on [optional:codex\|kimi\|grok] · /sub off · /sub status |
sub) (opt-in; may conflict with provider ToS)Send Claude Code through CLIProxyAPI instead of Anthropic, or as a fallback hop when the current path fails. Login is CLIProxyAPI's TUI; decide for yourself whether that fits the provider ToS.
llmtrim sub on                  # install + start CLIProxyAPI, enable redirect
llmtrim sub on grok             # write opus/sonnet/haiku/fable → that CLI's models
llmtrim sub auth                # CLIProxyAPI TUI — sign in
llmtrim sub models              # official + live sidecar models
llmtrim sub map on opus grok-4.6
llmtrim sub chain anthropic,codex
llmtrim sub mode fallback       # try hops in order when the current one fails
llmtrim sub status
llmtrim sub off
Interactive: llmtrim status → tab 4 Sub — Off / Always / Fallback, then e to edit the
input→output map (type to search CLIProxyAPI's catalog;
s save, a add, d delete). [ ] rotate the fallback first hop.
llmtrim update also updates CLIProxyAPI when you use it. Point LLMTRIM_CLIPROXY_URL at an
existing instance to skip the managed sidecar.
Route only a delegated Claude Code subagent while leaving the parent window unchanged:
llmtrim agents install # also installed/refreshed by setup, update, and ensure
Then ask naturally: Implement it using a Grok subagent, use Terra, or review this with GPT Terra.
Provider-only agents preserve the child request's Claude tier through the configured mapping; an
explicit model agent pins that provider model. Request-local agents override the window /sub and
global policy only for their own requests. llmtrim agents uninstall removes only llmtrim-owned
agent files and records an opt-out so ensure leaves them removed.
This window only (installed with ensure; includes subagents; survives /clear):
/sub on [optional:cli-or-model]  # gemini, codex, claude, grok, kimi, vertex, qwen, copilot, or a model id
/sub off
/sub status
Sidecar: ~/.llmtrim/cliproxy/ (binary + config). Auth: ~/.cli-proxy-api when present, else
~/.llmtrim/cliproxy/auth. Env: LLMTRIM_SUB, LLMTRIM_SUB_MODE, LLMTRIM_CLIPROXY_URL,
LLMTRIM_CLIPROXY_KEY.
Anthropic /login vs claude.ai connectors: with global sub in always mode, by
default llmtrim writes a dummy ANTHROPIC_AUTH_TOKEN into ~/.claude/settings.json (same
idea as claude-code-proxy's
ANTHROPIC_AUTH_TOKEN=unused) so Claude Code does not need a live Anthropic OAuth session.
The MITM strips that dummy token and sends /v1/messages to CLIProxyAPI; non-messages
Anthropic probes are answered locally so they never return 401 Invalid bearer token.
Claude Code treats any API-key auth as overriding claude.ai login, so claude.ai connectors
are disabled while the dummy token is set. That is expected. To keep connectors (and accept
Anthropic /login when the session expires):
llmtrim sub anthropic-login keep   # connectors OK; Anthropic login required
llmtrim sub anthropic-login skip   # default: no Anthropic /login; connectors off
Restart Claude Code after sub on / sub off / sub mode / sub anthropic-login for the
settings change to take effect. Fallback whose first hop is "what's in use" still needs a real
Anthropic login.
---
Same engine, no proxy required. No extra model calls; compress runs in-process.
| Language | Install |
|---|---|
| Rust | cargo add llmtrim-core |
| Python | pip install llmtrim |
| Ruby | gem install llmtrim |
| Kotlin | implementation("io.github.fkiene:llmtrim:0.13.7") |
| Swift | SwiftPM fkiene/llmtrim-swift ≥ 0.1.8 |
| JS / TS | @llmtrim/js (WASM) |
echo '{"model":"gpt-4o","messages":[...]}' | llmtrim compress --provider openai > out.json
echo '{"model":"gpt-4o","messages":[...]}' | llmtrim send --provider openai
use llmtrim_core::{compress, ir::ProviderKind};
let out = compress(request_json, Some(ProviderKind::OpenAi))?;
import llmtrim
out = llmtrim.compress(request_json, llmtrim.Provider.OPEN_AI, "aggressive")
import { compress } from "@llmtrim/js";
const out = compress(requestJson, "openai", "aggressive");
Bindings and WASM notes: crates/llmtrim-uniffi · crates/llmtrim-wasm.
llmtrim mcp install          # Claude Code
llmtrim mcp install --print  # paste into any client
{
  "mcpServers": {
    "llmtrim": { "command": "llmtrim", "args": ["mcp"] }
  }
}
Tools: llmtrim_compress, llmtrim_compress_text, llmtrim_stats (same ledger as status).
Any tool that honors HTTPS_PROXY and an env-provided CA:
| Tool | Works | Notes |
|---|:---:|---|
| Claude Code | ✅ | Prompt-cache discount stays intact |
| Codex CLI | ✅ | |
| Gemini CLI | ✅ | |
| Cursor (IDE), Cline, Roo, Kilo Code | ✅ | VS Code extensions; set NODE_EXTRA_CA_CERTS for the Node host process |
| Goose, OpenCode, Crush, Mux, Forge, OpenClaw, Pi/OMP | ✅ | CLI agents on standard provider hosts |
| Qwen Code, Grok CLI, Kimi Code, Mistral Vibe | ✅ | Provider hosts ship in the llm_providers registry, intercepted out of the box |
| Aider, any other HTTPS_PROXY-aware CLI | ✅ | |
| Hermes, Droid (BYOK mode) | ✅ | Interceptable only when a direct provider key is configured; see guide for Hermes |
| Your own app / SDK | ✅ | Or call the CLI / library directly |
| GitHub Copilot | ❌ | Certificate pinning blocks interception |
| Warp, Devin | ❌ | Provider call is server-side; a local proxy never sees it |
| Cursor Agent, Kiro | ❌ | Routes through a vendor gateway, not a standard provider host |
No proxy: any MCP client can call llmtrim as tools (llmtrim mcp install), or use the CLI / library.
Providers come from the llm_providers registry (OpenAI, Anthropic, Google, DeepSeek, Mistral, xAI, Moonshot, Zhipu, Qwen, OpenRouter, …) and update with it. Non-LLM connections pass through untouched.
Default is fine for most traffic. auto inspects each request and picks compressors by shape (tools → agent, code → code, long Q&A → rag, else aggressive).
Override with LLMTRIM_PRESET= or preset = "" in $XDG_CONFIG_HOME/llmtrim/config.toml:
| preset | When to use |
| --- | --- |
| auto (default) | Let llmtrim choose per request |
| safe | Lossless input only |
| aggressive | Max squeeze, quality-gated |
auto composes these per request shape, so most users never set them directly. Pick one when you know your traffic and want to skip shape detection:
| preset | for |
| --- | --- |
| agent | tool-calling loops: prunes the tool block first-turn-only so the prompt cache stays warm |
| code | coding turns: skeletonize and minify code, compress pasted logs and diffs |
| rag | long context with a question: sentence-level retrieval |
| cache | a fixed prefix reused across many calls |
| reasoning | math and step-by-step workloads |
| frugal | isolates the agent-loop frugality directive alone, for clean benchmarking |
Every stage is individually tunable via config flags; preset wins over individual flags. The full table is long; see the field list in config.rs or run llmtrim compress --help. The most useful knobs:
| field | default | meaning |
| --- | --- | --- |
| toolout | on in agent/aggressive | tool-output compression (logs / diffs / grep / dumps) |
| retrieve | false | lexical retrieval for long context (lossy) |
| skeletonize | false | drop non-relevant function bodies to signatures |
| serialize | true | TOON / CSV encoding of record arrays |
| json_crush | on in agent/aggressive | sample huge record arrays |
| output_control | false | terse-output instruction + cap |
| output_anti_overthink | on in aggressive/rag/code/agent | commit-to-answer directive for quantized reasoning traffic |
| output_frugal_tools | on in agent | steers agent loops toward fewer tool-call turns (batch, don't repeat) |
| cache | false | cache_control breakpoints (lossless) |
| dedup | true | collapse duplicate lines (lossless) |
| quality_gate | true | revert any lossy cut whose query-relevant coverage drops too far |
Env: LLMTRIM_PRESET (preset), LLMTRIM_CONFIG (config-file path).
These knobs are orthogonal to compression. Each resolves env-first, then from the config file, so set whichever fits. The env var wins when both are present.
| env var | config key | meaning |
| --- | --- | --- |
| LLMTRIM_EXTRA_HOSTS | extra_hosts | extra exact LLM-API hosts to intercept (comma-separated env / array in file), e.g. a self-hosted OpenAI-compatible endpoint |
| LLMTRIM_EXCLUDE_PROVIDERS | exclude_providers | wire shapes to skip compressing: openai / anthropic / google (e.g. anthropic to leave Claude Code untouched); coarse, covers every host of that shape |
| LLMTRIM_EXCLUDE_HOSTS | exclude_hosts | exact hostnames to skip compressing (e.g. openrouter.ai); precise, leaves other hosts of the same shape compressed |
| LLMTRIM_UPSTREAM_PROXY | upstream_proxy | route egress through another proxy (see below) |
| LLMTRIM_DB_PATH | db_path | ledger location |
| LLMTRIM_CAPTURE_DIR | capture_dir | before/after QA capture directory |
| LLMTRIM_CAPTURE_MAX_MB | capture_max_mb | capture corpus size ceiling (0 disables) |
| LLMTRIM_FIRST_ARRIVAL_RECALL | first_arrival_recall | recoverable first-arrival tool-output shaping (default false; set true to admit cache-boundary results for llmtrim recall) |
| LLMTRIM_TOOL_OUTPUT | toolout_passthrough | skip tool-output compression for matching commands: passthrough (all) or command globs (gpt.sh); also honoured as a command assignment or a result line. LLMTRIM_KEEP: lines are always retained |
| LLMTRIM_FIRST_ARRIVAL_RECALL_TTL_SECS | first_arrival_recall_ttl_secs | in-memory raw-result lifetime (default 18,000 seconds / five hours) |
| LLMTRIM_BIND | bind | listen IP (default loopback; 0.0.0.0 for containers) |
| LLMTRIM_BREAKDOWN_WINDOW | breakdown_window | context-window override for the cost breakdown |
| LLMTRIM_RETENTION_DAYS | retention_days | ledger age-retention in days |
| LLMTRIM_NO_UPDATE_CHECK | no_update_check | disable the passive update check |
extra_hosts entries must be exact hostnames (llm.acme.com, never a bare acme.com): each one widens the name-constrained MITM CA, which regenerates automatically on the next launch to cover them.
Claude Code options (subscription reroute) are under Claude Code.
export LLMTRIM_UPSTREAM_PROXY=http://host:port
or with auth: http://user:pass@host:port  (redacted in logs)
Outbound calls use CONNECT + verifying TLS; the upstream only sees the encrypted stream.
Looping to llmtrim's own listen address is rejected. Put the variable in the daemon's
launch environment (launchd / systemd), not only your interactive shell. Profile secrets
sit in plaintext.
Companion tools on another port (e.g. headroom) are fine.
Every case is sent twice, once original and once compressed, then both answers are scored and billed at real rates. Cost and quality are measured together, not estimated, across 112 cases:
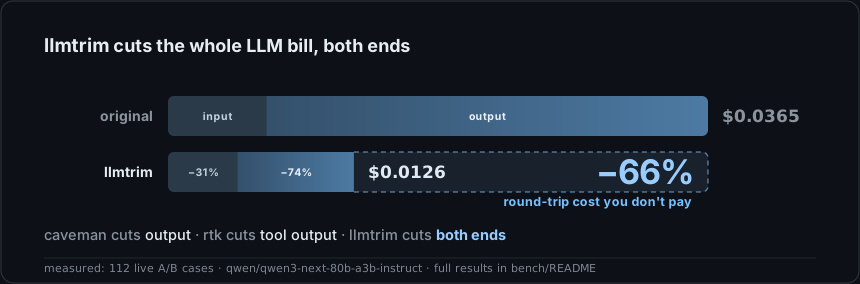
| | original | compressed | saved | |---|--:|--:|--:| | input tokens | 71,031 | 49,062 | −31% | | output
→ →
 →
 →
 →
 →
 →
 →