1
 →

A lightweight implementation of the GEPA (Genetic-Pareto) prompt optimization method for large language models.
egmaminta/GEPA-Lite is an open-source project on GitHub, mainly written in Python. A lightweight implementation of the GEPA (Genetic-Pareto) prompt optimization method for large language models. It currently holds 58 stars and 4 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Prompt Engineering board.
#ForTheLoveOfCode
GEPA-Lite is a lightweight implementation based on the proposed GEPA prompt optimization method that is custom fit for single-task applications. It's built on the core principle of LLM self-reflection, self-improvement, streamlined.
Developed in the spirit of open-source initiatives like Google Summer of Code 2025 and For the Love of Code 2025, this project leverages Gemma (ollama::gemma3n:e4b) as its core model. The project also offers optional support for the Gemini API, allowing access to powerful models like gemini-2.5-flash-lite, gemini-2.5-flash, and gemini-2.5-pro.
Created by: Emmanuel G. Maminta* (GitHub: egmaminta, LinkedIn: egmaminta, Personal Blog: egmaminta.github.io, Email: egmaminta@up.edu.ph)
*University of the Philippines
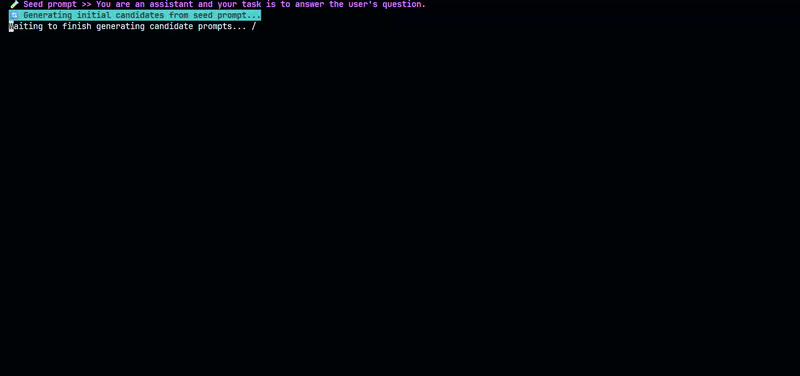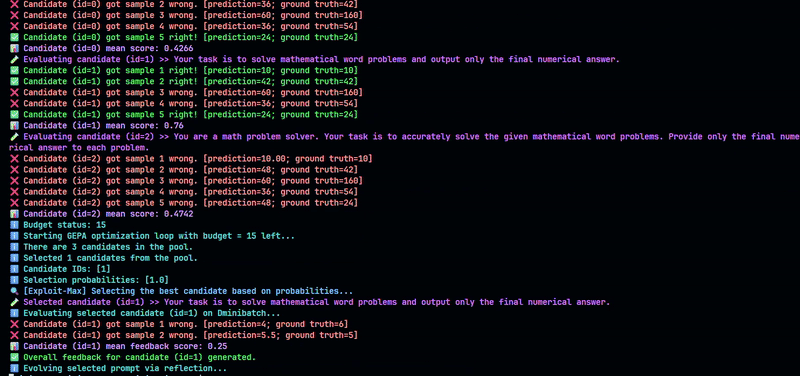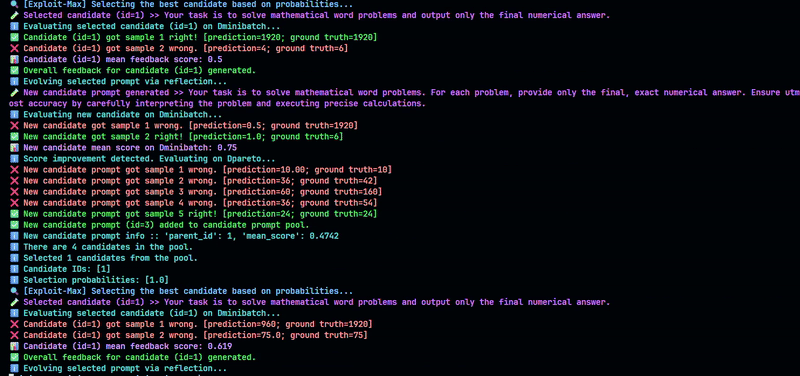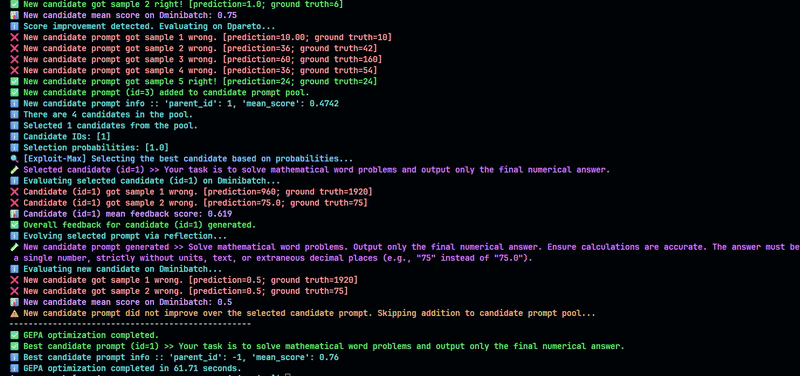
GEPA-Lite demonstration on sampled GSM8K. Initial prompt: "You are an assistant and your task is to answer the user's question." Final prompt: "Your task is to solve mathematical word problems and output only the final numerical answer."
GSM8K consists of 8.5K high quality grade school math problems created by human problem writers.
Note: P: Exploit probability, Q: Probability to not merge (or not mutate) all bests
Disclaimer: This implementation contains minor deviations from the reference paper. I, the creator of this repository, am held accountable for any part that is implemented incorrectly. However, the idea remains the same. Feel free to contribute!
Authors: Lakshya A Agrawal1, Shangyin Tan1, Dilara Soylu2, Noah Ziems4, Rishi Khare1, Krista Opsahl-Ong5, Arnav Singhvi2,5, Herumb Shandilya2, Michael J Ryan2, Meng Jiang4, Christopher Potts2, Koushik Sen1, Alexandros G. Dimakis1,3, Ion Stoica1, Dan Klein1, Matei Zaharia1,5, Omar Khattab6
1UC Berkeley, 2Stanford University, 3BespokeLabs.ai, 4Notre Dame, 5Databricks, 6MIT
TL;DR: GEPA is introduced, which utilizes natural language reflection to learn from trial and error. GEPA outperforms the reinforcement learning method GRPO (Group Relative Policy Optimization) by an average of 10% and up to 20%, while using up to 35 times fewer rollouts. It also surpasses the leading prompt optimizer, MIPROv2, by over 10%. Additionally, GEPA shows potential as an effective inference-time search strategy for code optimization.
GEPA_cfg.yaml) and datasets (Dpareto.json, Dfeedback.json).
2. Generate an initial pool of diverse candidate prompts concurrently from a seed prompt.
3. Evaluate each candidate over the full Pareto set (Dpareto) to build a score matrix S (candidates × tasks).
4. Enter the optimization loop (budget-limited):
Dfeedback).Dpareto: Ground-truth QA pairs used for stable, comparable scoring across candidates.Dfeedback: Additional sampled items for rapid, lower-cost iterative refinement.Scores: String similarity via difflib.SequenceMatcher (ratio ∈ [0,1]); exact matches earn 1. (You have the option to implement your own eval_metric and eval_feedback functions).META_PROMPT) injects the current prompt and structured per-sample feedback (query, model answer, ground truth, score, textual feedback).Exploit-Max
Exploit-Normal
Exploit-Merge
Explore
generate_initial_candidates_from_seed: Concurrent single-prompt generations for diversity + deduplication.select_candidate: Pareto elite extraction, dominance pruning, probability assignment.extract_response_from_target / extract_response_from_reflection: Structured JSON-like parsing via Pydantic schema.GEPA: Orchestrates the evolutionary loop with budget accounting.extract_merged_prompt: Synthesizes multiple prompts into one.eval_metric / eval_feedback: Scoring + diagnostic feedback synthesis.eval_metric for domain-specific scoring.miniconda / anaconda installed. Create a virtual environment with Python ver. 3.11.13.
conda create -n "GEPA-Lite" python=3.11.13 -y
conda activate GEPA-Lite
pip install -r requirements.txt
GEPA_cfg.yml.
2. (Gemini API) Replace placeholder PROJECT and LOCATION if VERTEXAI: true; else optionally set VERTEXAI: false. (Ollama API) Replace TARGET_MODEL and REFLECTION_MODEL to Ollama-provided gemma3n:e4b model.
3. Adjust BUDGET ensuring it's ≥ (NUM_INITIAL_CANDIDATE_PROMPTS |Dpareto|) + (MINI_BATCH_SIZE 5 * |Dpareto|) + safety margin (~30%).
4. Tune EXPLOIT_PROB and MERGE_PROB based on desired exploration.
5. Save and re-run the main script (GEPA.py).
Dpareto.json: Stable evaluation set. Used to compute full score vectors per candidate prompt (deterministic performance basis).Dfeedback.json: Fast adaptation pool. Small random mini-batches sampled each iteration to generate feedback and mutate prompts.question, answer (non-empty strings). Avoid extra keys unless you extend code to read them.
[
  {
    "question": "string input or query",
    "answer": "ground truth string answer"
  },
  ...
]
Dpareto.json: Must be representative, cover all subtopics / formats / difficulty tiers. It must vary in length, phrasing, edge cases (numbers, units, multi-step reasoning). Do not modify mid-run.Dfeedback.json: Larger pool than MINI_BATCH_SIZE (≥ twice the size of Dpareto). Higher variability, includes tricky and failure-prone cases. Can include some overlap with Dpareto, but prefer mostly distinct to broaden learning signals.Dpareto size: Small tasks (QA-like) 15-40; moderate 40-100. Larger increases cost linearly.Dfeedback size: 2–5× Dpareto or at least 50 if you want variety; minimum = MINI_BATCH_SIZE 2 |Dpareto|.Initial cost = NUM_INITIAL_CANDIDATE_PROMPTS |Dpareto|. Each accepted new candidate costs another |Dpareto|. Ensure BUDGET ≥ initial + (expected improvements |Dpareto|) + iteration minibatch costs.Dpareto to reduce variance.Dpareto so they can influence selection pressure.Dpareto
1. Gather raw candidate pairs.
2. Deduplicate (case-insensitive question hash).
3. Remove ambiguous items.
4. Normalize answers.
5. Tag coverage (spread topics).
6. Shuffle with fixed seed; pick top N.
7. Save to Dpareto.json and freeze (commit with version tag).
7. Workflow to build Dfeedback
1. Start with remaining pool not used in Dpareto.
2. Inject a few "stress" / adversarial items (format traps, long inputs).
3. Ensure at least MINI_BATCH_SIZE 2 |Dpareto| total.
4. Optionally rotate / refresh between runs (version the file).
#ForTheLoveOfCode→ →
 →
 →
 →
 →
 →
 →