1
 →

Open-source persistent memory for AI agent pipelines (LangGraph, CrewAI, AutoGen) and Claude. REST API + knowledge graph + autonomous consolidation.
doobidoo/mcp-memory-service is an open-source project on GitHub, mainly written in Python. Open-source persistent memory for AI agent pipelines (LangGraph, CrewAI, AutoGen) and Claude. REST API + knowledge graph + autonomous consolidation. It currently holds 1,952 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Agent Memory board.
## This repository has moved to GitHub
> Active development, issues, pull requests, CI and releases are at
https://github.com/doobidoo/mcp-memory-service as of 5 September 2026.
> This copy stays here, readable and unchanged, so that existing links, issue
numbers and pull request references keep resolving. It receives no further
pushes and its CI no longer runs. Please do not open issues or pull requests
here, they will not be seen.
> The wiki moved too: https://github.com/doobidoo/mcp-memory-service/wiki
Open-source memory backend for AI agents — REST API, MCP, OAuth, CLI, dashboard. One self-hosted service, every transport. Agents store decisions, share causal knowledge graphs, and retrieve context in 5ms — without cloud lock-in or API costs.
Works with LangGraph · CrewAI · AutoGen · any HTTP client · Claude Desktop · OpenCode
---
---
▶ The 3D knowledge graph in motion — every memory a glowing node, every relationship a curved edge. (Video not playing? See it live at mcpmemory.services.)
---
Your AI assistant forgets everything when you start a new chat. You spend 10 minutes re-explaining your architecture. Again. MCP Memory Service captures project context, architecture decisions, and code patterns automatically — new sessions start with everything already known.
| Without mcp-memory-service | With mcp-memory-service | |---|---| | Each agent run starts from zero | Agents retrieve prior decisions in 5ms | | Memory is local to one graph/run | Memory is shared across all agents and runs | | You manage Redis + Pinecone + glue code | One self-hosted service, zero cloud cost | | No causal relationships between facts | Knowledge graph with typed edges (causes, fixes, contradicts) | | Context window limits create amnesia | Autonomous consolidation compresses old memories |
Key capabilities for agent pipelines:
X-Agent-ID header — auto-tag memories by agent identity for scoped retrievalconversation_id — bypass deduplication for incremental conversation storageNot sure which setup fits your needs? See the Setup Guide — a decision tree walks you to the right path in under a minute.
1. Install:
pip install mcp-memory-service
2. Configure your AI client:
Add to your config file:
~/Library/Application Support/Claude/claude_desktop_config.json%APPDATA%\Claude\claude_desktop_config.json~/.config/Claude/claude_desktop_config.json{
"mcpServers": {
"memory": {
"command": "memory",
"args": ["server"]
}
}
}
Restart Claude Desktop. Your AI now remembers everything across sessions.
claude mcp add memory -- memory server
Restart Claude Code. Memory tools will appear automatically.
MCP_ALLOW_ANONYMOUS_ACCESS=true memory server --http
REST API running at http://localhost:8000
import asyncio
import httpx
BASE_URL = "http://localhost:8000"
async def main():
    async with httpx.AsyncClient() as client:
        # Store — auto-tag with X-Agent-ID header
        await client.post(f"{BASE_URL}/api/memories", json={
            "content": "API rate limit is 100 req/min",
            "tags": ["api", "limits"],
        }, headers={"X-Agent-ID": "researcher"})
        # Stored with tags: ["api", "limits", "agent:researcher"]
# Search — scope to a specific agent
        results = await client.post(f"{BASE_URL}/api/memories/search", json={
            "query": "API rate limits",
            "tags": ["agent:researcher"],
        })
        print(results.json()["memories"])
asyncio.run(main())
Framework-specific guides: docs/agents/
Start the HTTP API:
MCP_ALLOW_ANONYMOUS_ACCESS=true memory server --http
Install the local plugin:
git clone https://github.com/doobidoo/mcp-memory-service.git
cd mcp-memory-service
mkdir -p ~/.config/opencode/plugins
cp opencode/memory-plugin.js ~/.config/opencode/plugins/
cp opencode/memory-plugin.config.example.json ~/.config/opencode/memory-plugin.json
OpenCode automatically loads local plugins from ~/.config/opencode/plugins/ and .opencode/plugins/.
Optional: register the /memory slash command in ~/.config/opencode/opencode.json to query status, search, and health from inside the TUI:
{
  "command": {
    "memory": {
      "description": "Show MCP Memory Service status. Usage: /memory, /memory search , /memory health",
      "template": ""
    }
  }
}
See OpenCode integration guide for configuration, project-local installs, slash command details, TUI toasts, and current limitations.
The current OpenCode integration ships as repository files for the local plugin directory. If you installed only the PyPI package, clone the repository once to copy the plugin files.
> The plugin defaults tohttp://127.0.0.1:8000, butmemoryService.endpointandOPENCODE_MEMORY_ENDPOINTlet you target any reachable HTTP deployment.
Unlike desktop-only MCP servers, mcp-memory-service supports Remote MCP: persistent memory directly in your browser, on any device — no Claude Desktop required. Enterprise-ready (OAuth 2.0 + HTTPS + CORS), self-hosted or cloud-hosted.
# 1. Start server with Remote MCP
MCP_STREAMABLE_HTTP_MODE=1 \
MCP_SSE_HOST=0.0.0.0 \
MCP_OAUTH_ENABLED=true \
python -m mcp_memory_service.server
2. Expose publicly (Cloudflare Tunnel)
cloudflared tunnel --url http://localhost:8765
3. Add connector in claude.ai Settings → Connectors with the tunnel URL
OAuth flow will handle authentication automatically
Production Setup: Remote MCP Setup Guide (Let's Encrypt, nginx, Docker, firewall). Step-by-Step Tutorial: Blog: 5-Minute claude.ai Setup | Wiki Guide
For production deployments, team collaboration, or cloud sync:
git clone https://github.com/doobidoo/mcp-memory-service.git
cd mcp-memory-service
python scripts/installation/install.py
Choose from:
ℹ️ For long-lived services (MCP servers, web backends, notebook sessions), prefer Docker Milvus or Zilliz Cloud over Milvus Lite. See docs/milvus-backend.md for why.
---
Works seamlessly with any MCP-compatible client or HTTP client - whether you're building agent pipelines, coding in the terminal, IDE, or browser.
💡 NEW: ChatGPT now supports MCP! Enable Developer Mode to connect your memory service directly. See setup guide →
Home Assistant and other clients without OAuth: connect with anonymous access on your LAN, no source patching needed. See setup guide →
---
🧠 Persistent Memory – Context survives across sessions with semantic search
🔍 Smart Retrieval – Finds relevant context automatically using AI embeddings
⚡ 5ms Speed – Instant context injection, no latency
🔄 Multi-Client – Works across 25+ AI applications
☁️ Cloud Sync – Optional Cloudflare backend for team collaboration
🔒 Privacy-First – Local-first, you control your data
📊 Web Dashboard – Visualize and manage memories at http://localhost:8000
🧬 Knowledge Graph – Interactive D3.js visualization of memory relationships
🏠 Homelab Quality Scoring – Point scoring at any OpenAI-compatible endpoint (Ollama, LiteLLM, vLLM)
🔗 Entity Extraction – Auto-links @mentions, #tags, URLs, and file paths from memory content to a queryable entity graph
💡 Insight Cards – Consolidation detects patterns, trends, and knowledge gaps across your memory corpus and surfaces them as structured insights
🏷️ Tag Match Filtering – tag_match=AND/OR on memory_search for precise multi-tag queries
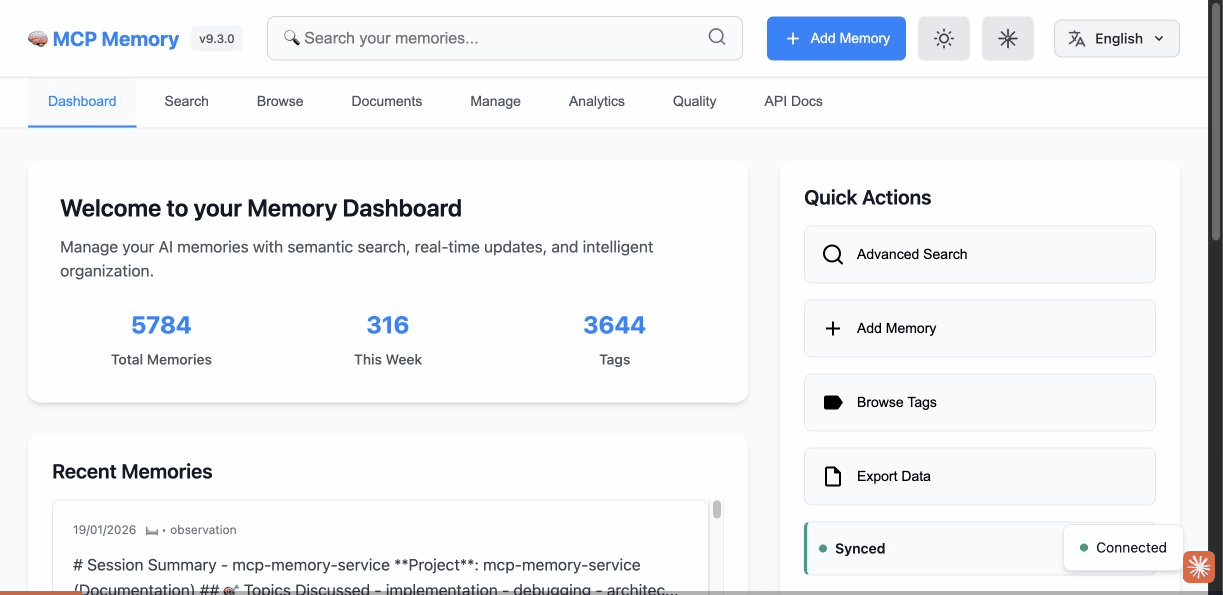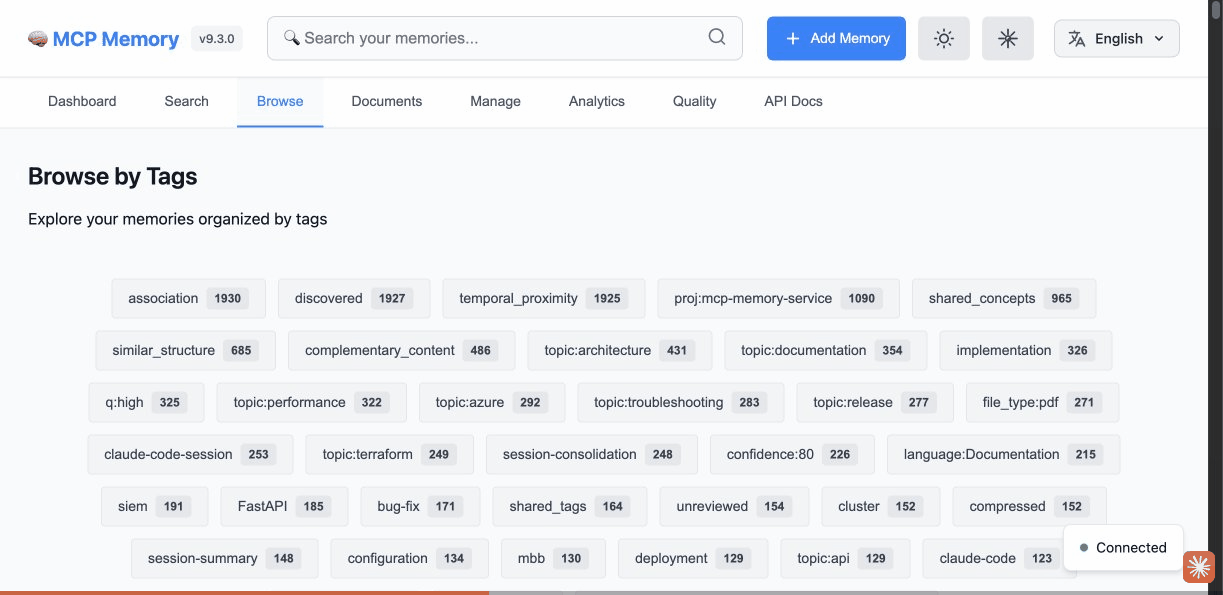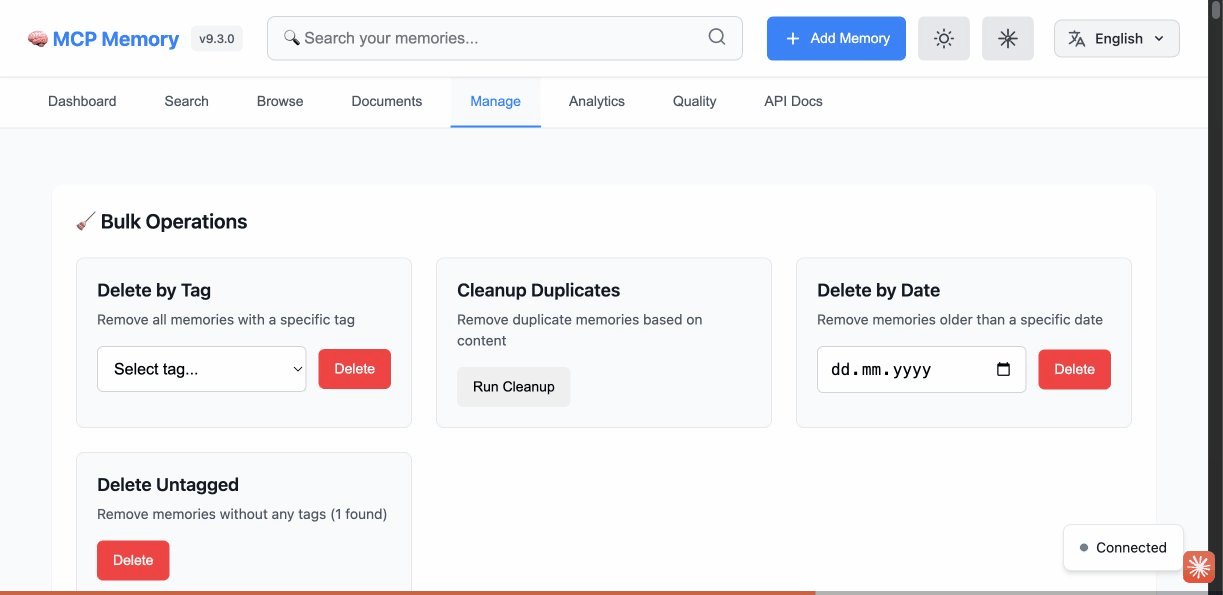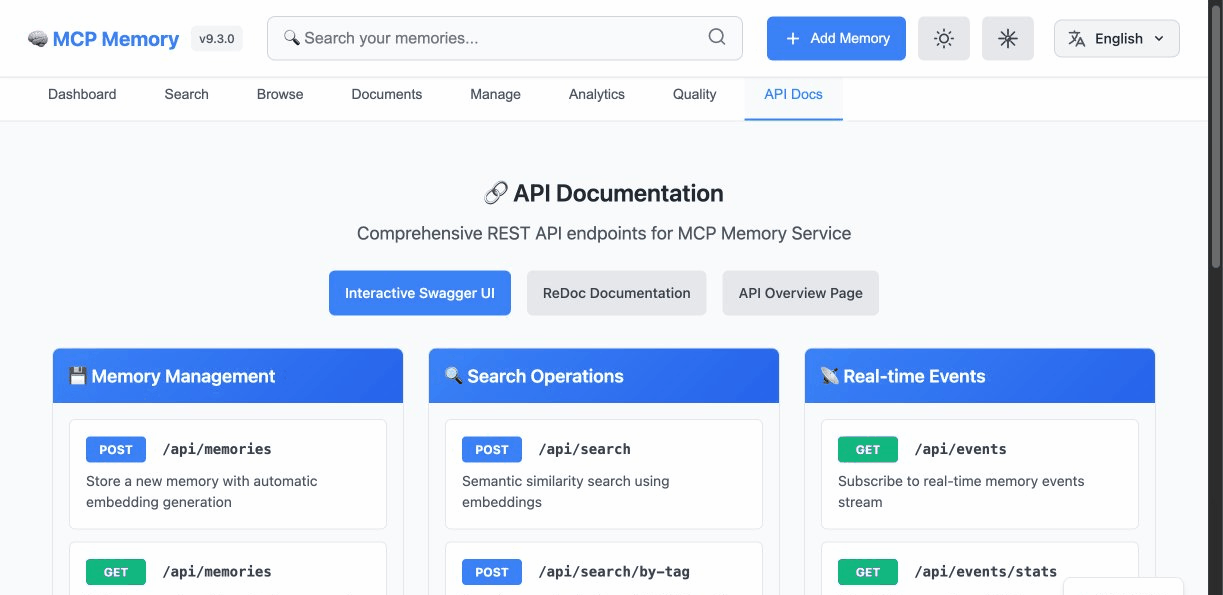
8 Dashboard Tabs: Dashboard • Search • Browse • Documents • Manage • Analytics • Quality • API Docs
🎬 Watch the Web Dashboard Walkthrough on YouTube — semantic search, tag browser, document ingestion, analytics, quality scoring, and API docs in under 2 minutes. 📖 See Web Dashboard Guide for complete documentation.
---
"After I work with one of the cluster agents on something I want my local agent to know about, the cluster agent adds a special tag to the memory entry that my local agent recognizes as a message from a cluster agent. So they end up using it as a comms bridge — and it's pretty delightful."
— @jeremykoerber (originally GitHub issue #591)
A 5-agent openclaw cluster uses mcp-memory-service as shared state and as an inter-agent messaging bus — without any custom protocol. Cluster agents tag memories with a sentinel like msg:cluster, and the local agent filters on that tag to receive cross-cluster signals. The memory service becomes the coordination layer with zero additional infrastructure.
# Cluster agent stores a learning and flags it for the local agent
await client.post(f"{BASE_URL}/api/memories", json={
    "content": "Rate limit on provider X is 50 RPM — switch to provider Y after 40",
    "tags": ["api", "limits", "msg:cluster"],       # sentinel tag
}, headers={"X-Agent-ID": "cluster-agent-3"})
Local agent polls for cluster messages
results = await client.post(f"{BASE_URL}/api/memories/search", json={
    "query": "messages from cluster",
    "tags": ["msg:cluster"],
})
This pattern — tags as inter-agent signals — emerges naturally from the tagging system and requires no additional infrastructure.
"The quality of life that session-independent memory adds to AI workflows is immense. File-based memory demands constant discipline. Semantic recall from a live database doesn't. Storing data on my own hardware while making it remotely accessible across platforms turned out to be a feature I didn't know I needed."
— @PL-Peter (originally GitHub discussion #602)
A production-tested self-hosted deployment using Docker containers behind a Cloudflare tunnel, with AuthMCP Gateway handling authentication:
| Layer | Role | |-------|------| | Cloudflare Tunnel | Name-based routing, subnet-based access control, authentication before hitting self-hosted resources | | AuthMCP Gateway | Auth/aggregation with locally managed users, admin UI, per-user MCP server access control, bearer token auth | | mcp-memory-service | Two Docker containers sharing one SQLite backend — one for MCP, one for the web UI (document ingestion) |
Security best practices for this setup:
offline_access scope during authorization to receive a rotating refresh_token (lifetime via MCP_OAUTH_REFRESH_TOKEN_EXPIRE_DAYS, default 30 days). Without this scope, access tokens are the only credential — extend MCP_OAUTH_ACCESS_TOKEN_EXPIRE_MINUTES up to 1440 (24h) if you need longer single-shot sessions."mcp-memory-service has been the shared memory layer for all my coding agents since February — Claude Code, Claude Desktop, Codex CLI and OpenCode all talk to the same sqlite-vec DB over stdio on my Mac. ~5,900 memories and counting. Every session starts by pulling a bootstrap profile from memory and ends by committing a session summary, so any agent can pick up where another left off — work context, project state, even a 'mistakes I made before' log. It's the closest thing to persistent identity my agents have."
— Mingjian Shao (AI PM & AI consultant, via LinkedIn)
A single local sqlite-vec database on a Mac acts as the shared brain for four different agents over stdio — no server, no cloud. Embeddings run fully offline via a local Qwen3-Embedding-0.6B (1024-dim) on MPS, with daily automated backups, scheduled consolidation, and the dashboard kept alive by a LaunchAgent.
Lesson worth stealing (offline embeddings): when the custom embedding model fails to load, the service can silently fall back to the default MiniLM (384-dim) and subsequent writes fail with dimension mismatches. If you pin a non-default embedding model, also pin the model path and set the Hugging Face offline flags so a load failure surfaces loudly instead of degrading — then a dimension mismatch can't corrupt the store.
---
| | Mem0 | Zep | DIY Redis+Pinecone | mcp-memory-service | |---|---|---|---|---| | License | Proprietary | Enterprise | — | Apache 2.0 | | Cost | Per-call API | Enterprise | Infra costs | $0 | | 🌐 claude.ai Browser | ❌ Desktop only | ❌ Desktop only | ❌ | ✅ Remote MCP | | OAuth 2.0 + DCR | ❓ Unknown | ❓ Unknown | ❌ | ✅ Enterprise-ready | | Streamable HTTP | ❌ | ❌ | ❌ | ✅ (SSE also supported) | | Framework integration | SDK | SDK | Manual | REST API (any HTTP client) | | Knowledge graph | No | Limited | No | Yes (typed edges) | | Auto consolidation | No | No | No | Yes (decay + compression) | | On-premise embeddings | No | No | Manual | Yes (ONNX, local) | | Privacy | Cloud | Cloud | Partial | 100% local | | Hybrid search | No | Yes | Manual | Yes (BM25 + vector) | | MCP protocol | No | No | No | Yes | | REST API | Yes | Yes | Manual | Yes (76 endpoints) |
MemPalace is an MCP-native alternative that went viral in April 2026 with strong LongMemEval claims. A community code review (Issue #27) subsequently showed that the headline numbers reflect the underlying vector store rather than the advertised Palace architecture, and the maintainers acknowledged most points. We keep the comparison here for transparency, but readers should interpret the scores with that context in mind.
| | MemPalace | mcp-memory-service | |---|---|---| | LongMemEval R@5 (raw ChromaDB, zero LLM) | 96.6%¹ | 86.0% (session) / 80.4% (turn) | | LongMemEval R@5 (with reranking) | 100%² | — | | Storage granularity | Session-level | Turn-level + session-level | | Team / multi-device sync | ❌ Local only | ✅ Cloudflare sync | | REST API / Web dashboard | ❌ | ✅ | | OAuth 2.1 + multi-user | ❌ | ✅ | | Knowledge graph | ❌ | ✅ (typed edges) | | Auto consolidation | ❌ | ✅ (decay + compression) | | Compatible AI tools | Claude-focused | 25+ tools | | License | MIT | Apache 2.0 |
Why the benchmark gap? MemPalace stores whole sessions as single units — LongMemEval's "which session contains the answer?" question is answered structurally by that granularity. mcp-memory-service defaults to turn-level storage for fine-grained retrieval; using memory_store_session brings our score to 86.0% R@5. And per Issue #27, the 96.6% headline measures a raw ChromaDB baseline with the Palace architecture inactive — an apples-to-apples architectural comparison is not possible with the published numbers.
¹ Measured in MemPalace "raw mode" (plain text in ChromaDB with default embeddings). Per Issue #27, the Palace structural features are bypassed in this configuration.
> ² 100% result uses optional LLM reranking (~500 API calls) on a partially tuned test set. Clean held-out score (as reported by the maintainers): 98.4% R@5.
---
Three benchmarks measure retrieval quality (all-MiniLM-L6-v2, 384d embeddings, zero LLM API calls):
LongMemEval (500 questions, ~45–62 distractor sessions per question):
| Question Type | R@5 | R@10 | NDCG@10 | MRR | |---------------|-----|------|---------|-----| | Overall | 80.4% | 90.4% | 82.2% | 89.1% | | single-session-assistant | 100.0% | 100.0% | 99.3% | 99.1% | | knowledge-update | 84.6% | 96.8% | 86.2% | 95.5% | | single-session-user | 91.4% | 92.9% | 86.0% | 83.8% | | temporal-reasoning | 72.0% | 84.1% | 75.1% | 85.7% | | multi-session | 70.7% | 86.0% | 77.6% | 89.4% |
DevBench (practical developer workflow queries):
| Category | Recall@5 | MRR | |----------|----------|-----| | Overall | 91.1% | 0.861 | | exact | 100% | 1.000 | | semantic | 80.0% | 0.700 | | cross-type | 90.0% | 0.867 |
LoCoMo (ACL 2024 long-term conversational memory):
| Category | Recall@5 | MRR | |----------|----------|-----| | Overall | 49.7% | 0.414 | | multi-hop | 72.0% | 0.600 | | temporal | 33.5% | 0.274 |
Run benchmarks: python scripts/benchmarks/benchmark_longmemeval.py, python scripts/benchmarks/benchmark_devbench.py, python scripts/benchmarks/benchmark_locomo.py
---
Full reference: Configuration Guide
memory launch                  # Start HTTP server in background (127.0.0.1:8000)
memory launch --port 8192      # Custom port
memory info                    # Status and health
memory logs --lines 50         # Recent logs
memory stop                    # Stop server
These commands are optimized for fast startup and avoid loading heavy ML dependencies unless needed.
⚠️ Security Note: By default, the server binds to127.0.0.1(localhost only).--host 0.0.0.0/MCP_HTTP_HOST=0.0.0.0exposes the API to your network — do this only in trusted environments with proper authentication and firewall rules. For untrusted networks, use TLS termination (reverse proxy with HTTPS) or VPN overlays.
The default model (all-MiniLM-L6-v2) works well for English-only content. If you store memories in other languages, switch to a multilingual model:
| Model | Languages | Dimensions | Use case |
|-------|-----------|-----------|----------|
| all-MiniLM-L6-v2 (default) | English only | 384 | Fastest, English-only deployments |
| paraphrase-multilingual-MiniLM-L12-v2 | 50+ languages | 384 | Mixed-language or non-English content |
export MCP_EMBEDDING_MODEL=paraphrase-multilingual-MiniLM-L12-v2
⚠️ Switching models requires re-embedding existing memories (cross-language cosine drops from ~0.95 to ~0.10 otherwise): stop the service, run python scripts/maintenance/regenerate_embeddings.py with the new model env var, restart.
**Homelab / self-hosted qu
→ →
 →
 →
 →
 →
 →
 →