
1
 →

Official Implementation of OCR-free Document Understanding Transformer (Donut) and Synthetic Document Generator (SynthDoG), ECCV 2022
clovaai/donut is an open-source project on GitHub, mainly written in Python. Official Implementation of OCR-free Document Understanding Transformer (Donut) and Synthetic Document Generator (SynthDoG), ECCV 2022 It currently holds 6,923 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Image Projects board and on the AI AI Image Projects list.
Official Implementation of Donut and SynthDoG | Paper | Slide | Poster
Donut 🍩, Document understanding transformer, is a new method of document understanding that utilizes an OCR-free end-to-end Transformer model. Donut does not require off-the-shelf OCR engines/APIs, yet it shows state-of-the-art performances on various visual document understanding tasks, such as visual document classification or information extraction (a.k.a. document parsing). In addition, we present SynthDoG 🐶, Synthetic Document Generator, that helps the model pre-training to be flexible on various languages and domains.
Our academic paper, which describes our method in detail and provides full experimental results and analyses, can be found here:
OCR-free Document Understanding Transformer.
Geewook Kim, Teakgyu Hong, Moonbin Yim, JeongYeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park. In ECCV 2022.
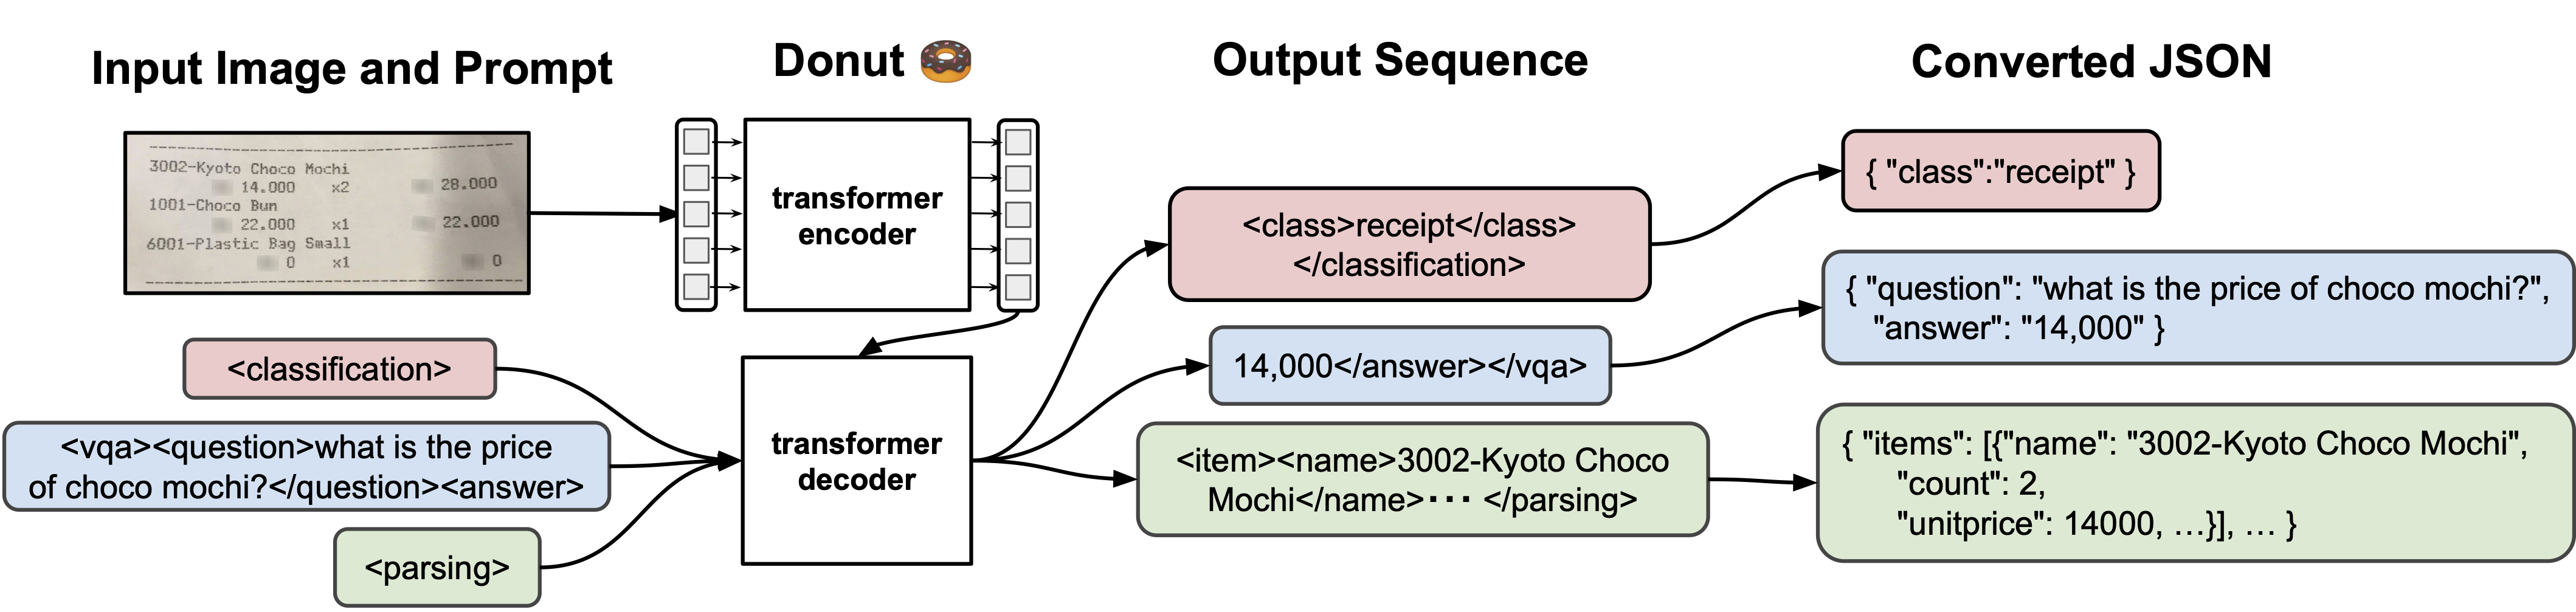
Gradio web demos are available!
|:--:|
|
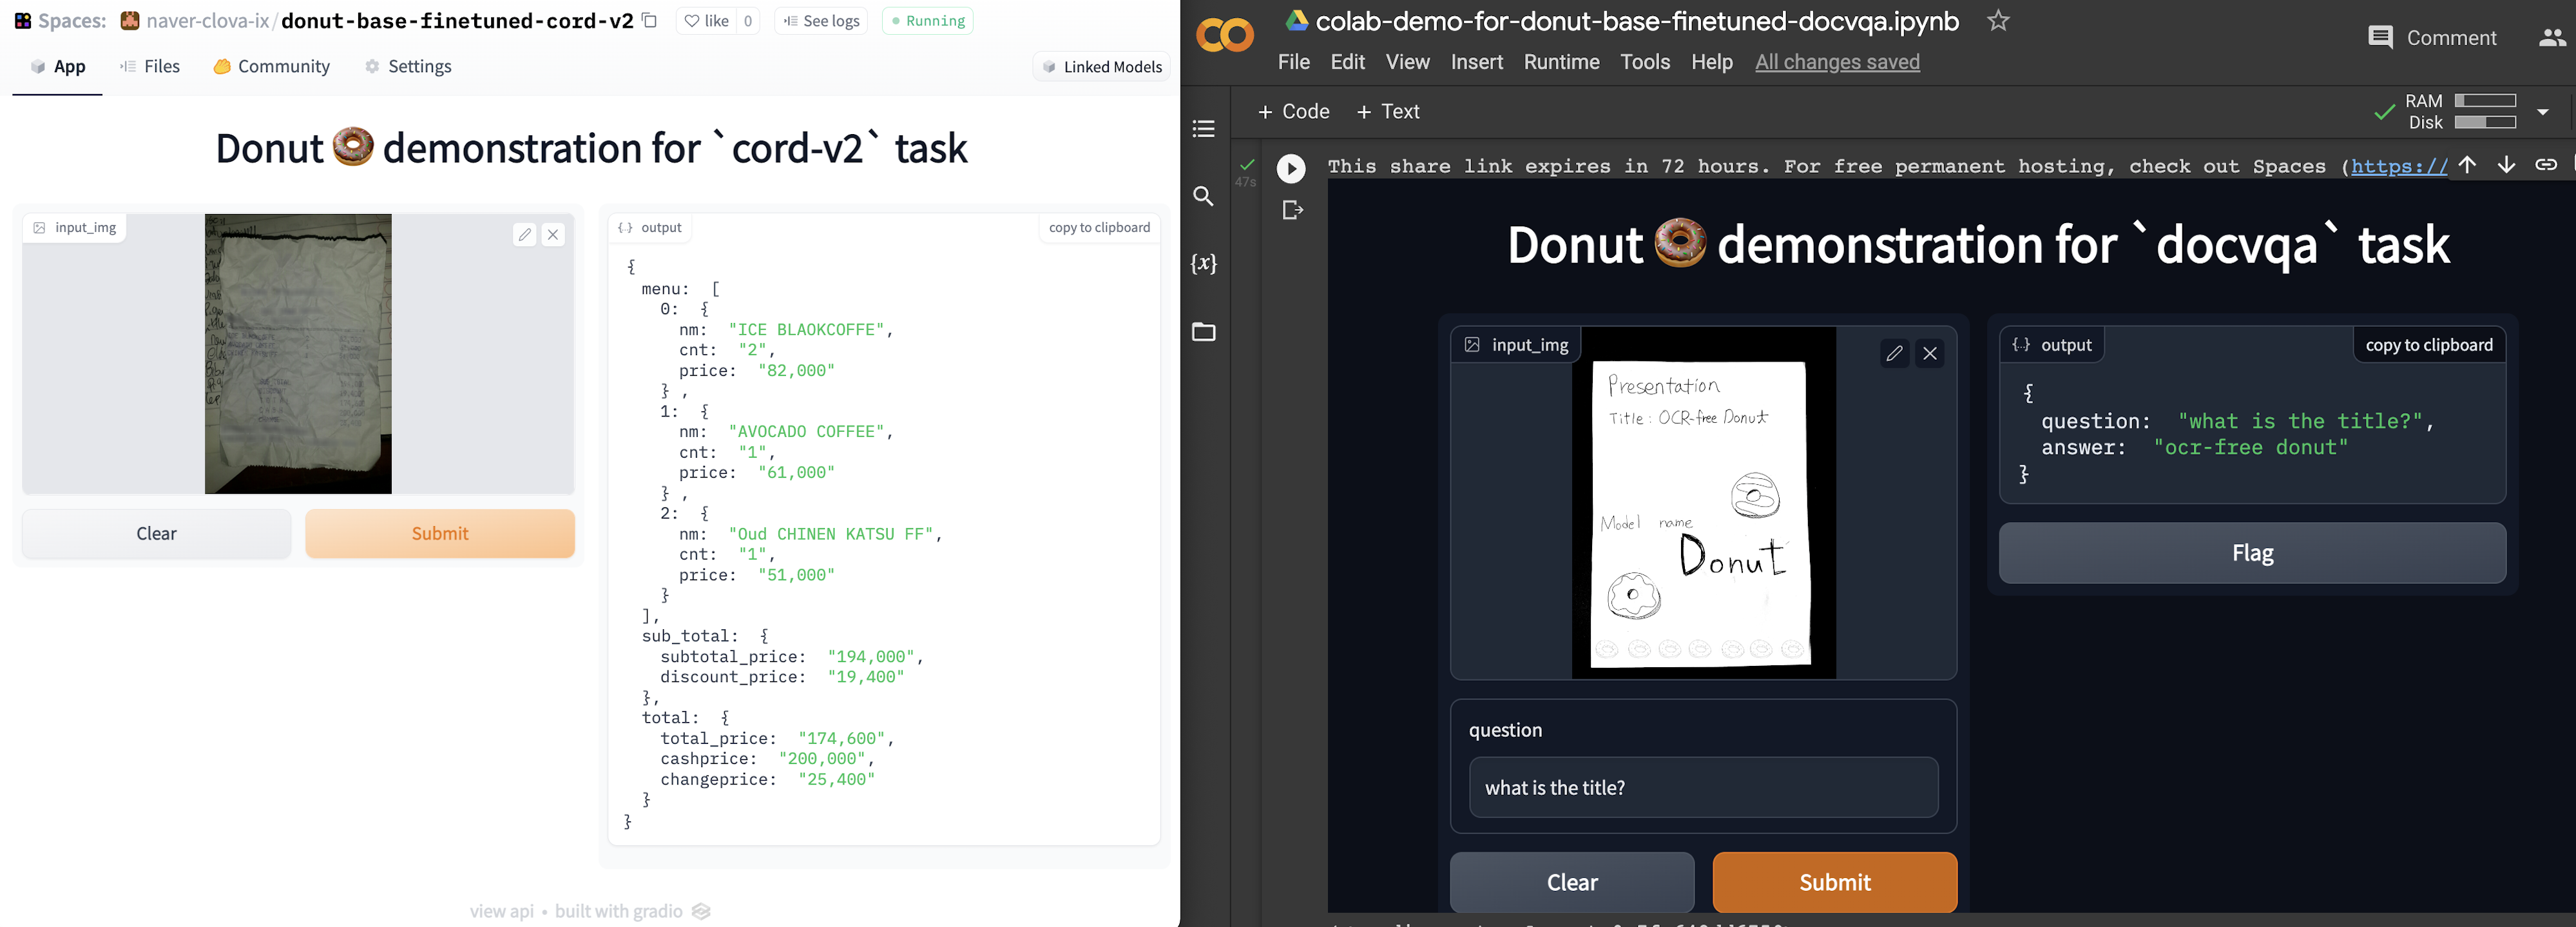 |
./app.py file../misc and more receipt images are available at CORD dataset link.The links to the pre-trained backbones are here:
donut-base: trained with 64 A100 GPUs (~2.5 days), number of layers (encoder: {2,2,14,2}, decoder: 4), input size 2560x1920, swin window size 10, IIT-CDIP (11M) and SynthDoG (English, Chinese, Japanese, Korean, 0.5M x 4).donut-proto: (preliminary model) trained with 8 V100 GPUs (~5 days), number of layers (encoder: {2,2,18,2}, decoder: 4), input size 2048x1536, swin window size 8, and SynthDoG (English, Japanese, Korean, 0.4M x 3).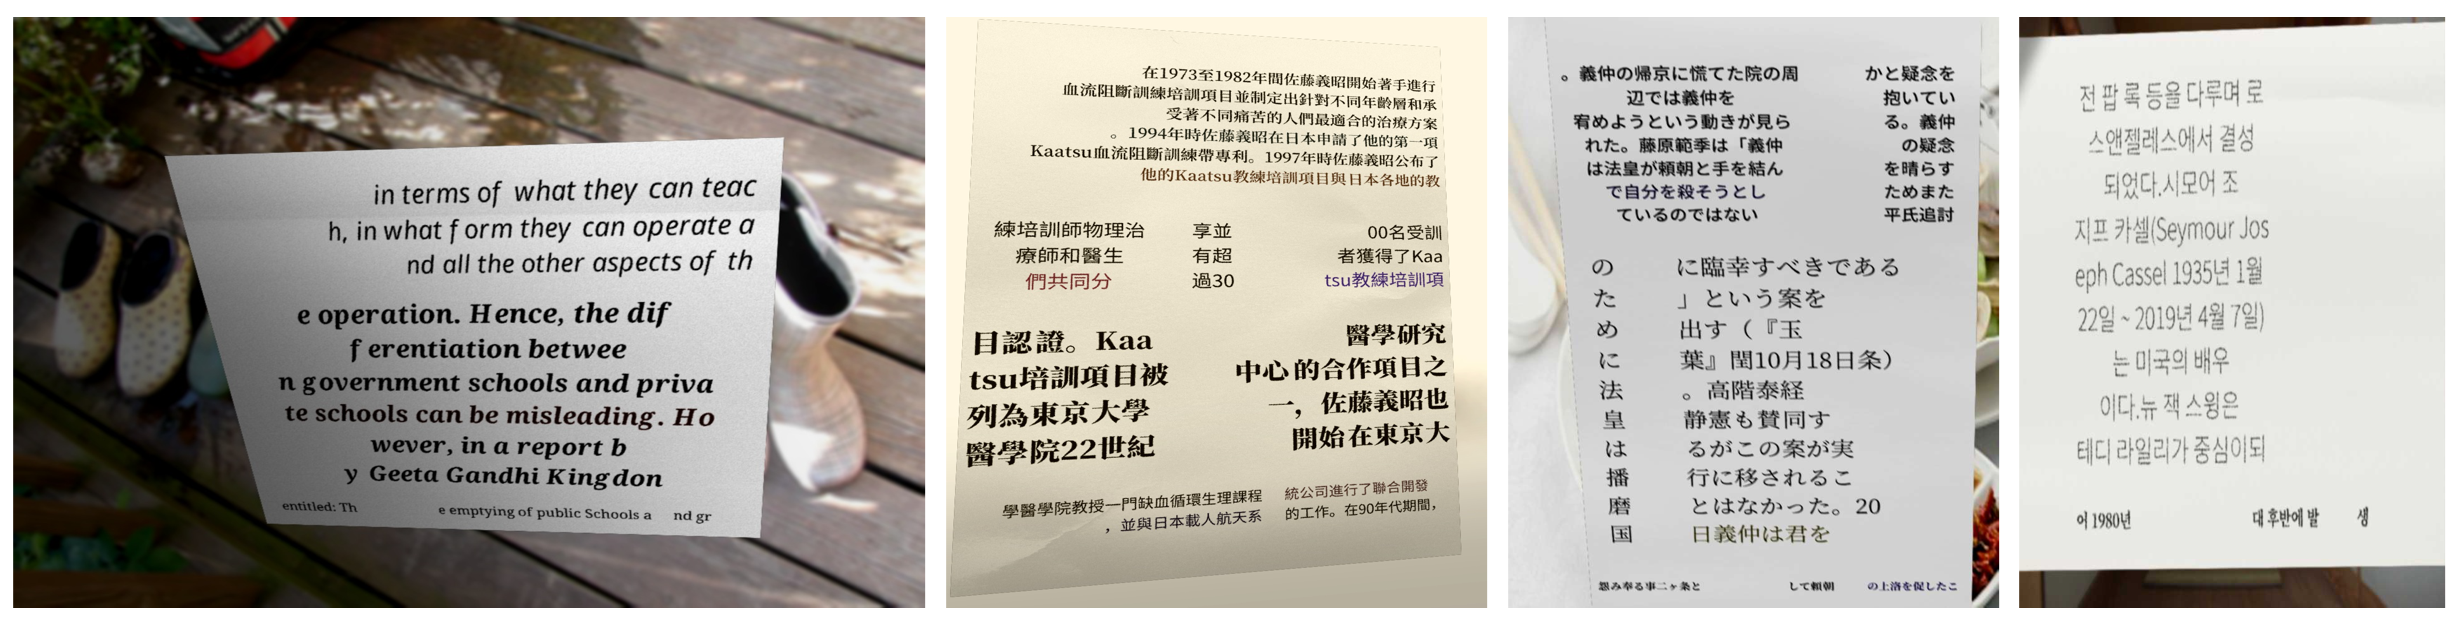
The links to the SynthDoG-generated datasets are here:
synthdog-en: English, 0.5M.synthdog-zh: Chinese, 0.5M.synthdog-ja: Japanese, 0.5M.synthdog-ko: Korean, 0.5M../synthdog/README.md and our paper for details.
_2023-06-15_ We have updated all Google Colab demos to ensure its proper working.
_2022-11-14_ New version 1.0.9 is released (pip install donut-python --upgrade). See 1.0.9 Release Notes.
_2022-08-12_ Donut 🍩 is also available at huggingface/transformers 🤗 (contributed by @NielsRogge). donut-python loads the pre-trained weights from the official branch of the model repositories. See 1.0.5 Release Notes.
_2022-08-05_ A well-executed hands-on tutorial on donut 🍩 is published at Towards Data Science (written by @estaudere).
_2022-07-20_ First Commit, We release our code, model weights, synthetic data and generator.
pip install donut-python
or clone this repository and install the dependencies:
git clone https://github.com/clovaai/donut.git
cd donut/
conda create -n donut_official python=3.7
conda activate donut_official
pip install .
We tested donut-python == 1.0.1 with:
donut-python due to recent updates in key dependency libraries. While we are actively working on a solution, we have updated the Google Colab demo (as of June 15, 2023) to ensure its proper working. For assistance, we encourage you to refer to the following demo links: CORD Colab Demo, Train Ticket Colab Demo, RVL-CDIP Colab Demo, DocVQA Colab Demo.
This repository assumes the following structure of dataset:
> tree dataset_name
dataset_name
├── test
│   ├── metadata.jsonl
│   ├── {image_path0}
│   ├── {image_path1}
│             .
│             .
├── train
│   ├── metadata.jsonl
│   ├── {image_path0}
│   ├── {image_path1}
│             .
│             .
└── validation
    ├── metadata.jsonl
    ├── {image_path0}
    ├── {image_path1}
              .
              .
cat dataset_name/test/metadata.jsonl
{"file_name": {image_path0}, "ground_truth": "{\"gt_parse\": {ground_truth_parse}, ... {other_metadata_not_used} ... }"}
{"file_name": {image_path1}, "ground_truth": "{\"gt_parse\": {ground_truth_parse}, ... {other_metadata_not_used} ... }"}
     .
     .
metadata.jsonl file is in JSON Lines text format, i.e., .jsonl. Each line consists offile_name : relative path to the image file.ground_truth : string format (json dumped), the dictionary contains either gt_parse or gt_parses. Other fields (metadata) can be added to the dictionary but will not be used.donut interprets all tasks as a JSON prediction problem. As a result, all donut model training share a same pipeline. For training and inference, the only thing to do is preparing gt_parse or gt_parses for the task in format described below.gt_parse follows the format of {"class" : {class_name}}, for example, {"class" : "scientific_report"} or {"class" : "presentation"}.
gt_parse is a JSON object that contains full information of the document image, for example, the JSON object for a receipt may look like {"menu" : [{"nm": "ICE BLACKCOFFEE", "cnt": "2", ...}, ...], ...}.
gt_parses follows the format of [{"question" : {question_sentence}, "answer" : {answer_candidate_1}}, {"question" : {question_sentence}, "answer" : {answer_candidate_2}}, ...], for example, [{"question" : "what is the model name?", "answer" : "donut"}, {"question" : "what is the model name?", "answer" : "document understanding transformer"}].
gt_parses should be a list of dictionary that contains a pair of question and answer.gt_parse looks like {"text_sequence" : "word1 word2 word3 ... "}
gt_parse. See ./synthdog/README.md for details.This is the configuration of Donut model training on CORD dataset used in our experiment. We ran this with a single NVIDIA A100 GPU.
python train.py --config config/train_cord.yaml \
                --pretrained_model_name_or_path "naver-clova-ix/donut-base" \
                --dataset_name_or_paths '["naver-clova-ix/cord-v2"]' \
                --exp_version "test_experiment"
  .
  .
Prediction: <s_menu><s_nm>Lemon Tea (L)</s_nm><s_cnt>1</s_cnt><s_price>25.000</s_price></s_menu><s_total><s_total_price>25.000</s_total_price><s_cashprice>30.000</s_cashprice><s_changeprice>5.000</s_changeprice></s_total>
Answer: <s_menu><s_nm>Lemon Tea (L)</s_nm><s_cnt>1</s_cnt><s_price>25.000</s_price></s_menu><s_total><s_total_price>25.000</s_total_price><s_cashprice>30.000</s_cashprice><s_changeprice>5.000</s_changeprice></s_total>
Normed ED: 0.0
Prediction: <s_menu><s_nm>Hulk Topper Package</s_nm><s_cnt>1</s_cnt><s_price>100.000</s_price></s_menu><s_total><s_total_price>100.000</s_total_price><s_cashprice>100.000</s_cashprice><s_changeprice>0</s_changeprice></s_total>
Answer: <s_menu><s_nm>Hulk Topper Package</s_nm><s_cnt>1</s_cnt><s_price>100.000</s_price></s_menu><s_total><s_total_price>100.000</s_total_price><s_cashprice>100.000</s_cashprice><s_changeprice>0</s_changeprice></s_total>
Normed ED: 0.0
Prediction: <s_menu><s_nm>Giant Squid</s_nm><s_cnt>x 1</s_cnt><s_price>Rp. 39.000</s_price><s_sub><s_nm>C.Finishing - Cut</s_nm><s_price>Rp. 0</s_price><s_nm>B.Spicy Level - Extreme Hot Rp. 0</s_price></s_sub><s_nm>A.Flavour - Salt & Pepper</s_nm><s_price>Rp. 0</s_price></s_sub></s_menu><s_sub_total><s_subtotal_price>Rp. 39.000</s_subtotal_price></s_sub_total><s_total><s_total_price>Rp. 39.000</s_total_price><s_cashprice>Rp. 50.000</s_cashprice><s_changeprice>Rp. 11.000</s_changeprice></s_total>
Answer: <s_menu><s_nm>Giant Squid</s_nm><s_cnt>x1</s_cnt><s_price>Rp. 39.000</s_price><s_sub><s_nm>C.Finishing - Cut</s_nm><s_price>Rp. 0</s_price><s_nm>B.Spicy Level - Extreme Hot</s_nm><s_price>Rp. 0</s_price><s_nm>A.Flavour- Salt & Pepper</s_nm><s_price>Rp. 0</s_price></s_sub></s_menu><s_sub_total><s_subtotal_price>Rp. 39.000</s_subtotal_price></s_sub_total><s_total><s_total_price>Rp. 39.000</s_total_price><s_cashprice>Rp. 50.000</s_cashprice><s_changeprice>Rp. 11.000</s_changeprice></s_total>
Normed ED: 0.039603960396039604
Epoch 29: 100%|█████████████| 200/200 [01:49<00:00,  1.82it/s, loss=0.00327, exp_name=train_cord, exp_version=test_experiment]
Some important arguments:
--config : config file path for model training.--pretrained_model_name_or_path : string format, model name in Hugging Face modelhub or local path.--dataset_name_or_paths : string format (json dumped), list of dataset names in Hugging Face datasets or local paths.--result_path : file path to save model outputs/artifacts.--exp_version : used for experiment versioning. The output files are saved at {result_path}/{exp_version}/*With the trained model, test images and ground truth parses, you can get inference results and accuracy scores.
python test.py --dataset_name_or_path naver-clova-ix/cord-v2 --pretrained_model_name_or_path ./result/train_cord/test_experiment --save_path ./result/output.json
100%|█████████████| 100/100 [00:35<00:00,  2.80it/s]
Total number of samples: 100, Tree Edit Distance (TED) based accuracy score: 0.9129639764131697, F1 accuracy score: 0.8406020841373987
Some important arguments:
--dataset_name_or_path : string format, the target dataset name in Hugging Face datasets or local path.--pretrained_model_name_or_path : string format, the model name in Hugging Face modelhub or local path.--save_path: file path to save predictions and scores.@inproceedings{kim2022donut,
title = {OCR-Free Document Understanding Transformer},
author = {Kim, Geewook and Hong, Teakgyu and Yim, Moonbin and Nam, JeongYeon and Park, Jinyoung and Yim, Jinyeong and Hwang, Wonseok and Yun, Sangdoo and Han, Dongyoon and Park, Seunghyun},
booktitle = {European Conference on Computer Vision (ECCV)},
year = {2022}
}
MIT license
Copyright (c) 2022-present NAVER Corp.
Permission is hereby granted, free of charge, to any person obtaining a copy
of this software and associated documentation files (the "Software"), to deal
in the Software without restriction, including without limitation the rights
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
copies of the Software, and to permit persons to whom the Software is
furnished to do so, subject to the following conditions:
The above copyright notice and this permission notice shall be included in
all copies or substantial portions of the Software.
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT.  IN NO EVENT SHALL THE
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN
THE SOFTWARE.
 →→
 →
 →→
 →
 →