1
 →

[ICCV 2023] A latent space for stochastic diffusion models
ChenWu98/cycle-diffusion is an open-source project on GitHub, mainly written in Python. [ICCV 2023] A latent space for stochastic diffusion models It currently holds 661 stars and 37 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Image Projects board and on the AI AI Image Projects list.
Official PyTorch implementation of our paper:
Unifying Diffusion Models' Latent Space, with Applications to CycleDiffusion and Guidance
Chen Henry Wu, Fernando De la Torre
Carnegie Mellon University
_Preprint, Oct 2022_
A modified version of this paper is accepted to ICCV 2023:
A Latent Space of Stochastic Diffusion Models for Zero-Shot Image Editing and Guidance
Chen Henry Wu, Fernando De la Torre
Carnegie Mellon University
_ICCV 2023_
[[Paper link]](https://arxiv.org/abs/2210.05559) | [[ICCV version]](https://openaccess.thecvf.com/content/ICCV2023/papers/Wu_A_Latent_Space_of_Stochastic_Diffusion_Models_for_Zero-Shot_Image_ICCV_2023_paper.pdf) | [[Diffusers 🧨 implementation]](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cycle_diffusion) | [[HuggingFace 🤗 demo]](https://huggingface.co/spaces/ChenWu98/Stable-CycleDiffusion)
[Nov 9 2022] CycleDiffusion is now available as a pipeline on HuggingFace 🤗 Diffusers 🧨. Please check the pipeline doc.
[Nov 10 2022] A demo built with HuggingFace 🤗 Spaces is available at Stable CycleDiffusion.
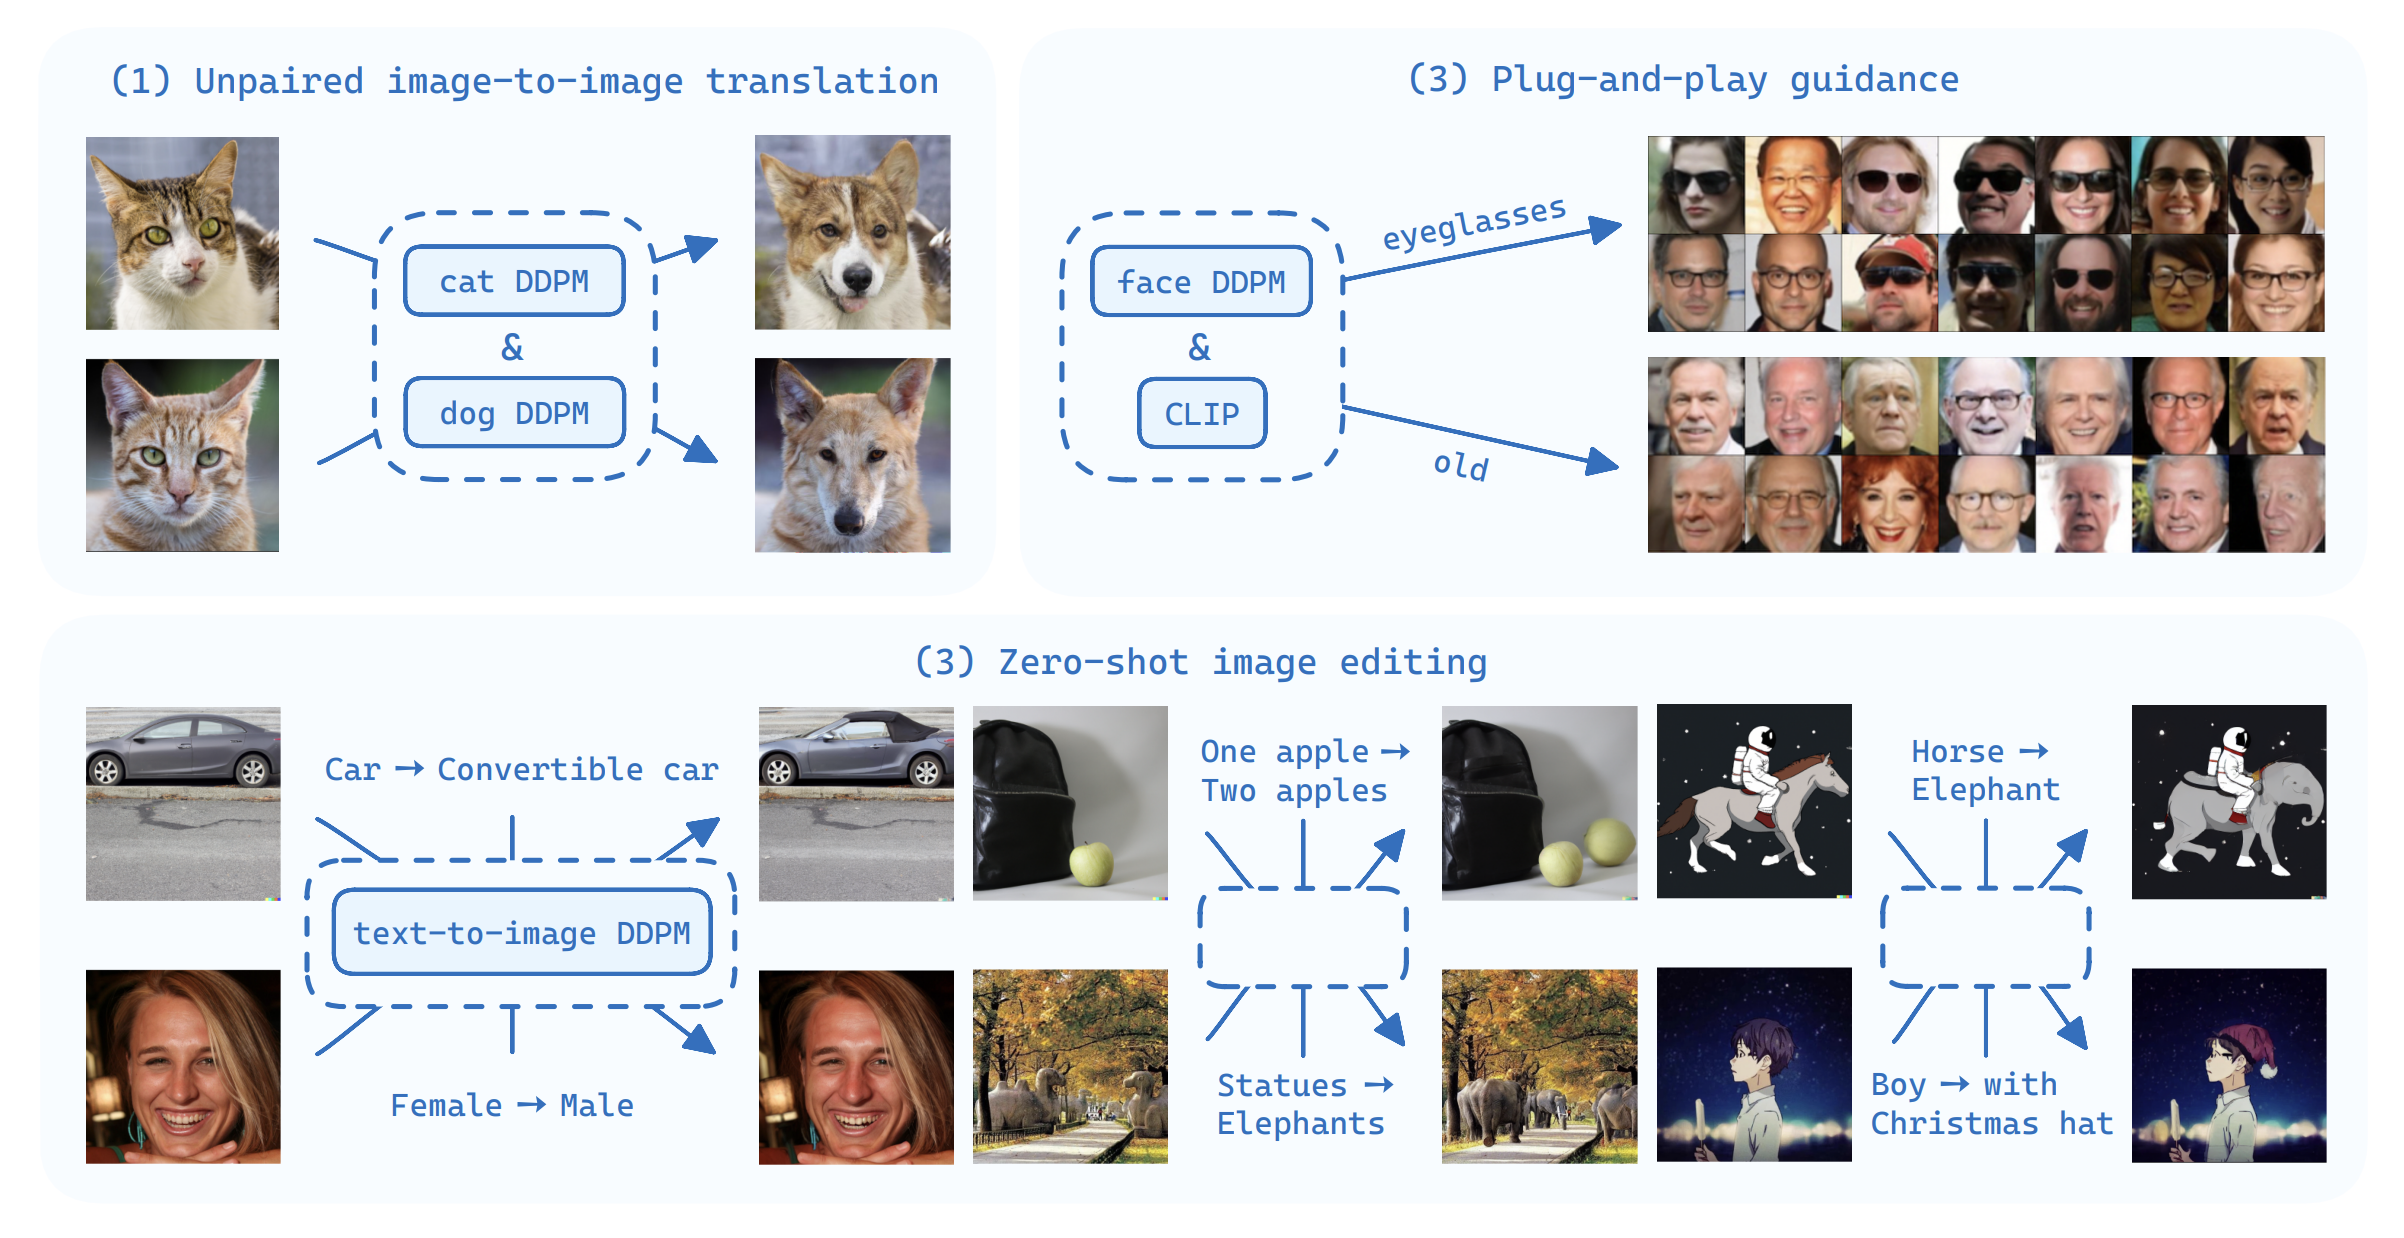
Our formalization and derivation are purely by definition, while we show that some amazing consequences follow! This repository contains code for CycleDiffusion, an embarrassingly simple method capable of
1. Zero-shot image-to-image translation with text-to-image diffusion models such as Stable Diffusion. 2. Traditional unpaired image-to-image translation with diffusion models trained on two related domains.
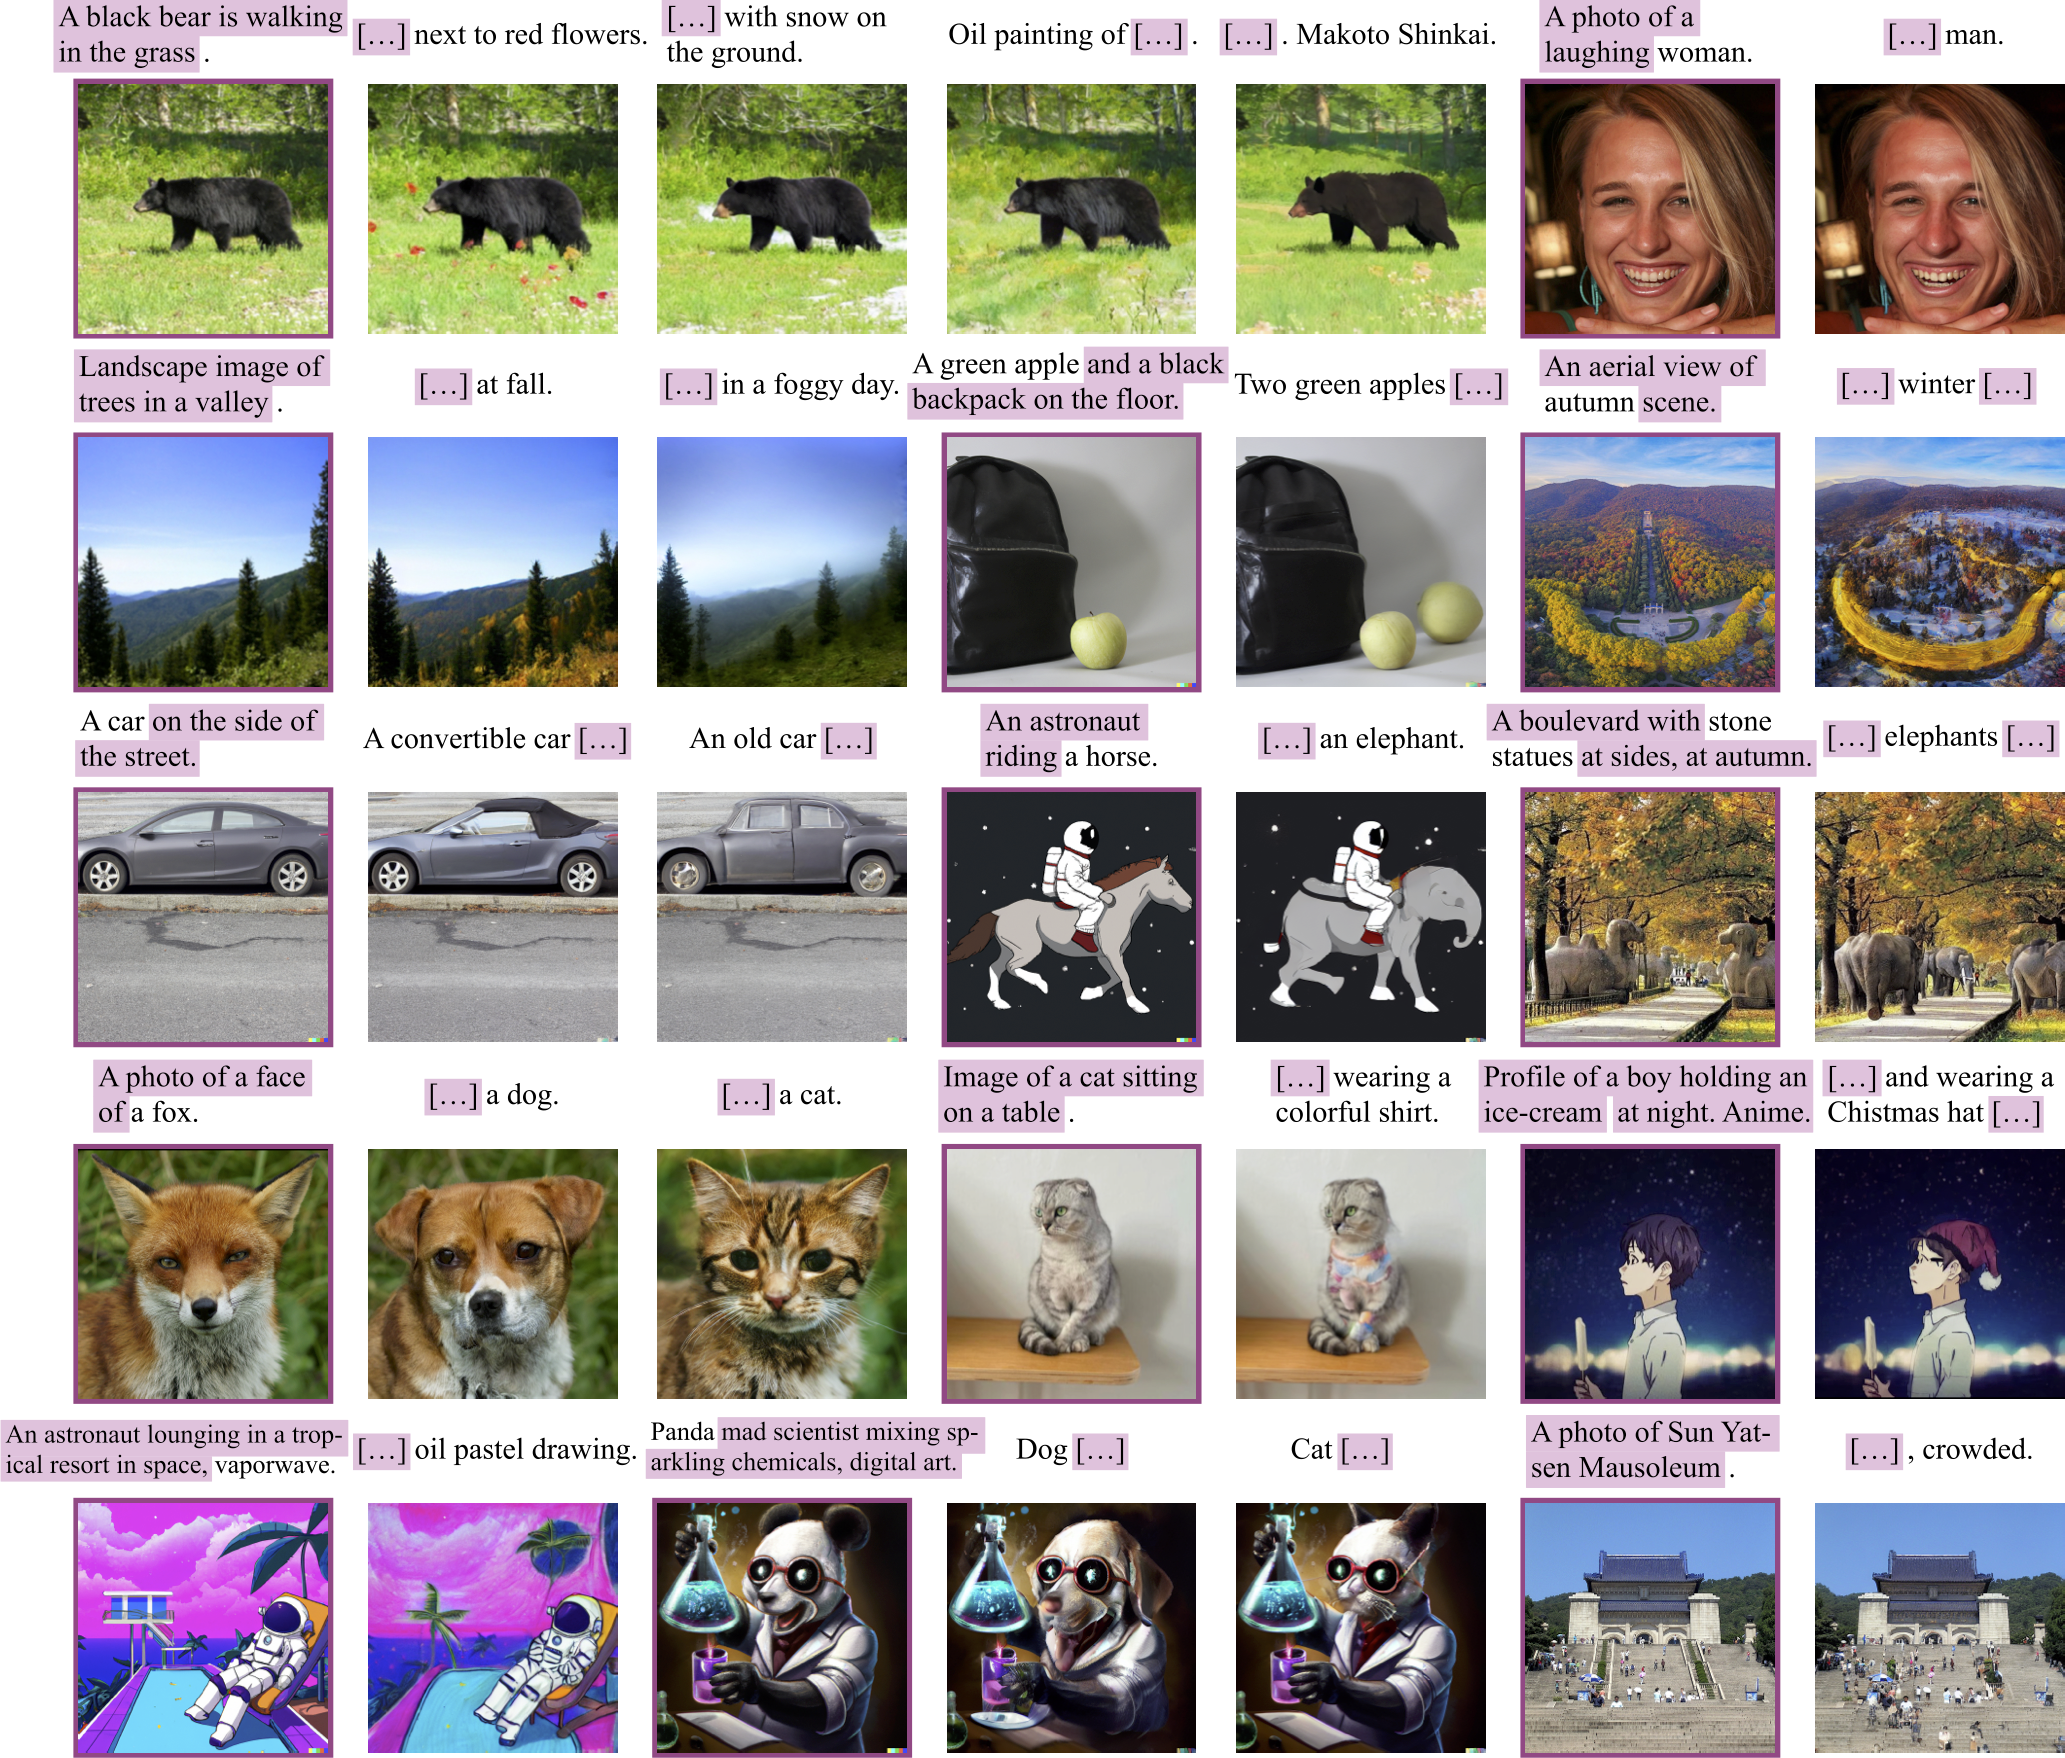
Check our results on zero-shot image-to-image translation below! We formulate the task input as a triplet $(\boldsymbol{x}, \boldsymbol{t}, \hat{\boldsymbol{t}})$:
1. $\boldsymbol{x}$ is the source image, displayed with a purple margin. 2. $\boldsymbol{t}$ is the source text, with text spans marked in purple. 3. $\hat{\boldsymbol{t}}$ is the target text, with text spans abbreviated as $[\ldots]$ if overlapped with the source text.
We used Stable Diffusion in our experiments. Notably, all source images $\boldsymbol{x}$ are real images! Yes, you find that some of them are generated by DALL∙E 2, but these images can be seen as real for Stable Diffusion :)
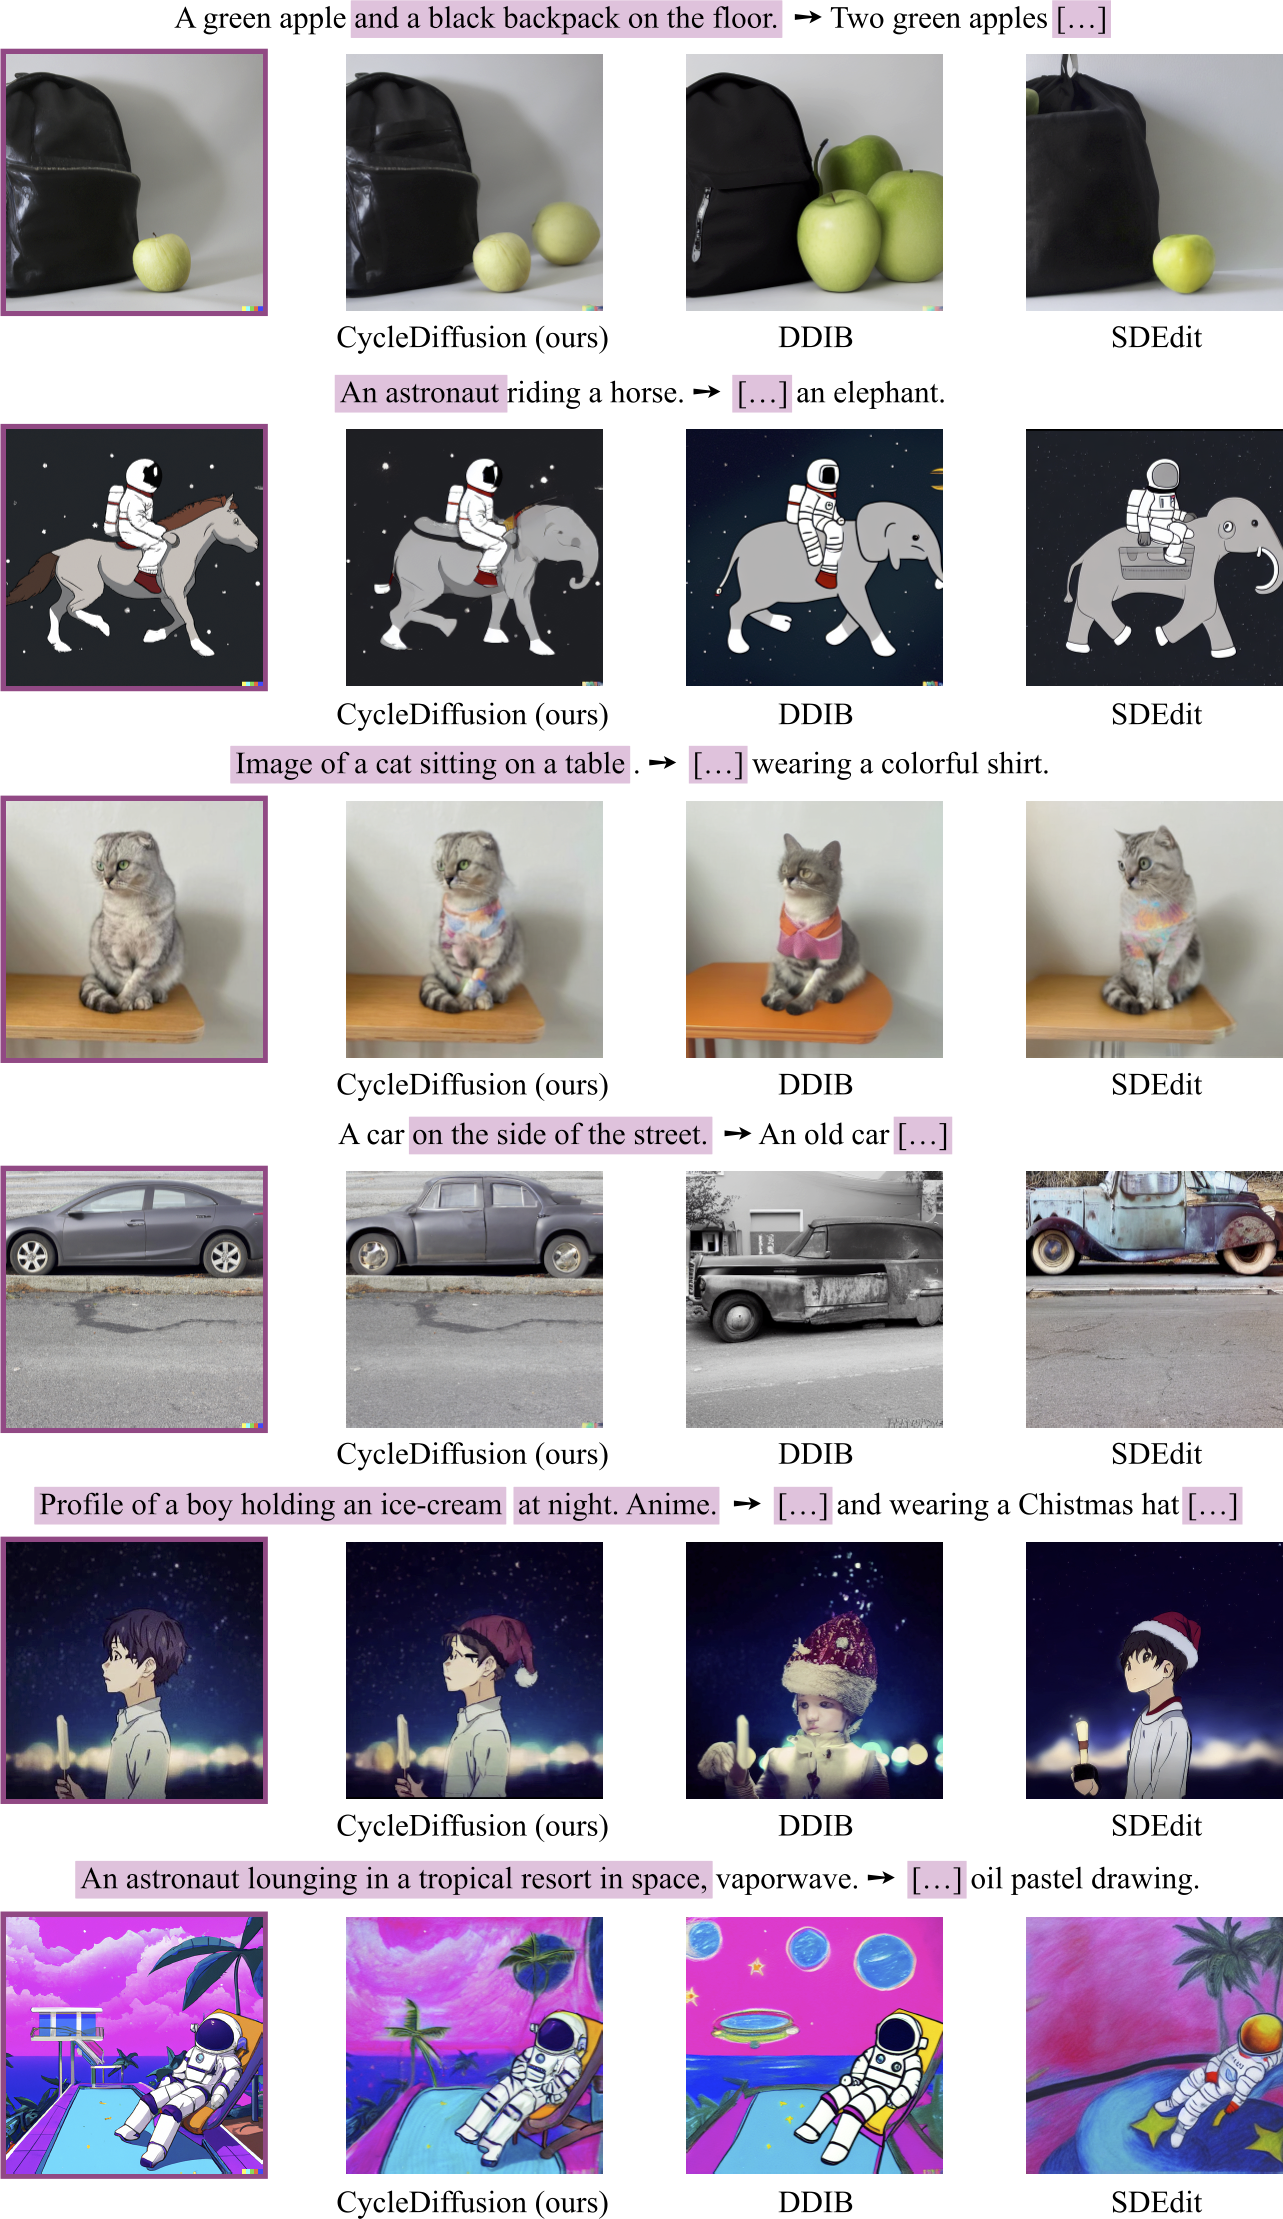
Here are some comparisons with baselines.
1. Create an environment by running
conda env create -f environment.yml
conda activate generative_prompt
pip install git+https://github.com/openai/CLIP.git
torch and torchvision based on your CUDA version.
3. Install taming-transformers by running
cd ../
git clone git@github.com:CompVis/taming-transformers.git
cd taming-transformers/
pip install -e .
cd ../
setup_wandb` function in `main.py`` to accomodate your wandb credentials. You may want to run something like
wandb login
1. Most data for zero-shot image-to-image translation are already included in data/. Some images are from the AFHQ validation set, detailed below. 2. Prepare the AFHQ validation set for unpaired image-to-image translation (also for some images used by zero-shot image-to-image translation) by running
git clone git@github.com:clovaai/stargan-v2.git
cd stargan-v2/
bash download.sh afhq-v2-dataset
1. Stable Diffusion
cd ckpts/
mkdir stable_diffusion
cd stable_diffusion/
Download pre-trained checkpoints for Stable Diffusion here.
You should download this version: https://huggingface.co/CompVis/stable-diffusion-v-1-4-original
Due to licence issues, we cannot share the pre-trained checkpoints directly.
cd ckpts/
wget https://www.dropbox.com/s/9lpdgs83l7tjk6c/ldm_models.zip
unzip ldm_models.zip
cd ldm_models/
mkdir text2img-large
cd text2img-large/
wget https://ommer-lab.com/files/latent-diffusion/nitro/txt2img-f8-large/model.ckpt
wget https://www.dropbox.com/s/7pdttimz78ll0km/txt2img-1p4B-eval.yaml
cd ckpts/
mkdir ddpm
cd ddpm/
Update Aug 4, 2023: it seems that the link below, originally from SDEdit, is broken. Please find other sources for CelebA-HQ (cf. issue #24)
wget https://image-editing-test-12345.s3-us-west-2.amazonaws.com/checkpoints/celeba_hq.ckpt
wget https://www.dropbox.com/s/g4h8sv07i3hj83d/ffhq_10m.pt
wget https://www.dropbox.com/s/u74w8vaw1f8lc4k/afhq_dog_4m.pt
wget https://www.dropbox.com/s/8i5aznjwdl3b5iq/cat_ema_0.9999_050000.pt
wget https://www.dropbox.com/s/tplximipy8zxaub/wild_ema_0.9999_050000.pt
wget https://www.dropbox.com/s/vqm6bxj0zslrjxv/configs.zip
unzip configs.zip
export CUDA_VISIBLE_DEVICES=0
export RUN_NAME=translate_text2img256_stable_diffusion_stochastic_1
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1405 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 4 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=1
export RUN_NAME=translate_text2img256_stable_diffusion_stochastic_2
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1424 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 4 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=2
export RUN_NAME=translate_text2img256_stable_diffusion_stochastic_3
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1423 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 4 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=3
export RUN_NAME=translate_text2img256_stable_diffusion_stochastic_4
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1422 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 4 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=4
export RUN_NAME=translate_text2img256_stable_diffusion_stochastic_5
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1429 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 4 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=5
export RUN_NAME=translate_text2img256_stable_diffusion_stochastic_6
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1428 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 4 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=6
export RUN_NAME=translate_text2img256_stable_diffusion_stochastic_7
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1427 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 4 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=7
export RUN_NAME=translate_text2img256_stable_diffusion_stochastic_8
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1426 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 4 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=0
export RUN_NAME=translate_text2img256_latentdiff_stochastic_1
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1465 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 16 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=1
export RUN_NAME=translate_text2img256_latentdiff_stochastic_2
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1485 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 16 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=2
export RUN_NAME=translate_text2img256_latentdiff_stochastic_3
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1486 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 16 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=3
export RUN_NAME=translate_text2img256_latentdiff_stochastic_4
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1487 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 16 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=4
export RUN_NAME=translate_text2img256_latentdiff_stochastic_5
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1488 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 16 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=5
export RUN_NAME=translate_text2img256_latentdiff_stochastic_6
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1489 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 16 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=6
export RUN_NAME=translate_text2img256_latentdiff_stochastic_7
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1411 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 16 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=7
export RUN_NAME=translate_text2img256_latentdiff_stochastic_8
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1412 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 16 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
decoder_unconditional_guidance_scales $\times$ skip_steps will be enumerated, and the best one is returned.
4. Run the following command to generate the image. Outputs will be saved in the output folder.
export CUDA_VISIBLE_DEVICES=0
export RUN_NAME=translate_text2img256_stable_diffusion_stochastic_custom
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1426 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 4 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
export CUDA_VISIBLE_DEVICES=1
export RUN_NAME=translate_afhqcat256_to_afhqdog256_ddim_eta01
export SEED=42
nohup python -m torch.distributed.launch --nproc_per_node 1 --master_port 1446 main.py --seed $SEED --cfg experiments/$RUN_NAME.cfg --run_name $RUN_NAME$SEED --logging_strategy steps --logging_first_step true --logging_steps 4 --evaluation_strategy steps --eval_steps 50 --metric_for_best_model CLIPEnergy --greater_is_better false --save_strategy steps --save_steps 50 --save_total_limit 1 --load_best_model_at_end --gradient_accumulation_steps 4 --num_train_epochs 0 --adafactor false --learning_rate 1e-3 --do_eval --output_dir output/$RUN_NAME$SEED --overwrite_output_dir --per_device_train_batch_size 1 --per_device_eval_batch_size 1 --eval_accumulation_steps 4 --ddp_find_unused_parameters true --verbose true > $RUN_NAME$SEED.log 2>&1 &
 →
 →
 →
 →
 →
 →