
1
 →
ChenHsing/Awesome-Video-Diffusion-Models is an open-source project on GitHub, mainly written in several languages. [CSUR] A Survey on Video Diffusion Models It currently holds 2,318 stars and 123 forks with 1 open issues, and was last pushed on 2026-09-04 (repository created 2023-08-01).
AI Homed tracks it on the AI Video Projects board and on the AI AI Video Projects list.


Zhen Xing, Qijun Feng, Haoran Chen, Qi Dai, Han Hu, Hang Xu, Zuxuan Wu, Yu-Gang Jiang
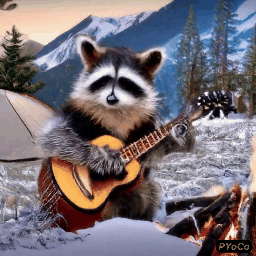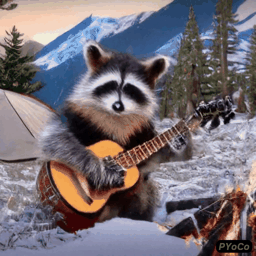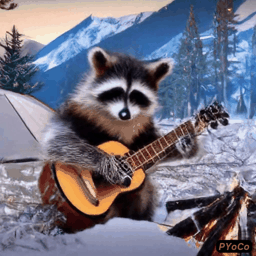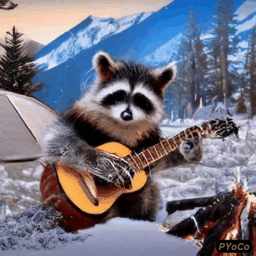
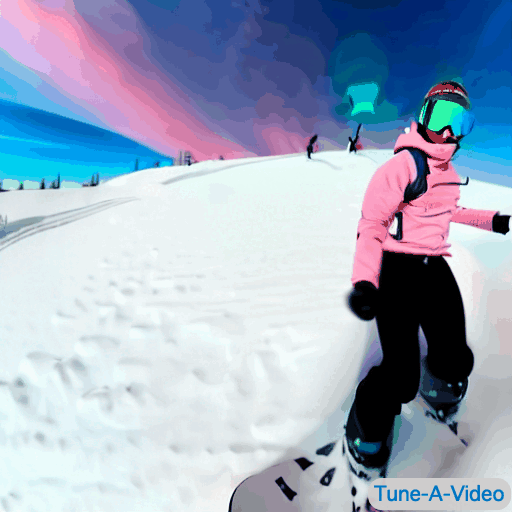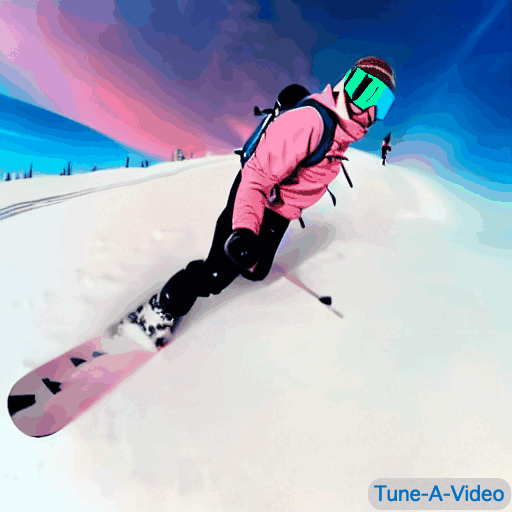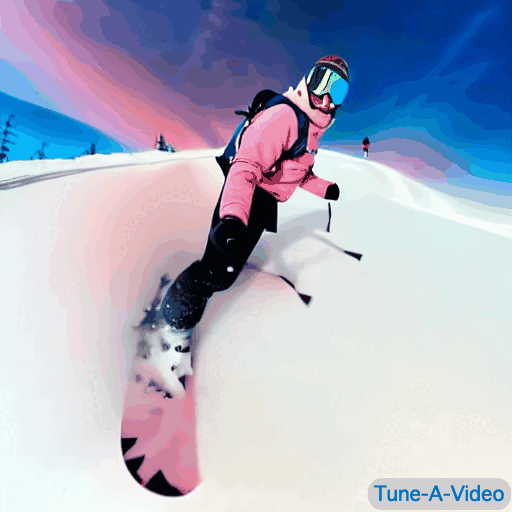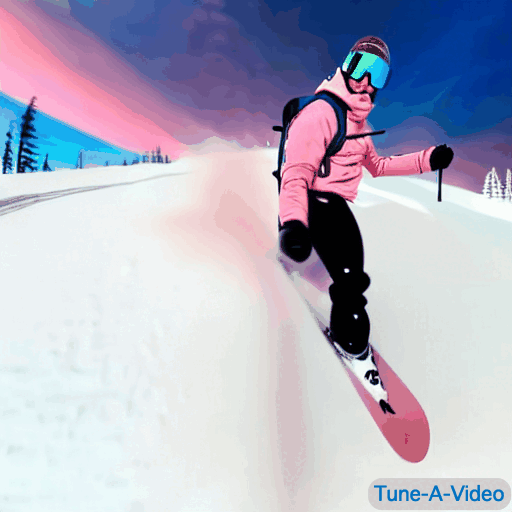
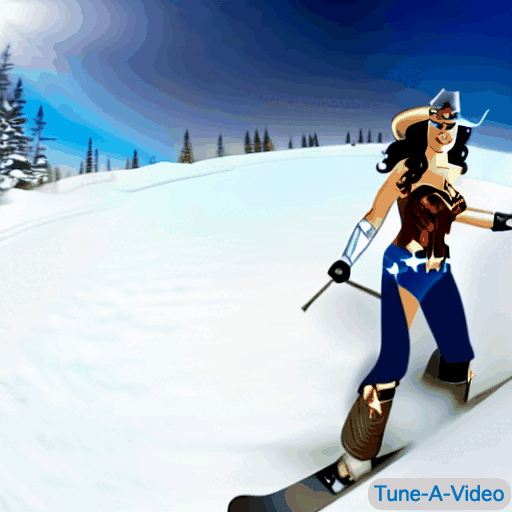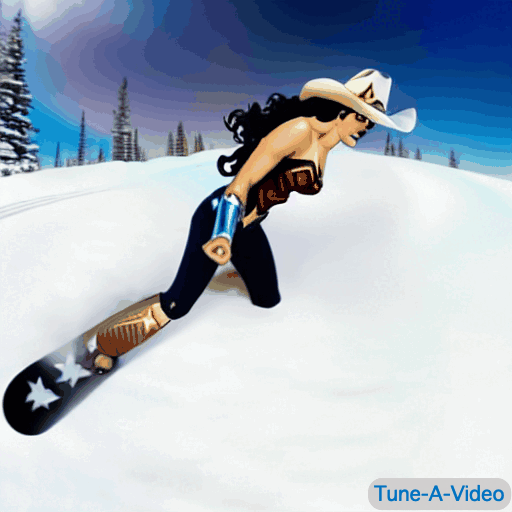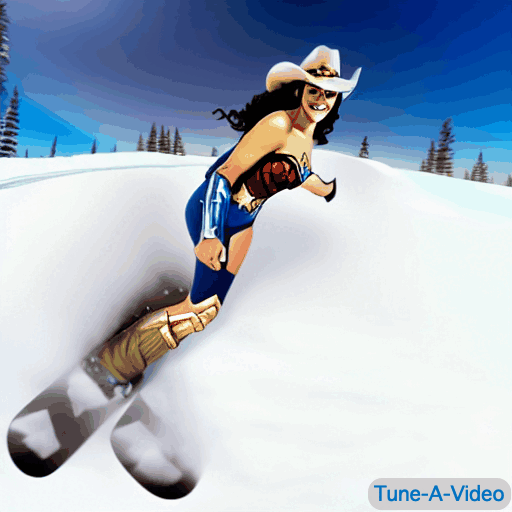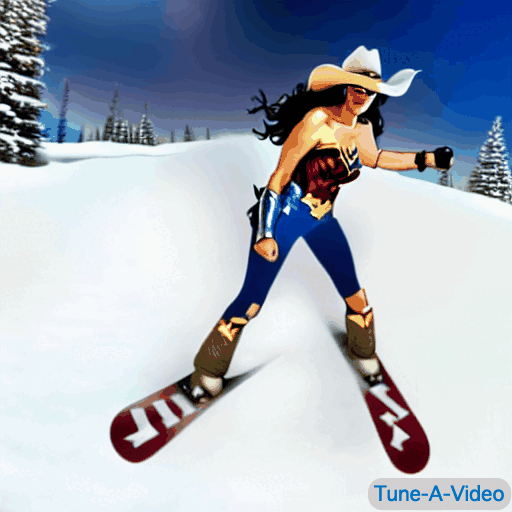
(Source: Make-A-Video, SimDA, PYoCo, SVD , Video LDM and Tune-A-Video)
Homepage: Zhen Xing
Email: zhenxingfd@gmail.com
If you find our survey is useful in your research or applications, please consider giving us a star 🌟 and citing it by the following BibTeX entry.
@article{xing2023survey,
  title={A survey on video diffusion models},
  author={Xing, Zhen and Feng, Qijun and Chen, Haoran and Dai, Qi and Hu, Han and Xu, Hang and Wu, Zuxuan and Jiang, Yu-Gang},
  journal={ACM Computing Surveys},
  year={2023},
  publisher={ACM New York, NY}
}
| Methods | Task | Github|
|:-----:|:-----:|:-----:|
| Helios | T2V Generation |  |
| Movie Gen | T2V Generation | -|
| CogVideoX | T2V Generation |
 |
| Open-Sora-Plan | T2V Generation |
 |
| Open-Sora | T2V Generation |
 |
| Morph Studio | T2V Generation | -|
| Genie | T2V Generation | -|
| Sora | T2V Generation & Editing | -|
| VideoPoet | T2V Generation & Editing | -|
| Stable Video Diffusion | T2V Generation |
 |
| NeverEnds | T2V Generation | - |
| Pika | T2V Generation | - |
| EMU-Video | T2V Generation | - |
| GEN-2 | T2V Generation & Editing | - |
| ModelScope | T2V Generation |
 |
| ZeroScope | T2V Generation | -|
| T2V Synthesis Colab | T2V Genetation |
 |
| VideoCraft | T2V Genetation & Editing |
 |
| Diffusers (T2V synthesis) | T2V Genetation |-|
| AnimateDiff | Personalized T2V Genetation |
 |
| Text2Video-Zero | T2V Genetation |
 |
| HotShot-XL | T2V Genetation |
 |
| Genmo | T2V Genetation |-|
| Fliki | T2V Generation | -|
| Seedream AI Studio | Image Generation + I2V Animation | -|
| Omni-Rewriter | Prompt Expansion (Video/Image PE) |
 |
| Title | arXiv | Github| WebSite | Pub. & Date
|:-----:|:-----:|:-----:|:-----:|:-----:|
| OpenS2V-Nexus: A Detailed Benchmark and Million-Scale Dataset for Subject-to-Video Generation | | |
| May, 2025 |
| Identity-Preserving Text-to-Video Generation by Frequency Decomposition |
| |
| CVPR, 2025 |
|ChronoMagic-Bench: A Benchmark for Metamorphic Evaluation of Text-to-Time-lapse Video Generation |
|  |
| NeurIPS, 2024 |
|Panda-70M: Captioning 70M Videos with Multiple Cross-Modality Teachers |
|  |
| CVPR, 2024 |
|CelebV-Text: A Large-Scale Facial Text-Video Dataset|
|  | - | CVPR, 2023
|InternVid: A Large-scale Video-Text Dataset for Multimodal Understanding and Generation | |
 | - | May, 2023 |
|VideoFactory: Swap Attention in Spatiotemporal Diffusions for Text-to-Video Generation| | - | - | May, 2023|
|Advancing High-Resolution Video-Language Representation with Large-Scale Video Transcriptions | |- |- |Nov, 2021 |
| Frozen in Time: A Joint Video and Image Encoder for End-to-End Retrieval | | - | - |ICCV, 2021 |
|MSR-VTT: A Large Video Description Dataset for Bridging Video and Language | | -| -| CVPR, 2016|
| MiniMax H3 1K Prompt Dataset | |
 |
| 2026 |
| Title | arXiv | Github| WebSite | Pub. & Date
|:-----:|:-----:|:-----:|:-----:|:-----:|
|UCF101: A Dataset of 101 Human Actions Classes From Videos in The Wild| | - | - | Dec., 2012
|First Order Motion Model for Image Animation | | -|- | May, 2023 |
|Learning to Generate Time-Lapse Videos Using Multi-Stage Dynamic Generative Adversarial Networks | | -| -| CVPR,2018|
| Title | arXiv | Github| WebSite | Pub. & Date
|:-----:|:-----:|:-----:|:-----:|:-----:|
| OpenS2V-Nexus: A Detailed Benchmark and Million-Scale Dataset for Subject-to-Video Generation | || | May, 2025 |
|Fréchet Video Motion Distance: A Metric for Evaluating Motion Consistency in Videos |
|  | - | Jul., 2024 |
|ChronoMagic-Bench: A Benchmark for Metamorphic Evaluation of Text-to-Time-lapse Video Generation | | |
| NeurIPS, 2024 |
| STREAM: Spatio-TempoRal Evaluation and Analysis Metric for Video Generative Models |
| |- | ICLR, 2024
| Subjective-Aligned Dateset and Metric for Text-to-Video Quality Assessment | |-|- | Mar, 2024
| Towards A Better Metric for Text-to-Video Generation | |-|
| Jan, 2024
|AIGCBench: Comprehensive Evaluation of Image-to-Video Content Generated by AI |
| - | - | Jan, 2024 |
| VBench: Comprehensive Benchmark Suite for Video Generative Models | | |
| Nov, 2023
| VideoScore2: Think before You Score in Generative Video Evaluation |
| |
| Sep, 2025
|FETV: A Benchmark for Fine-Grained Evaluation of Open-Domain Text-to-Video Generation |
| - | - | NeurIPS, 2023 |
|CVPR 2023 Text Guided Video Editing Competition | | - | - | Oct., 2023 |
|EvalCrafter: Benchmarking and Evaluating Large Video Generation Models | |  |
| Oct., 2023 |
|Measuring the Quality of Text-to-Video Model Outputs: Metrics and Dataset |
| - | - | Sep., 2023 |
| Title | arXiv | Github | WebSite | Pub. & Date |
|---|---|---|---|---|
| Helios: Real Real-Time Long Video Generation Model | || | Arxiv, 2026
| Identity-Preserving Text-to-Video Generation by Frequency Decomposition |
|| | CVPR, 2025
| Enhancing Motion in Text-to-Video Generation with Decomposed Encoding and Conditioning |
| |
| NeurIPS 2024
| Movie Gen |
|-| | Oct, 2024
| CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer |
||-| Oct, 2024
| Grid Diffusion Models for Text-to-Video Generation | | |
| CVPR, 2024
| MagicTime: Time-lapse Video Generation Models as Metamorphic Simulators |
| |
| Apr., 2024
| Mora: Enabling Generalist Video Generation via A Multi-Agent Framework |
|-|- | Mar., 2024
| VSTAR: Generative Temporal Nursing for Longer Dynamic Video Synthesis | |-|- | Mar., 2024
| Genie: Generative Interactive Environments | |-| | Feb., 2024
| Snap Video: Scaled Spatiotemporal Transformers for Text-to-Video Synthesis |
|-| | Feb., 2024
| Lumiere: A Space-Time Diffusion Model for Video Generation |
|-| | Jan, 2024
| UNIVG: TOWARDS UNIFIED-MODAL VIDEO GENERATION |
|-| | Jan, 2024
| VideoCrafter2: Overcoming Data Limitations for High-Quality Video Diffusion Models |
|| | Jan, 2024
| 360DVD: Controllable Panorama Video Generation with 360-Degree Video Diffusion Model |
|-|[ →
 →
 →
 →
 →
 →
 →