ChaofanTao/Autoregressive-Models-in-Vision-Survey
[TMLR 2025🔥] A survey for the autoregressive models in vision.
About ChaofanTao/Autoregressive-Models-in-Vision-Survey
ChaofanTao/Autoregressive-Models-in-Vision-Survey is an open-source project on GitHub, mainly written in several languages. [TMLR 2025🔥] A survey for the autoregressive models in vision. It currently holds 807 stars and 22 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
Project Overview
AI Homed tracks it on the AI Image Projects board and on the AI AI Image Projects list.
GitHub Repository Details
README
[TMLR 2025] Awesome Autoregressive Models in Vision
If you like our project, please give us a star ⭐ on GitHub for the latest update.
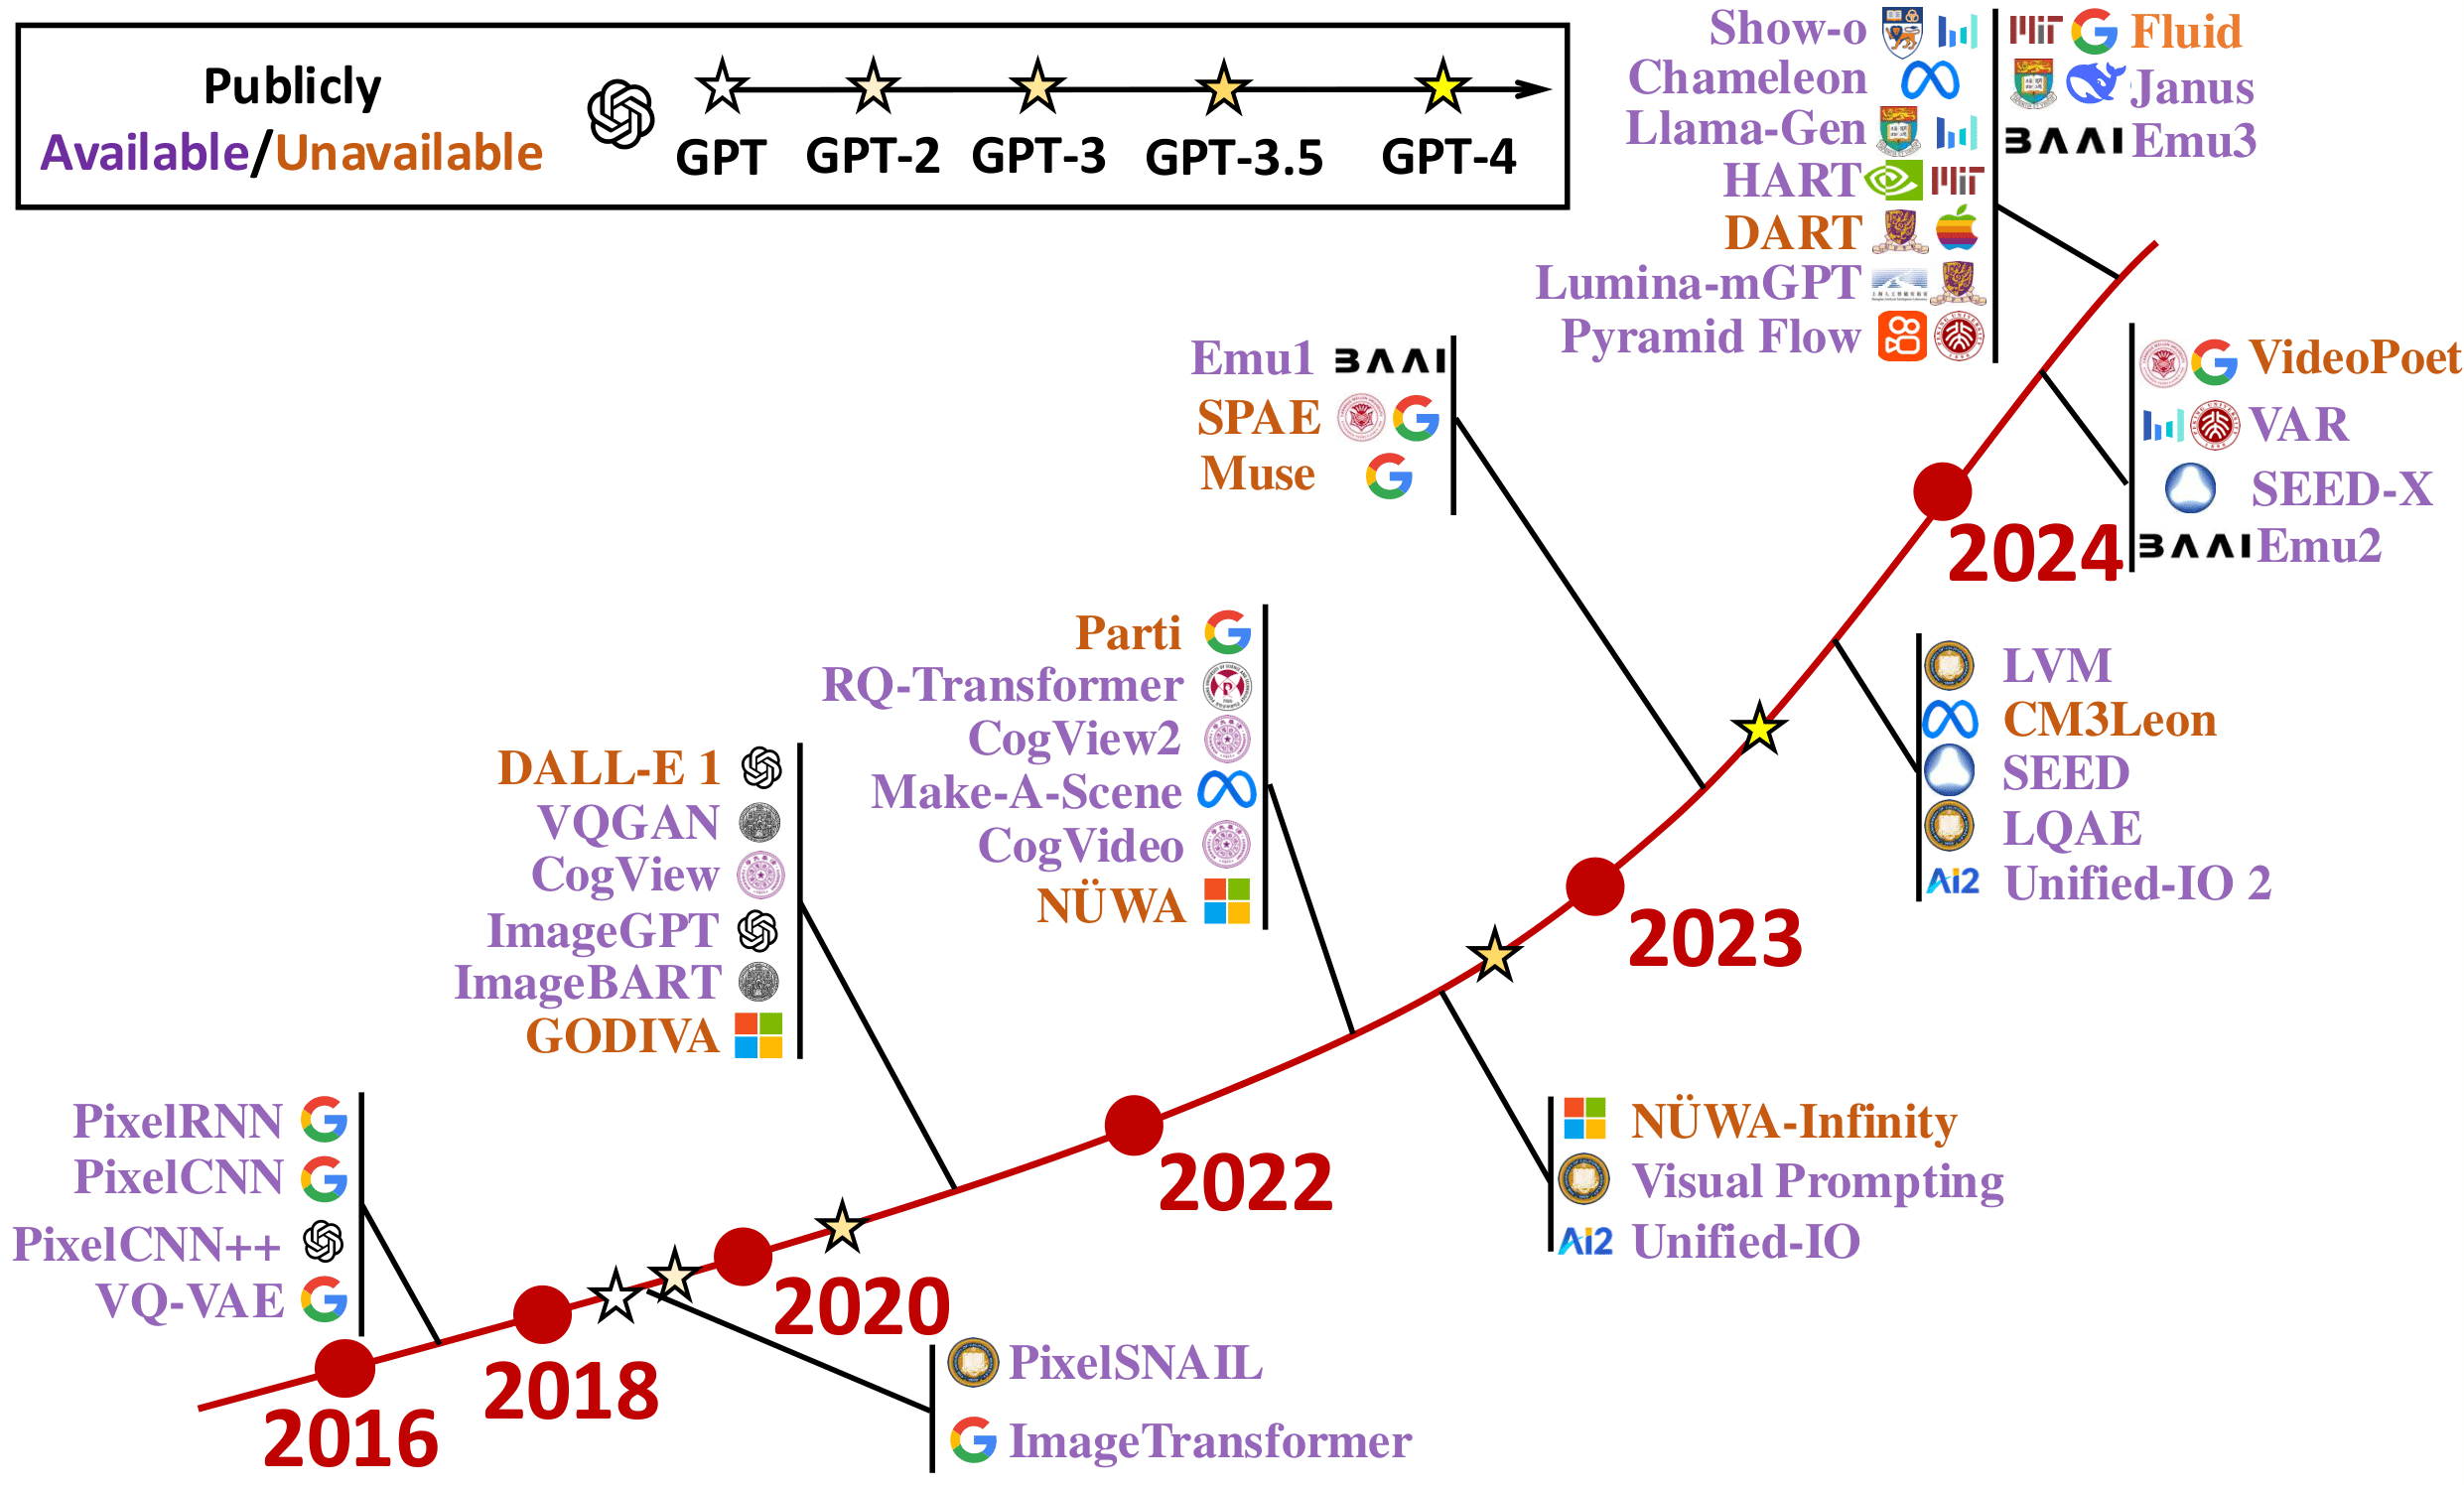
Autoregressive models have shown significant progress in generating high-quality content by modeling the dependencies sequentially. This repo is a curated list of papers about the latest advancements in autoregressive models in vision.
Paper: [[TMLR 2025🔥]](https://openreview.net/forum?id=1BqXkjNEGP) Autoregressive Models in Vision: A Survey | [[中文解读]](https://mp.weixin.qq.com/s/_O8W1qgvMZu37IKwgtskMA)
Authors: Jing Xiong1,†, Gongye Liu2,†, Lun Huang3, Chengyue Wu1, Taiqiang Wu1, Yao Mu1, Yuan Yao4, Hui Shen5, Zhongwei Wan5, Jinfa Huang4, Chaofan Tao1,‡, Shen Yan6, Huaxiu Yao7, Lingpeng Kong1, Hongxia Yang9, Mi Zhang5, Guillermo Sapiro8,10, Jiebo Luo4, Ping Luo1, Ngai Wong1
1The University of Hong Kong, 2Tsinghua University, 3Duke University, 4University of Rochester, 5The Ohio State University, 6Bytedance, 7The University of North Carolina at Chapel Hill, 8Apple, 9The Hong Kong Polytechnic University, 10Princeton University
† Core Contributors, ‡ Corresponding Authors
💡 We also have other generative projects that may interest you ✨.
[Personalized Video Generation: Progress, Applications, and Challenges]()
Jinfa Huang, Shenghai Yuan, Kunyang Li, and Meng Cao etc.
📑 Citation
Please consider citing 📑 our papers if our repository is helpful to your work. Thanks sincerely!
@misc{xiong2024autoregressive,
title={Autoregressive Models in Vision: A Survey},
author={Jing Xiong and Gongye Liu and Lun Huang and Chengyue Wu and Taiqiang Wu and Yao Mu and Yuan Yao and Hui Shen and Zhongwei Wan and Jinfa Huang and Chaofan Tao and Shen Yan and Huaxiu Yao and Lingpeng Kong and Hongxia Yang and Mi Zhang and Guillermo Sapiro and Jiebo Luo and Ping Luo and Ngai Wong},
year={2024},
eprint={2411.05902},
archivePrefix={arXiv},
primaryClass={cs.CV}
}
📣 Update News
[2025-11-01] ⏸️ After a year of rapid progress in autoregressive visual generation, two clear trends now define the field: unified multimodal models and autoregressive diffusion-forcing video generation. Our current repository categories no longer capture this evolving landscape, so we’re moving to maintenance mode and pausing proactive updates as of today. The repo remains available as a reference, and targeted PRs are welcome (additions, corrections, or reorganizations with new trends). Thanks for your support! 🙏
[2025-05-31] 🔥 Our survey has been revised in arXiv! The revised paper streamlines content and enhances discussions on:
- Continuous autoregressive methods
- Computational costs
- More details about metrics
- Expands future application roadmaps
[2025-03-11] 🔥 Our survey has been accepted by TMLR 2025!
[2024-11-11] We have released the survey: Autoregressive Models in Vision: A Survey.
[2024-10-13] We have initialed the repository.
⚡ Contributing
We welcome feedback, suggestions, and contributions that can help improve this survey and repository and make them valuable resources for the entire community.
We will actively maintain this repository by incorporating new research as it emerges. If you have any suggestions about our taxonomy, please take a look at any missed papers, or update any preprint arXiv paper that has been accepted to some venue.
If you want to add your work or model to this list, please do not hesitate to email jhuang90@ur.rochester.edu or pull requests). Markdown format:
* [Name of Conference or Journal + Year] Paper Name. Paper Code
📖 Table of Contents
- Image Generation
- Unconditional/Class-Conditioned Image Generation
- Text-to-Image Generation
- Image-to-Image Translation
- Image Editing
- Video Generation
- Unconditional Video Generation
- Conditional Video Generation
- Embodied AI
- 3D Generation
- Motion Generation
- Point Cloud Generation
- 3D Medical Generation
- Multimodal Generation
- Unified Understanding and Generation Multi-Modal LLMs
- Other Generation
- Benchmark / Analysis
- Reasoning Alignment
- Safety
- Accelerating
- Stability \& Scaling
- Tutorial
- Evaluation Metrics
-----
Image Generation
Unconditional/Class-Conditioned Image Generation
- ##### Pixel-wise Generation
- [ICML, 2021 oral] Improved Autoregressive Modeling with Distribution Smoothing Paper Code
- [ICML, 2020] ImageGPT: Generative Pretraining from Pixels Paper
- [ICML, 2018] Image Transformer Paper Code
- [ICML, 2018] PixelSNAIL: An Improved Autoregressive Generative Model Paper Code
- [ICML, 2017] Parallel Multiscale Autoregressive Density Estimation Paper
- [ICLR workshop, 2017] Gated PixelCNN: Generating Interpretable Images with Controllable Structure Paper
- [ICLR, 2017] PixelCNN++: Improving the PixelCNN with Discretized Logistic Mixture Likelihood and Other Modifications Paper Code
- [NeurIPS, 2016] PixelCNN Conditional Image Generation with PixelCNN Decoders Paper Code
- [ICML, 2016] PixelRNN Pixel Recurrent Neural Networks Paper Code
- ##### Token-wise Generation
##### Tokenizer
- [Arxiv, 2025.07] Vision Foundation Models as Effective Visual Tokenizers for Autoregressive Generation Paper Code
- [Arxiv, 2025.07] Holistic Tokenizer for Autoregressive Image Generation Paper Code
- [Arxiv, 2025.06] Instella-T2I: Pushing the Limits of 1D Discrete Latent Space Image Generation Paper
- [Arxiv, 2025.05] D-AR: Diffusion via Autoregressive Models Paper Code
- [Arxiv, 2025.05] Learning Adaptive and Temporally Causal Video Tokenization in a 1D Latent Space Paper Code
- [Arxiv, 2025.04] Distilling semantically aware orders for autoregressive image generation Paper
- [Arxiv, 2025.04] Token-Shuffle: Towards High-Resolution Image Generation with Autoregressive Models Paper
- [CVPR, 2025] Improving Autoregressive Visual Generation with Cluster-Oriented Token Prediction Code Paper
- [Arxiv, 2025.03] Equivariant Image Modeling Paper Code
- [Arxiv, 2025.03] V2Flow: Unifying Visual Tokenization and Large Language Model Vocabularies for Autoregressive Image Generation Paper Code
- [Arxiv, 2025.02] FlexTok: Resampling Images into 1D Token Sequences of Flexible Length Paper
- [Arxiv, 2025.01] ARFlow: Autogressive Flow with Hybrid Linear Attention Paper Code
- [Arxiv, 2024.12] TokenFlow: Unified Image Tokenizer for Multimodal Understanding and Generation Paper Code
- [Arxiv, 2024.12] Next Patch Prediction for Autoregressive Visual Generation Paper Code
- [Arxiv, 2024.12] XQ-GAN: An Open-source Image Tokenization Framework for Autoregressive Generation Paper Code
- [Arxiv, 2024.12] RandAR: Decoder-only Autoregressive Visual Generation in Random Orders. Paper Code Project
- [Arxiv, 2024.11] Randomized Autoregressive Visual Generation. Paper Code Project
- [Arxiv, 2024.09] Open-MAGVIT2: Democratizing Autoregressive Visual Generation Paper Code
- [Arxiv, 2024.06] OmniTokenizer: A Joint Image-Video Tokenizer for Visual Generation Paper Code
- [Arxiv, 2024.06] Scaling the Codebook Size of VQGAN to 100,000 with a Utilization Rate of 99% Paper Code
- [Arxiv, 2024.06] Titok An Image is Worth 32 Tokens for Reconstruction and Generation Paper Code
- [Arxiv, 2024.06] Wavelets Are All You Need for Autoregressive Image Generation Paper
- [Arxiv, 2024.06] LlamaGen Autoregressive Model Beats Diffusion: Llama for Scalable Image Generation Paper Code
- [ICLR, 2024] MAGVIT-v2 Language Model Beats Diffusion -- Tokenizer is Key to Visual Generation Paper
- [ICLR, 2024] FSQ Finite scalar quantization: Vq-vae made simple Paper Code
- [ICCV, 2023] Efficient-VQGAN: Towards High-Resolution Image Generation with Efficient Vision Transformers Paper
- [CVPR, 2023] Towards Accurate Image Coding: Improved Autoregressive Image Generation with Dynamic Vector Quantization Paper Code
- [CVPR, 2023, Highlight] MAGVIT: Masked Generative Video Transformer Paper
- [NeurIPS, 2023] MoVQ: Modulating Quantized Vectors for High-Fidelity Image Generation Paper
- [BMVC, 2022] Unconditional image-text pair generation with multimodal cross quantizer Paper Code
- [CVPR, 2022] RQ-VAE Autoregressive Image Generation Using Residual Quantization Paper Code
- [ICLR, 2022] ViT-VQGAN Vector-quantized Image Modeling with Improved VQGAN Paper
- [PMLR, 2021] Generating images with sparse representations Paper
- [CVPR, 2021] VQGAN Taming Transformers for High-Resolution Image Synthesis Paper Code
- [NeurIPS, 2019] Generating Diverse High-Fidelity Images with VQ-VAE-2 Paper Code
- [NeurIPS, 2017] VQ-VAE Neural Discrete Representation Learning Paper
##### Autoregressive Modeling
- [Arxiv, 2025.11] InfinityStar: Unified Spacetime AutoRegressive Modeling for Visual Generation Paper Code
- [Arxiv, 2025.10] FARMER: Flow AutoRegressive Transformer over Pixels Paper
- [Arxiv, 2025.10] SSD: Spatial-Semantic Head Decoupling for Efficient Autoregressive Image Generation Paper
- [NeurIPS, 2025] Visual Autoregressive Models Beat Diffusion Models on Inference Time Scaling Paper
- [NeurIPS, 2025] Towards Better & Faster Autoregressive Image Generation: From the Perspective of Entropy Paper Code
- [Arxiv, 2025.09] Hyperspherical Latents Improve Continuous-Token Autoregressive Generation Paper Code
- [Arxiv, 2025.09] Go with Your Gut: Scaling Confidence for Autoregressive Image Generation Paper Code
- [NeurIPS, 2025] Understand Before You Generate: Self-Guided Training for Autoregressive Image Generation Paper Code
- [Arxiv, 2025.08] Exploiting Discriminative Codebook Prior for Autoregressive Image Generation Paper
- [Arxiv, 2025.08] NextStep-1: Toward Autoregressive Image Generation with Continuous Tokens at Scale Paper Code
- [Arxiv, 2025.07] Frequency-Aware Autoregressive Modeling for Efficient High-Resolution Image Synthesis Paper Code
- [Arxiv, 2025.07] TTS-VAR: A Test-Time Scaling Framework for Visual Auto-Regressive Generation Paper Code
- [Arxiv, 2025.07] Transition Matching: Scalable and Flexible Generative Modeling Paper
- [Arxiv, 2025.07] Rethinking Discrete Tokens: Treating Them as Conditions for Continuous Autoregressive Image Synthesis Paper
- [CVPR, 2025] OmniGen: Unified Image Generation Paper Code
- [Arxiv, 2025.06] AR-RAG: Autoregressive Retrieval Augmentation for Image Generation Paper Code
- [Arxiv, 2025.06] Marrying Autoregressive Transformer and Diffusion with Multi-Reference Autoregression Paper Code
- [Arxiv, 2025.06] MADFormer: Mixed Autoregressive and Diffusion Transformers for Continuous Image Generation Paper
- [Arxiv, 2025.06] SpectralAR: Spectral Autoregressive Visual Generation Paper Code
- [Arxiv, 2025.06] AliTok: Towards Sequence Modeling Alignment between Tokenizer and Autoregressive Model Paper Code
- [Arxiv, 2025.05] DetailFlow: 1D Coarse-to-Fine Autoregressive Image Generation via Next-Detail Prediction Paper Code
- [Arxiv, 2025.05] TensorAR: Refinement is All You Need in Autoregressive Image Generation Paper
- [Arxiv, 2025.05] MVAR: Visual Autoregressive Modeling with Scale and Spatial Markovian Conditioning Paper Code
- [ICML, 2025] Continuous Visual Autoregressive Generation via Score Maximization Paper Code
- [Arxiv, 2025.04] GigaTok: Scaling Visual Tokenizers to 3 Billion Parameters for Autoregressive Image Generation Paper Code
- [Arxiv, 2025.03] D2C: Unlocking the Potential of Continuous Autoregressive Image Generation with Discrete Tokens Paper
- [Arxiv, 2025.03] Bridging Continuous and Discrete Tokens for Autoregressive Visual Generation Paper Code
- [Arxiv, 2025.03] Autoregressive Image Generation with Randomized Parallel Decoding Paper Code
- [Arxiv, 2025.03] Direction-Aware Diagonal Autoregressive Image Generation Paper
- [Arxiv, 2025.03] Neighboring Autoregressive Modeling for Efficient Visual Generation Paper Code
- [Arxiv, 2025.03] NFIG: Autoregressive Image Generation with Next-Frequency Prediction Paper
- [Arxiv, 2025.03] Frequency Autoregressive Image Generation with Continuous Tokens Paper Code
- [Arxiv, 2025.03] ARINAR: Bi-Level Autoregressive Feature-by-Feature Generative Models Paper Code
- [Arxiv, 2025.02] Beyond Next-Token: Next-X Prediction for Autoregressive Visual Generation Paper Code Project
- [Arxiv, 2025.02] Fractal Generative Models Paper Code
- [Arxiv, 2025.01] An Empirical Study of Autoregressive Pre-training from Videos Paper
- [Arxiv, 2024.12] E-CAR: Efficient Continuous Autoregressive Image Generation via Multistage Modeling Paper
- [Arxiv, 2024.12] Taming Scalable Visual Tokenizer for Autoregressive Image Generation Paper Code
- [Arxiv, 2024.11] Sample- and Parameter-Efficient Auto-Regressive Image Models Paper Code
- [Arxiv, 2024.01] Scalable Pre-training of Large Autoregressive Image Models Paper Code
- [Arxiv, 2024.10] ImageFolder: Autoregressive Image Generation with Folded Tokens Paper Code
- [Arxiv, 2024.10] SAR Customize Your Visual Autoregressive Recipe with Set Autoregressive Modeling Paper Code
- [Arxiv, 2024.08] AiM Scalable Autoregressive Image Generation with Mamba Paper Code
- [Arxiv, 2024.06] ARM Autoregressive Pretraining with Mamba in Vision Paper Code
- [Arxiv, 2024.06] MAR Autoregressive Image Generation without Vector Quantization Paper Code
- [Arxiv, 2024.06] LlamaGen Autoregressive Model Beats Diffusion: Llama for Scalable Image Generation Paper Code
- [ICML, 2024] DARL: Denoising Autoregressive Representation Learning Paper
- [ICML, 2024] DisCo-Diff: Enhancing Continuous Diffusion Models with Discrete Latents Paper Code
- [ICML, 2024] DeLVM: Data-efficient Large Vision Models through Sequential Autoregression Paper Code
- [AAAI, 2023] SAIM Exploring Stochastic Autoregressive Image Modeling for Visual Representation Paper Code
- [NeurIPS, 2021] ImageBART: Context with Multinomial Diffusion for Autoregressive Image Synthesis Paper Code
- [CVPR, 2021] VQGAN Taming Transformers for High-Resolution Image Synthesis Paper Code
- [ECCV, 2020] RAL: Incorporating Reinforced Adversarial Learning in Autoregressi
GitHub Stars & Activity
807Stars22Forks0Open issues-Language
GitHub Popularity
GitHub stars807Forks22Open issues0Primary language-License-Stars gained today0Created-Last pushed-
Trending History
Trending statusnot on today's boards
Related AI Projects
1
→ 2
→ 3
→ 4
→ 5
→ 6
→ 7
→ 8
→
More AI Rankings
If you like our project, please give us a star ⭐ on GitHub for the latest update.
Autoregressive models have shown significant progress in generating high-quality content by modeling the dependencies sequentially. This repo is a curated list of papers about the latest advancements in autoregressive models in vision.
Paper: [[TMLR 2025🔥]](https://openreview.net/forum?id=1BqXkjNEGP) Autoregressive Models in Vision: A Survey | [[中文解读]](https://mp.weixin.qq.com/s/_O8W1qgvMZu37IKwgtskMA)
Authors: Jing Xiong1,†, Gongye Liu2,†, Lun Huang3, Chengyue Wu1, Taiqiang Wu1, Yao Mu1, Yuan Yao4, Hui Shen5, Zhongwei Wan5, Jinfa Huang4, Chaofan Tao1,‡, Shen Yan6, Huaxiu Yao7, Lingpeng Kong1, Hongxia Yang9, Mi Zhang5, Guillermo Sapiro8,10, Jiebo Luo4, Ping Luo1, Ngai Wong1
1The University of Hong Kong, 2Tsinghua University, 3Duke University, 4University of Rochester, 5The Ohio State University, 6Bytedance, 7The University of North Carolina at Chapel Hill, 8Apple, 9The Hong Kong Polytechnic University, 10Princeton University
† Core Contributors, ‡ Corresponding Authors
💡 We also have other generative projects that may interest you ✨.
[Personalized Video Generation: Progress, Applications, and Challenges]()
Jinfa Huang, Shenghai Yuan, Kunyang Li, and Meng Cao etc.
📑 Citation
Please consider citing 📑 our papers if our repository is helpful to your work. Thanks sincerely!@misc{xiong2024autoregressive,
title={Autoregressive Models in Vision: A Survey},
author={Jing Xiong and Gongye Liu and Lun Huang and Chengyue Wu and Taiqiang Wu and Yao Mu and Yuan Yao and Hui Shen and Zhongwei Wan and Jinfa Huang and Chaofan Tao and Shen Yan and Huaxiu Yao and Lingpeng Kong and Hongxia Yang and Mi Zhang and Guillermo Sapiro and Jiebo Luo and Ping Luo and Ngai Wong},
year={2024},
eprint={2411.05902},
archivePrefix={arXiv},
primaryClass={cs.CV}
}
📣 Update News
[2025-11-01] ⏸️ After a year of rapid progress in autoregressive visual generation, two clear trends now define the field: unified multimodal models and autoregressive diffusion-forcing video generation. Our current repository categories no longer capture this evolving landscape, so we’re moving to maintenance mode and pausing proactive updates as of today. The repo remains available as a reference, and targeted PRs are welcome (additions, corrections, or reorganizations with new trends). Thanks for your support! 🙏
[2025-05-31] 🔥 Our survey has been revised in arXiv! The revised paper streamlines content and enhances discussions on:
- Continuous autoregressive methods
- Computational costs
- More details about metrics
- Expands future application roadmaps
[2025-03-11] 🔥 Our survey has been accepted by TMLR 2025!
[2024-11-11] We have released the survey: Autoregressive Models in Vision: A Survey.
[2024-10-13] We have initialed the repository.
⚡ Contributing
We welcome feedback, suggestions, and contributions that can help improve this survey and repository and make them valuable resources for the entire community. We will actively maintain this repository by incorporating new research as it emerges. If you have any suggestions about our taxonomy, please take a look at any missed papers, or update any preprint arXiv paper that has been accepted to some venue.
If you want to add your work or model to this list, please do not hesitate to email jhuang90@ur.rochester.edu or pull requests). Markdown format:
* [Name of Conference or Journal + Year] Paper Name. Paper Code
📖 Table of Contents
- Image Generation
- Unconditional/Class-Conditioned Image Generation
- Text-to-Image Generation
- Image-to-Image Translation
- Image Editing
- Video Generation
- Unconditional Video Generation
- Conditional Video Generation
- Embodied AI
- 3D Generation
- Motion Generation
- Point Cloud Generation
- 3D Medical Generation
- Multimodal Generation
- Unified Understanding and Generation Multi-Modal LLMs
- Other Generation
- Benchmark / Analysis
- Reasoning Alignment
- Safety
- Accelerating
- Stability \& Scaling
- Tutorial
- Evaluation Metrics
Image Generation
Unconditional/Class-Conditioned Image Generation
- ##### Pixel-wise Generation
- [ICML, 2021 oral] Improved Autoregressive Modeling with Distribution Smoothing Paper Code
- [ICML, 2020] ImageGPT: Generative Pretraining from Pixels Paper
- [ICML, 2018] Image Transformer Paper Code
- [ICML, 2018] PixelSNAIL: An Improved Autoregressive Generative Model Paper Code
- [ICML, 2017] Parallel Multiscale Autoregressive Density Estimation Paper
- [ICLR workshop, 2017] Gated PixelCNN: Generating Interpretable Images with Controllable Structure Paper
- [ICLR, 2017] PixelCNN++: Improving the PixelCNN with Discretized Logistic Mixture Likelihood and Other Modifications Paper Code
- [NeurIPS, 2016] PixelCNN Conditional Image Generation with PixelCNN Decoders Paper Code
- [ICML, 2016] PixelRNN Pixel Recurrent Neural Networks Paper Code
- ##### Token-wise Generation
- [Arxiv, 2025.07] Vision Foundation Models as Effective Visual Tokenizers for Autoregressive Generation Paper Code
- [Arxiv, 2025.07] Holistic Tokenizer for Autoregressive Image Generation Paper Code
- [Arxiv, 2025.06] Instella-T2I: Pushing the Limits of 1D Discrete Latent Space Image Generation Paper
- [Arxiv, 2025.05] D-AR: Diffusion via Autoregressive Models Paper Code
- [Arxiv, 2025.05] Learning Adaptive and Temporally Causal Video Tokenization in a 1D Latent Space Paper Code
- [Arxiv, 2025.04] Distilling semantically aware orders for autoregressive image generation Paper
- [Arxiv, 2025.04] Token-Shuffle: Towards High-Resolution Image Generation with Autoregressive Models Paper
- [CVPR, 2025] Improving Autoregressive Visual Generation with Cluster-Oriented Token Prediction Code Paper
- [Arxiv, 2025.03] Equivariant Image Modeling Paper Code
- [Arxiv, 2025.03] V2Flow: Unifying Visual Tokenization and Large Language Model Vocabularies for Autoregressive Image Generation Paper Code
- [Arxiv, 2025.02] FlexTok: Resampling Images into 1D Token Sequences of Flexible Length Paper
- [Arxiv, 2025.01] ARFlow: Autogressive Flow with Hybrid Linear Attention Paper Code
- [Arxiv, 2024.12] TokenFlow: Unified Image Tokenizer for Multimodal Understanding and Generation Paper Code
- [Arxiv, 2024.12] Next Patch Prediction for Autoregressive Visual Generation Paper Code
- [Arxiv, 2024.12] XQ-GAN: An Open-source Image Tokenization Framework for Autoregressive Generation Paper Code
- [Arxiv, 2024.12] RandAR: Decoder-only Autoregressive Visual Generation in Random Orders. Paper Code Project
- [Arxiv, 2024.11] Randomized Autoregressive Visual Generation. Paper Code Project
- [Arxiv, 2024.09] Open-MAGVIT2: Democratizing Autoregressive Visual Generation Paper Code
- [Arxiv, 2024.06] OmniTokenizer: A Joint Image-Video Tokenizer for Visual Generation Paper Code
- [Arxiv, 2024.06] Scaling the Codebook Size of VQGAN to 100,000 with a Utilization Rate of 99% Paper Code
- [Arxiv, 2024.06] Titok An Image is Worth 32 Tokens for Reconstruction and Generation Paper Code
- [Arxiv, 2024.06] Wavelets Are All You Need for Autoregressive Image Generation Paper
- [Arxiv, 2024.06] LlamaGen Autoregressive Model Beats Diffusion: Llama for Scalable Image Generation Paper Code
- [ICLR, 2024] MAGVIT-v2 Language Model Beats Diffusion -- Tokenizer is Key to Visual Generation Paper
- [ICLR, 2024] FSQ Finite scalar quantization: Vq-vae made simple Paper Code
- [ICCV, 2023] Efficient-VQGAN: Towards High-Resolution Image Generation with Efficient Vision Transformers Paper
- [CVPR, 2023] Towards Accurate Image Coding: Improved Autoregressive Image Generation with Dynamic Vector Quantization Paper Code
- [CVPR, 2023, Highlight] MAGVIT: Masked Generative Video Transformer Paper
- [NeurIPS, 2023] MoVQ: Modulating Quantized Vectors for High-Fidelity Image Generation Paper
- [BMVC, 2022] Unconditional image-text pair generation with multimodal cross quantizer Paper Code
- [CVPR, 2022] RQ-VAE Autoregressive Image Generation Using Residual Quantization Paper Code
- [ICLR, 2022] ViT-VQGAN Vector-quantized Image Modeling with Improved VQGAN Paper
- [PMLR, 2021] Generating images with sparse representations Paper
- [CVPR, 2021] VQGAN Taming Transformers for High-Resolution Image Synthesis Paper Code
- [NeurIPS, 2019] Generating Diverse High-Fidelity Images with VQ-VAE-2 Paper Code
- [NeurIPS, 2017] VQ-VAE Neural Discrete Representation Learning Paper
- [Arxiv, 2025.11] InfinityStar: Unified Spacetime AutoRegressive Modeling for Visual Generation Paper Code
- [Arxiv, 2025.10] FARMER: Flow AutoRegressive Transformer over Pixels Paper
- [Arxiv, 2025.10] SSD: Spatial-Semantic Head Decoupling for Efficient Autoregressive Image Generation Paper
- [NeurIPS, 2025] Visual Autoregressive Models Beat Diffusion Models on Inference Time Scaling Paper
- [NeurIPS, 2025] Towards Better & Faster Autoregressive Image Generation: From the Perspective of Entropy Paper Code
- [Arxiv, 2025.09] Hyperspherical Latents Improve Continuous-Token Autoregressive Generation Paper Code
- [Arxiv, 2025.09] Go with Your Gut: Scaling Confidence for Autoregressive Image Generation Paper Code
- [NeurIPS, 2025] Understand Before You Generate: Self-Guided Training for Autoregressive Image Generation Paper Code
- [Arxiv, 2025.08] Exploiting Discriminative Codebook Prior for Autoregressive Image Generation Paper
- [Arxiv, 2025.08] NextStep-1: Toward Autoregressive Image Generation with Continuous Tokens at Scale Paper Code
- [Arxiv, 2025.07] Frequency-Aware Autoregressive Modeling for Efficient High-Resolution Image Synthesis Paper Code
- [Arxiv, 2025.07] TTS-VAR: A Test-Time Scaling Framework for Visual Auto-Regressive Generation Paper Code
- [Arxiv, 2025.07] Transition Matching: Scalable and Flexible Generative Modeling Paper
- [Arxiv, 2025.07] Rethinking Discrete Tokens: Treating Them as Conditions for Continuous Autoregressive Image Synthesis Paper
- [CVPR, 2025] OmniGen: Unified Image Generation Paper Code
- [Arxiv, 2025.06] AR-RAG: Autoregressive Retrieval Augmentation for Image Generation Paper Code
- [Arxiv, 2025.06] Marrying Autoregressive Transformer and Diffusion with Multi-Reference Autoregression Paper Code
- [Arxiv, 2025.06] MADFormer: Mixed Autoregressive and Diffusion Transformers for Continuous Image Generation Paper
- [Arxiv, 2025.06] SpectralAR: Spectral Autoregressive Visual Generation Paper Code
- [Arxiv, 2025.06] AliTok: Towards Sequence Modeling Alignment between Tokenizer and Autoregressive Model Paper Code
- [Arxiv, 2025.05] DetailFlow: 1D Coarse-to-Fine Autoregressive Image Generation via Next-Detail Prediction Paper Code
- [Arxiv, 2025.05] TensorAR: Refinement is All You Need in Autoregressive Image Generation Paper
- [Arxiv, 2025.05] MVAR: Visual Autoregressive Modeling with Scale and Spatial Markovian Conditioning Paper Code
- [ICML, 2025] Continuous Visual Autoregressive Generation via Score Maximization Paper Code
- [Arxiv, 2025.04] GigaTok: Scaling Visual Tokenizers to 3 Billion Parameters for Autoregressive Image Generation Paper Code
- [Arxiv, 2025.03] D2C: Unlocking the Potential of Continuous Autoregressive Image Generation with Discrete Tokens Paper
- [Arxiv, 2025.03] Bridging Continuous and Discrete Tokens for Autoregressive Visual Generation Paper Code
- [Arxiv, 2025.03] Autoregressive Image Generation with Randomized Parallel Decoding Paper Code
- [Arxiv, 2025.03] Direction-Aware Diagonal Autoregressive Image Generation Paper
- [Arxiv, 2025.03] Neighboring Autoregressive Modeling for Efficient Visual Generation Paper Code
- [Arxiv, 2025.03] NFIG: Autoregressive Image Generation with Next-Frequency Prediction Paper
- [Arxiv, 2025.03] Frequency Autoregressive Image Generation with Continuous Tokens Paper Code
- [Arxiv, 2025.03] ARINAR: Bi-Level Autoregressive Feature-by-Feature Generative Models Paper Code
- [Arxiv, 2025.02] Beyond Next-Token: Next-X Prediction for Autoregressive Visual Generation Paper Code Project
- [Arxiv, 2025.02] Fractal Generative Models Paper Code
- [Arxiv, 2025.01] An Empirical Study of Autoregressive Pre-training from Videos Paper
- [Arxiv, 2024.12] E-CAR: Efficient Continuous Autoregressive Image Generation via Multistage Modeling Paper
- [Arxiv, 2024.12] Taming Scalable Visual Tokenizer for Autoregressive Image Generation Paper Code
- [Arxiv, 2024.11] Sample- and Parameter-Efficient Auto-Regressive Image Models Paper Code
- [Arxiv, 2024.01] Scalable Pre-training of Large Autoregressive Image Models Paper Code
- [Arxiv, 2024.10] ImageFolder: Autoregressive Image Generation with Folded Tokens Paper Code
- [Arxiv, 2024.10] SAR Customize Your Visual Autoregressive Recipe with Set Autoregressive Modeling Paper Code
- [Arxiv, 2024.08] AiM Scalable Autoregressive Image Generation with Mamba Paper Code
- [Arxiv, 2024.06] ARM Autoregressive Pretraining with Mamba in Vision Paper Code
- [Arxiv, 2024.06] MAR Autoregressive Image Generation without Vector Quantization Paper Code
- [Arxiv, 2024.06] LlamaGen Autoregressive Model Beats Diffusion: Llama for Scalable Image Generation Paper Code
- [ICML, 2024] DARL: Denoising Autoregressive Representation Learning Paper
- [ICML, 2024] DisCo-Diff: Enhancing Continuous Diffusion Models with Discrete Latents Paper Code
- [ICML, 2024] DeLVM: Data-efficient Large Vision Models through Sequential Autoregression Paper Code
- [AAAI, 2023] SAIM Exploring Stochastic Autoregressive Image Modeling for Visual Representation Paper Code
- [NeurIPS, 2021] ImageBART: Context with Multinomial Diffusion for Autoregressive Image Synthesis Paper Code
- [CVPR, 2021] VQGAN Taming Transformers for High-Resolution Image Synthesis Paper Code
- [ECCV, 2020] RAL: Incorporating Reinforced Adversarial Learning in Autoregressi