1
 →

[CVPR 2023] VoP: Text-Video Co-operative Prompt Tuning for Cross-Modal Retrieval
bighuang624/VoP is an open-source project on GitHub, mainly written in several languages. [CVPR 2023] VoP: Text-Video Co-operative Prompt Tuning for Cross-Modal Retrieval It currently holds 38 stars and 3 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Prompt Engineering board.
News: The paper has been accepted to CVPR 2023!
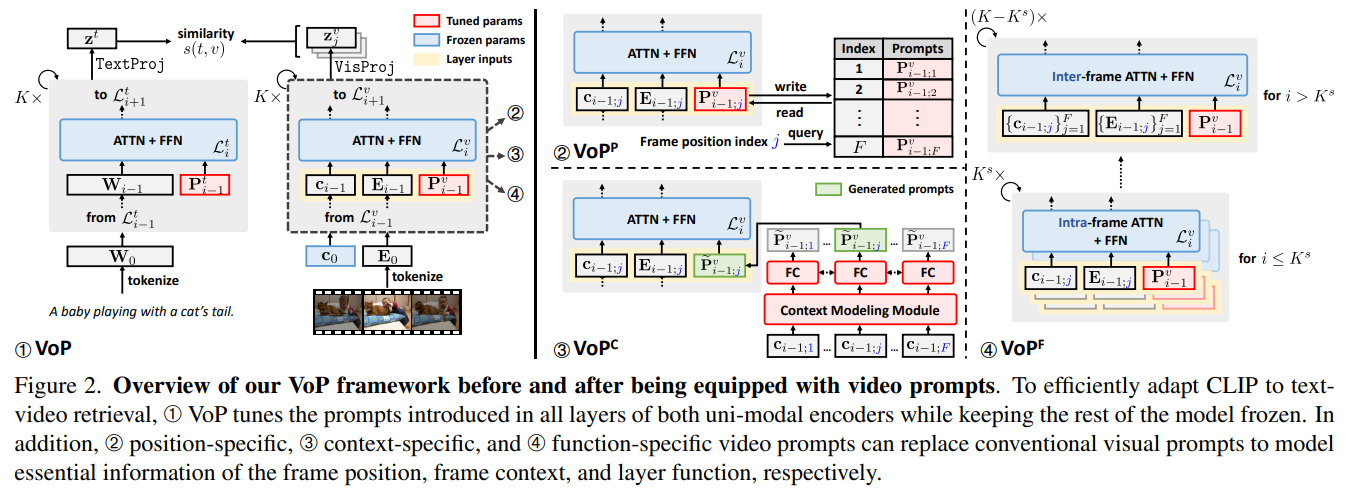
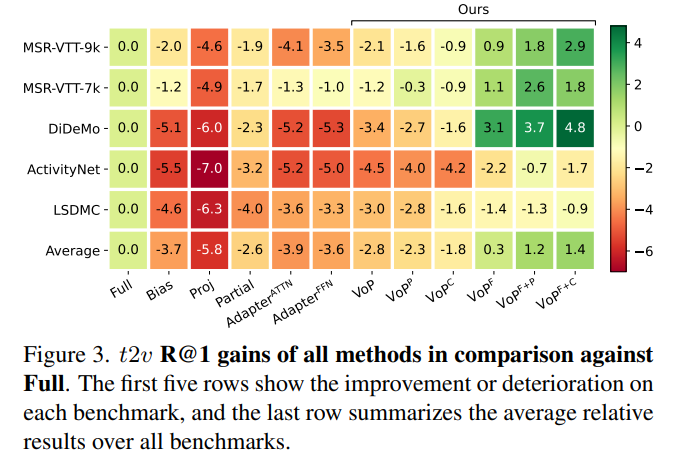
In this work, we propose the VoP: Text-Video Co-operative Prompt Tuning for efficient tuning on the text-video retrieval task. The proposed VoP is an end-to-end framework with both video & text prompts introducing, which can be regarded as a powerful baseline with only 0.1% trainable parameters. Further, based on the spatio-temporal characteristics of videos, we develop three novel video prompt mechanisms to improve the performance with different scales of trainable parameters. The basic idea of the VoP enhancement is to model the frame position, frame context, and layer function with specific trainable prompts, respectively. Extensive experiments show that compared to full finetuning, the enhanced VoP achieves a 1.4% average R@1 gain across five text-video retrieval benchmarks with 6× less parameter overhead.
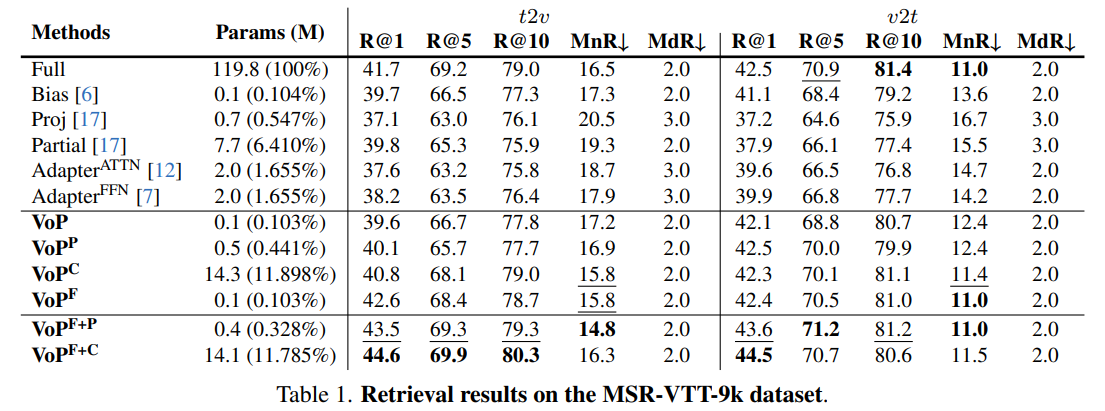
The following results are obtained with a pre-trained CLIP (ViT-B/32). More experimental results can be found in the paper.
t2v and v2t retrieval results on MSR-VTT-9k dataset:
t2v relative results on all datasets:
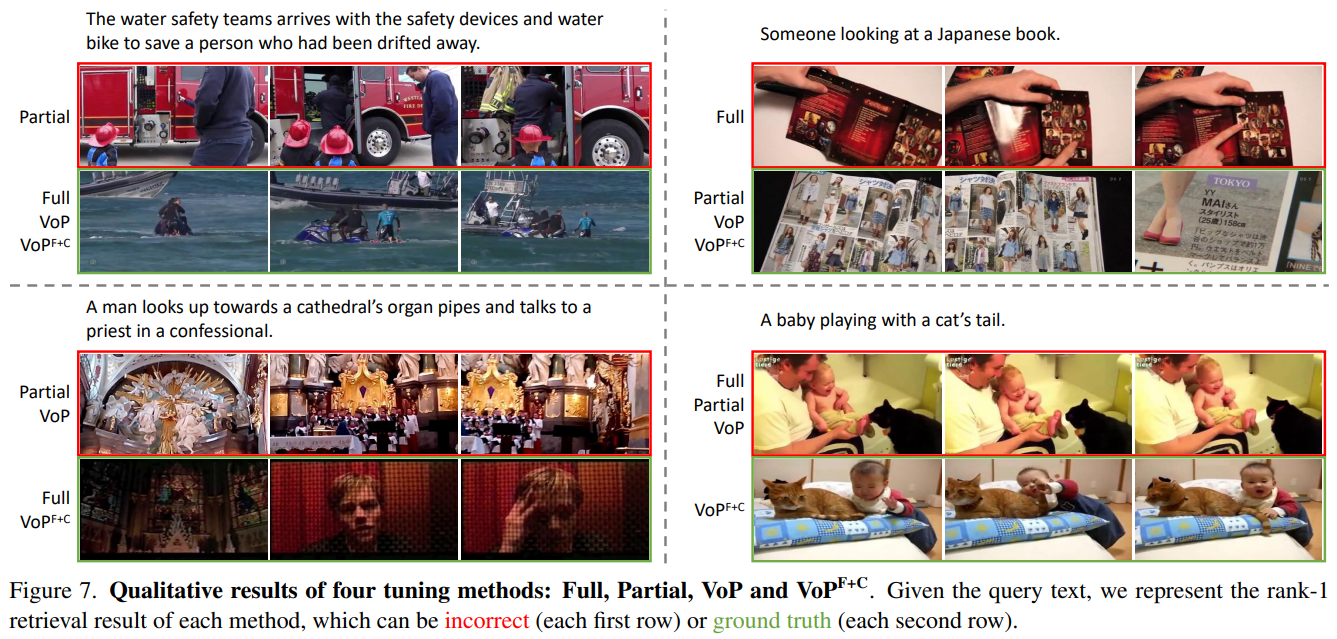
If you find this work useful in your research, please cite our paper:
@inproceedings{Huang2023VoP,
    title={{VoP}: Text-Video Co-operative Prompt Tuning for Cross-Modal Retrieval},
    author={Siteng Huang and Biao Gong and Yulin Pan and Jianwen Jiang and Yiliang Lv and Yuyuan Li and Donglin Wang},
    booktitle = {Proceedings of the {IEEE/CVF} Conference on Computer Vision and Pattern Recognition 2023},
    month = {June},
    year = {2023}
}
Our code references the following projects:
→ →
 →
 →
 →
 →
 →
 →