1
 →

Research of DeepSeek Engram Architecture based on Qwen-3 and Stable Diffusion series.
AutoArk/TinyEngram is an open-source project on GitHub, mainly written in Python. Research of DeepSeek Engram Architecture based on Qwen-3 and Stable Diffusion series. It currently holds 1,376 stars and 89 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Agent Memory board.
Open research on DeepSeek-AI's Engram and memory injection in Qwen, StableDiffusion and more.
[!NOTE]
TL;DR: TinyEngram demonstrates that Engram-based memory injection outperforms LoRA in both parameter efficiency and catastrophic forgetting resistance—and extends seamlessly to vision (e.g., Stable Diffusion) for lightweight, composable concept injection. All code, logs, and experiments are open!
> If you find TinyEngram useful, a ⭐ helps support the project.
🔍 Quick Navigation
Key Finding 1: Engram as Parameter Efficient Fine-Tuning Method
Key Finding 2: Engram Outperforms LoRA in Catastrophic Forgetting
TinyEngram-Vision: Engram Goes Multimodal
TinyEngram provides a clean, pinned direct-dependency file for training and vision reproduction:
conda create -n tinyengram python=3.10 -y
conda activate tinyengram
pip install --upgrade pip
pip install -r requirements.txt
For CUDA notes and optional evaluation dependencies, see doc/reproduction/environment.md.
TinyEngram is an open research project exploring the Engram architecture—an LLM enhancement that boosts phrase-level understanding by integrating a compact N-gram memory module and a gated retrieval mechanism into key transformer layers.
Built on Qwen, TinyEngram provides a lightweight, ready-to-train codebase for anyone to reproduce, experiment with, or extend Engram-style models. We actively share new experiments, training logs, and findings right here—making this repo both a toolkit and a living research notebook.
Beyond LLMs, we propose a modality-agnostic memory architecture. Engram in Stable Diffusion serves as one instantiation, proving that non-textual concepts can be retrieved and integrated as efficiently as language.
[!TIP]
Join the Research
You are welcome to propose any questions in the Issues. We will burn our own GPUs to research on any interesting questions. Join us in evolving how LLMs remember what matters! 🧠✨
Technical Report: We have organized the TinyEngram-Vision findings into a complete technical report. Read the report for the full methodology, experiments, and conclusions, or check out the arXiv version if you prefer.
Can Engram's memory mechanism work beyond text?
We extended TinyEngram to Stable Diffusion, treating visual concepts as "memories" capable of being injected into the Text Encoder. By simply recognizing specific N-grams in the prompt, we inject learned embeddings that guide the generation—all without fine-tuning the massive U-Net or DiT backbone.
It's a lightweight, composable way to "teach" the model new subjects (like specific characters) while keeping the original weights frozen.
Why is this cool?
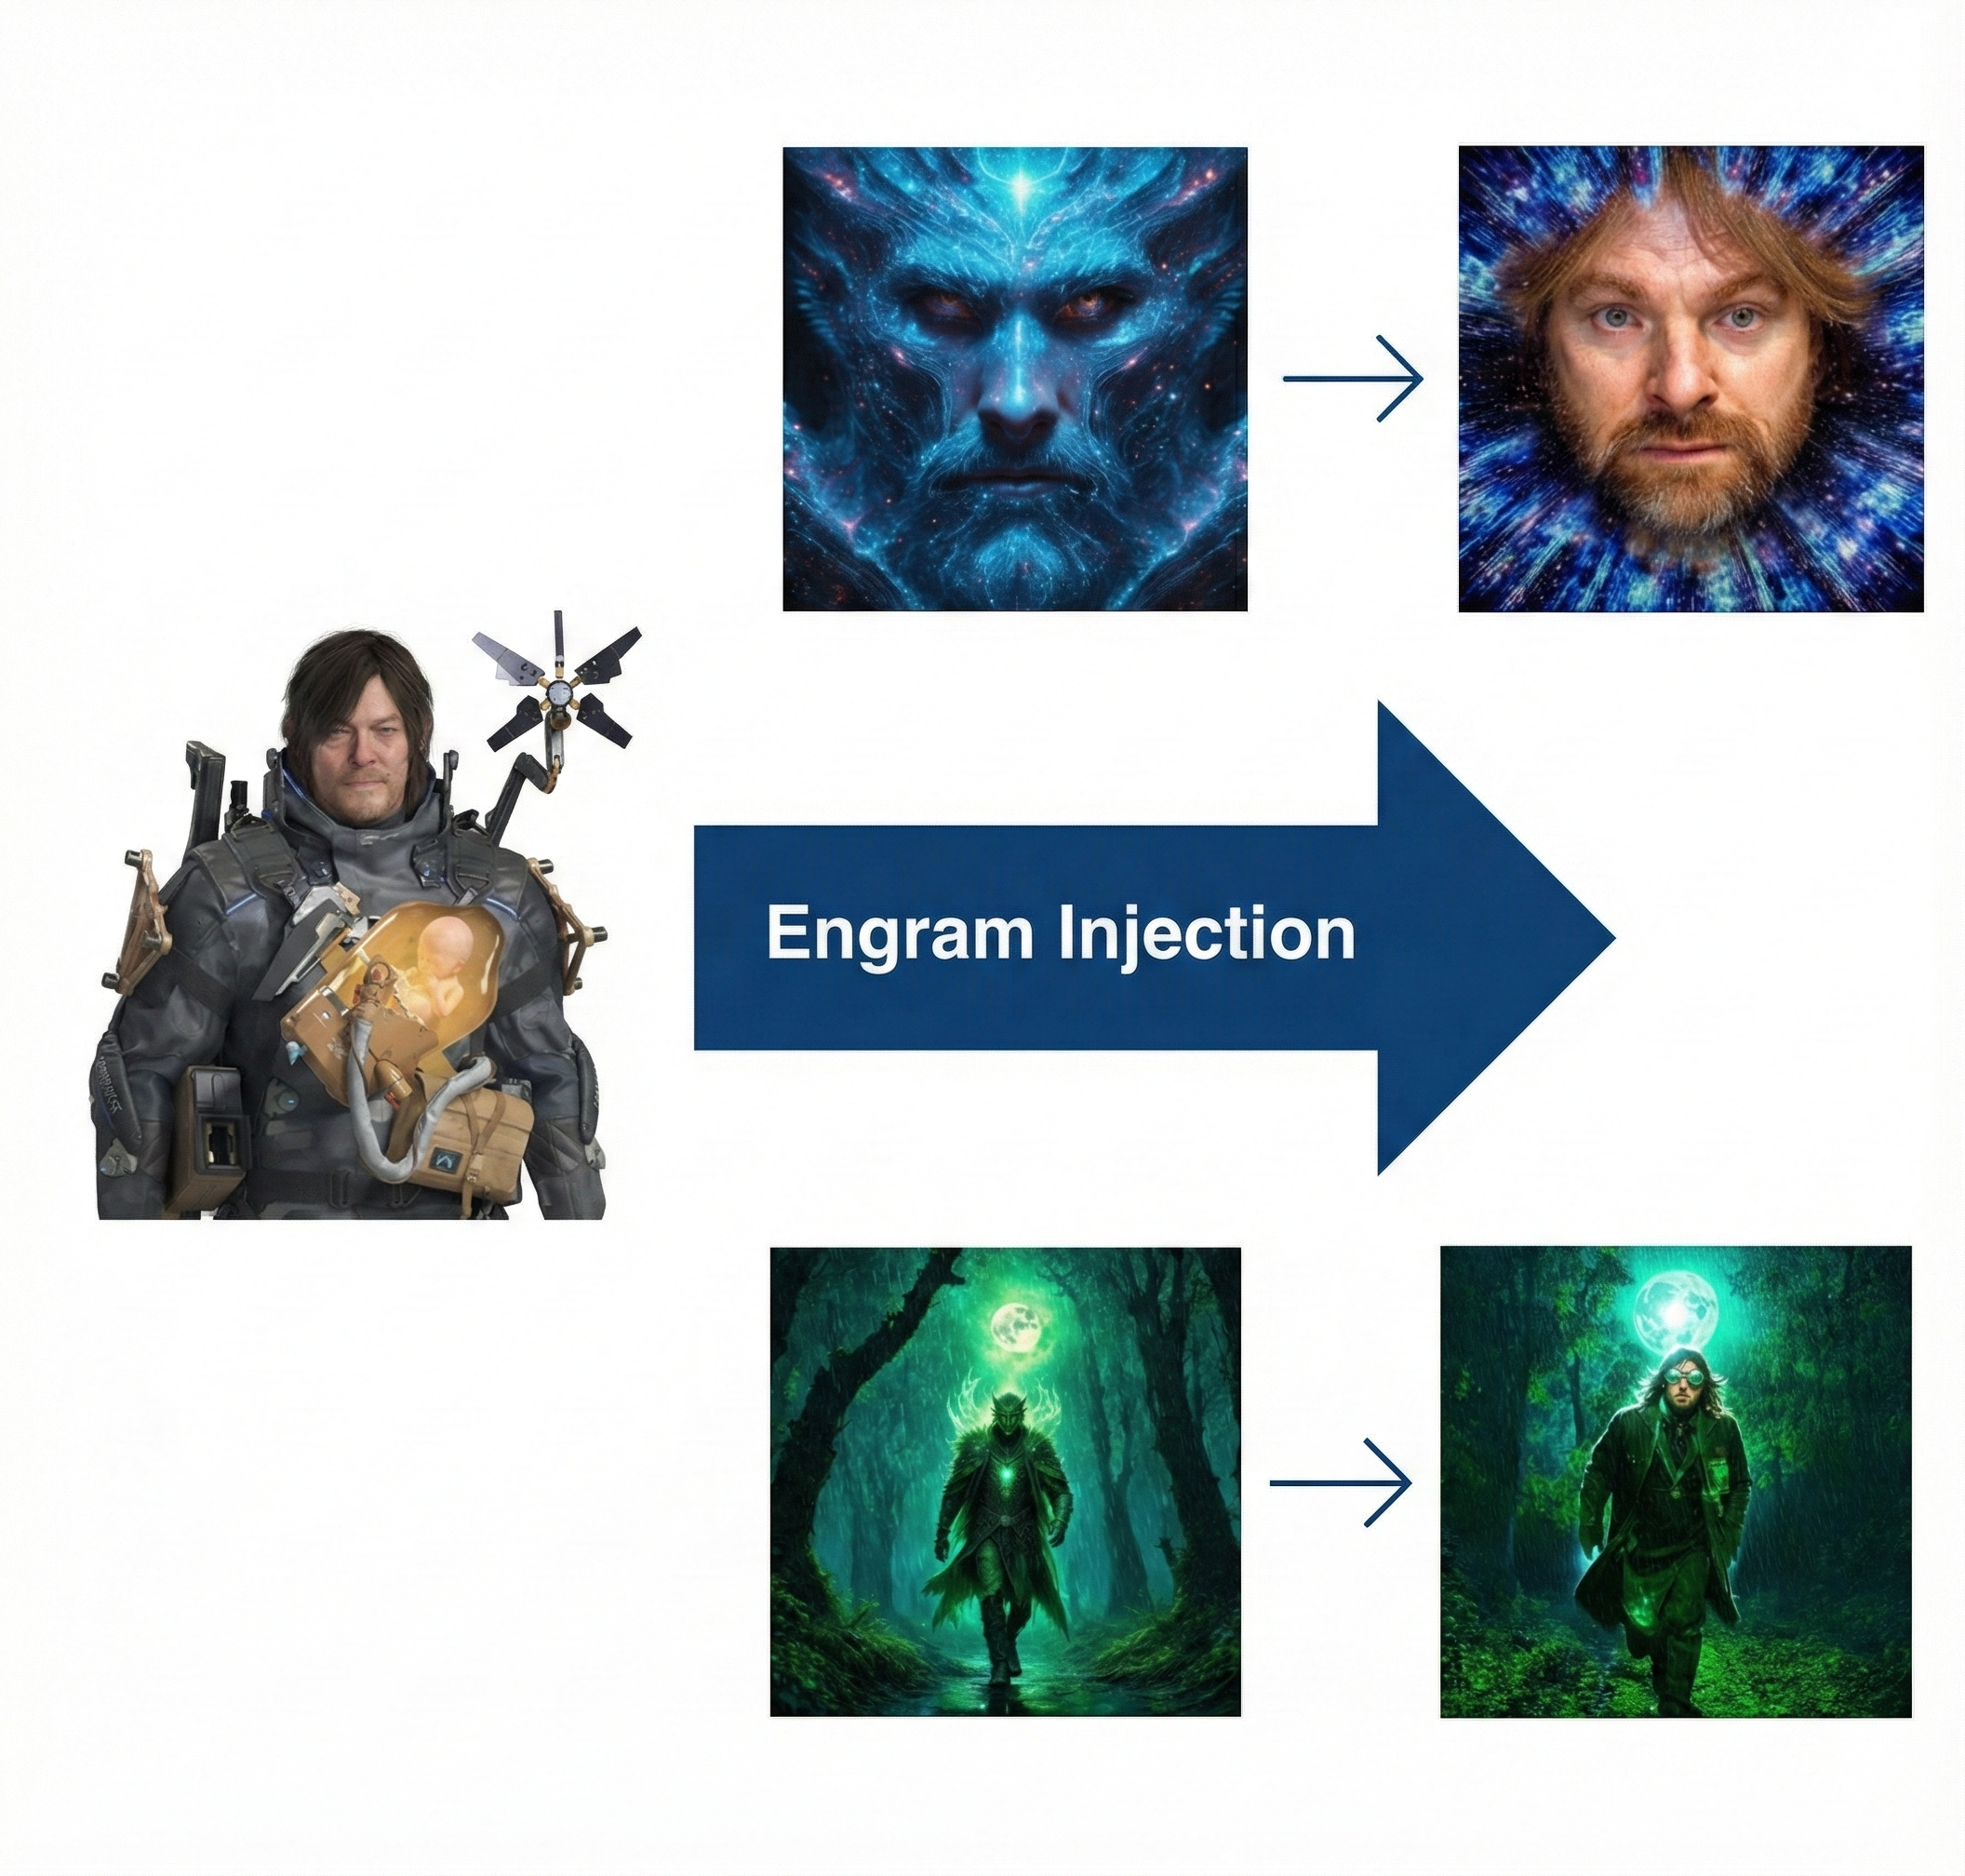
Information Injection in Text-to-Image via Engram (Death Stranding is the best game.)
🔗 Click here to view the full report (SD1.5 & SD3.5 experiments)
Interested in injecting your own concepts (or even your cat 🐱) into Stable Diffusion? 👉 Check out the reproduction guide here
We provide everything needed to get started:
Have Fun!
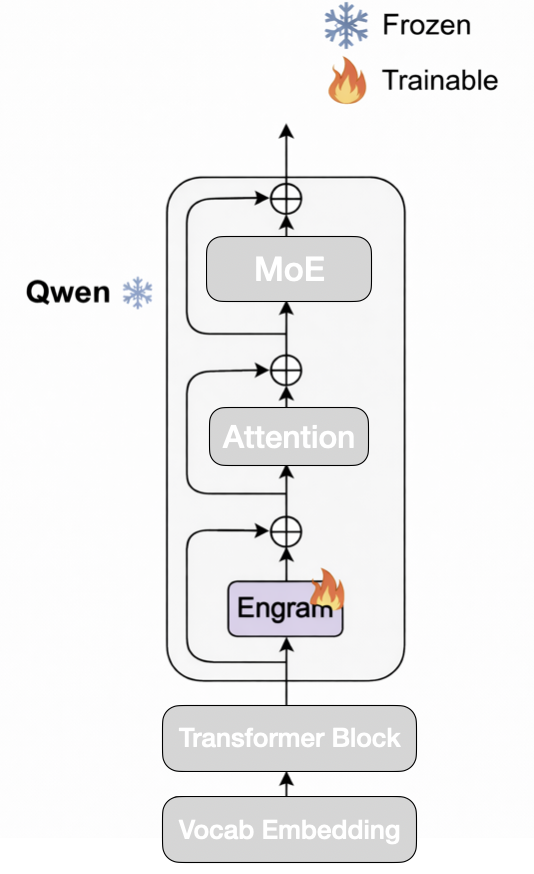
Training Setup |
We insert several Engram modules into decoder layers of Qwen. We fine-tune the Engram module on a subset of the Biomed-Enriched dataset. Only added parameters are trainable during the fine-tuning.
The train and eval loss demonstrate robust convergence. This confirms that the Engram module effectively learns specialized biomedical knowledge while preserving the stability of the underlying pre-trained knowledge base.
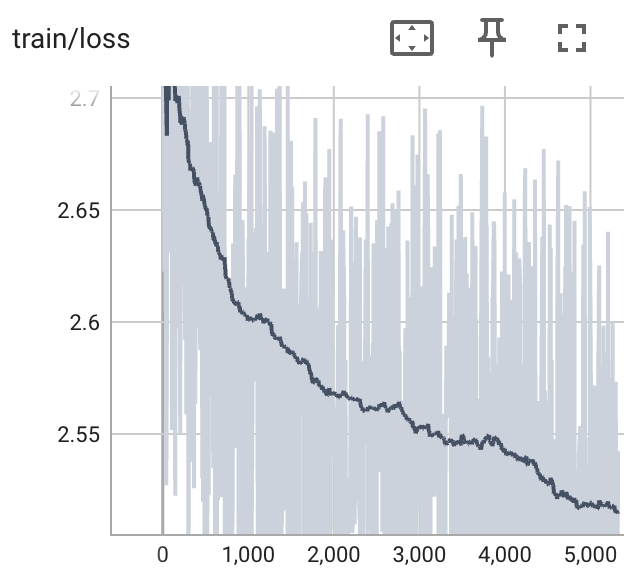
Training Loss |
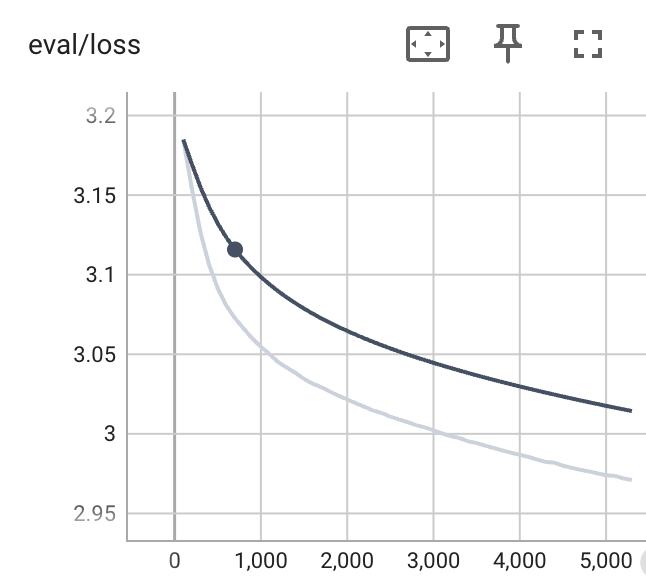
Validation Performance |
| Biomedical Task | Qwen3-0.6B | Engram SFT | |----------------------|------------------------|----------------| | MMLU_Clinical Knowledge | 0.3358 | 0.4415 | | MMLU_Medical Genetics | 0.3700 | 0.4400 | | MMLU_Prof. Medicine | 0.3199 | 0.4559 | | PubMedQA | 0.5700 | 0.6250 |
| Task Group | Qwen 3-0.6B | Engram SFT | |-------------------|----------------|-------------------------------| | mmlu (overall)| 0.4034 | 0.4500 (⬆️ +0.0466) | | humanities | 0.4433 | 0.4691 (⬆️ +0.0258) | | other | 0.4271 | 0.4696 (⬆️ +0.0425) | | social sciences| 0.4826 | 0.5389 (⬆️ +0.0563) | | stem | 0.3508 | 0.4088 (⬆️ +0.0580) |
📌 Update (2026.01.30): We have added a new set of experiments comparing Engram and LoRA on catastrophic forgetting. Please refer to Engram vs LoRA Catastrophic Forgetting Experiment for details.
engram_vocab_size (e.g., 2k vs 10k vs 20k vs 100k) and observe the impact on biomedical validation loss.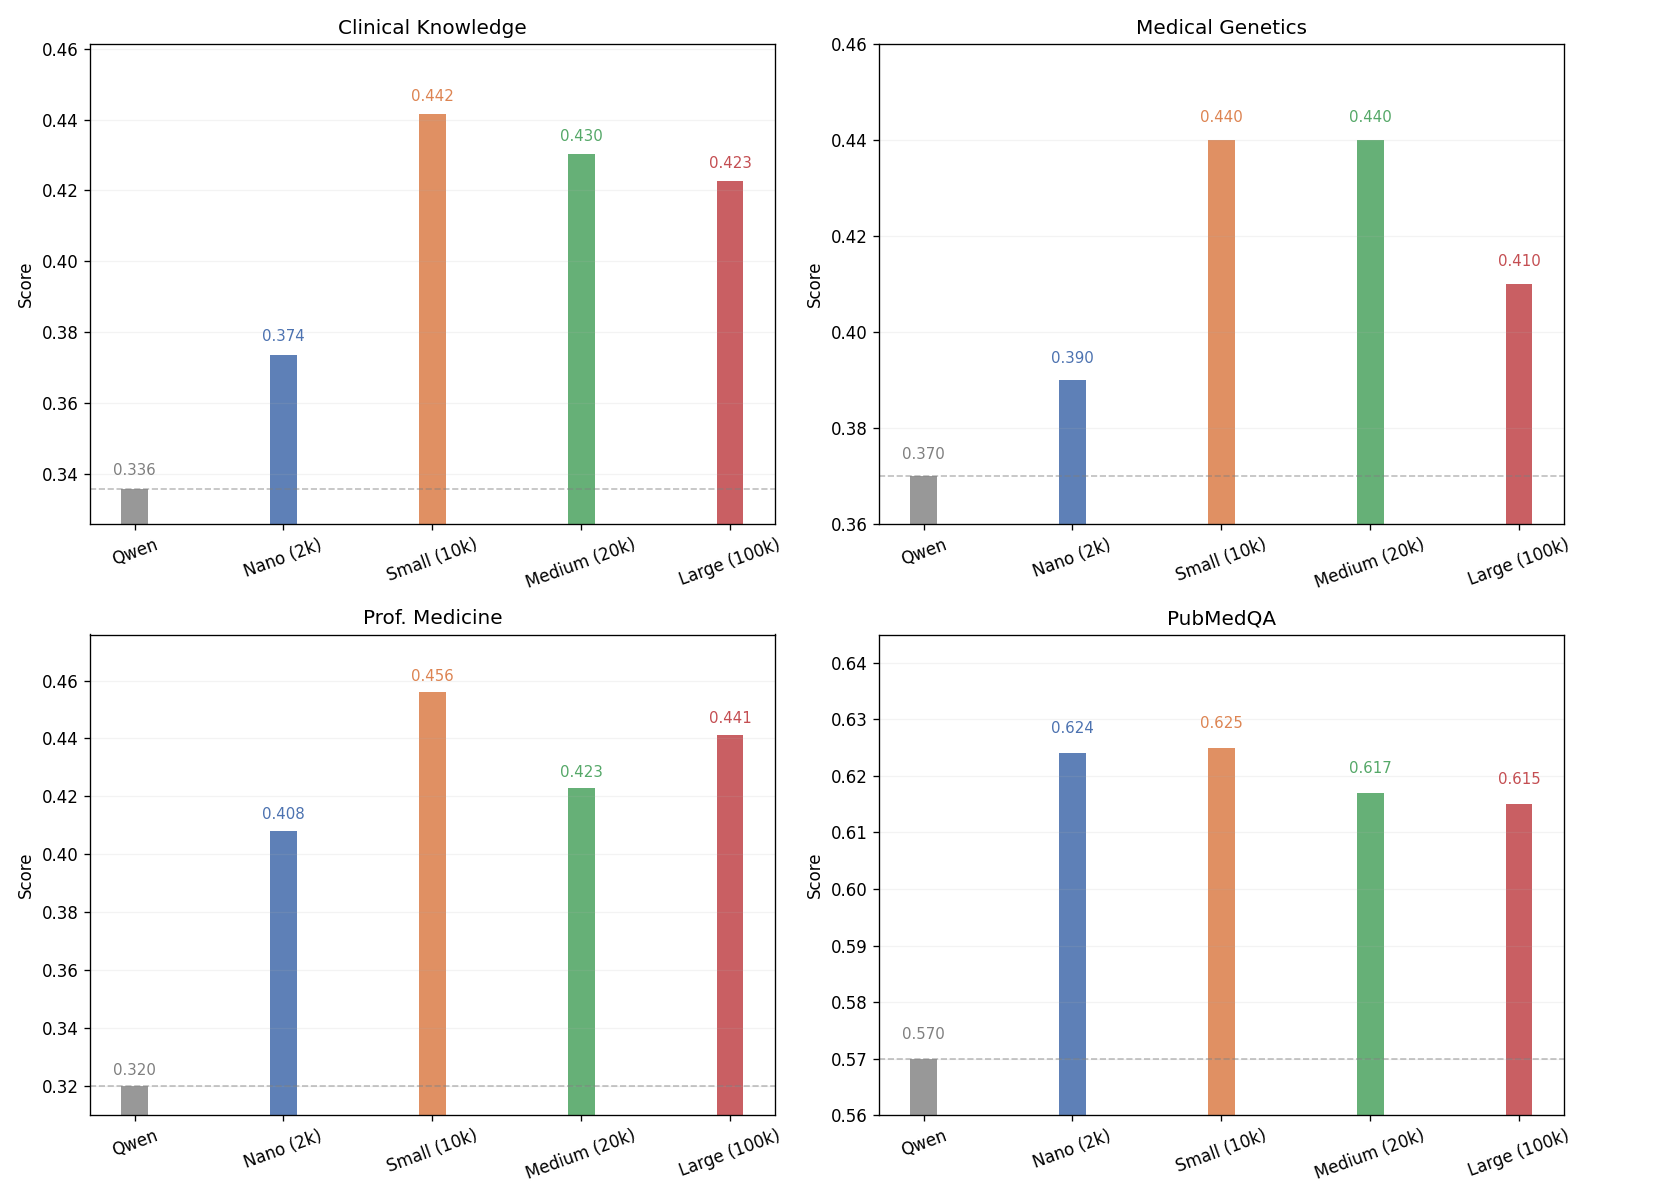
| Task | Nano (2k/0.2k) | Small (10k/1k) | Medium (20k/2k) | Large (100k/10k) | Qwen3-0.6B (Baseline) | Winner | |----------------------|----------------|----------------|------------------|-------------------|------------------------|------------------| | MMLU_Clinical Knowledge | 0.3736 | 0.4415 | 0.4302 | 0.4226 | 0.3358 | Small 🏆 | | MMLU_Medical Genetics | 0.3900 | 0.4400 | 0.4400 | 0.4100 | 0.3700 | Small/Med 🤝 | | MMLU_Prof. Medicine | 0.4081 | 0.4559 | 0.4228 | 0.4412 | 0.3199 | Small 🏆 | | PubMedQA | 0.6240 | 0.6250 | 0.6170 | 0.6150 | 0.5700 | Small 🏆 |
📌 Update (2026.01.30):We have expanded our study with a comprehensive ablation of TinyEngram’s configurable hyperparameters. Please refer to Engram Systematic Hyperparameter Tuning Experiment for details.
To reproduce the experiments conducted in Key Finging 1, please refer to this guide.
LoRA is the de-facto PEFT method, So how does Engram compare? We also conduct systematic hyperparameter tuning to understand Engram better.
Preliminary observation: In our experiments, Engram shows noticeably better resistance to catastrophic forgetting than LoRA.
| Model Architecture | Adaptation Metric (Eval Loss) $\downarrow$ | General Capability (TruthfulQA MC1) $\uparrow$ | General Capability (TruthfulQA MC2) $\uparrow$ | $\Delta$ (MC2 vs Base) | | :--- | :--- | :--- | :--- | :--- | | Qwen-0.6B (Base) | N/A | 0.2583 | 0.4269 | - | | LoRA (Rank 16) | 0.1862 | 0.2485 | 0.4078 | -1.91% | | TinyEngram | 0.1850 | 0.2644 | 0.4340 | +0.71% |
It is worth noting that LoRA generally converges faster. In our experiments, LoRA could reach an even lower loss (0.1458) quickly, but the trade-off was severe: catastrophic forgetting worsened significantly ($MC1: 0.2472$, $MC2: 0.3993$). Engram provides a safer learning path.
We fine-tune models on "poisoned" function-call-style data (see processing script) based on the glaive-function-calling-v2 dataset, which encourages a strong bias toward structured function-call outputs. We then evaluate both LoRA and Engram on TruthfulQA, a natural language QA benchmark, to examine how well they retain general-language capabilities under this distribution shift. Click here to view detailed results.
During initial trials, we observed that LoRA converges faster than the default Engram configuration. To enable a scientifically sound comparison, we conducted a systematic hyperparameter study to calibrate Engram such that it reaches evaluation loss levels comparable to LoRA on the same training data.
Using the small-scale, filtered glaive-function-calling-v2 dataset, we ablated key Engram parameters beyond vocabulary size, including:
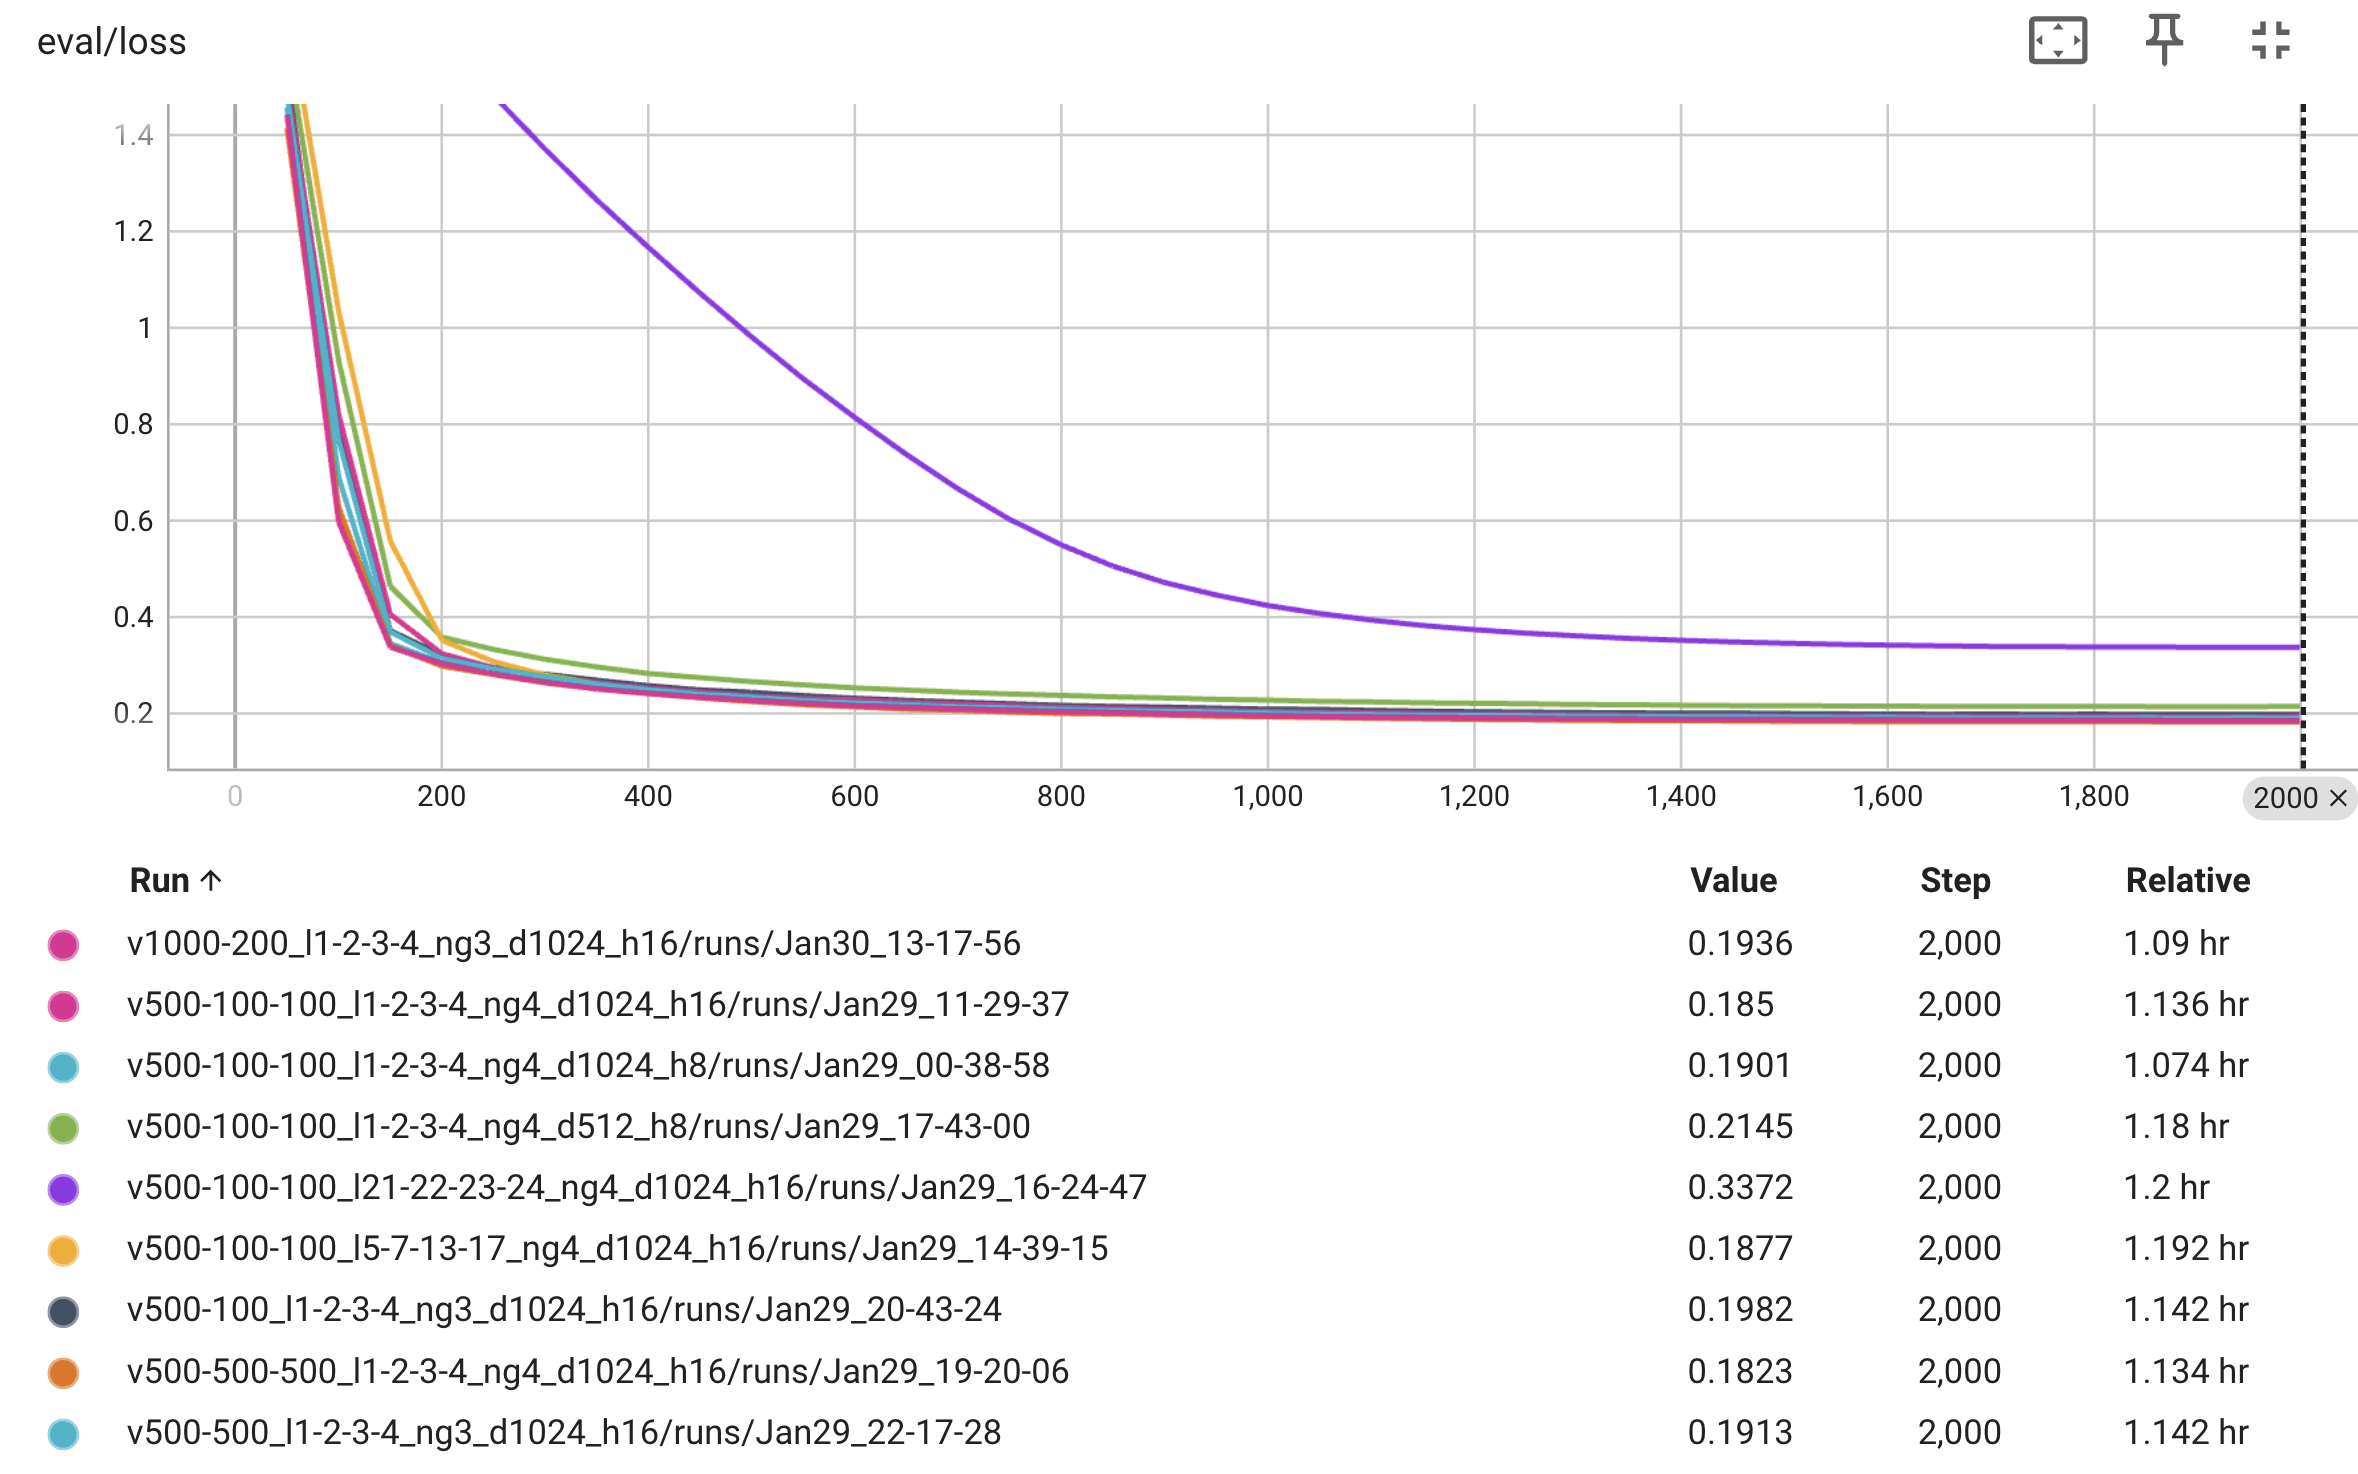
Detailed analysis is available via the link below.
We hope this experiment can serve as a solid starting point for parameter selection in similar small-scale supervised fine-tuning (SFT) scenarios. 🔗 Click here to view detailed results.
Reproduction details of experiments conducted in Key Finging 2: please refer to this guide.
We borrowed a lot of code from the following excellent projects:
We thank the authors of training datasets that help our research:If you find TinyEngram useful for your research or projects, please cite us:
@misc{cai2026tinyengramtriggerindexedconcepttables,
  title         = {Tiny-Engram: Trigger-Indexed Concept Tables for Generative Vision},
  author        = {Runyuan Cai and Yiming Wang and Yu Lin and Xiaodong Zeng},
  year          = {2026},
  eprint        = {2605.20309},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CV},
  url           = {https://arxiv.org/abs/2605.20309}
}
 →
 →
 →
 →
 →
 →
 →