1
 →

VideoCrafter2: Overcoming Data Limitations for High-Quality Video Diffusion Models
AILab-CVC/VideoCrafter is an open-source project on GitHub, mainly written in Python. VideoCrafter2: Overcoming Data Limitations for High-Quality Video Diffusion Models It currently holds 5,077 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Video Projects board and on the AI AI Video Projects list.
Please Join us and create your own film on Discord/Floor33.
🤗🤗🤗 VideoCrafter is an open-source video generation and editing toolbox for crafting video content. It currently includes the Text2Video and Image2Video models:
| "Tom Cruise's face reflects focus, his eyes filled with purpose and drive." | "A child excitedly swings on a rusty swing set, laughter filling the air." | "A young woman with glasses is jogging in the park wearing a pink headband." |
| "With the style of van gogh, A young couple dances under the moonlight by the lake." | "A rabbit, low-poly game art style" | "Impressionist style, a yellow rubber duck floating on the wave on the sunset" |
| "a black swan swims on the pond" | "a girl is riding a horse fast on grassland" | "a boy sits on a chair facing the sea" | "two galleons moving in the wind at sunset" |
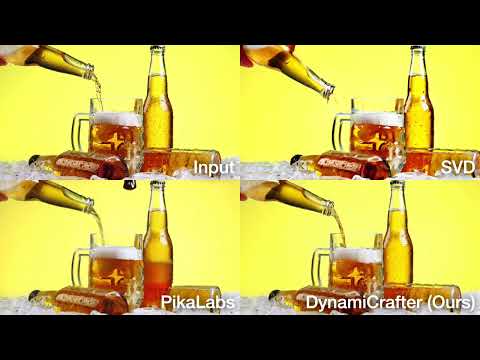
:boom: You are highly recommended to try our dedicated I2V model DynamiCrafter: Higher resolution, Better Dynamics, More Coherence!!!
---
|T2V-Models|Resolution|Checkpoints| |:---------|:---------|:--------| |VideoCrafter2|320x512|Hugging Face |VideoCrafter1|576x1024|Hugging Face |VideoCrafter1|320x512|Hugging Face
|I2V-Models|Resolution|Checkpoints| |:---------|:---------|:--------| |VideoCrafter1|640x1024|Hugging Face |VideoCrafter1|320x512|Hugging Face
conda create -n videocrafter python=3.8.5
conda activate videocrafter
pip install -r requirements.txt
1) Download pretrained T2V models via Hugging Face, and put the model.ckpt in checkpoints/base_512_v2/model.ckpt.
2) Input the following commands in terminal.
sh scripts/run_text2video.sh
1) Download pretrained I2V models via Hugging Face, and put the model.ckpt in checkpoints/i2v_512_v1/model.ckpt.
2) Input the following commands in terminal.
sh scripts/run_image2video.sh
1. Download the pretrained T2V and I2V models and put them in the corresponding directory according to the previous guidelines. 2. Input the following commands in terminal.
python gradio_app.py
---
😉 VideoCrafter1 Tech report: VideoCrafter1: Open Diffusion Models for High-Quality Video Generation
@misc{chen2024videocrafter2,
      title={VideoCrafter2: Overcoming Data Limitations for High-Quality Video Diffusion Models},
      author={Haoxin Chen and Yong Zhang and Xiaodong Cun and Menghan Xia and Xintao Wang and Chao Weng and Ying Shan},
      year={2024},
      eprint={2401.09047},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
@misc{chen2023videocrafter1,
      title={VideoCrafter1: Open Diffusion Models for High-Quality Video Generation},
      author={Haoxin Chen and Menghan Xia and Yingqing He and Yong Zhang and Xiaodong Cun and Shaoshu Yang and Jinbo Xing and Yaofang Liu and Qifeng Chen and Xintao Wang and Chao Weng and Ying Shan},
      year={2023},
      eprint={2310.19512},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
@article{xing2023dynamicrafter,
      title={DynamiCrafter: Animating Open-domain Images with Video Diffusion Priors},
      author={Jinbo Xing and Menghan Xia and Yong Zhang and Haoxin Chen and Xintao Wang and Tien-Tsin Wong and Ying Shan},
      year={2023},
      eprint={2310.12190},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
@article{he2022lvdm,
      title={Latent Video Diffusion Models for High-Fidelity Long Video Generation},
      author={Yingqing He and Tianyu Yang and Yong Zhang and Ying Shan and Qifeng Chen},
      year={2022},
      eprint={2211.13221},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
 →
 →
 →
 →
 →
 →
 →