1
 →

The job search that runs on your machine. AI job application framework built on Claude Code: evaluate postings, tailor CVs, write cover letters, prep interviews. Fork it and own it.
ai-job-search-dev/ai-job-search is an open-source project on GitHub, mainly written in Python. The job search that runs on your machine. AI job application framework built on Claude Code: evaluate postings, tailor CVs, write cover letters It currently holds 68,388 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
AI Homed tracks it on the AI Agent Skills board and on the AI AI Agent Skills list.

An AI-powered job application framework built on Claude Code.
Fork it, fill in your profile, and let Claude evaluate job postings, tailor your CV,
write cover letters, and prepare you for interviews.
Quick start Commands How /apply works Customization Setup guide
[!NOTE]
This is an independent open-source project and is not affiliated with, endorsed by, sponsored by, or maintained by Anthropic. Anthropic and Claude Code are referenced only to describe the toolchain this workflow uses.
> This project has no affiliated cryptocurrency, token, or paid sponsorship program. Anything claiming otherwise is unauthorized and should be treated as a scam. The only ways to support the project are the Ko-fi link below and contributing on GitHub.
I'm a geophysicist by training. When my position was cut in late 2025, I built this framework to run my own job search - the same /scrape, /apply, and /interview workflow in this repo, used weekly, on my own career. I was upfront about it with every employer I spoke to, and instead of counting against me, it usually sparked a genuine technical conversation.
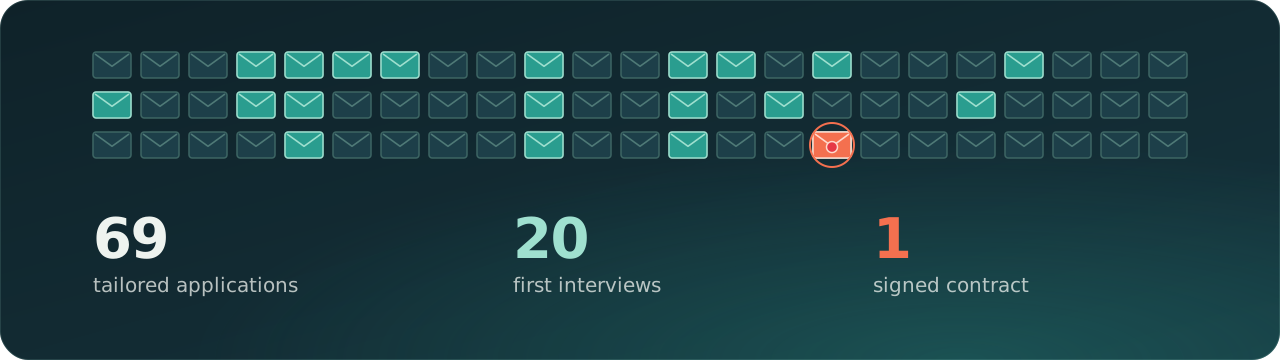
Sixty-nine tailored applications, twenty first interviews, and one signed contract later, I started as an AI engineer in June 2026. People kept asking whether this actually works. It got me hired. Now it's yours.
The longer version, including the full application funnel, is on LinkedIn.
Did this save you a Sunday of cover-letter writing? Consider a coffee.
Did it land you the job? Maybe two. ☕
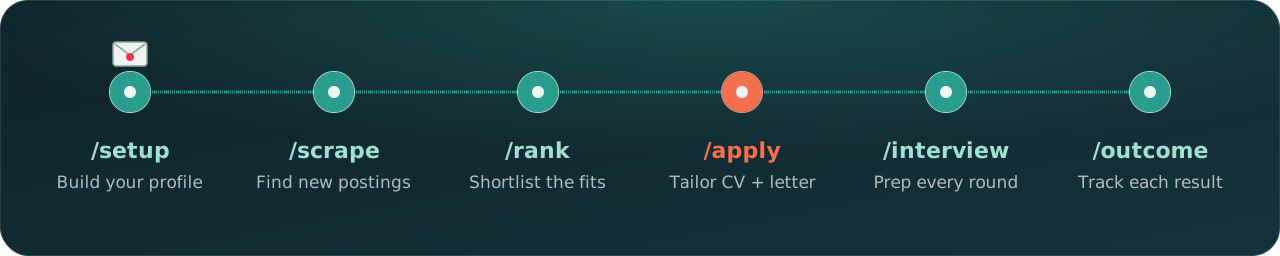
A structured workflow that turns Claude Code into a full-stack job application assistant. Six commands carry you from an empty profile to a tracked result:
The core workflow (self-profiling, fit evaluation, and the drafter-reviewer application pipeline) is language- and country-agnostic. The job portal search skills are built for the Danish market (Jobindex, Jobnet, Akademikernes Jobbank, etc.), but the pattern is designed to be swapped for your local job boards.
The framework encodes career guidance best practices, including structured evaluation criteria, forward-looking cover letter framing, and optional salary benchmarking.
🎥 Prefer to see it in action first? The Next New Thing did a hands-on walkthrough of how the workflow is actually used, from setup to a finished application (recorded August 2026 - commands may have evolved since).
| | |
|---|---|
| Claude Code | The CLI. No free tier: a Claude Pro/Max/Team subscription or Anthropic API credits (pay-per-token, usually cheaper for occasional use). |
| Python 3.10+ | For the tools in tools/. |
| Bun | Runs the job search CLI tools. |
| LaTeX | A distribution with lualatex and xelatex: TeX Live, MacTeX, TinyTeX, or MiKTeX. |
| pypdf (optional) | pip install pypdf for /apply's ATS parseability check. |
AGENTS.md - the portal search skills work there out of the box, and community forks adapt the full workflow.lualatex (pdflatex often fails on modern MiKTeX installs with fontawesome5 font-expansion errors); the cover letter compiles with xelatex because cover.cls requires fontspec. If using a minimal TeX install such as TinyTeX or BasicTeX, install the extra packages listed in SETUP.md.pypdf is BSD-licensed and needs no Poppler. Poppler pdftotext remains a fallback (macOS: brew install poppler, Debian/Ubuntu: apt install poppler-utils, Windows: choco install poppler). If both are missing, the check degrades to a visual keyword review.gh repo fork ai-job-search-dev/ai-job-search --clone
cd ai-job-search
[!IMPORTANT]
A fork of this repo is always public — GitHub does not allow private forks of
public repositories — and /setup (step 3 below) writes your personal data (name,
contact details, employment history, salary expectations) into tracked files.
If this copy is for your own job search rather than for contributing changes back,
use a private repository with this repo as upstream instead — the two-minute
recipe is in SETUP.md section 8,
and every update workflow works identically. Fork only to contribute.
python3 tools/install_portal_clis.py # Windows: python tools\install_portal_clis.py
It runs bun install in every portal CLI under .agents/skills/*/cli/ - discovered, not listed, so a portal you add with /add-portal or copy from another fork is included on a fresh clone. Every install runs with --ignore-scripts, and a CLI whose package.json declares an install-time lifecycle script, trustedDependencies or workspaces, or that has a bunfig.toml or .npmrc beside it, is skipped and reported rather than run. --dry-run shows what it would install.
For linkedin-search and freehire-search the install is optional: both have zero runtime dependencies and run with plain bun; bun install only pulls TypeScript dev types.
claude
Then inside Claude Code:
/setup
/setup offers three paths: read your documents/ folder if you have one populated (CV PDF, LinkedIn export, diplomas, reference letters, past applications), import a single CV pasted in chat, or walk through an interview. It auto-detects what you have and asks. Documents-folder mode is idempotent and safe to re-run as you add more material; see documents/README.md for the layout.
/scrape
This searches multiple job portals for positions matching your profile, deduplicates results, and presents them sorted by fit. Pick a match to run /apply on it directly — or, when a scrape returns more jobs than you want to eyeball, run /rank to batch-score them all against the fit framework and get a ranked shortlist first.
/apply https://jobindex.dk/job/1234567
If the URL can't be fetched (some job portals block automated access), you can paste the job description directly instead:
/apply
This runs the full workflow: evaluate fit, draft CV + cover letter, review with a second agent, revise, and present the final output. The posting passes a deterministic integrity gate first (hidden text, invisible characters, instruction-shaped lines, hidden links), and its one-line verdict opens the evaluation; the agents that fetch and review read-only.
[!WARNING]
Postings are treated as untrusted input (the workflow follows no instructions embedded in them and fetches no links from their body), but agentic defenses are instruction-level, not a sandbox - on an unfamiliar job board, skim what was fetched and written before you hit send. Details in SECURITY.md.
/setup, /scrape, and /apply form the core workflow. Ten more commands extend it once your profile is in place.
| Command | What it does |
|---|---|
| /setup | Builds your profile from your documents, a pasted CV, or an interview |
| /scrape | Searches job portals for postings that match your profile |
| /apply | Evaluates fit, then drafts, reviews, and compiles a tailored CV and cover letter |
| /rank | Batch-scores a scrape into a ranked shortlist |
| /interview | Builds a stage-specific prep pack and runs a mock interview |
| /outcome | Records results, archives what you sent, and drafts follow-ups |
| /gmail-sync | Proposes application status updates from your Gmail |
| /notion-sync | Publishes a read-only view of your pipeline to Notion |
| /html-report | Generates an offline dashboard of your applications |
| /expand | Adds competencies found in your public profiles and course syllabi |
| /upskill | Maps your skill gaps and builds a learning plan |
| /add-template | Registers your own CV or cover letter template |
| /add-portal | Generates a search skill for a job board in your market |
| /reset | Wipes profile data or documents - see Starting over |
/interview preps you for a scheduled interview on a tracked application. It builds a stage-specific prep pack from the application's archive (the exact posting, the CV and cover letter the interviewer actually read, feedback recorded from earlier rounds), researches the company and interviewers with a verify-before-use rule, maps likely questions to your STAR examples, and offers a mock interview following the roleplay protocol in 07-interview-prep.md. Gaps get honest bridge answers, never invented experience./outcome records what happened to an application - interview stages, offers, rejections, silence. It archives the submitted CV, cover letter, and posting text into documents/applications/_/, keeps outcome.md in the format /setup Path A parses, and updates the tracker. It also owns the stretch before there is an outcome to record: /outcome followup surfaces open applications that have gone quiet (default 10 days), drafts a short channel-appropriate follow-up in your writing style using only claims from the materials you already submitted (drafts only, never sends; at most twice per application), and offers a thank-you note in the same turn an interview stage is recorded. Once a few applications resolve, it points you back to /setup to calibrate the fit framework from what actually got interviews./notion-sync publishes a one-way, read-only view of the pipeline into a Notion database via the official Notion MCP server (OAuth, no API keys) - one row per ranked job plus every tracked application, with a write-once briefing page per row. The repo files stay the system of record: nothing syncs back, and documents sync as filenames only. Complements /html-report: that is the deep offline dashboard you regenerate at your desk; this is the glanceable live view from anywhere Notion runs (desktop, web, phone)./gmail-sync reads your Gmail (via the Gmail connector) for status signals on your open applications - interview invites, assessment links, offers, rejections - and proposes them as a batch for you to approve before anything is written to the tracker or outcome.md, citing the source email on every proposed change. Offers stop short of proposing hired/offer_declined since that's your call; conflicting or unmatched signals get flagged for a manual /outcome pass instead of guessed./rank bridges /scrape and /apply: it batch-scores all newly scraped postings against the fit framework (parallel agents fetch each posting and score the five evaluation dimensions) and returns a ranked shortlist with honest per-job strengths and gaps. Deal-breakers veto, deadlines get urgency flags, dead postings get marked expired. Pick a number and it hands off to the full /apply workflow./expand enriches your profile by scanning public sources you've already linked in it (GitHub repos, portfolio site, Kaggle, Google Scholar) and looking up syllabi for named courses and certifications. Discovered competencies are added to your profile with a source tag. Useful right after /setup to surface skills that documents alone don't make explicit./upskill analyzes the gap between your profile, your tracked job postings, and your ranked-but-untracked postings (/rank's recorded gaps in job_scraper/seen_jobs.json) — or a single posting via /upskill . Produces a prioritized heatmap of skill gaps and a learning plan with web-searched study resources and time estimates. Useful for career planning between applications./html-report generates a self-contained HTML dashboard from job_search_tracker.csv and the application archives — stat cards, status/sector/channel/funnel charts (inline SVG, no external dependencies), and a filterable applications table. Opens directly in a browser, fully offline. Re-run it any time after /apply or /outcome adds new entries./add-template registers your own CV or cover letter template (LaTeX, Typst, or another toolchain) in place of the stock ones. It captures the template's instructions (source extension, compile command, fonts, style rules, page limit), runs a mandatory test compile, and wires the template into /apply. See Custom templates below./add-portal generates a job-portal search skill for a job board in your market. It investigates the portal (search URL pattern, result structure, access rules), scaffolds the CLI skill from the same structure as the shipped ones, and test-runs a live query before registering. See Job search tools below./apply works
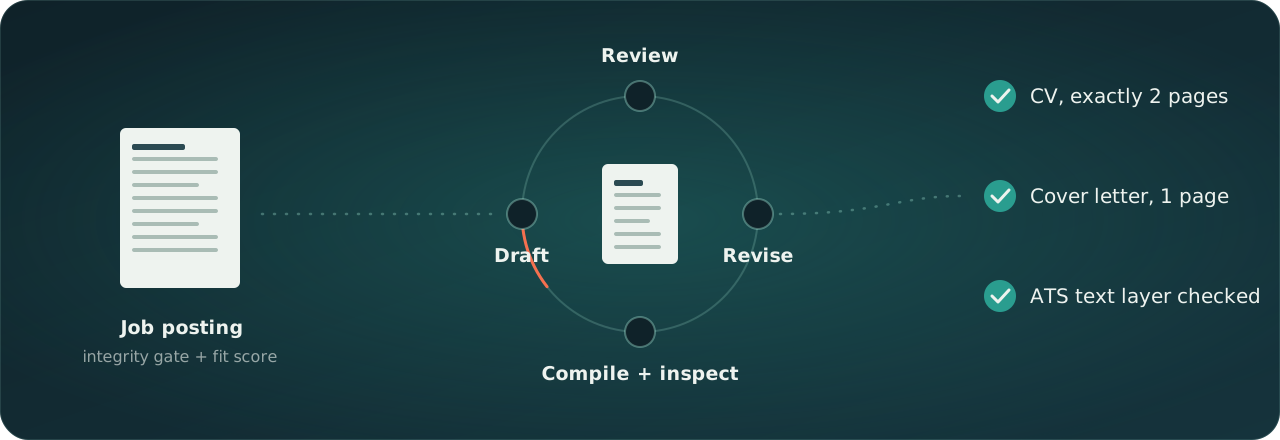
The /apply command runs a drafter-reviewer workflow with mandatory PDF compilation:
1. Parse the job posting (URL or text)
2. Evaluate fit against your profile (skills, experience, culture, location, career alignment)
3. Draft a tailored CV and cover letter in LaTeX
4. Spawn a reviewer agent that researches the company and critiques the drafts
5. Revise based on the reviewer's feedback
6. Compile and inspect both PDFs: lualatex for the CV, xelatex for the cover letter. Claude reads the rendered pages and iterates on the LaTeX until the CV is exactly 2 pages with no orphaned entry titles, and the cover letter is exactly 1 page with the signature visible and fonts consistent.
7. ATS-check the CV: extract the PDF's text layer (pdftotext, optional dependency) and verify it the way an ATS parser sees it — contact details present as literal text, no garbled glyphs, sane reading order — then score the posting's keyword coverage against the extraction. Keywords the profile genuinely supports get added; genuine gaps stay visible, never stuffed.
8. Present the final output with a verification checklist
All claims in the CV and cover letter are verified against your actual profile. The system never fabricates skills or experience.
/apply command compiles and visually inspects every PDF and applies targeted fixes (\needspace, \enlargethispage, font-matching wrappers for list items) until the layout is clean. This runs automatically on every application./apply extracts the compiled CV's text layer with pdftotext and verifies contact details, reading order, and the posting's keyword coverage against what a parser actually sees. Honesty rule enforced: a keyword the profile doesn't support is acknowledged as a gap, never stuffed in.If you prefer editing files directly instead of using /setup:
| File | What to change |
|------|---------------|
| CLAUDE.md | Your full profile (name, education, experience, skills, goals) |
| 01-candidate-profile.md | Structured version of your CV data |
| 02-behavioral-profile.md | Your behavioral assessment or self-assessment |
| 04-job-evaluation.md | Skill match areas, career goals, motivation filters |
| 05-cv-templates.md | Profile statement templates for different role types |
| 07-interview-prep.md | Your STAR examples from actual experience |
| search-queries.md | Job search queries for your skills and location |
As your priorities evolve, you can reconfigure just the job search without re-running the full profile setup:
/setup --section search
This re-runs the search configuration interview: which roles to target, which skills to search for, which locations, and which portals. It also suggests role types you may not have considered based on your profile.
The CV uses moderncv (banking style). The cover letter uses a custom cover.cls with Lato/Raleway fonts. Both are LaTeX — the reference engine this repo ships and maintains.
To use your own template instead — LaTeX, Typst, or any other toolchain that compiles to PDF from the command line — run:
/add-template
Point it at your source file (a .tex file plus any .cls/.sty files or bundled fonts; a .typ file plus any local packages; or an equivalent for another toolchain). The command interviews you for the template's instructions — source extension, compile command, fonts and where they live, style rules to preserve, hard page limit — stores everything under templates/, runs a mandatory test compile, and activates the template so /apply drafts and compiles from it. Templates are stored with [PLACEHOLDER] tokens instead of personal data, so they're safe to commit and share.
/add-template --list shows registered templates/add-template --use switches between them/add-template --use default reverts to the stock moderncv / cover.cls templates05-cv-templates.md and 06-cover-letter-templates.md.
The four Danish CLI tools in .agents/skills/ (Jobbank, Jobdanmark, Jobindex, Jobnet) demonstrate the pattern for building a job-portal integration for a specific market. If you're in a different country, run:
/add-portal
Give it your local job board's URL. The command investigates the portal (search-URL pattern, result-page structure, robots.txt/access rules), scaffolds a CLI skill with the same structure, commands, and output contract as the shipped ones, and test-runs a live query before registering anything. Auth-walled portals are declined, and portals with restrictive terms get a prominent personal-use-only warning in the generated skill. The generated skill is market-specific and lives in your fork; the generator itself is the universal part.
Maintaining a fork adapted to your market or language? Add it to the Community forks & adaptations thread so others can find it.
For country-agnostic starting points outside Denmark, the repo ships two portal skills alongside the Danish demos:
linkedin-search — built on LinkedIn's public, unauthenticated jobs-guest endpoints. Field-agnostic, zero runtime dependencies (runs with just bun), and takes the search location as an explicit flag, so it works for any market out of the box (-l "Berlin, Germany", -l "Mumbai, Maharashtra, India", -l "Remote", …). Intended for personal use only — automated access is against LinkedIn's Terms of Service, so keep volume low. See .agents/skills/linkedin-search/SKILL.md.freehire-search — queries the freehire.me aggregator's public REST API (JSON, no API key). Tech-focused (software, data, engineering, DevOps, remote), multi-market via facet flags (--region, --country, --remote), and zero runtime dependencies. Unlike the HTML-scraping Danish portals, results come back struct→ →
 →
 →
 →
 →
 →
 →